
Figure 1 From An Investigation Of End To End Models For Robust Speech
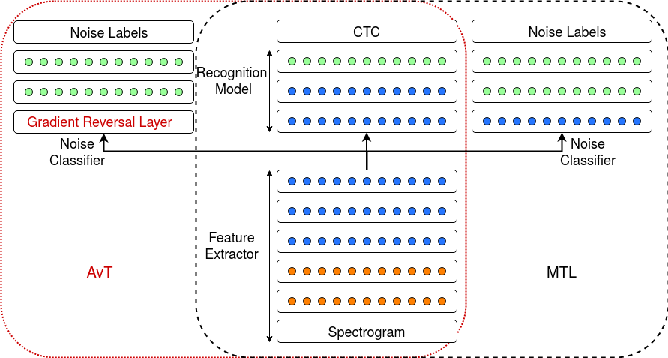
Figure 1 from An Investigation of End-to-End Models for Robust Speech ...
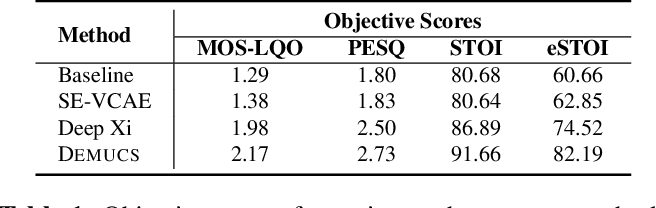
Table 1 from An Investigation of End-to-End Models for Robust Speech ...
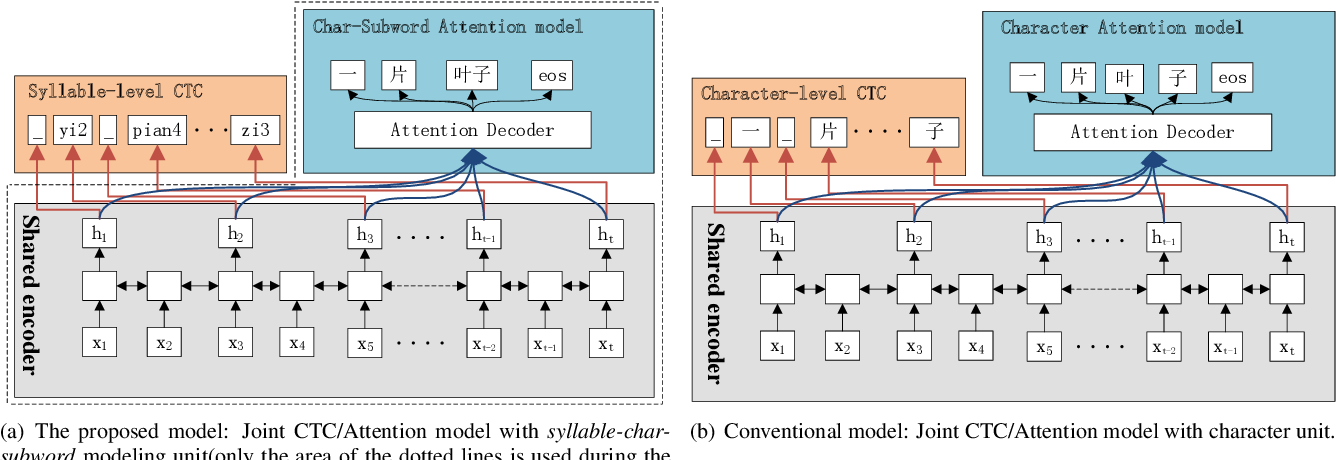
Figure 1 from An Investigation of Using Hybrid Modeling Units for ...

(PDF) An Investigation of End-to-End Models for Robust Speech Recognition

Figure 1 from A Comparison of End-to-End Models for Long-Form Speech ...

Figure 1 from Integrating Pre-Trained Speech and Language Models for ...

Figure 1 from An Investigation Into On-device Personalization of End-to ...
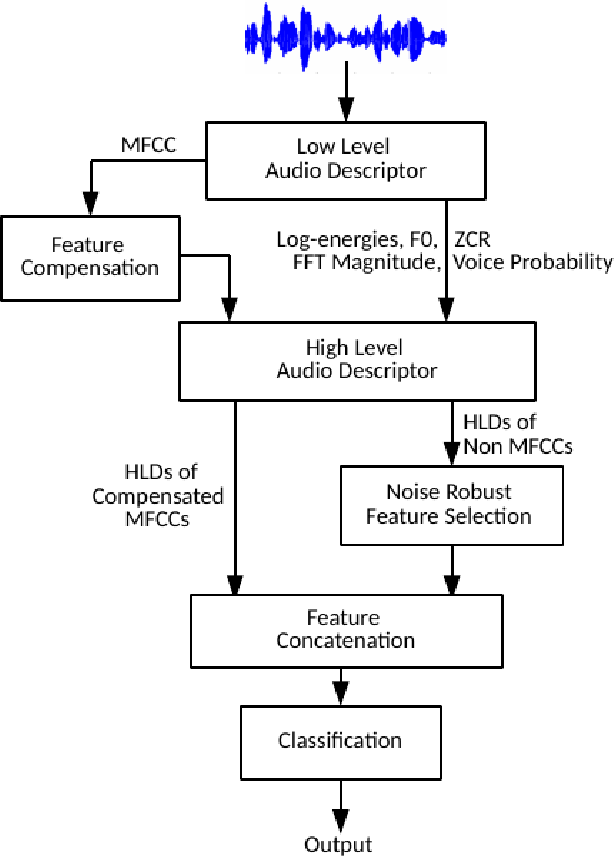
Figure 1 from Front-End Feature Compensation for Noise Robust Speech ...

Figure 1 from AgeNet-AT: An End-to-End Model for Robust Joint Speaker ...
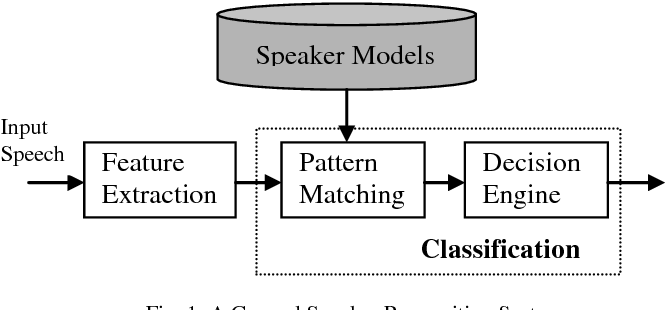
Figure 1 from Overview of Front-end Features for Robust Speaker ...
Advertisement Space (300x250)
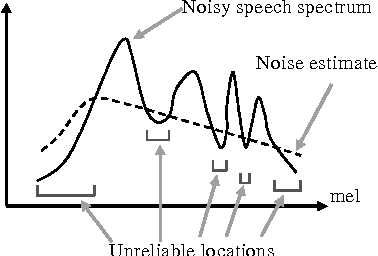
Figure 1 from A robust front-end algorithm for distributed speech ...
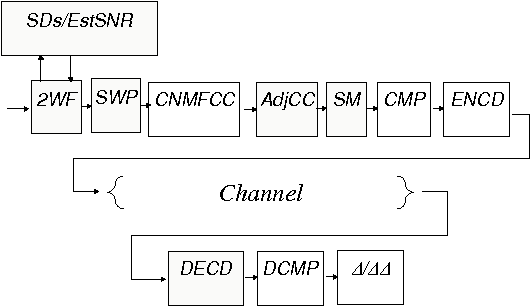
Figure 1 from A robust front-end algorithm for distributed speech ...
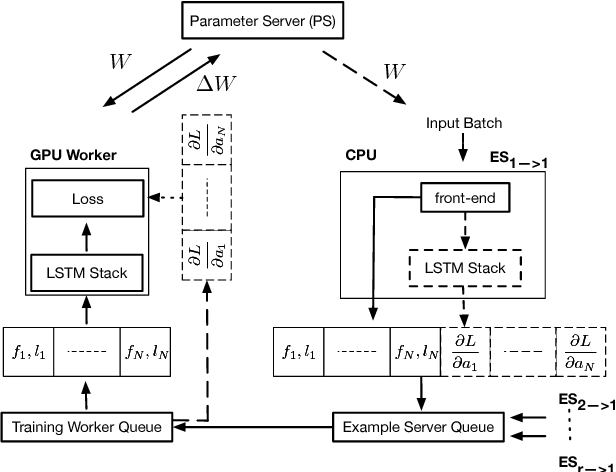
Figure 1 from End-to-End Training of Acoustic Models for Large ...

Figure 1 from Robust front-end for speech recognition based on ...
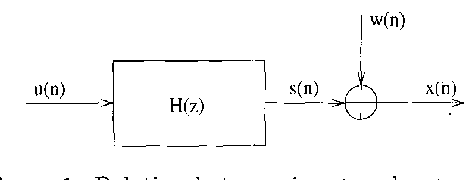
Figure 1 from A performance comparison of robust speech analysis ...

Figure 1 from End-to-End Deep Convolutional Recurrent Models for Noise ...
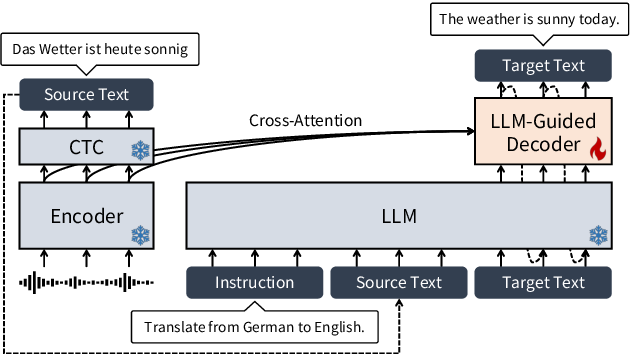
Figure 1 from End-to-End Speech Translation Guided by Robust ...
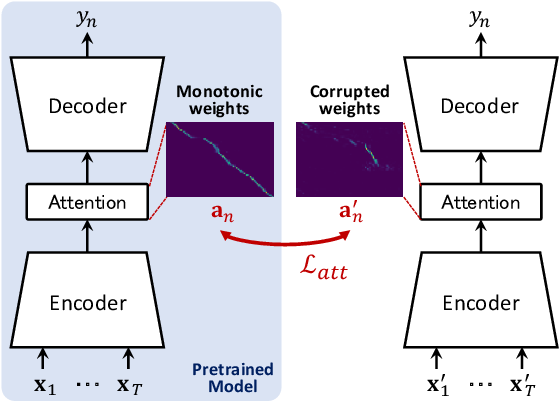
Figure 1 from Noise-robust Attention Learning for End-to-End Speech ...
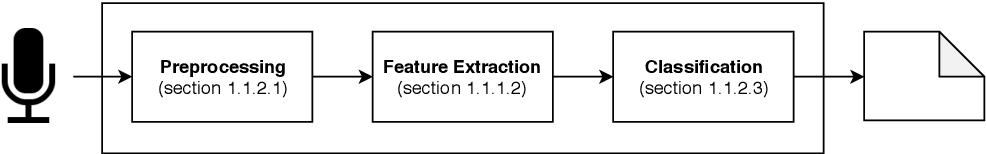
Figure 1.1 from Design and Implementation of an End-to-End Speech ...
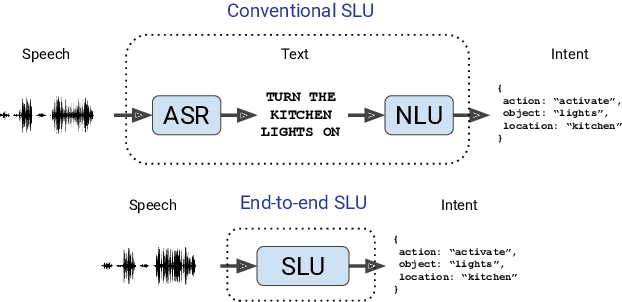
Figure 1 from Speech Model Pre-training for End-to-End Spoken Language ...
Advertisement Space (336x280)

Figure 1 from Robustness of end-to-end Automatic Speech Recognition ...

Figure 1 from Combining multiple end-to-end speech recognition models ...

Figure 1 from Learning Robust and Multilingual Speech Representations ...

Figure 1 from Decoupled Structure for Improved Adaptability of End-to ...

Figure 1 from Combined speech enhancement and auditory modelling for ...

Figure 1 from End-to-end model for named entity recognition from speech ...

Figure 1 from Modality Confidence Aware Training for Robust End-to-End ...
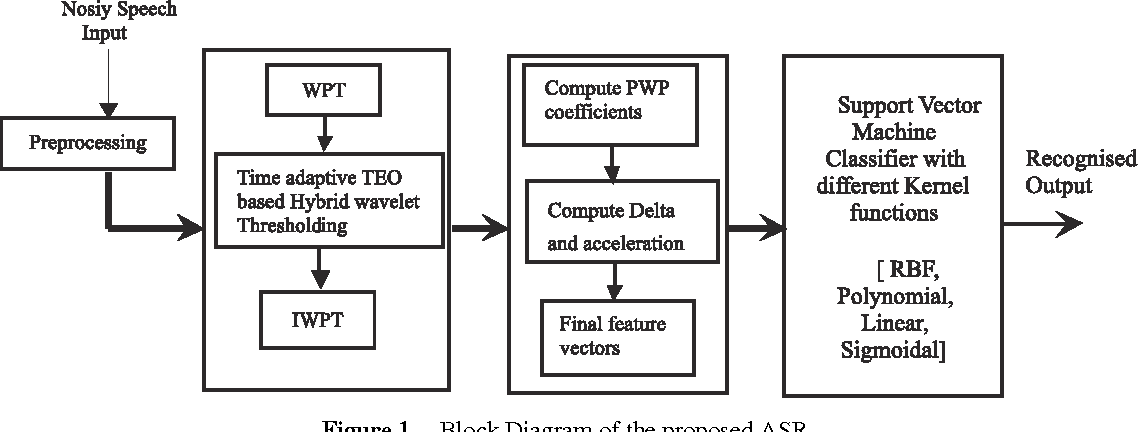
Figure 1 from A Noise Robust Speech Recognition System Using Wavelet ...

Figure 1 from An Improved End-to-End Audio-Visual Speech Recognition ...

Figure 1 from Adapting Large Language Model with Speech for Fully ...
Advertisement Space (336x280)

Figure 1 from Embedding Guided End-to-End Framework for Robust Image ...
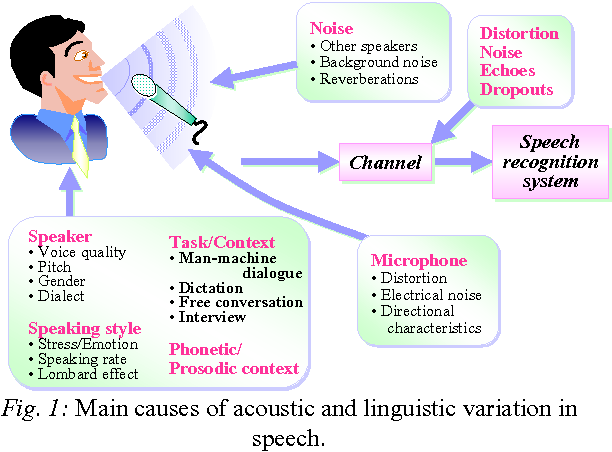
Figure 1 from Robust methods in automatic speech recognition and ...

Figure 1 from Vietnamese Speech Synthesis with End-to-End Model and ...

Figure 1 from Delve deep into End-To-End Automatic Speech Recognition ...

Figure 1 from Dual-Path Style Learning for End-to-End Noise-Robust ...
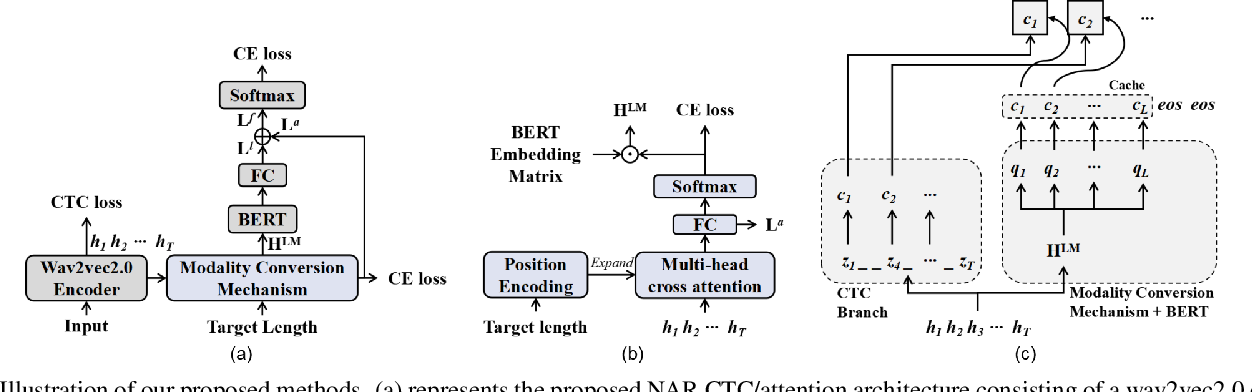
Figure 1 from Improving Non-Autoregressive End-to-End Speech ...