
Figure 1 From Attention Head Interactive Dual Attention Transformer For
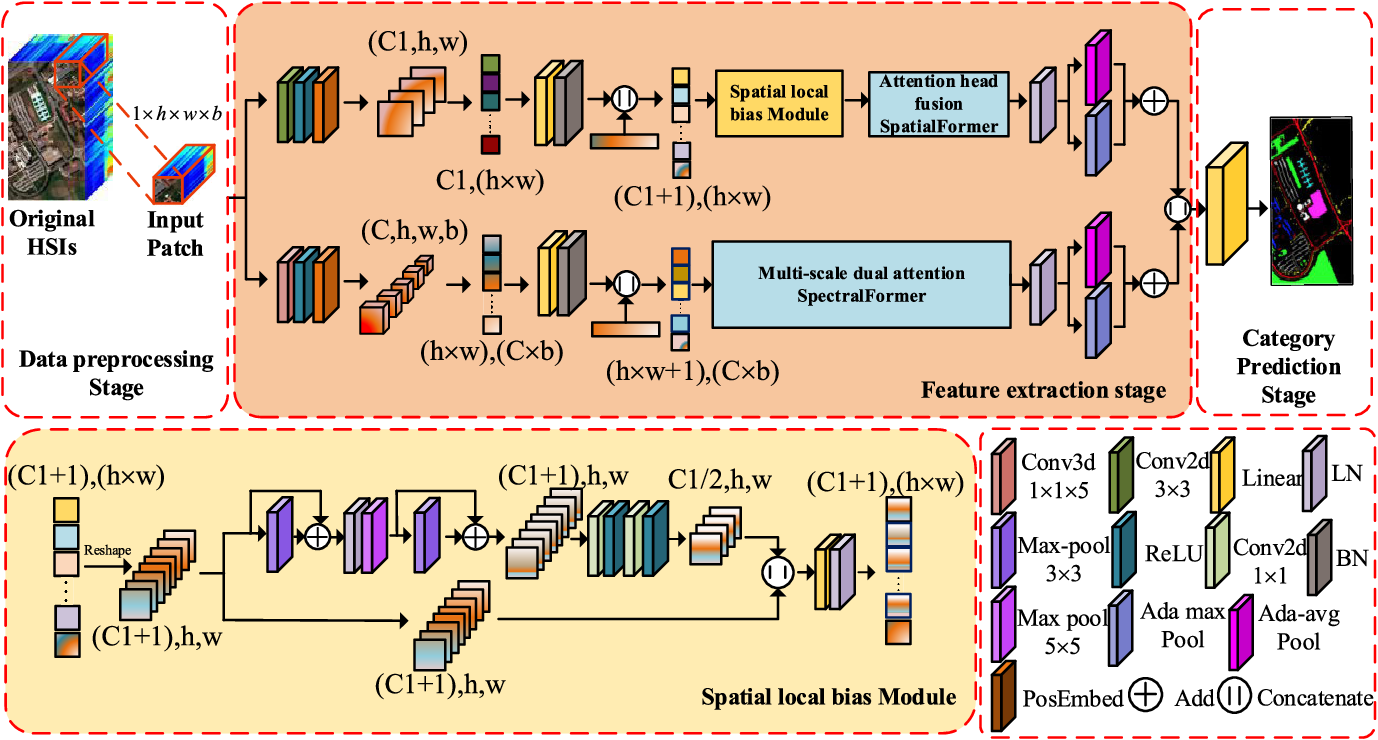
Figure 1 from Attention Head Interactive Dual Attention Transformer for ...

Figure 1 from A Dual Cross Attention Transformer Network for Infrared ...

Figure 1 from Efficient Dual Attention Transformer for Image Super ...

Figure 1 from Efficient Dual Attention Transformer for Image Super ...

Figure 1 from Dual Path Transformer with Partition Attention | Semantic ...

Figure 1 from Dual Path Transformer with Partition Attention | Semantic ...

Figure 1 from Adaptive Multi-Neighborhood Attention based Transformer ...

Figure 1 from A Dual-Attention Transformer Network for Pansharpening ...

TTDAT: Two-Step Training Dual Attention Transformer for Malware ...

TTDAT: Two-Step Training Dual Attention Transformer for Malware ...
Advertisement Space (300x250)
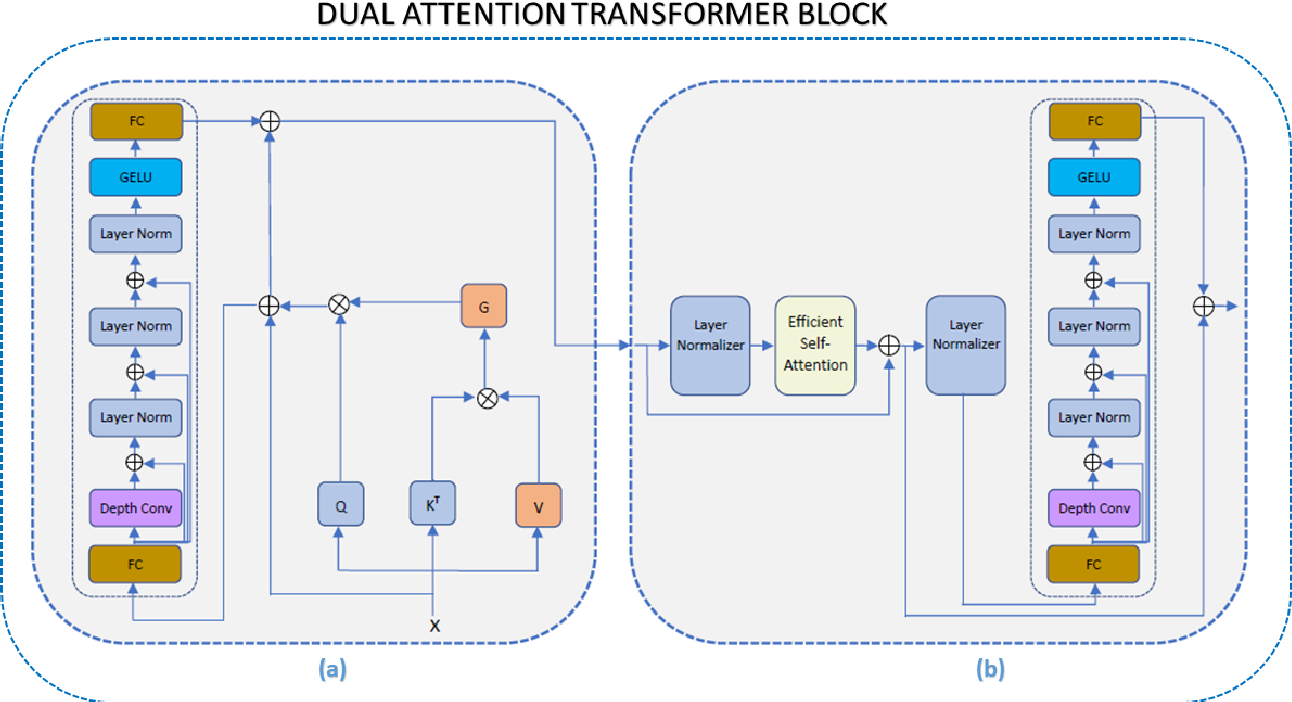
Figure 2 from TransDAE: Dual Attention Mechanism in a Hierarchical ...

Figure 1 from How Does Attention Work in Vision Transformers? A Visual ...
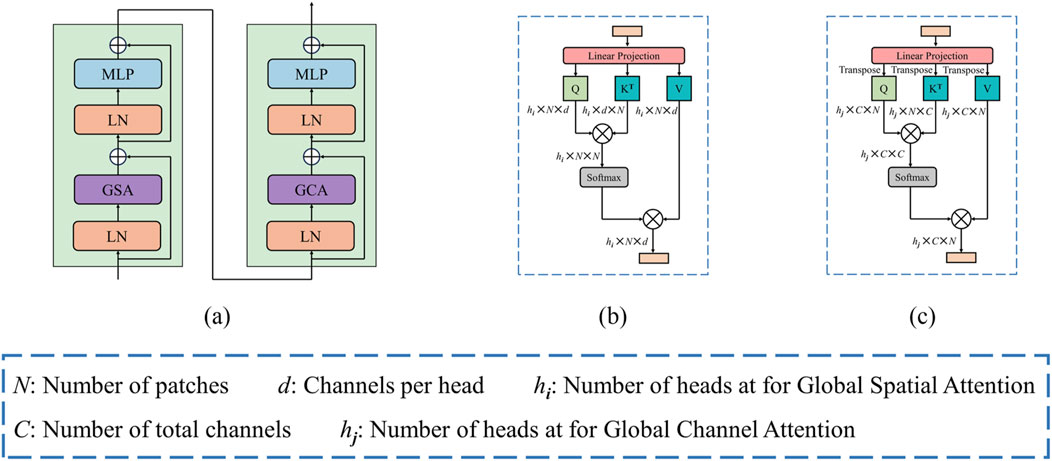
Frontiers | A dual-branch and dual attention transformer and CNN hybrid ...
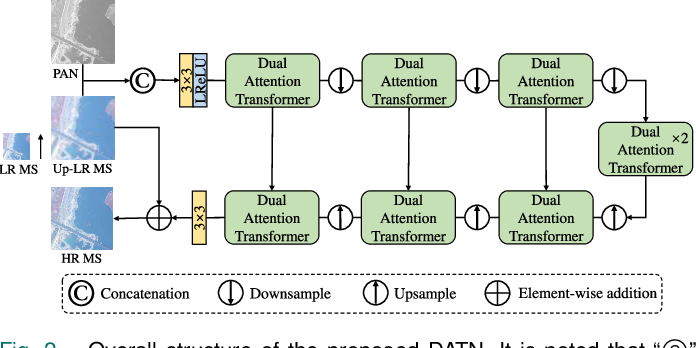
Figure 2 from A Dual-Attention Transformer Network for Pansharpening ...
An illustration for a Transformer with two-head attention units ...
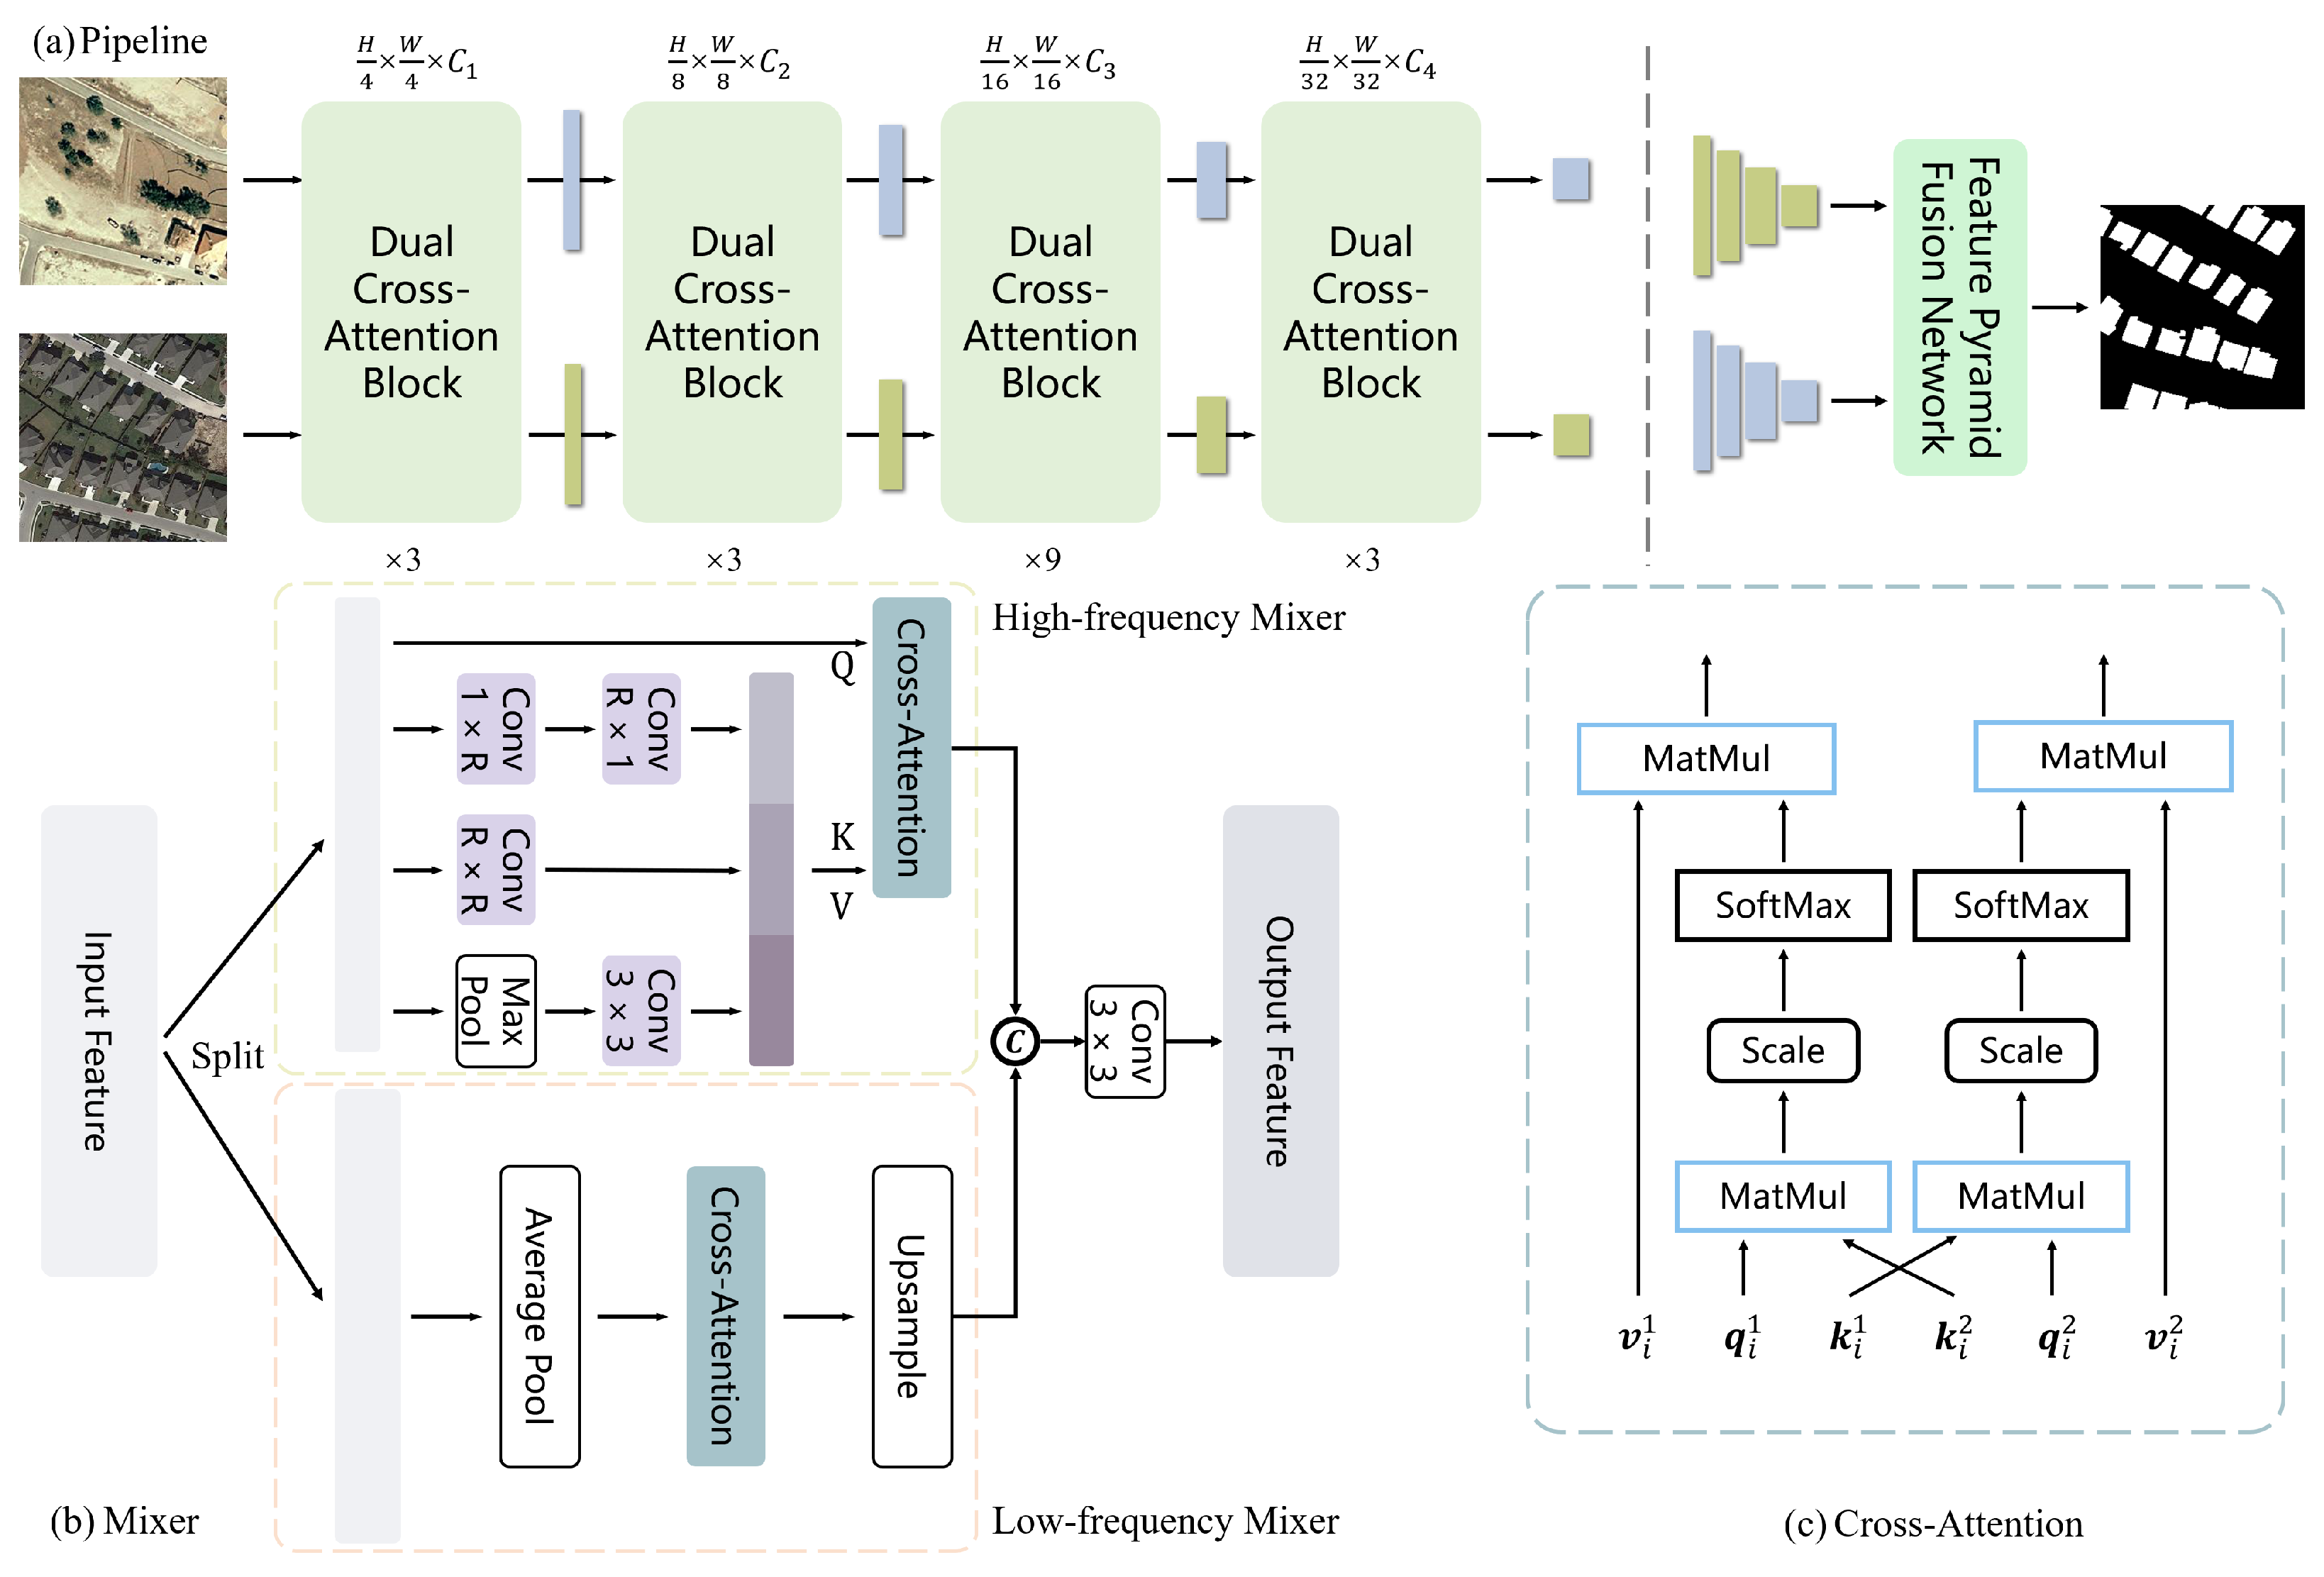
DCAT: Dual Cross-Attention-Based Transformer for Change Detection

Understanding Multi Head Attention in Transformers | by Sachinsoni | Medium
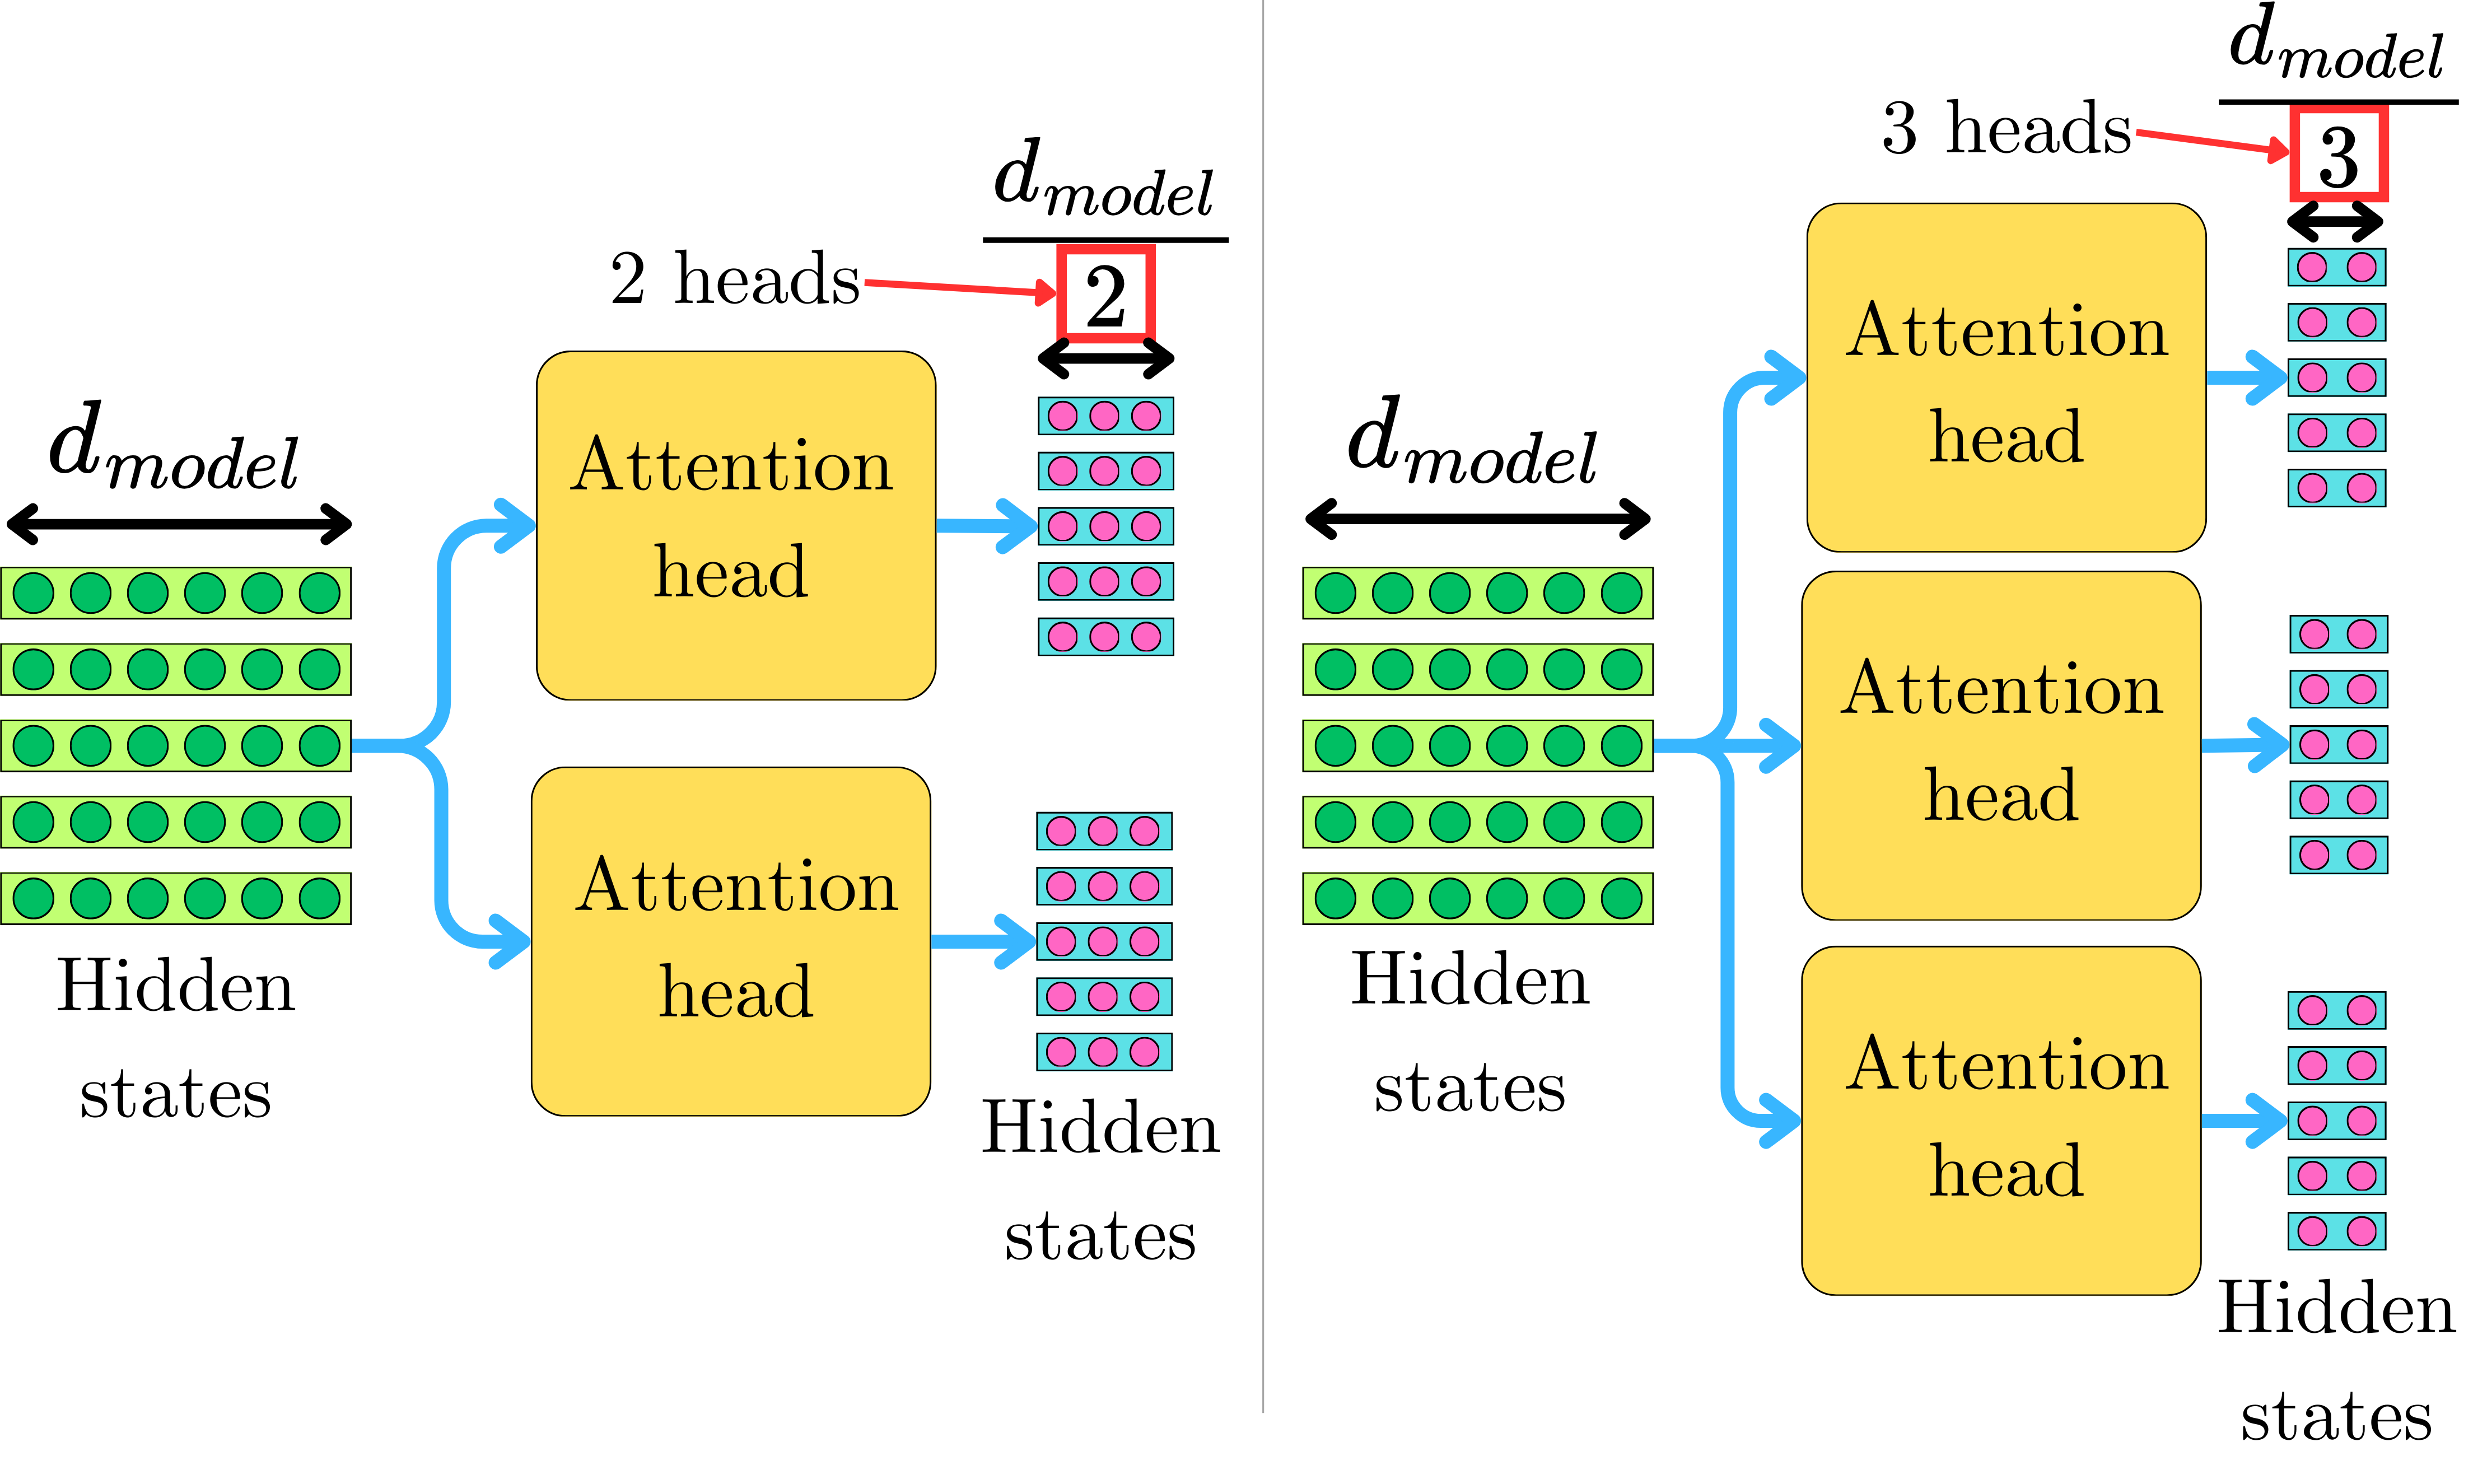
Attention Is All You Need: The Original Transformer Architecture

【ECCV2022】DaViT: Dual Attention Vision Transformers-CSDN博客

Is Transformer multi-headed attention a form of ensemble? - Cross Validated
Advertisement Space (336x280)
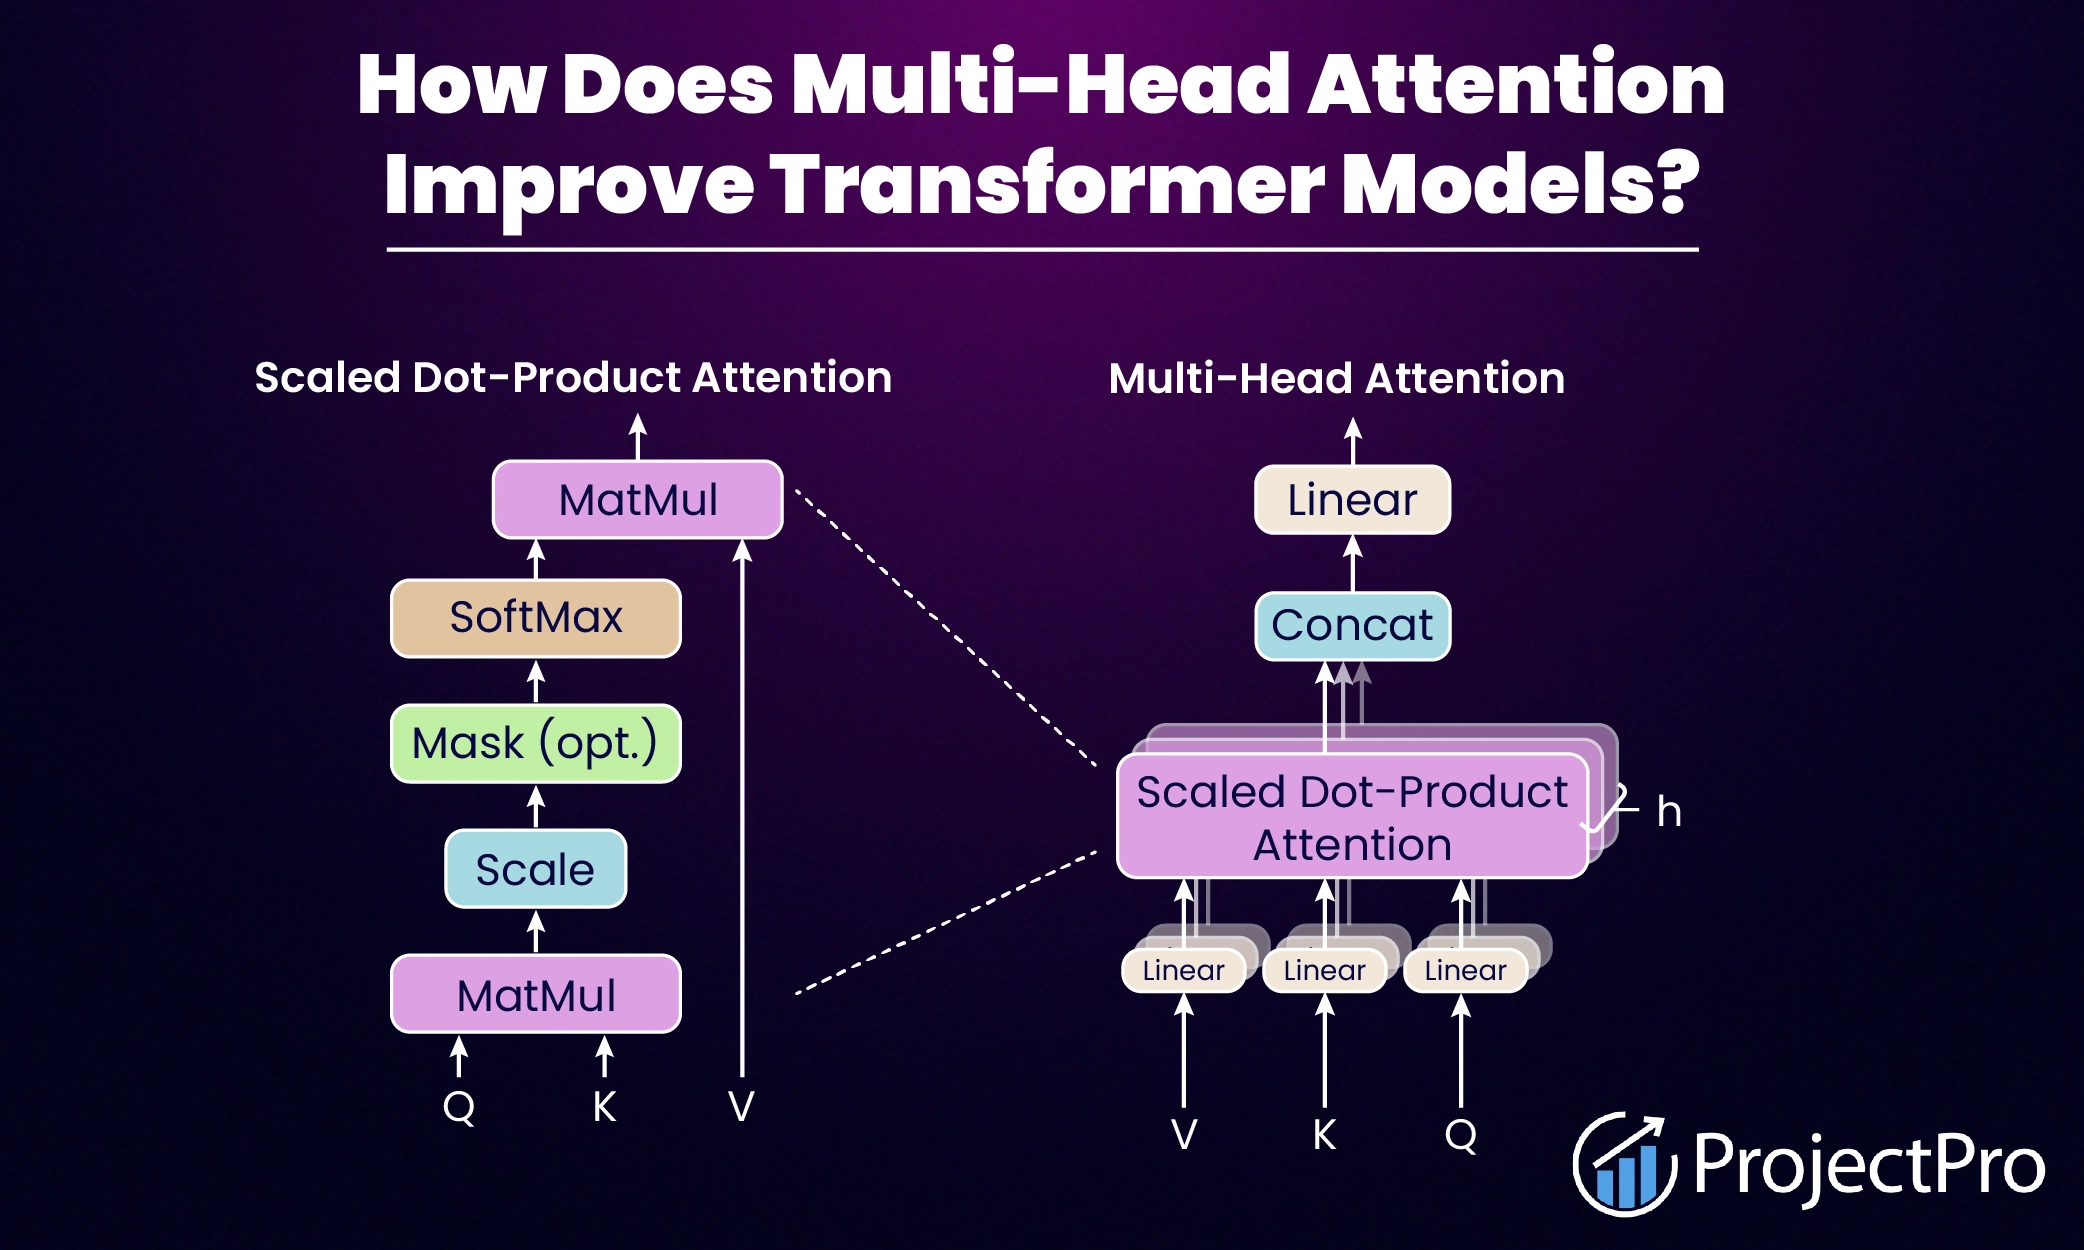
How Does Multi-Head Attention Improve Transformer Models?
TransfomerLayer structure. Figure 6. Multi-Head Attention structure ...
Transformer and Multi-Head attention mechanism. In contrast to LSTM ...
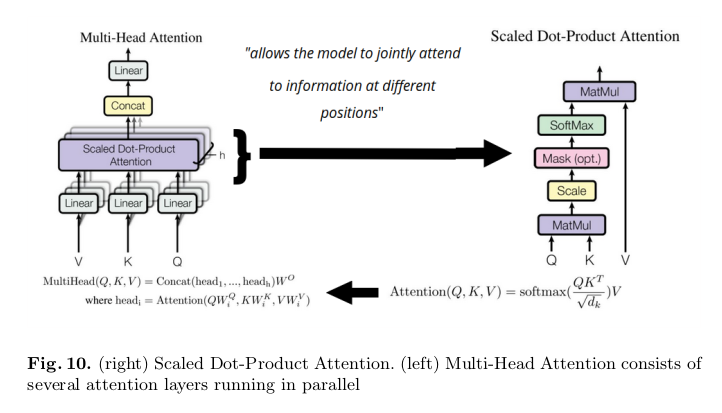
Attention Is All You Need: The Transformer - Sayef's Tech Blog

Transformer encoder block with multi-head attention and scaled dot ...

Understanding Multi Head Attention in Transformers | by Sachinsoni | Medium

Multi-head attention architecture, where each head of attention maps a ...
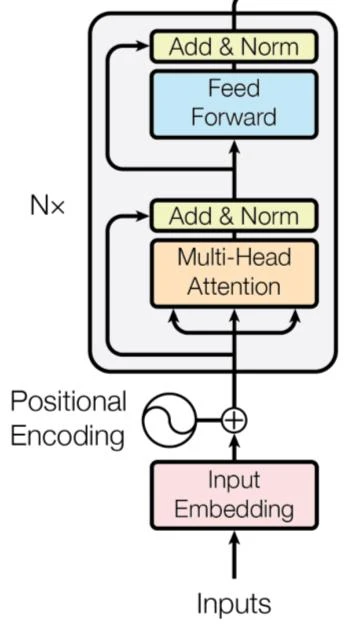
Transformers from Scratch - Part 3: Multi-Head Attention Mechanism ...

DCAT: Dual Cross-Attention-Based Transformer for Change Detection
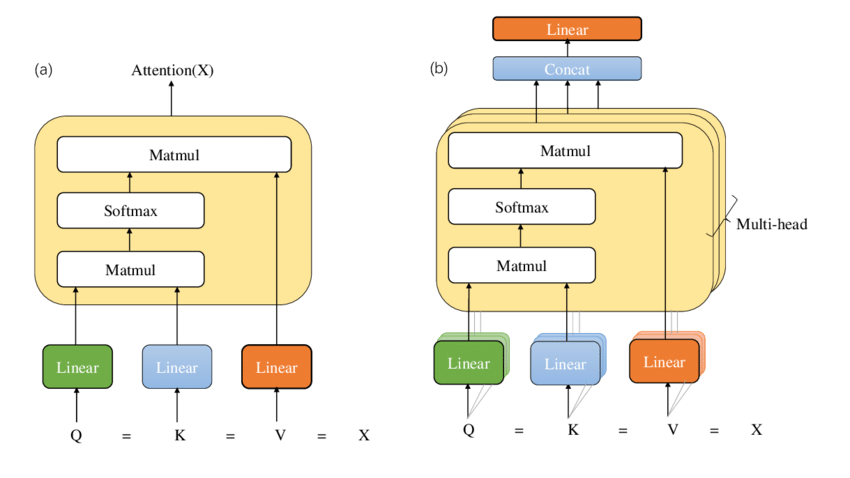
How Does Multi-Head Attention Improve Transformer Models?
Advertisement Space (336x280)

3: Illustration of Multi-head attention mechanism in a Transformer ...
Architecture of the Multi-Head Attention based Transformer Model ...

Figure 1 from DBT-Net: Dual-Branch Federative Magnitude and Phase ...
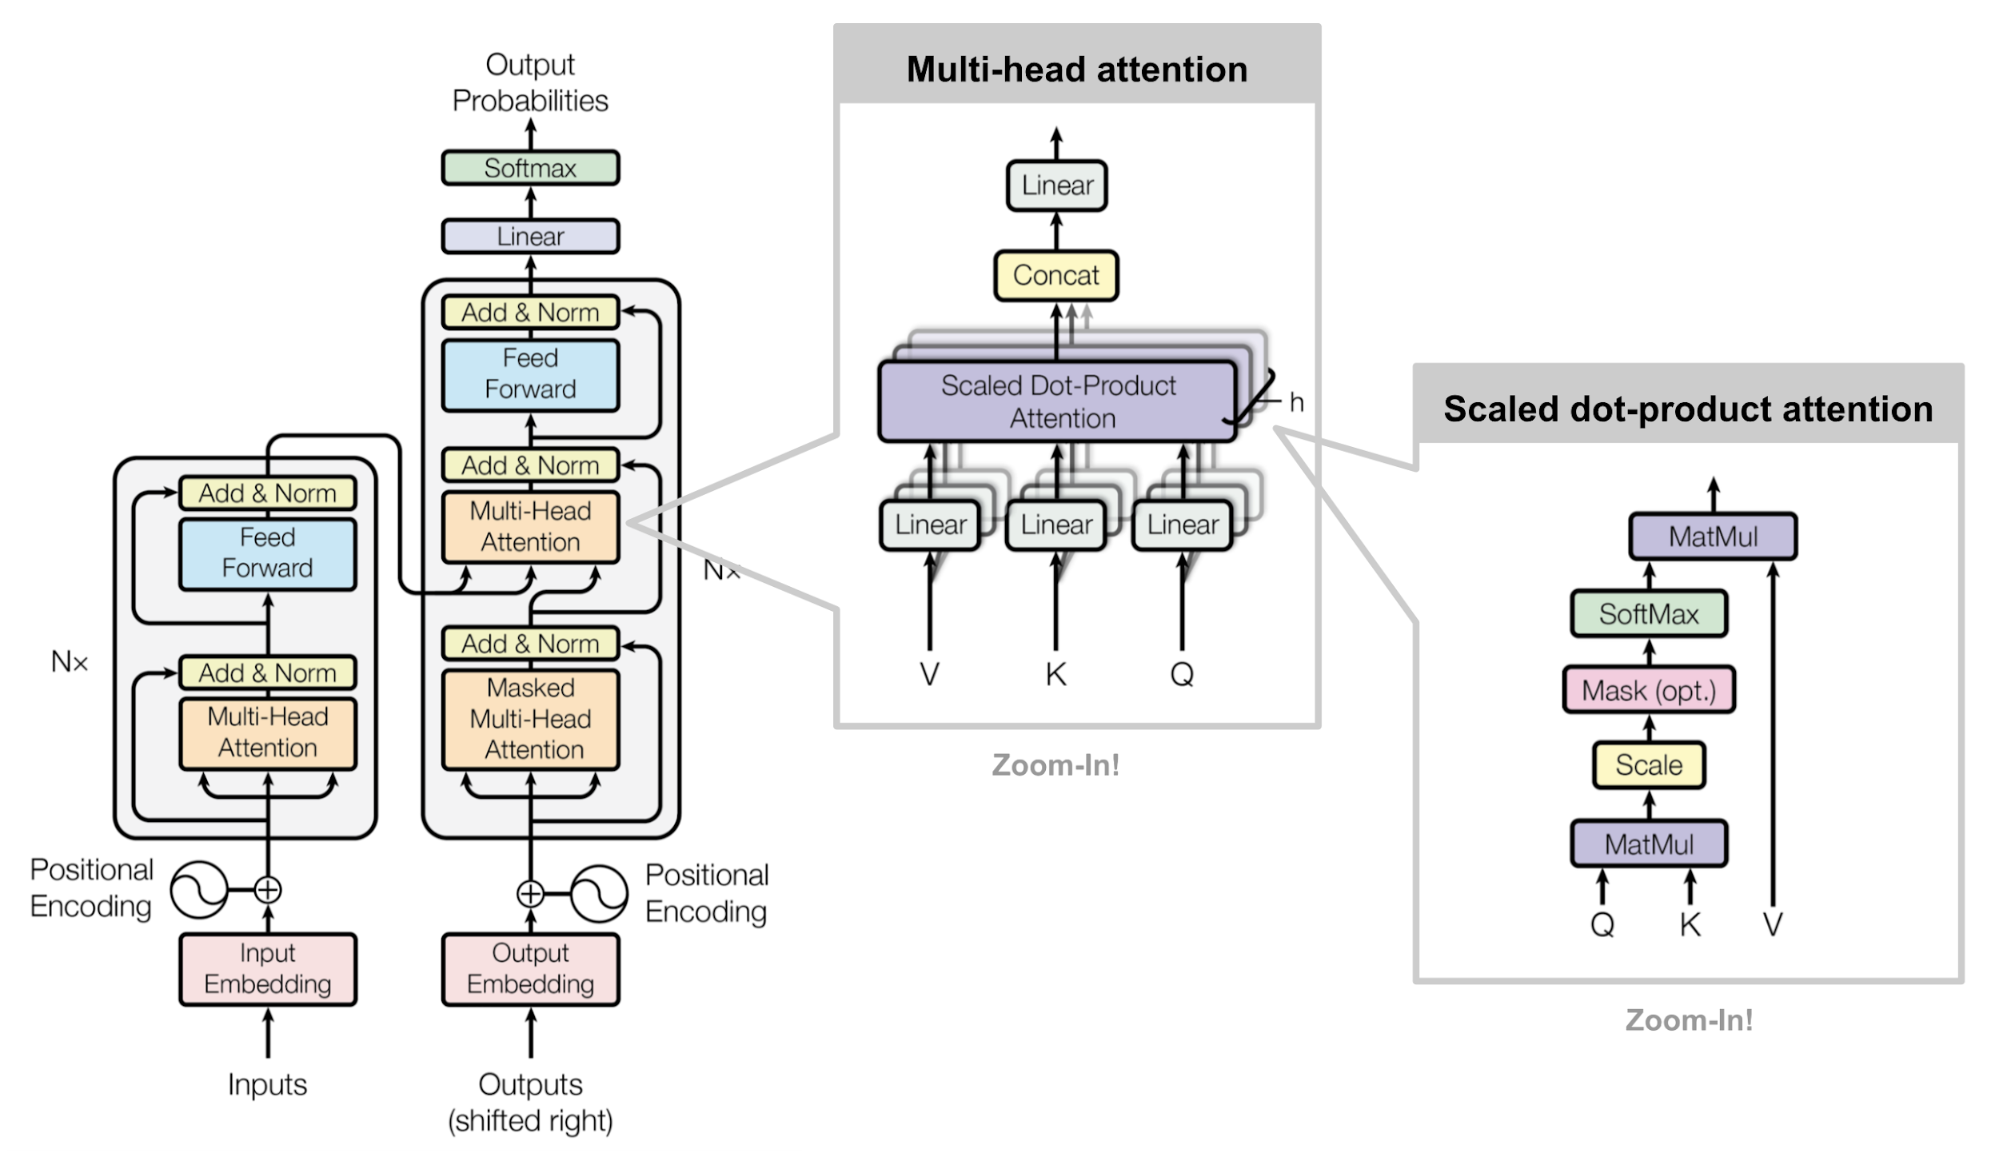
Attention - PRIMO.ai

Unpacking the Power of Attention Mechanisms in Deep Learning - viso.ai
Components of the Multi-Head Attention Design. (Vaswani et al., 2017 ...