
Figure 1 From Communication Efficient Llm Pre Training With Sparseloco
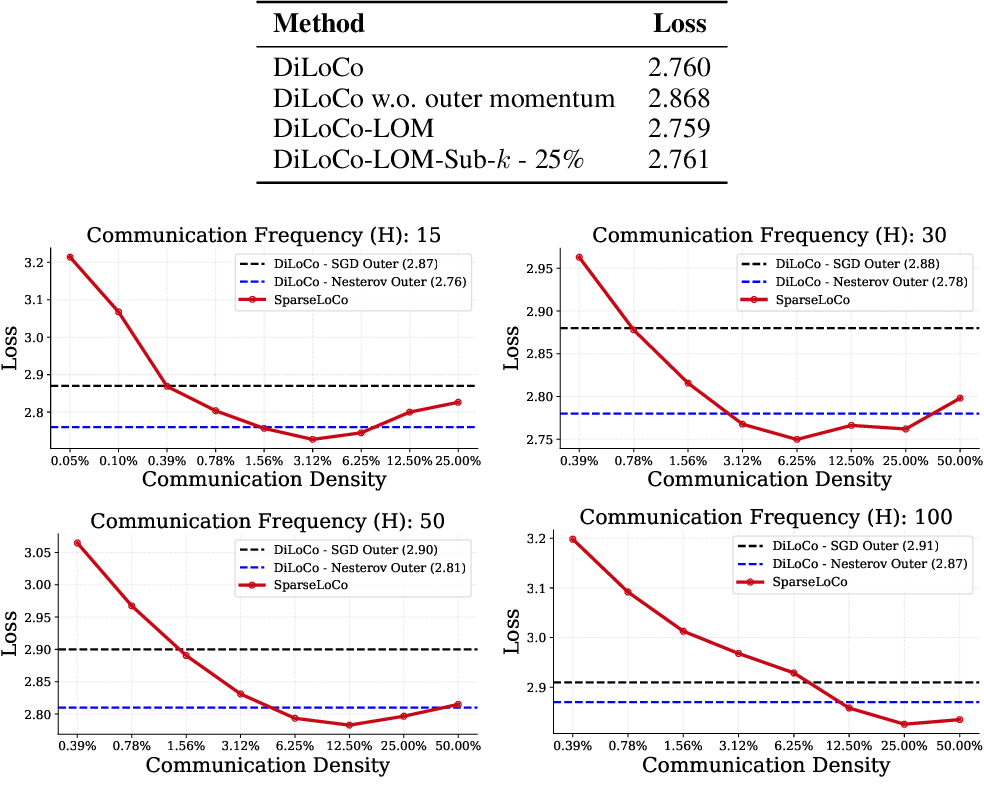
Figure 1 from Communication Efficient LLM Pre-training with SparseLoCo ...

Figure 1 from A Little Help Goes a Long Way: Efficient LLM Training by ...

Figure 1 from User-LLM: Efficient LLM Contextualization with User ...
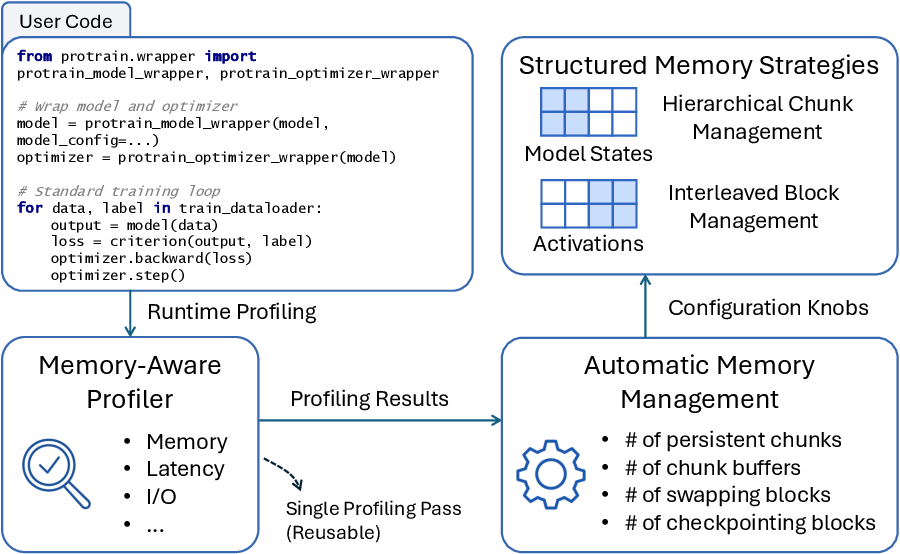
Figure 1 from ProTrain: Efficient LLM Training via Memory-Aware ...
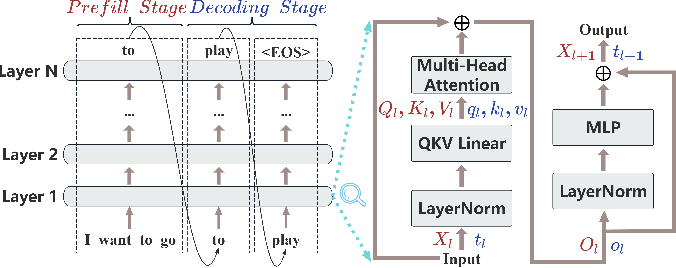
Figure 1 from Efficient LLM Edge Collaboration Deployment with LoRA ...

Figure 1 from Memory-Efficient LLM Training by Various-Grained Low-Rank ...

Figure 1 from Progressive Mixed-Precision Decoding for Efficient LLM ...

Figure 1 from An Agile Framework for Efficient LLM Accelerator ...
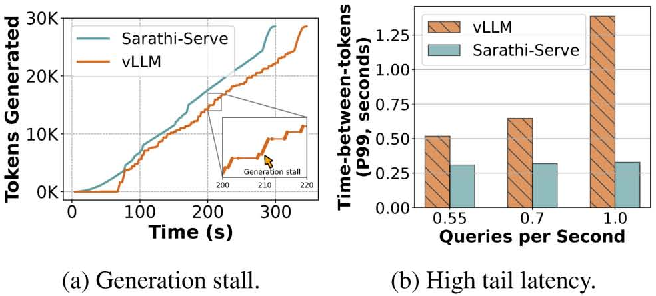
Figure 1 from Efficient LLM Inference via Chunked Prefills | Semantic ...
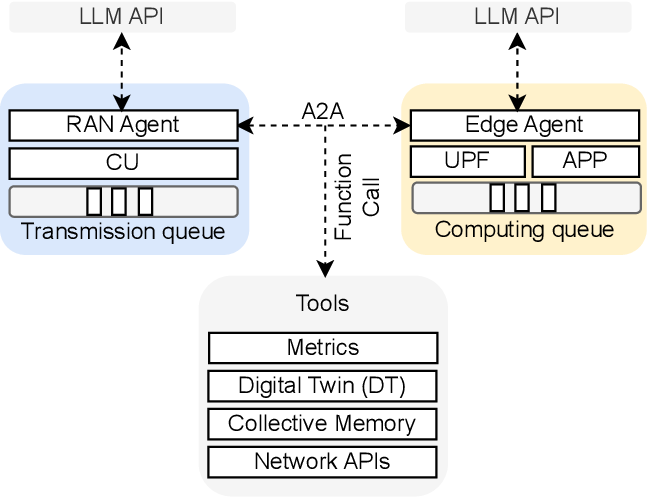
Figure 1 from Toward an Unbiased Collective Memory for Efficient LLM ...
Advertisement Space (300x250)
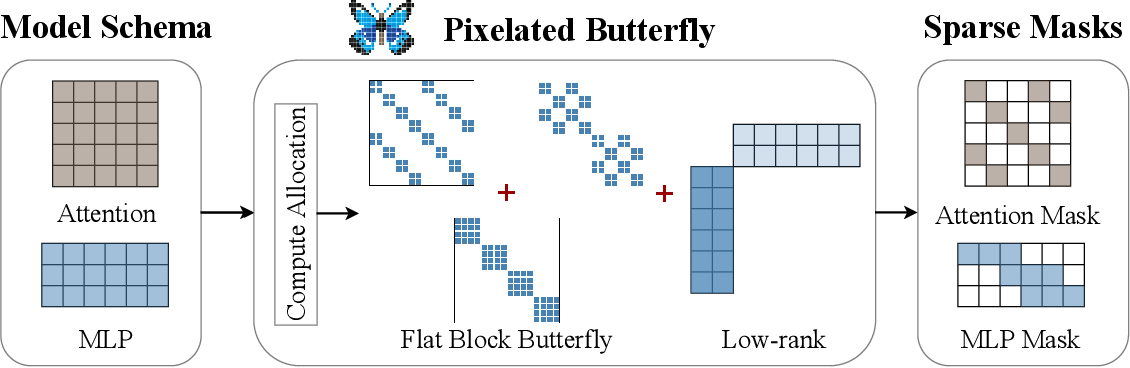
Figure 1 from Pixelated Butterfly: Simple and Efficient Sparse training ...
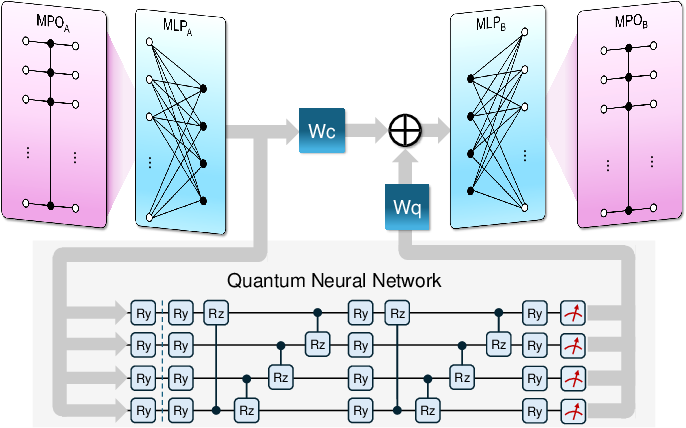
Figure 1 from Quantum-Enhanced LLM Efficient Fine Tuning | Semantic Scholar

Figure 3 from LServe: Efficient Long-sequence LLM Serving with Unified ...

Figure 1 from Comm-CoT: Standardized Chain-of-Thought Communication ...

Figure 2.2 from Communication-Efficient LLM Training for Federated ...

Figure 1 from E^2-LLM: Efficient and Extreme Length Extension of Large ...

Figure 1 from SparQ Attention: Bandwidth-Efficient LLM Inference ...
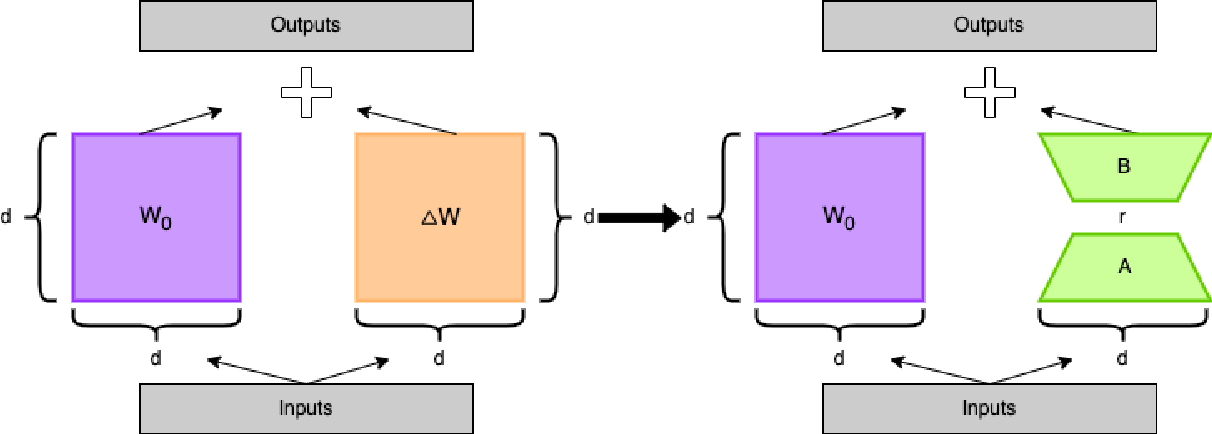
Figure 2.3 from Communication-Efficient LLM Training for Federated ...

Figure 1 from Language Model Pre-Training with Sparse Latent Typing ...
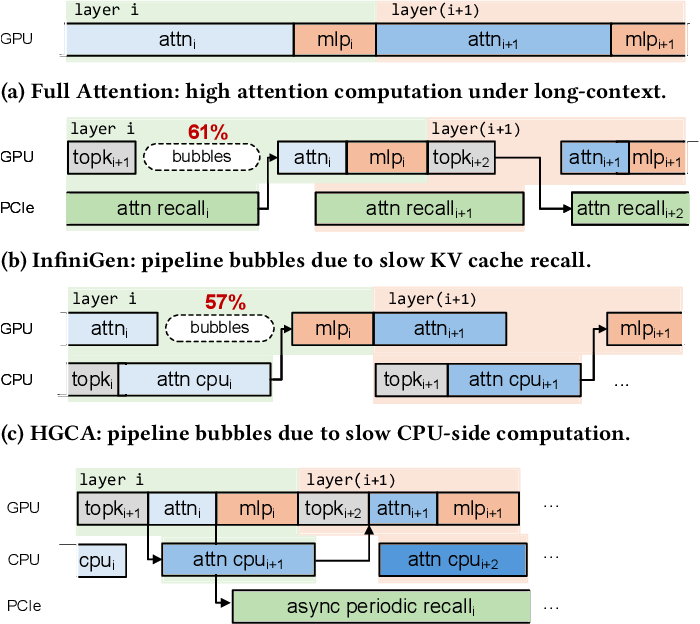
Figure 1 from ScoutAttention: Efficient KV Cache Offloading via Layer ...
Advertisement Space (336x280)

Figure 2.1 from Communication-Efficient LLM Training for Federated ...

Figure 1 from Enabling Efficient Interaction between an Algorithm Agent ...

Figure 2.5 from Communication-Efficient LLM Training for Federated ...
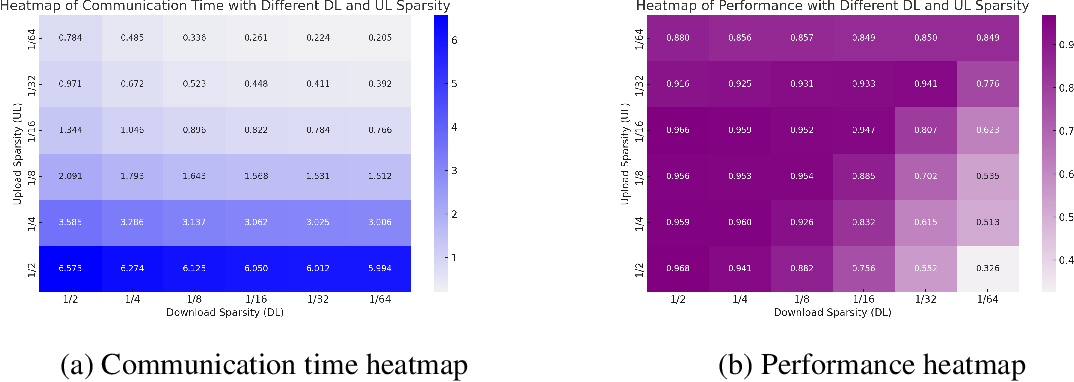
Figure 6.1 from Communication-Efficient LLM Training for Federated ...

Scaling with Collapse: Efficient and Predictable Training of LLM ...

Figure 1 from Communication-Efficient Federated Learning with Sparsity ...
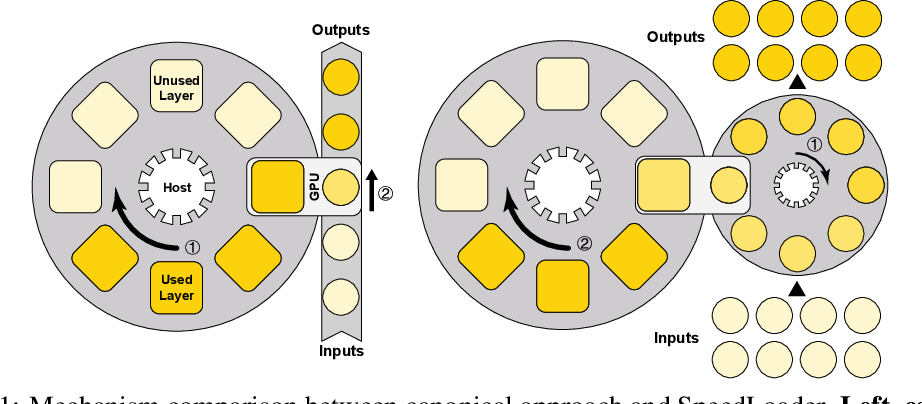
Figure 1 from SpeedLoader: An I/O efficient scheme for heterogeneous ...

Figure 5.3 from Communication-Efficient LLM Training for Federated ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...

Flow of Reasoning: Efficient Training of LLM Policy with Divergent ...
Advertisement Space (336x280)
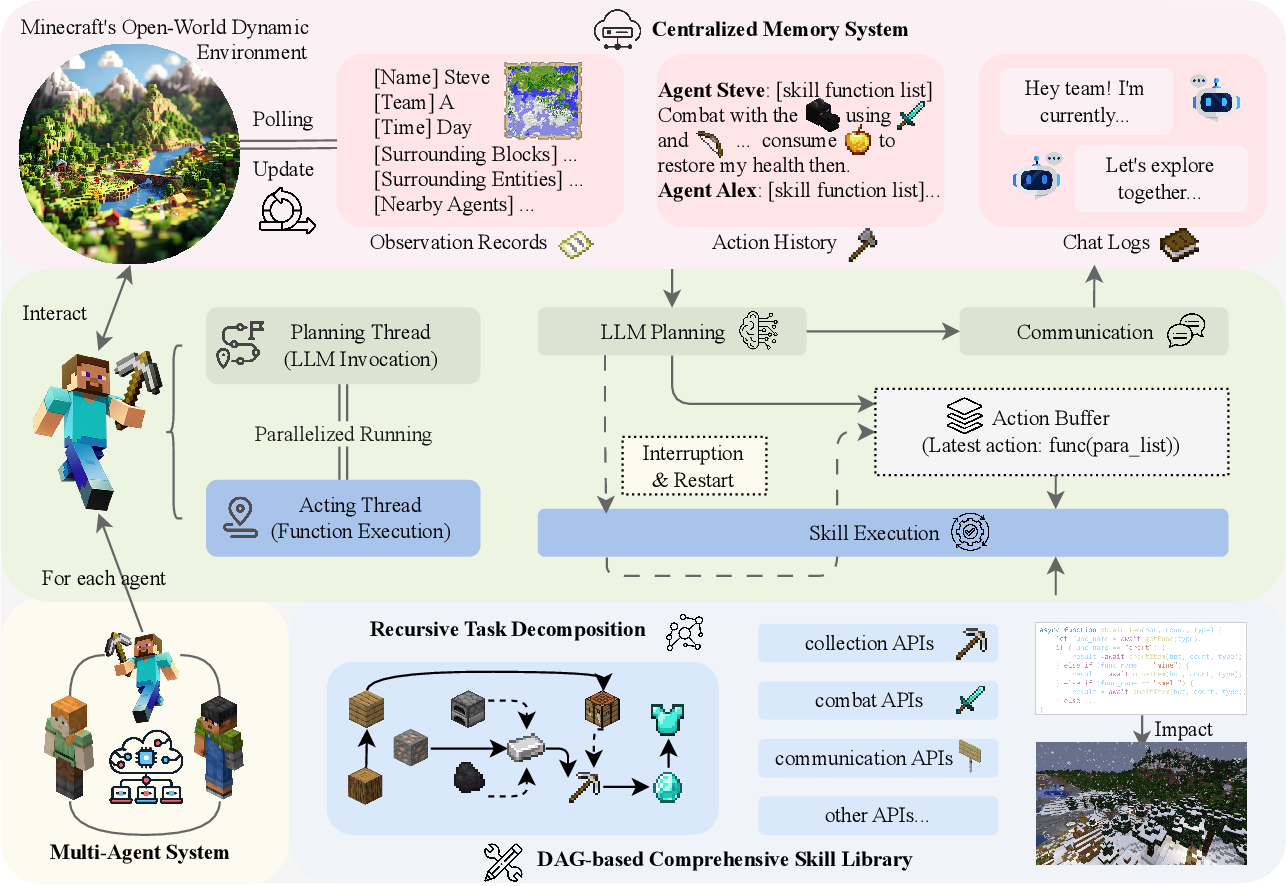
Figure 1 from Parallelized Planning-Acting for Efficient LLM-based ...
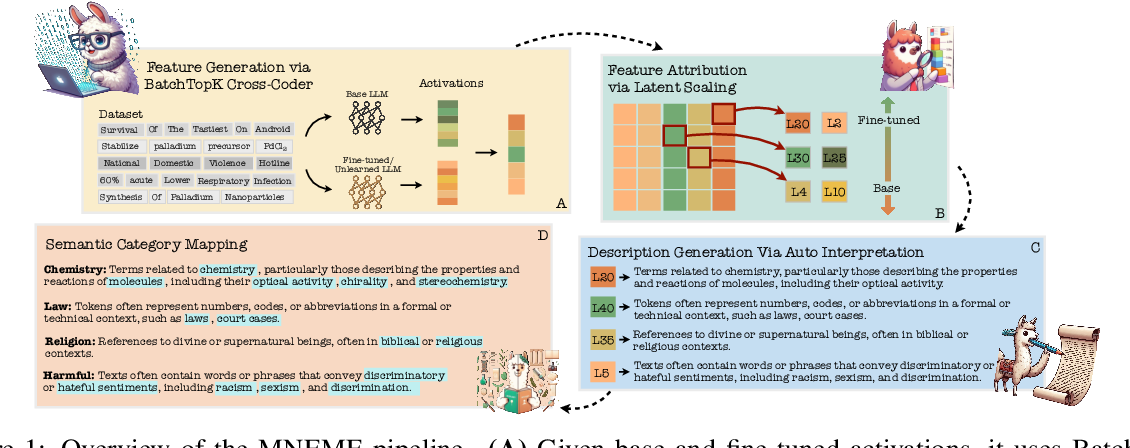
Figure 1 from Reviving Your MNEME: Predicting The Side Effects of LLM ...
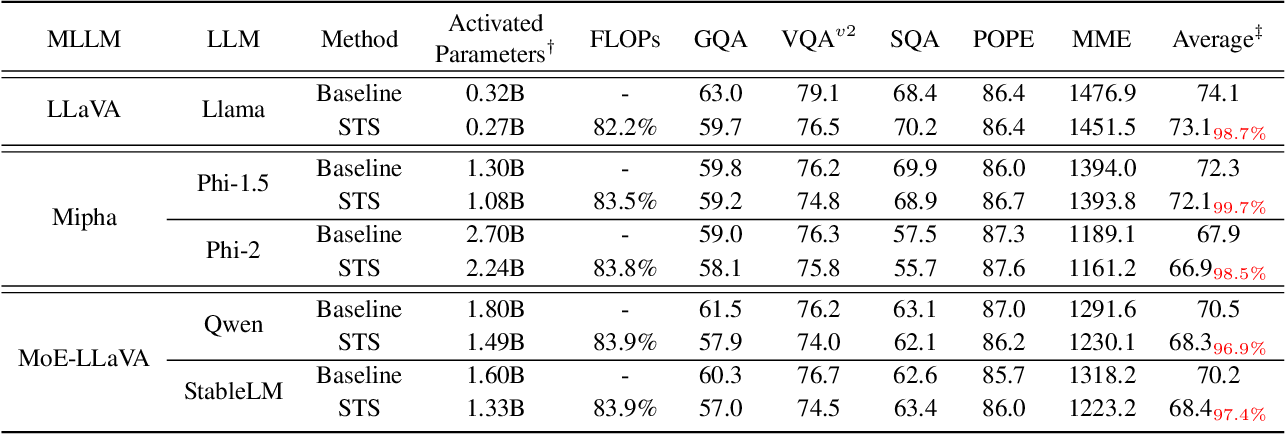
Table 1 from Sparse Training Scheme for Multimodal LLM | Semantic Scholar
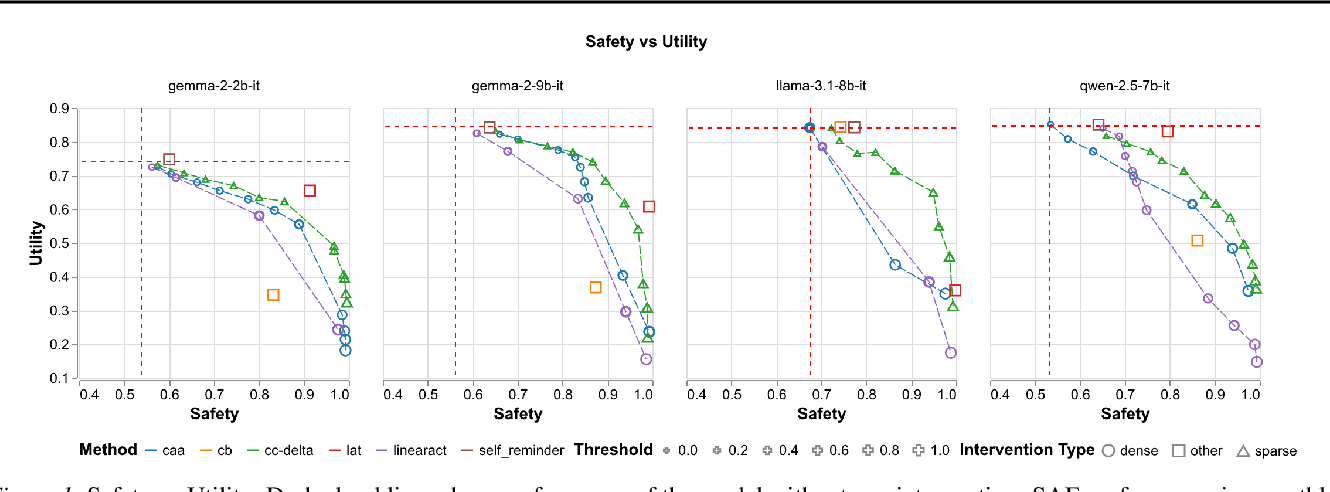
Figure 1 from Sparse Autoencoders are Capable LLM Jailbreak Mitigators ...

Paper page - Grass: Compute Efficient Low-Memory LLM Training with ...
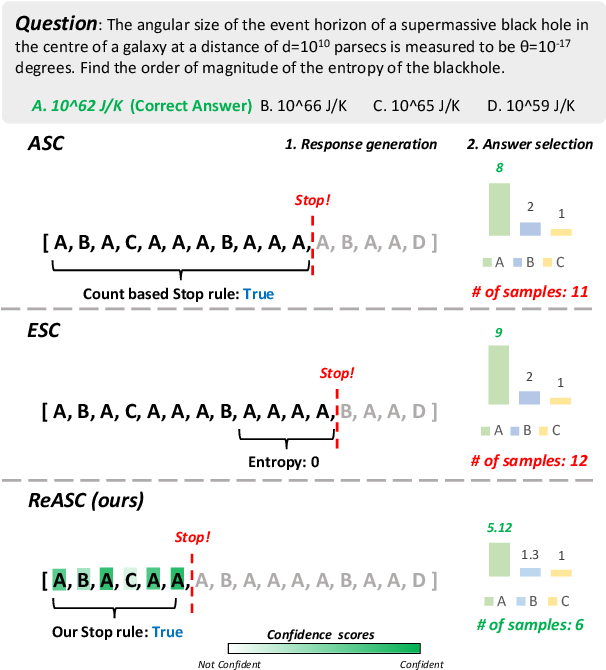
Figure 1 from Reliability-Aware Adaptive Self-Consistency for Efficient ...