
Figure 1 From Consistent Representation Learning Across Modalities For

Figure 1 from Consistent Representation Learning Across Modalities for ...
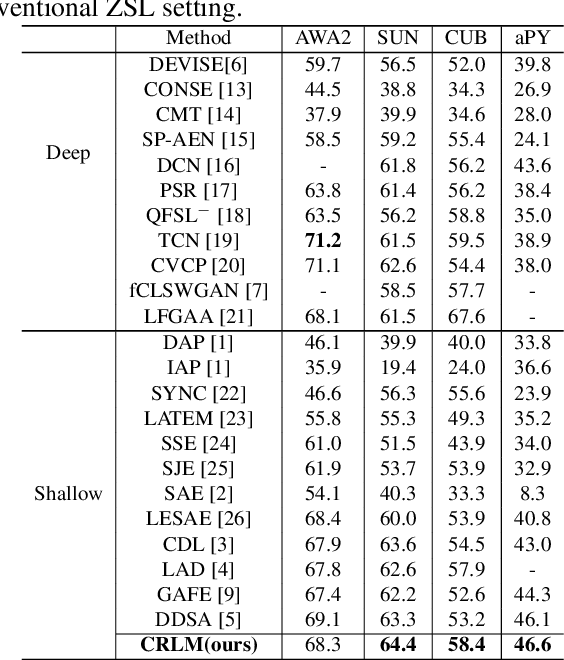
Table 1 from Consistent Representation Learning Across Modalities for ...

Figure 1 from Consistent Representation Learning for High Dimensional ...
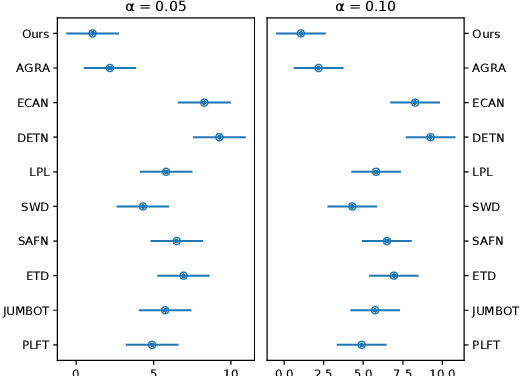
Figure 1 from Learning Consistent Global-Local Representation for Cross ...

Figure 1 from Representation learning via consistent assignment of ...

Figure 1 from Cross-modality Representation Interactive Learning for ...

Figure 1 from Representation Learning via Consistent Assignment of ...

Figure 1 from Cross-modality Representation Interactive Learning for ...

Figure 1 from Cross-modality Representation Interactive Learning for ...
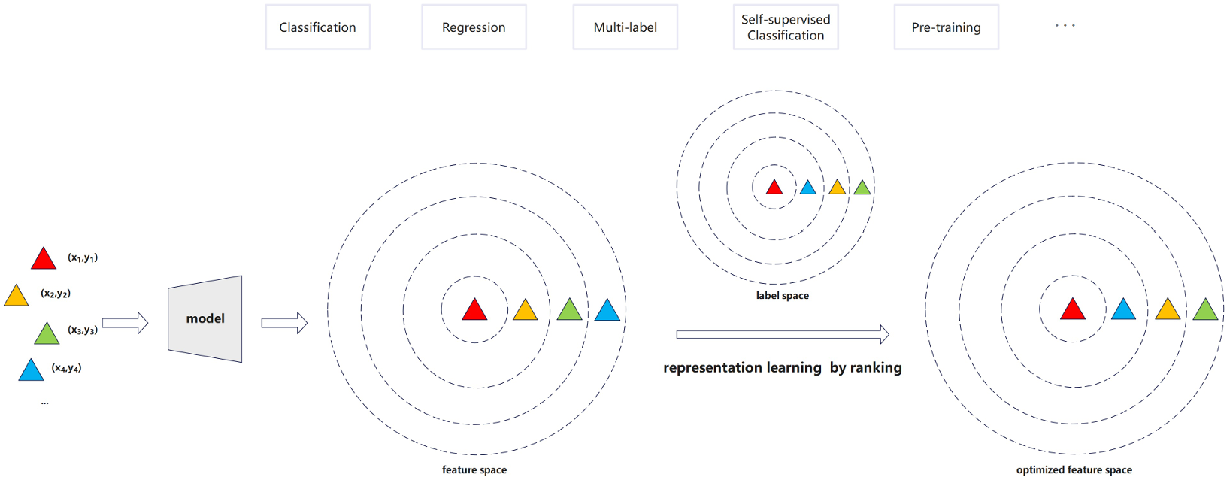
Figure 1 from Representation Learning by Ranking across multiple tasks ...
Advertisement Space (300x250)

Figure 1 from Towards Universal Sequence Representation Learning for ...

Figure 1 from CORE: Learning Consistent Ordinal REpresentations for ...

Figure 1 from Spatially Consistent Representation Learning | Semantic ...

Figure 1 from Value-Consistent Representation Learning for Data ...

Figure 1 from Semantically Consistent Multi-view Representation ...

Figure 1 from Learning Modality-Specific Representations for Visible ...

Figure 1 from Unbiased Embodied Visual Representation Learning with ...
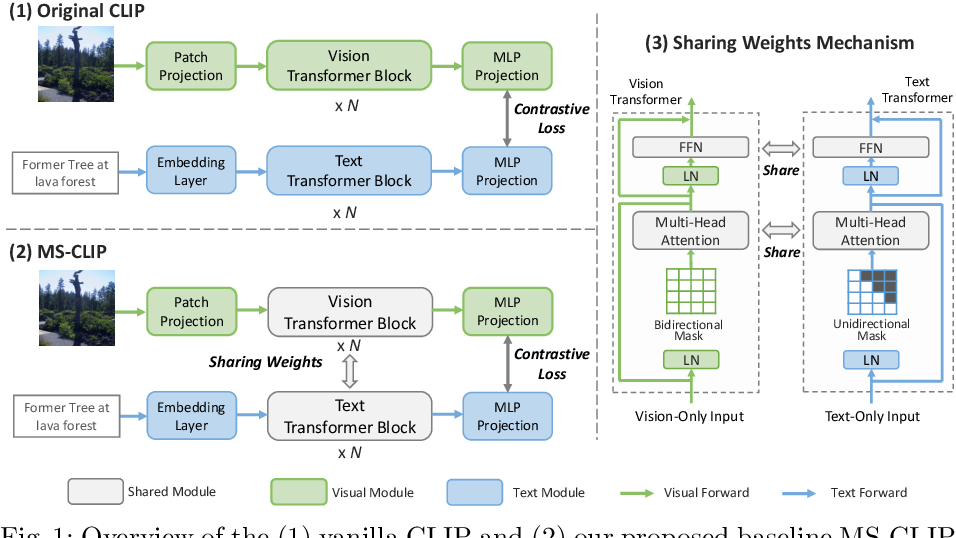
Figure 1 from Learning Visual Representation from Modality-Shared ...

Figure 1 from Multimodal Patient Representation Learning with Missing ...

Figure 1 from Multimodal Contrastive Training for Visual Representation ...
Advertisement Space (336x280)
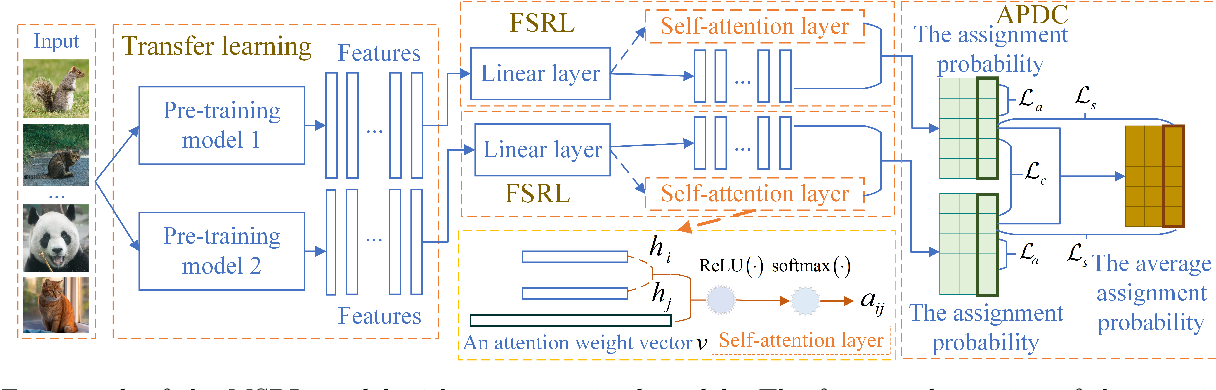
Figure 1 from Multiview Self-Representation Learning across ...

Figure 1 from Mix-up Consistent Cross Representations for Data ...

Figure 1 from Unified Multi-modal Unsupervised Representation Learning ...

Figure 1 from Self-Supervised Learning for Biologically-Inspired Place ...
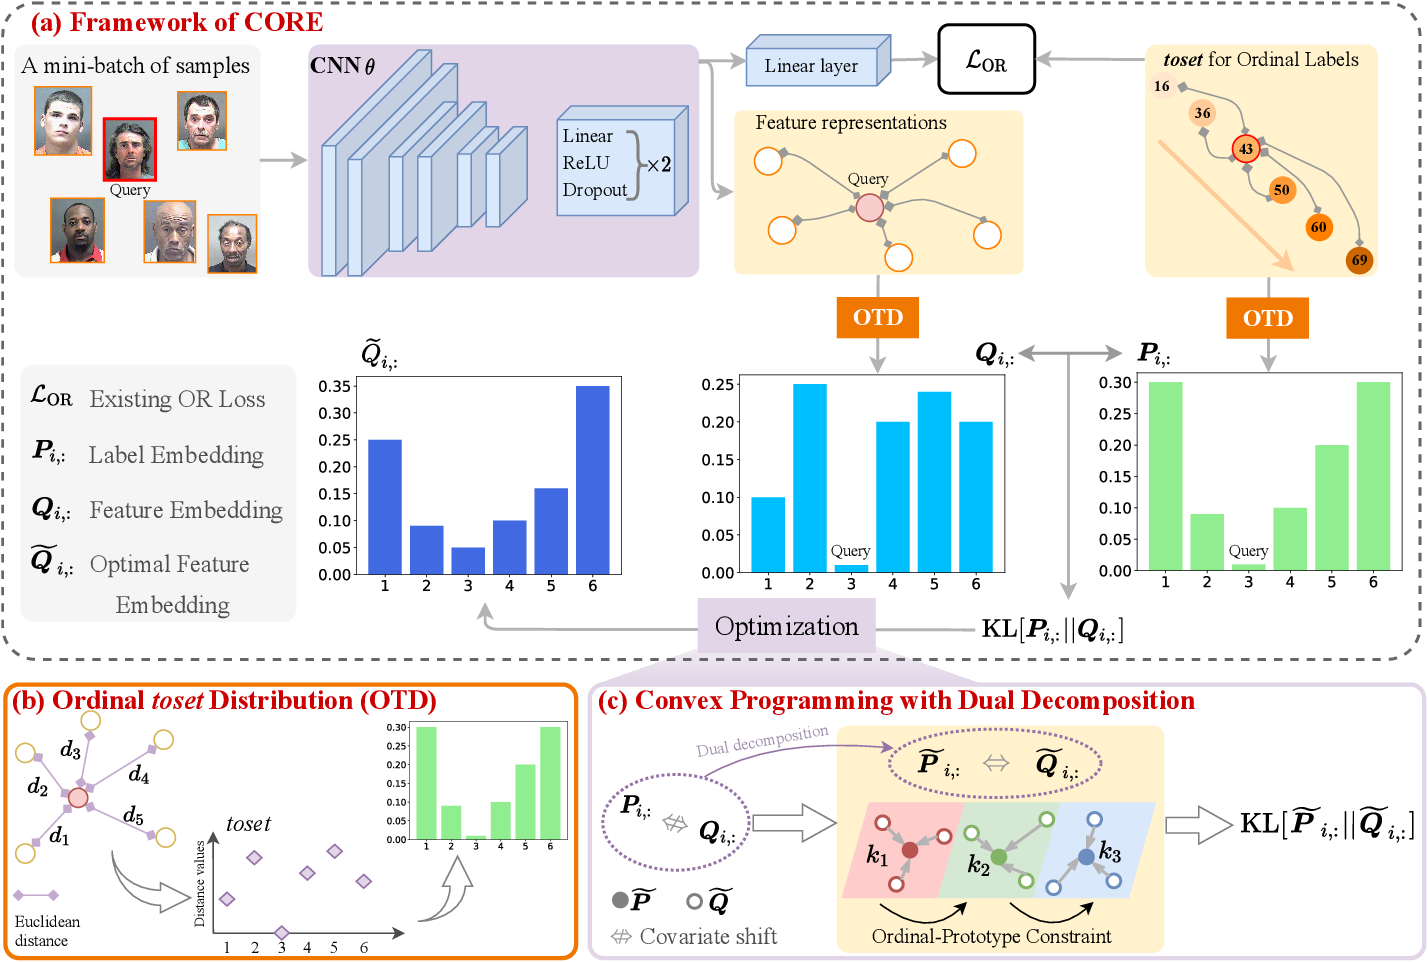
Figure 2 from CORE: Learning Consistent Ordinal REpresentations for ...

Figure 1 from Multimodal contrastive learning for unsupervised video ...

Figure 1 from Learning Temporally-Consistent Representations for Data ...

Figure 1 from Improving the Modality Representation with multi-view ...

(PDF) Cross-modality representation learning from transformer for ...
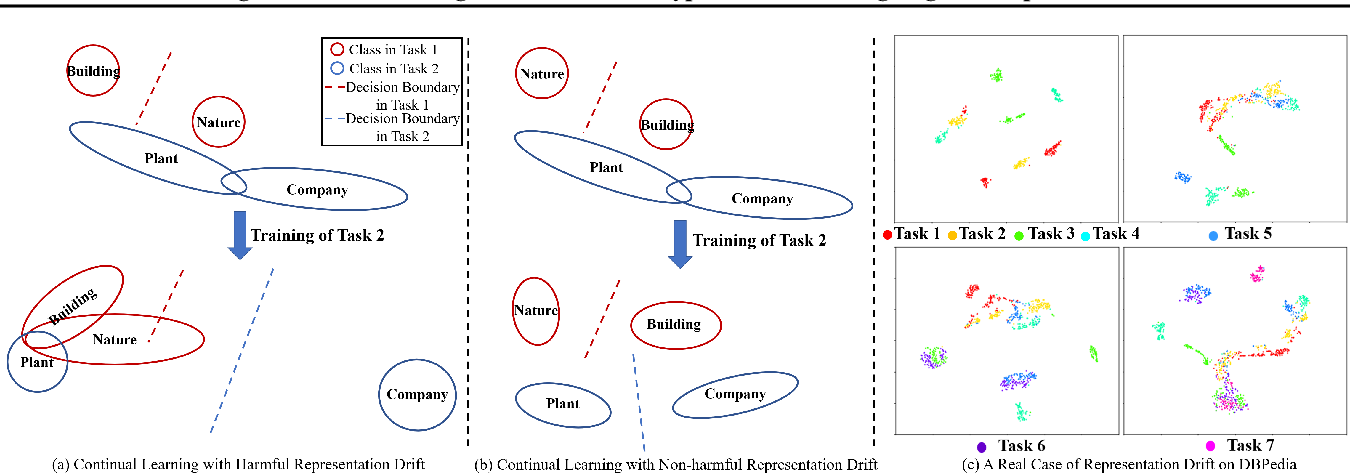
Figure 1 from Enhancing Continual Learning with Global Prototypes ...
Advertisement Space (336x280)
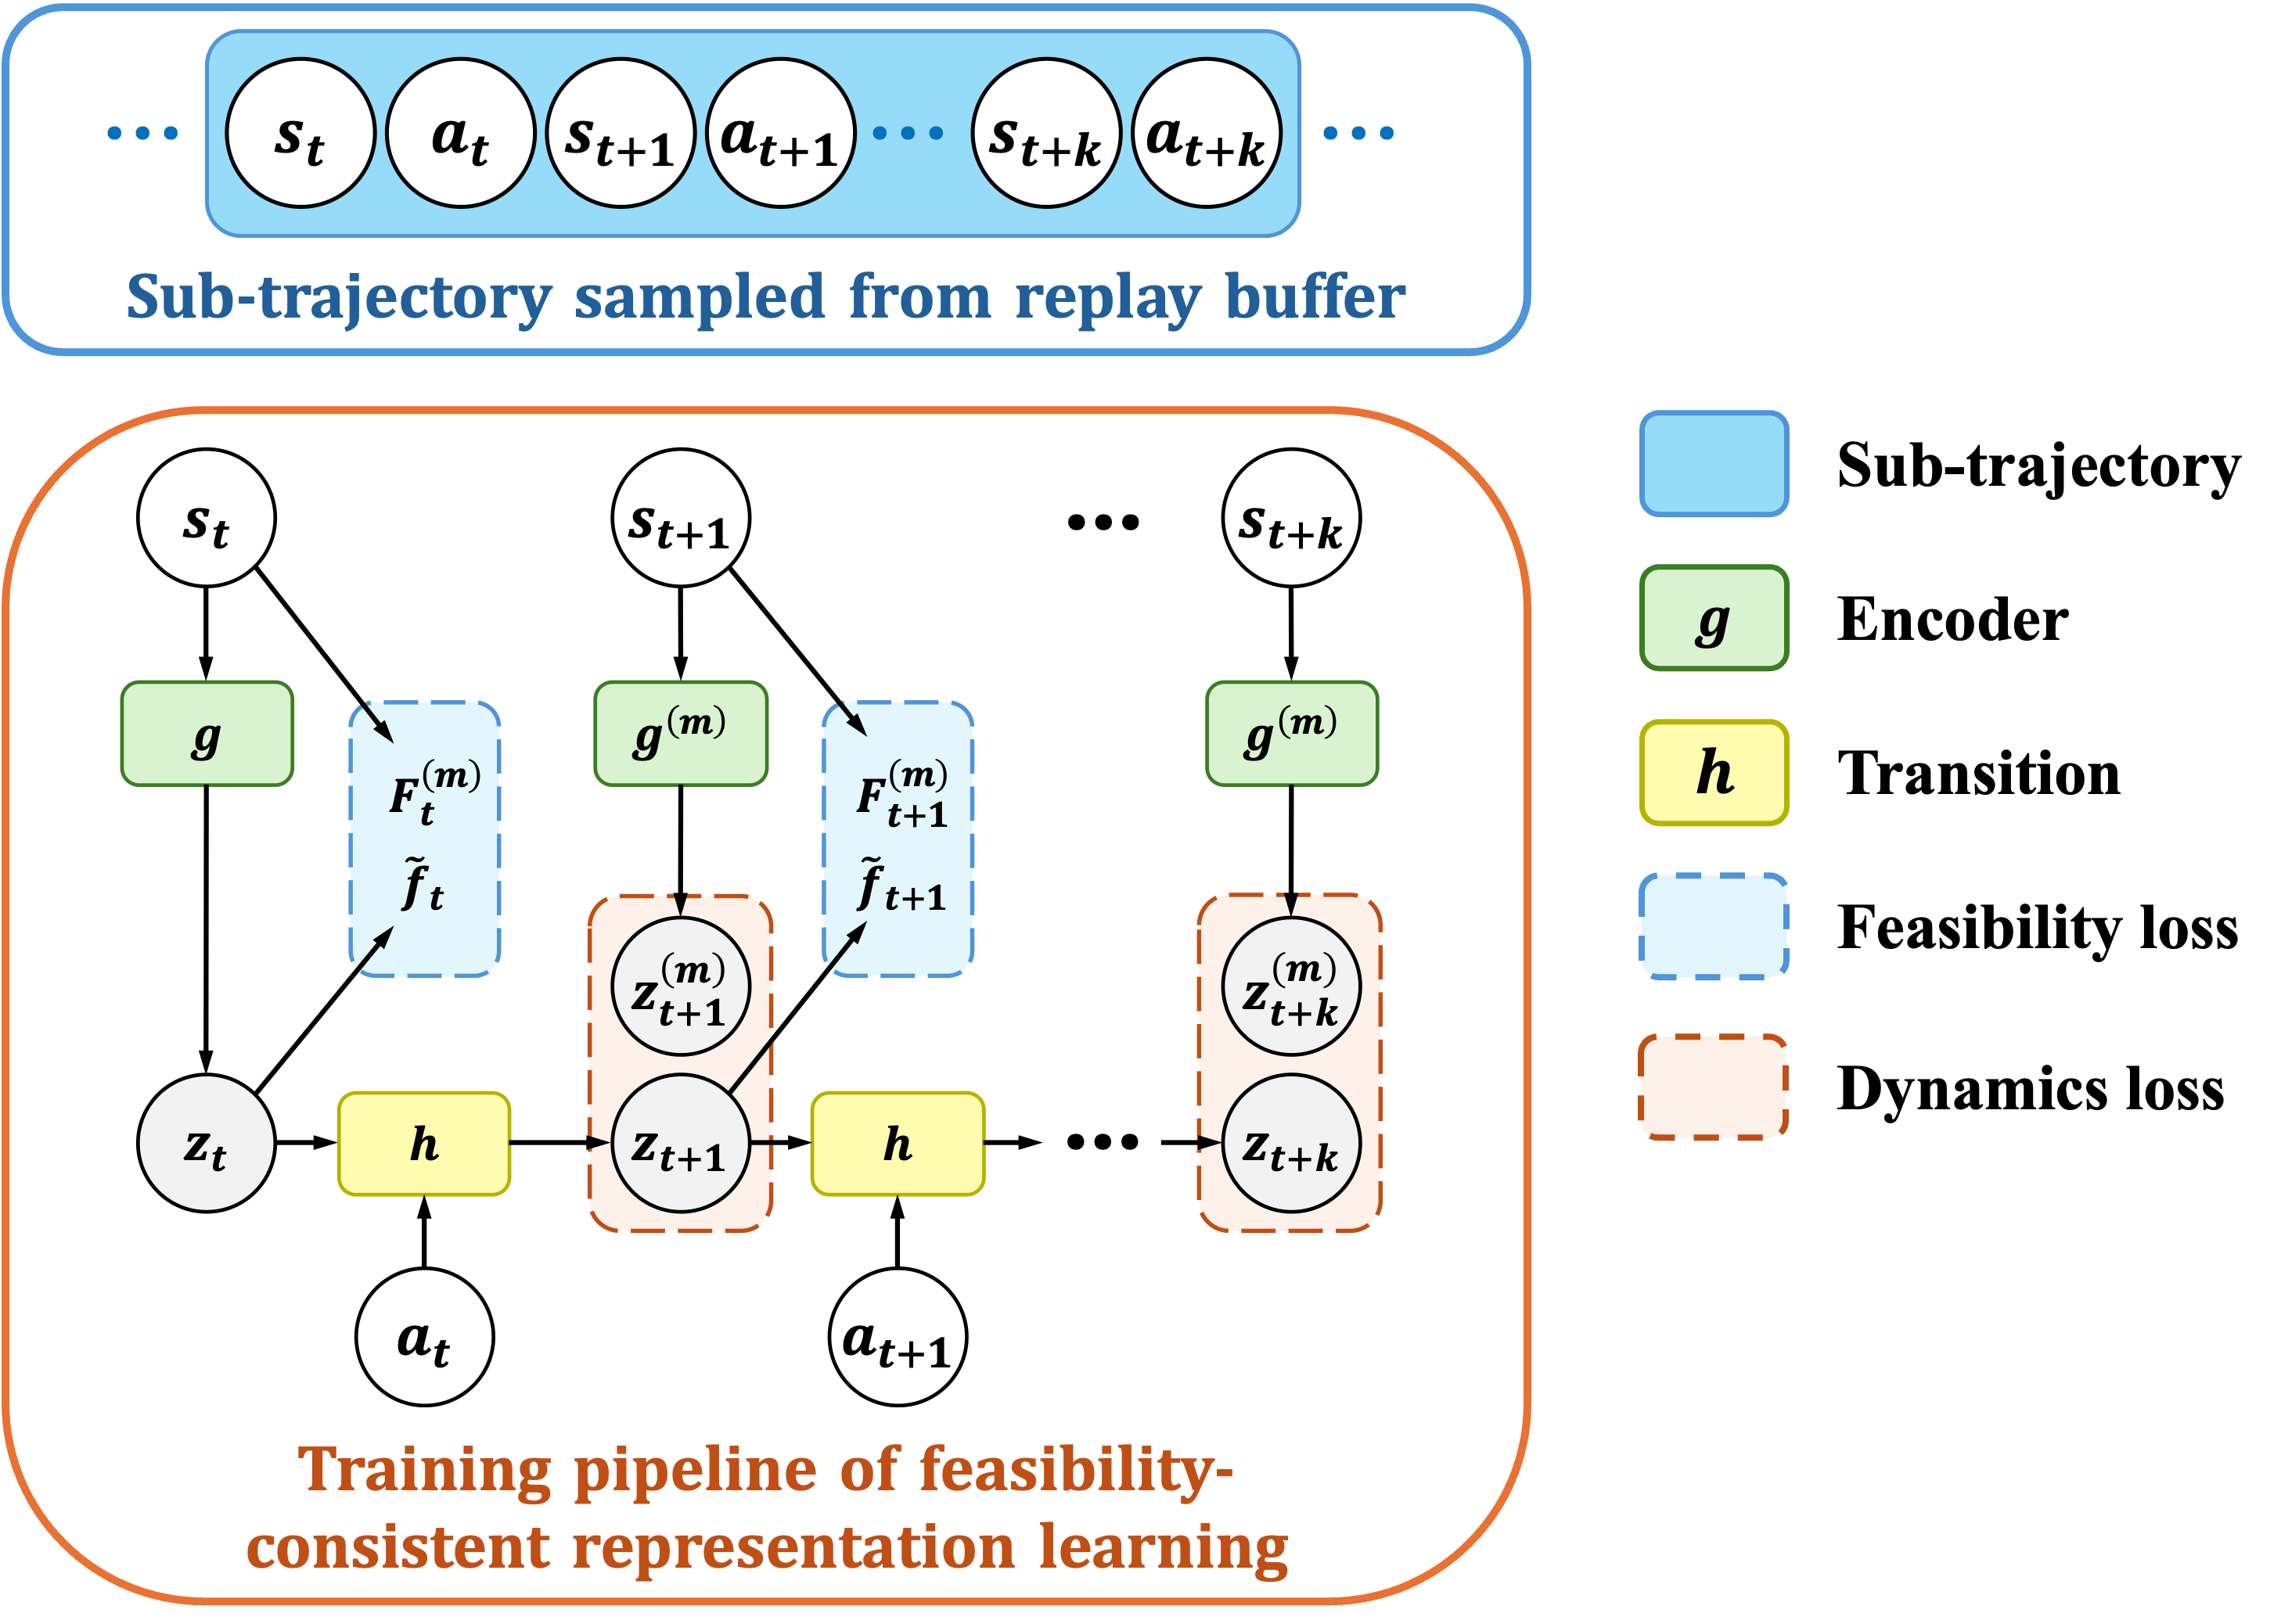
[2405.11718] Feasibility Consistent Representation Learning for Safe ...

Figure 1 from Dual Denoising Diffusion Model for Session-based Social ...
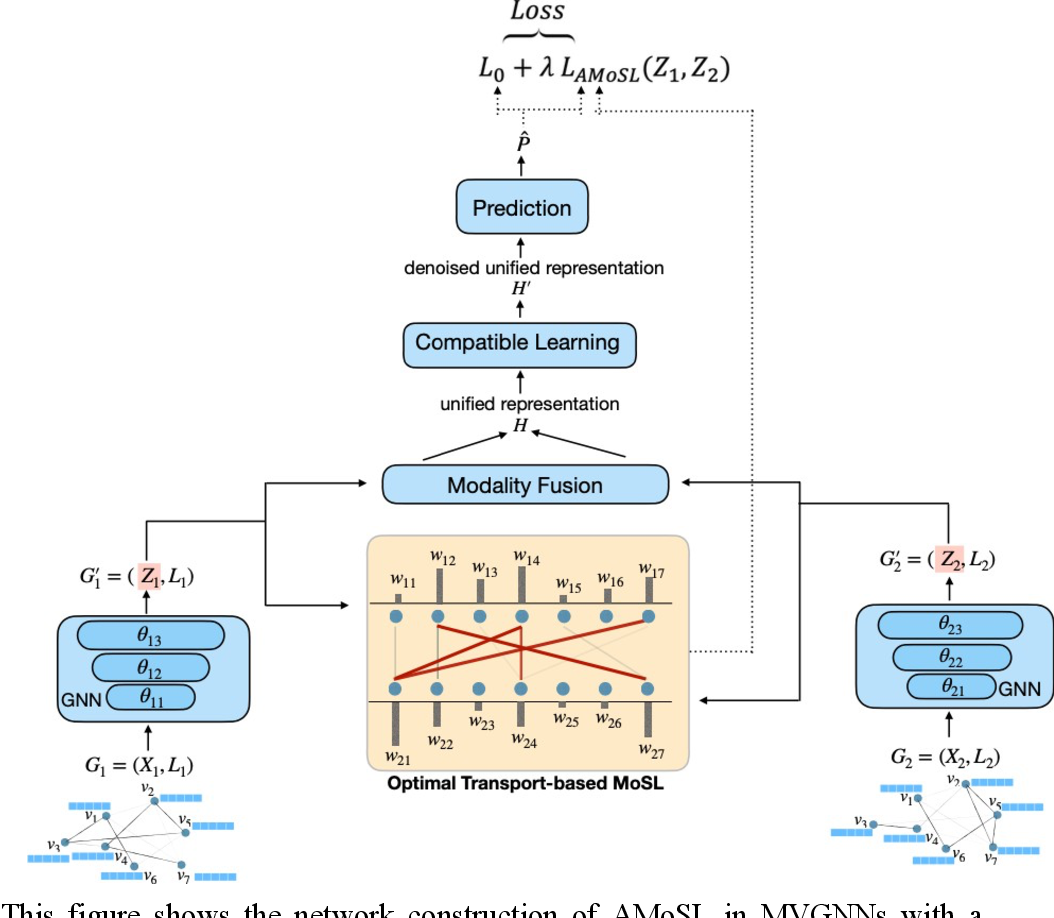
Figure 1 from AMOSL: Adaptive Modality-wise Structure Learning in Multi ...

Figure 1 from Asynchronous Multimodal Video Sequence Fusion via ...

Full article: Representation learning for geospatial data

(2021 - CVPR) Spatially Consistent Representation Learning | PDF ...