
Figure 1 From Enhancing Unsupervised Speech Recognition With Diffusion

Figure 1 from Enhancing Unsupervised Speech Recognition with Diffusion ...

Table 1 from Enhancing Unsupervised Speech Recognition with Diffusion ...
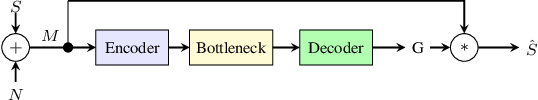
Figure 1 from Unsupervised Speech Enhancement with Speech Recognition ...

Figure 1 from Improving Speech Emotion Recognition with Unsupervised ...
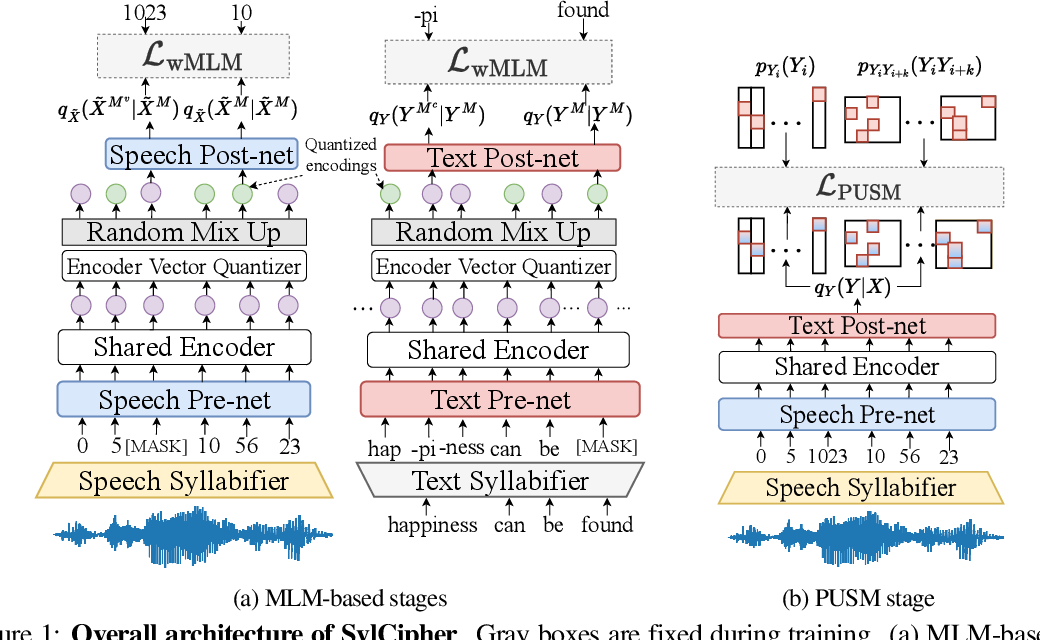
Figure 1 from Towards Unsupervised Speech Recognition at the Syllable ...

Figure 1 from Unsupervised domain adaptation for speech recognition ...

Figure 1 from Towards Unsupervised Speech Recognition and Synthesis ...

Figure 1 from A Theory of Unsupervised Speech Recognition | Semantic ...

(PDF) Enhancing Unsupervised Speech Recognition with Diffusion GANs

Figure 1 from End-To-End Multi-Accent Speech Recognition with ...
Advertisement Space (300x250)

Enhancing Unsupervised Speech Recognition with Diffusion GANs | URC ...

Figure 1 from Speech Enhancement Network with Unsupervised Attention ...

Figure 1 from Universal Speech Enhancement with Score-based Diffusion ...

Figure 1 from Unsupervised Domain Adaptation for Speech Recognition via ...

Figure 2 from Unsupervised Speech Recognition with N-skipgram and ...

Figure 1 from Unsupervised Speech Enhancement using Data-defined Priors ...

Figure 1 from uSee: Unified Speech Enhancement And Editing with ...
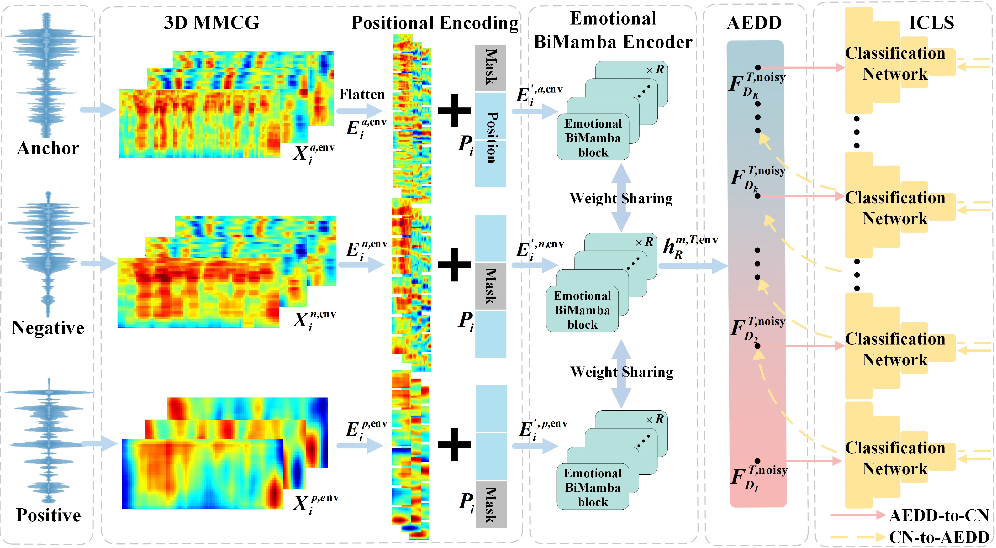
Figure 1 from Enhanced Speech Emotion Recognition in Noisy Environments ...

Figure 1 from Unsupervised pre-training for sequence to sequence speech ...

Figure 1 from Unsupervised Adaptive Speaker Recognition by Coupling ...
Advertisement Space (336x280)

Figure 1 from Bridging Speech and Textual Pre-Trained Models With ...

Figure 1 from Unsupervised Diffusion Model for Sensor-based Human ...

Figure 1 from Unsupervised Noise Adaptive Speech Enhancement by ...

Figure 1 from Unsupervised Speech Enhancement using Data-defined Priors ...

Figure 1 from Unsupervised Fuzzy Inference System for Speech Emotion ...

Figure 1 from Unsupervised Statistical Feature-Guided Diffusion Model ...
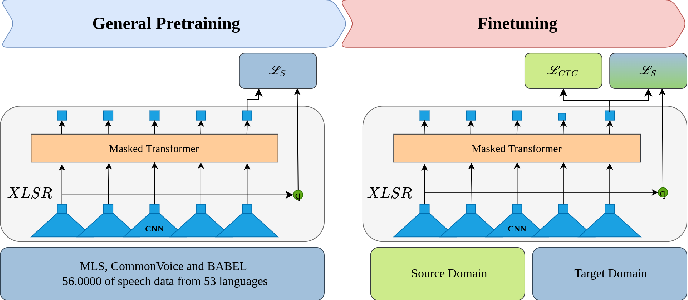
Figure 1 from Sample-Efficient Unsupervised Domain Adaptation of Speech ...

Figure 1 from Unsupervised Speech Segmentation and Variable Rate ...

Figure 1 from Unified Architecture and Unsupervised Speech ...

Figure 1 from Cross-Domain Diffusion Based Speech Enhancement for Very ...
Advertisement Space (336x280)

Figure 1 from Unsupervised Human Activity Recognition through Two-stage ...

Figure 1 from Diffusion-based Signal Refiner for Speech Enhancement ...
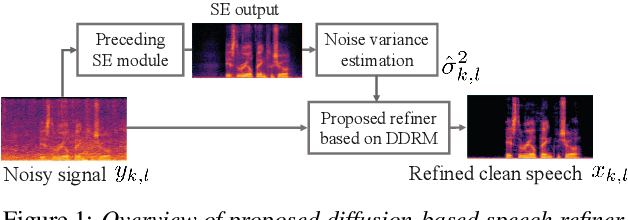
Figure 1 from A Versatile Diffusion-based Generative Refiner for Speech ...
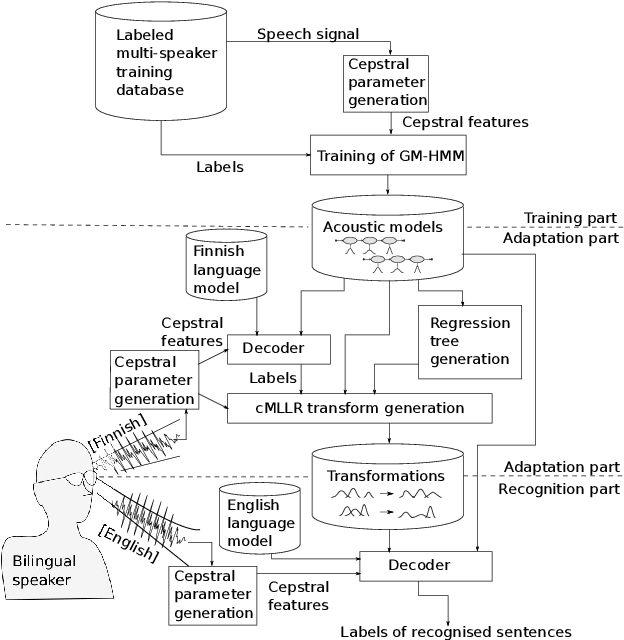
Figure 1 from Unsupervised cross-lingual speaker adaptation for ...

Figure 1 from Unsupervised Domain Adaptation Integrating Transformer ...
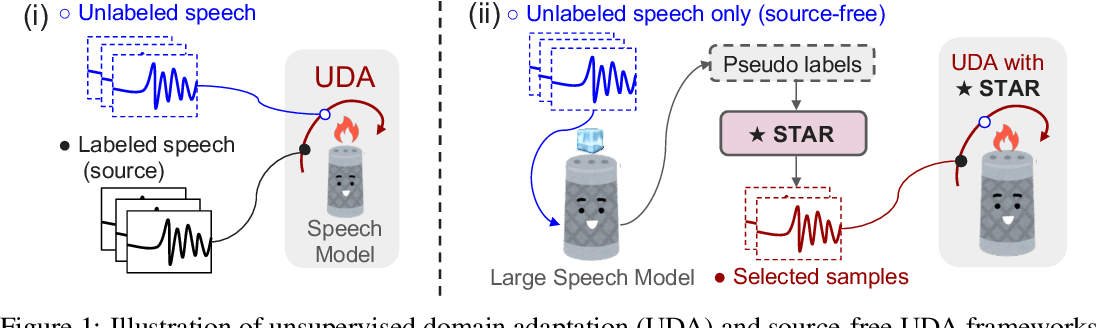
Figure 1 from Self-Taught Recognizer: Toward Unsupervised Adaptation ...