
Figure 1 From Exploring Multimodal Pre Trained Models For Speech

Figure 1 from Exploring Multimodal Pre-trained Models for Speech ...

Figure 1 from Exploring Pre-trained Speech Model for Articulatory ...
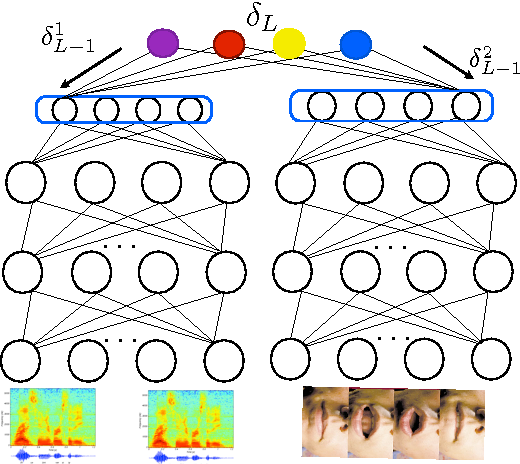
Figure 1 from Deep multimodal learning for Audio-Visual Speech ...

Figure 1 from Multimodal Speech Emotion Recognition Using Modality ...

Figure 1 from Exploring Multimodal Data Approach in Natural Language ...

Figure 1 from Textually Pretrained Speech Language Models | Semantic ...

Figure 1 from Adapting Self-Supervised Models to Multi-Talker Speech ...

Figure 1 from MultiFusion: Fusing Pre-Trained Models for Multi-Lingual ...
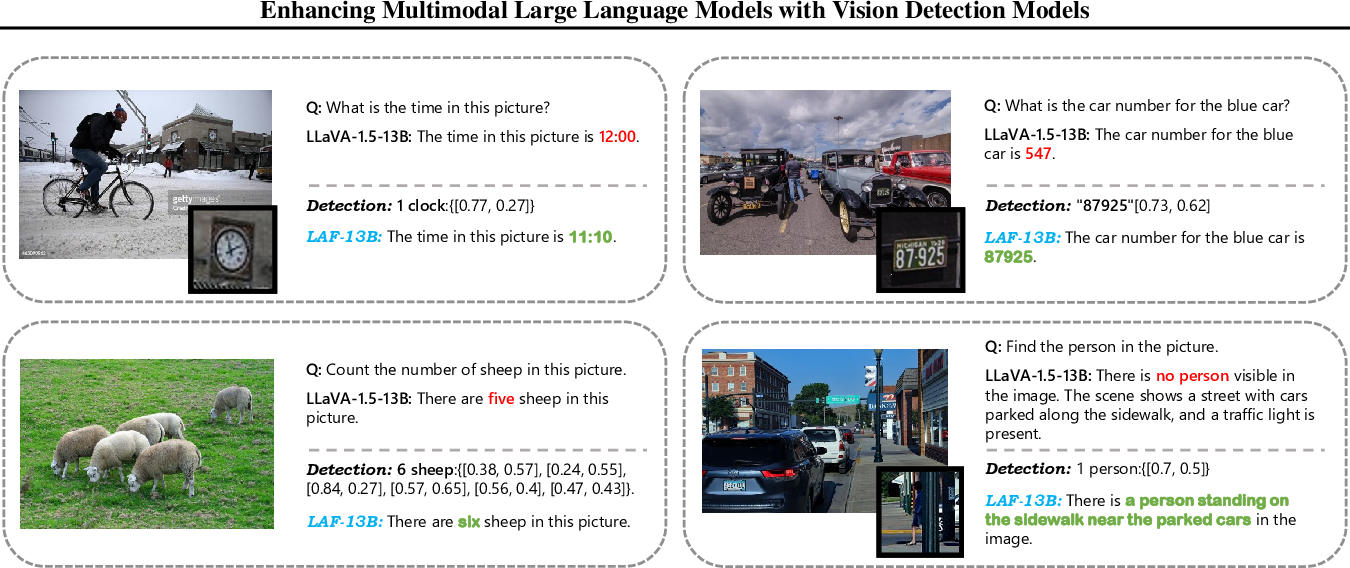
Figure 1 from Enhancing Multimodal Large Language Models with Vision ...

Figure 1 from Multilingual Zero Resource Speech Recognition Base on ...
Advertisement Space (300x250)

Figure 1 from Multimodal Large Language Models: A Survey | Semantic Scholar
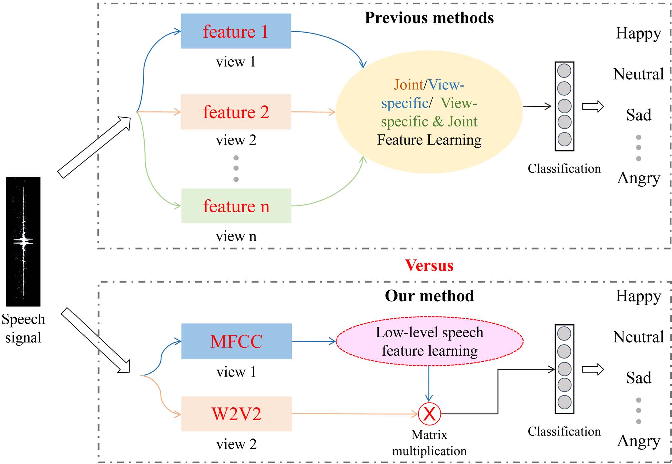
Figure 1 from Improving Pre-Trained Model-Based Speech Emotion ...

Figure 1 from Speech Separation based on pre-trained model and Deep ...
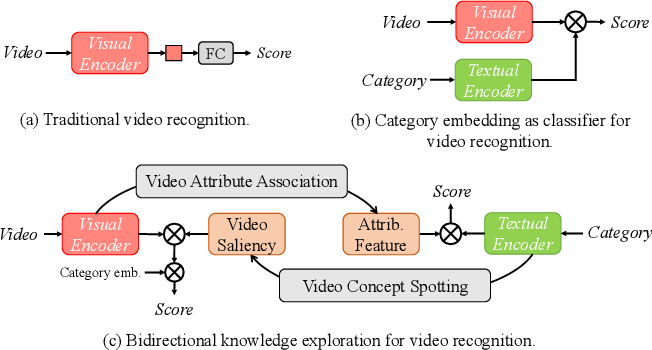
Figure 1 from Bidirectional Cross-Modal Knowledge Exploration for Video ...
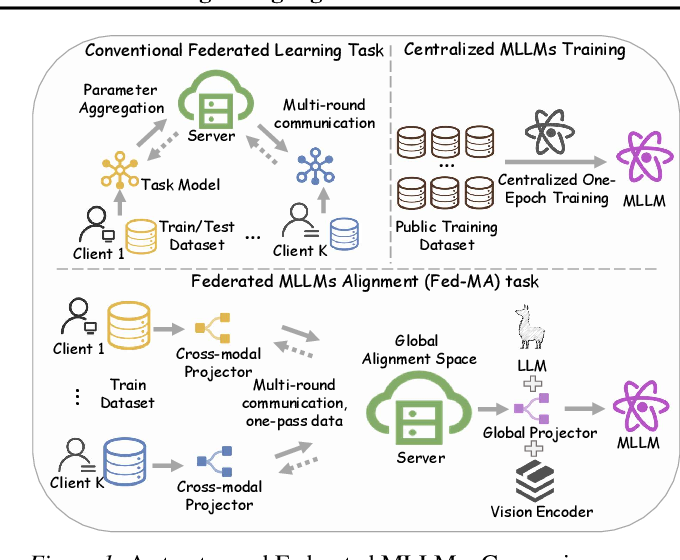
Figure 1 from A Step Toward Federated Pretraining of Multimodal Large ...

Free Video: Leveraging Pre-trained Models for Speech Processing from ...

Figure 2 from Multimodal foundation models are better simulators of the ...
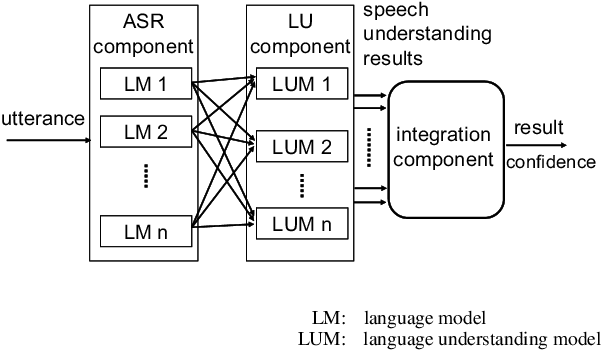
Figure 1 from Improving speech understanding accuracy with limited ...

Figure 1 from Bidirectional Cross-Modal Knowledge Exploration for Video ...

Benchmarking Pretrained Models for Speech Emotion Recognition: A Focus ...
Advertisement Space (336x280)
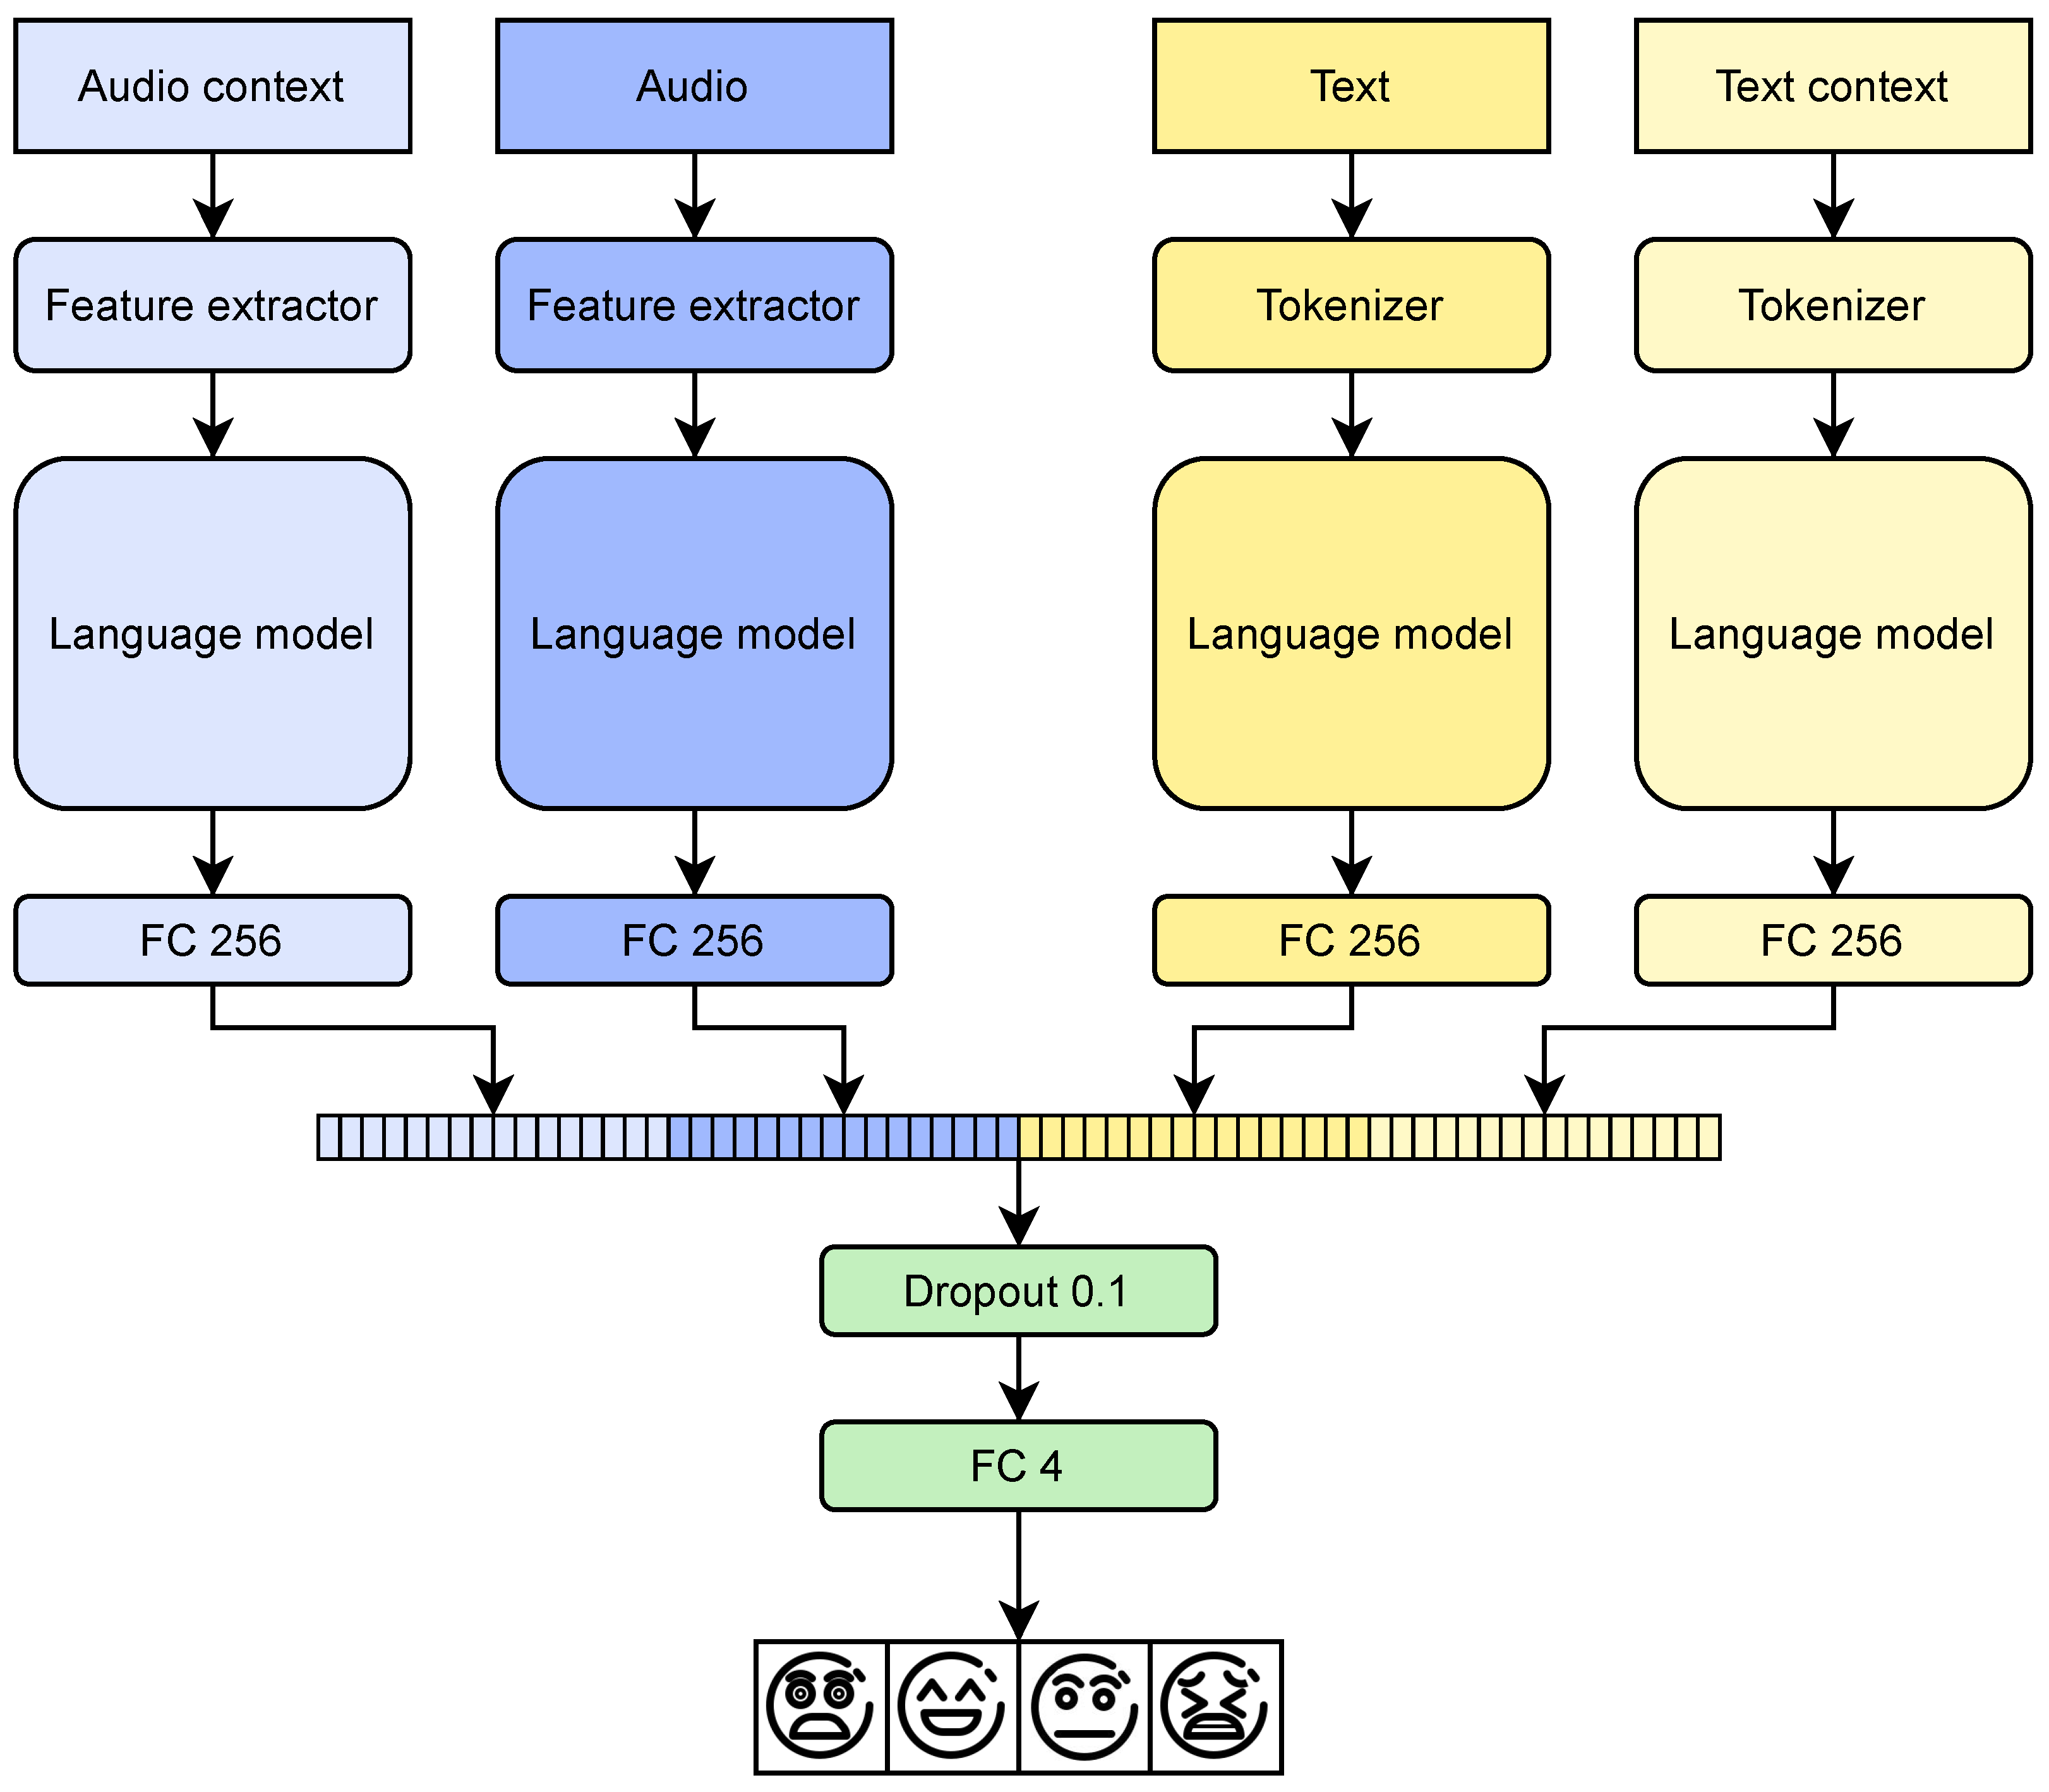
Small Language Models for Speech Emotion Recognition in Text and Audio ...

Figure 1 from Generative Pretraining in Multimodality | Semantic Scholar

Multimodal Unsupervised Speech Translation for Recognizing and ...
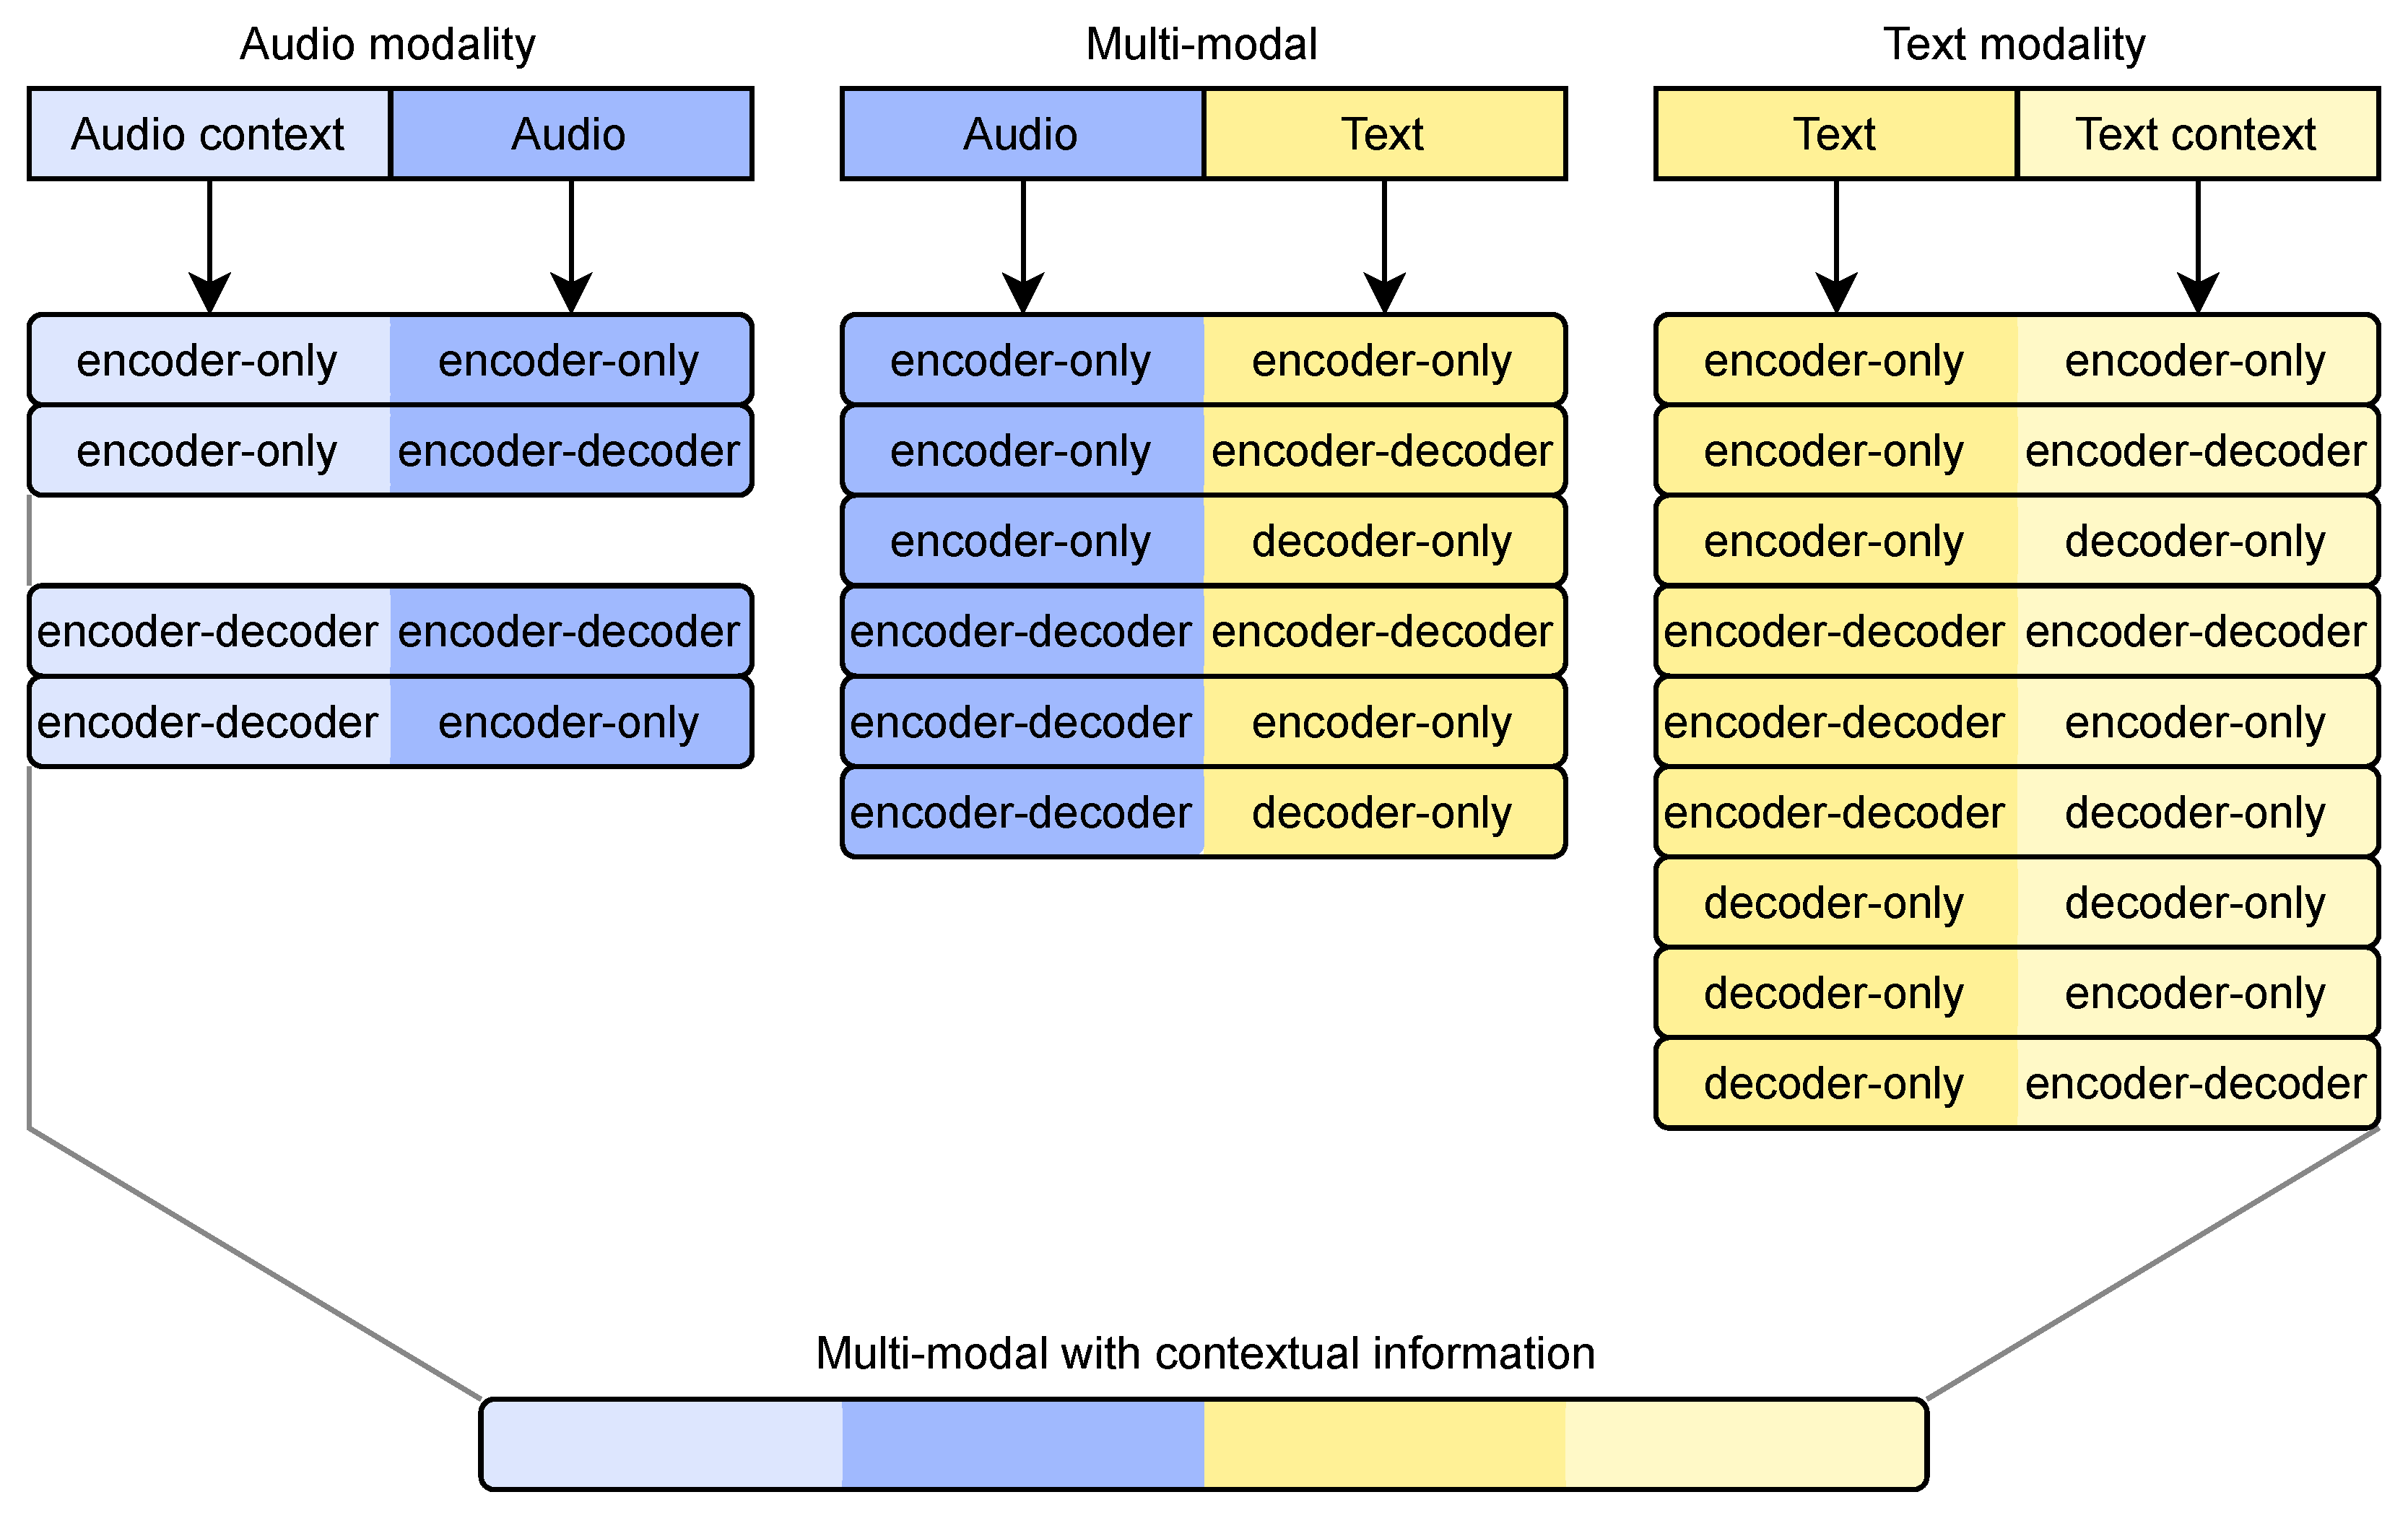
Small Language Models for Speech Emotion Recognition in Text and Audio ...

On Pre-training of Multimodal Language Models Customized for Chart ...
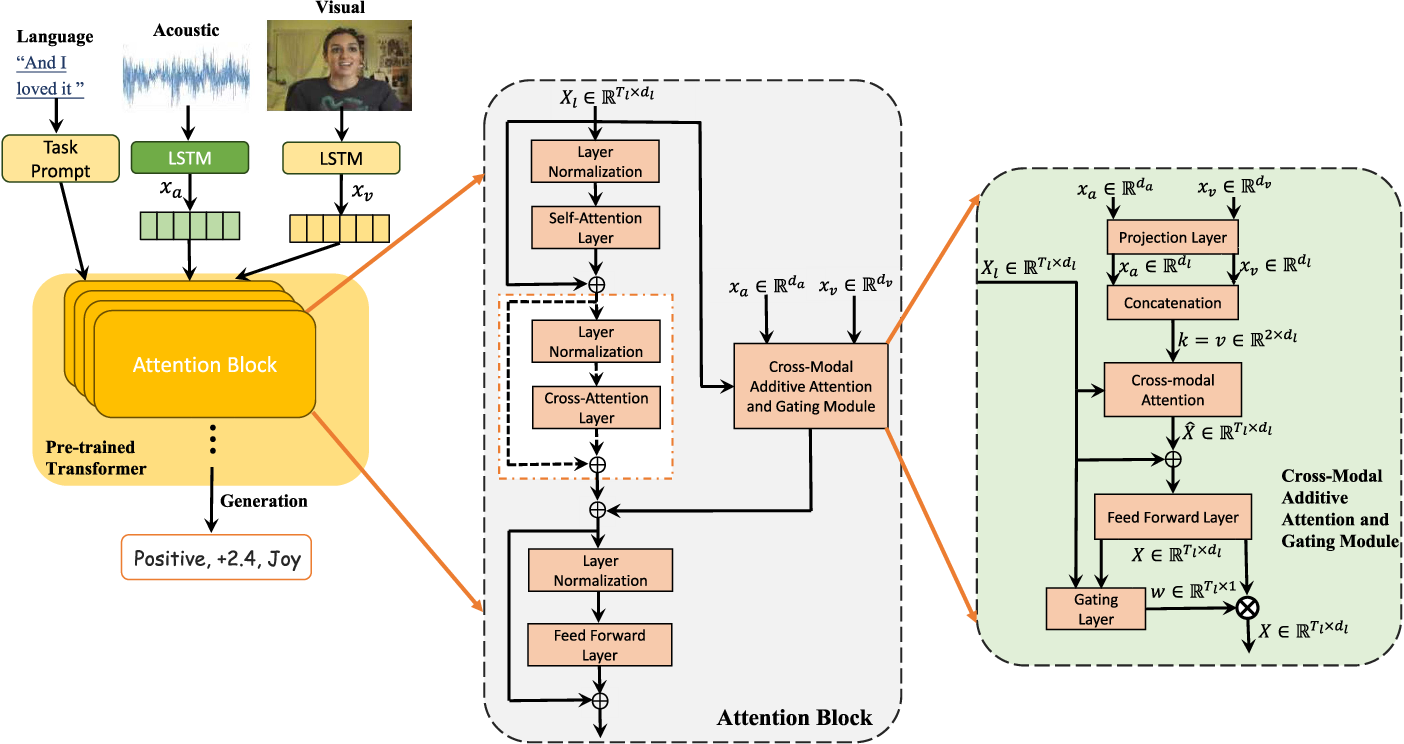
Figure 3 from Injecting Multimodal Information Into Pre-Trained ...

Integrating Pre-Trained Speech and Language Models for End-to-End ...
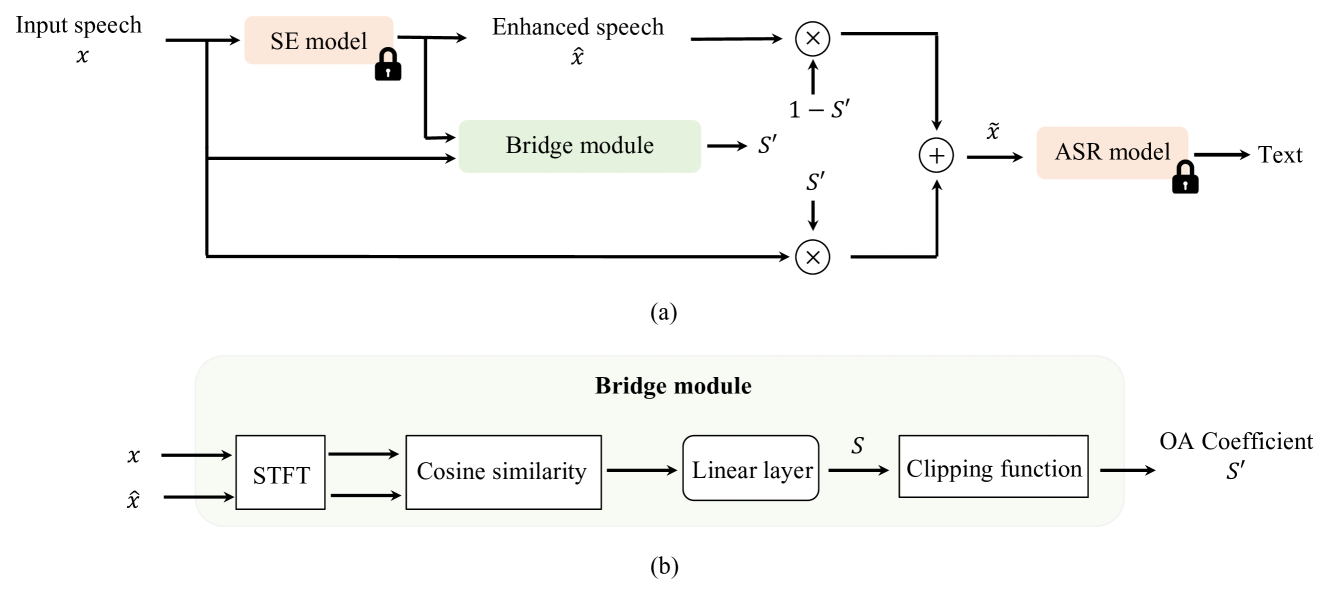
Integrating Pre-Trained Speech and Language Models for End-to-End ...

Figure 1 from A Closer Look at the Robustness of Vision-and-Language ...

Figure 1 from A Noise-Robust Self-Supervised Pre-Training Model Based ...
Advertisement Space (336x280)

Exploring Mode Connectivity for Pre-trained Language Models | Underline

Figure 1 from Memobert: Pre-Training Model with Prompt-Based Learning ...
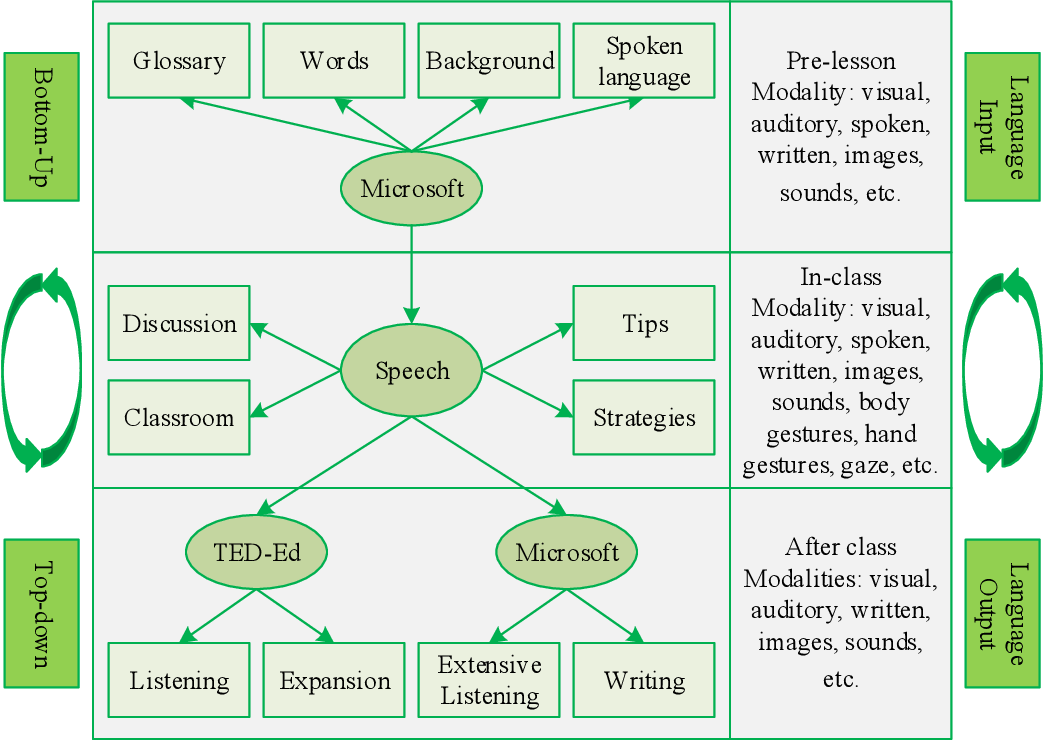
Figure 1 from A Study on the Improvement of English Listening ...

We propose to train multimodal speech recognition models while randomly ...

Integrating Pre-Trained Speech and Language Models for End-to-End ...

Exploring Self-supervised Pre-trained ASR Models For Dysarthric and ...