
Figure 1 From Focus Internal Mllm Representations For Efficient Fine
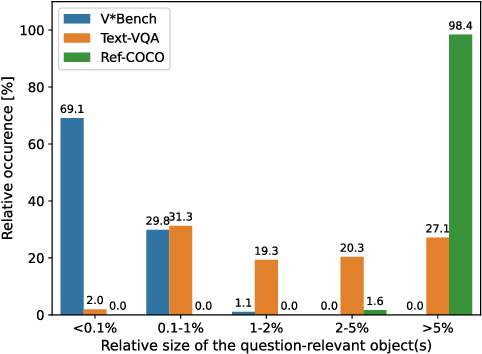
Figure 1 from FOCUS: Internal MLLM Representations for Efficient Fine ...

Table 1 from FOCUS: Internal MLLM Representations for Efficient Fine ...
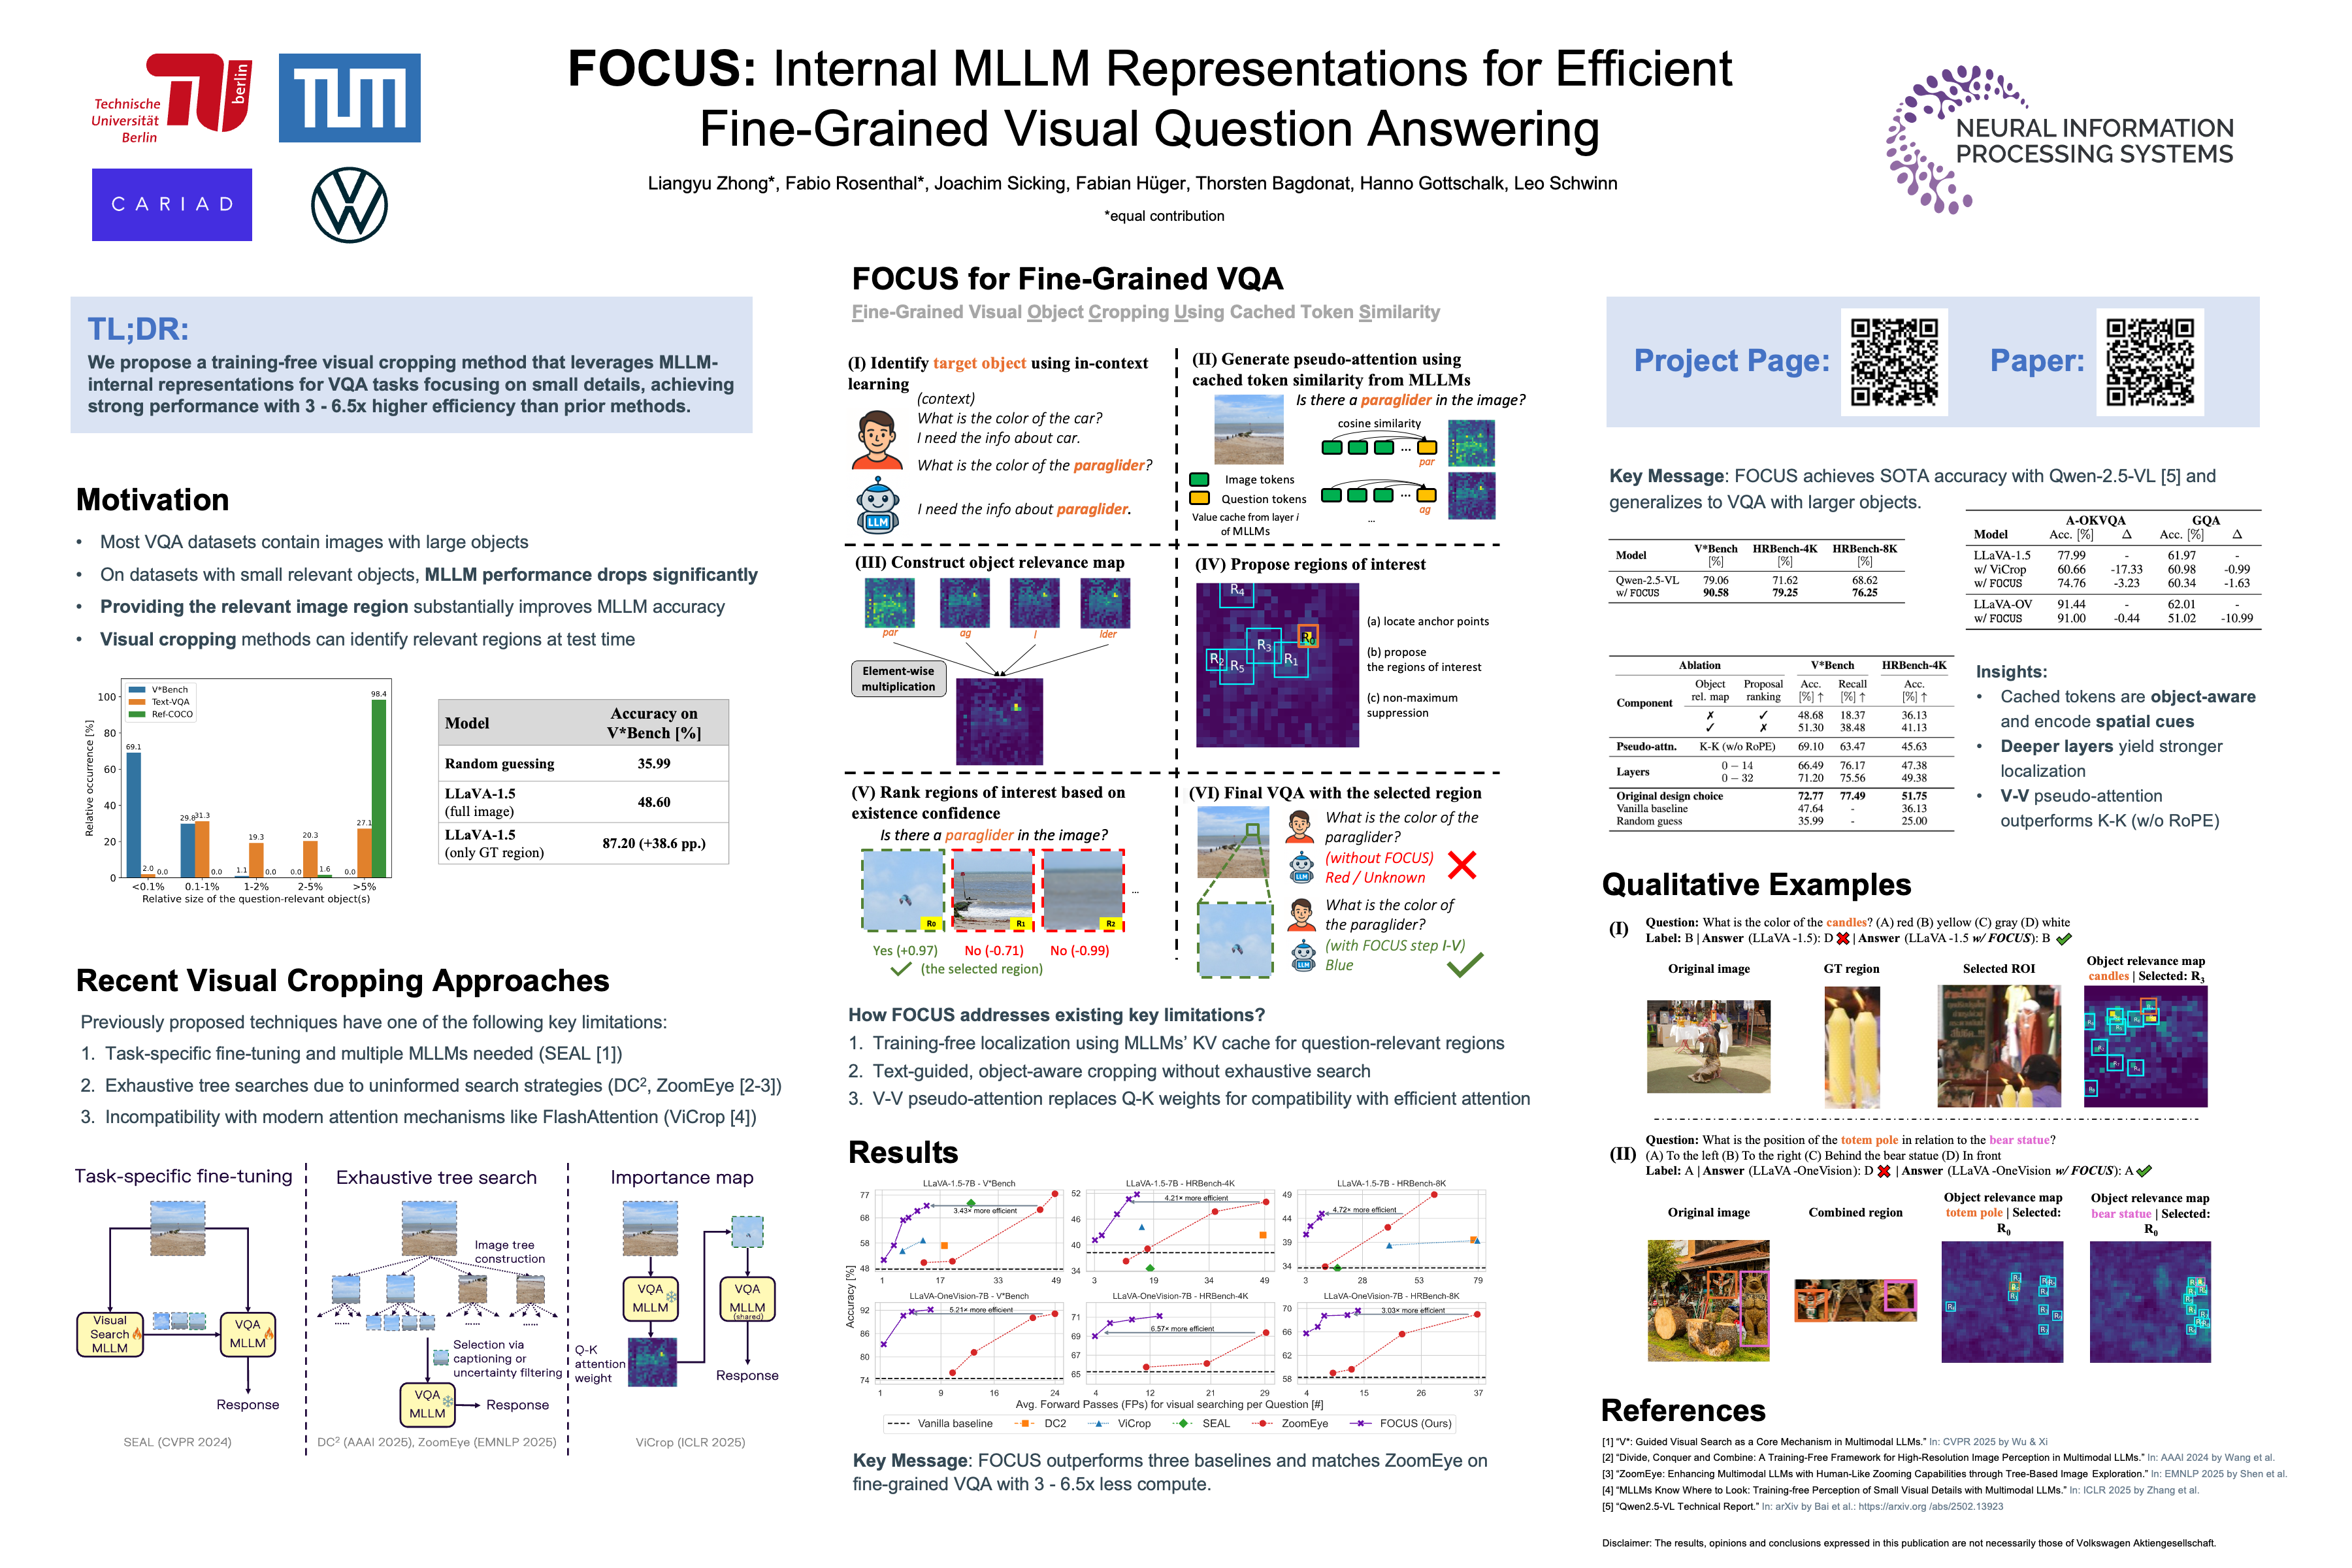
NeurIPS Poster FOCUS: Internal MLLM Representations for Efficient Fine ...
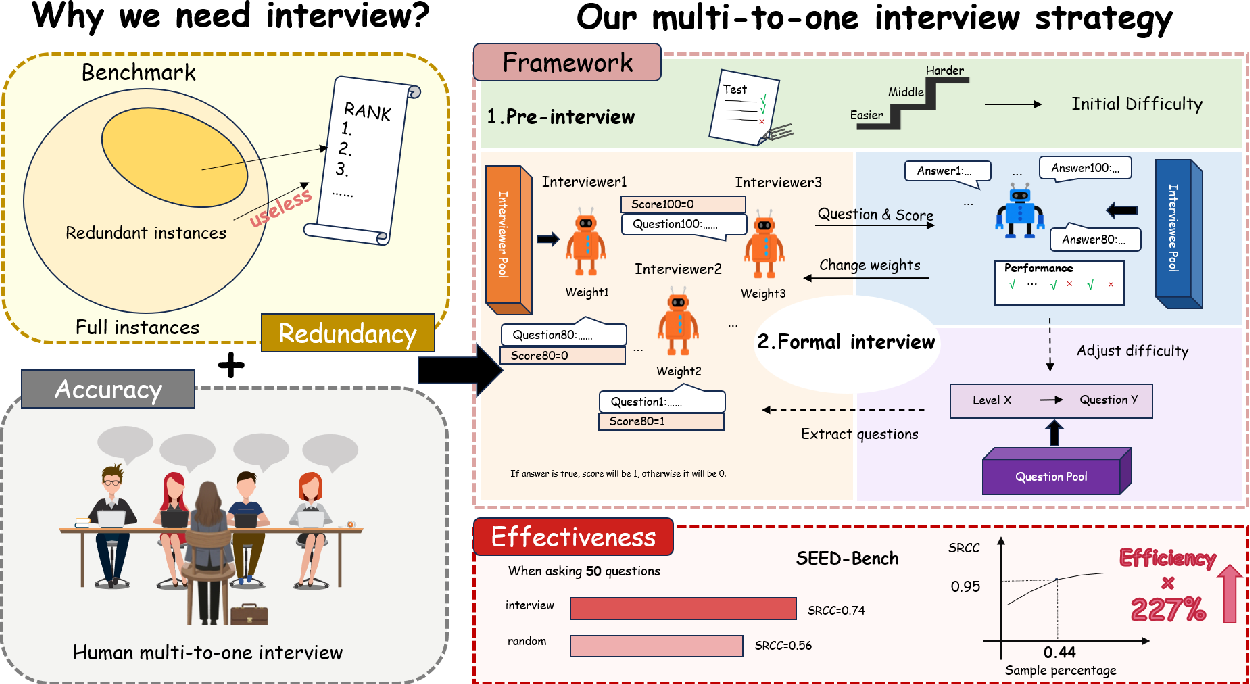
Figure 1 from A Multi-To-One Interview Paradigm for Efficient MLLM ...

Figure 1 from Guiding Cross-Modal Representations with MLLM Priors via ...

Figure 1 from Guiding Cross-Modal Representations with MLLM Priors via ...

Figure 1 from AIC MLLM: Autonomous Interactive Correction MLLM for ...

Figure 1 from AIC MLLM: Autonomous Interactive Correction MLLM for ...

Figure 1 from Low-latency MLLM Inference with Spatiotemporal ...
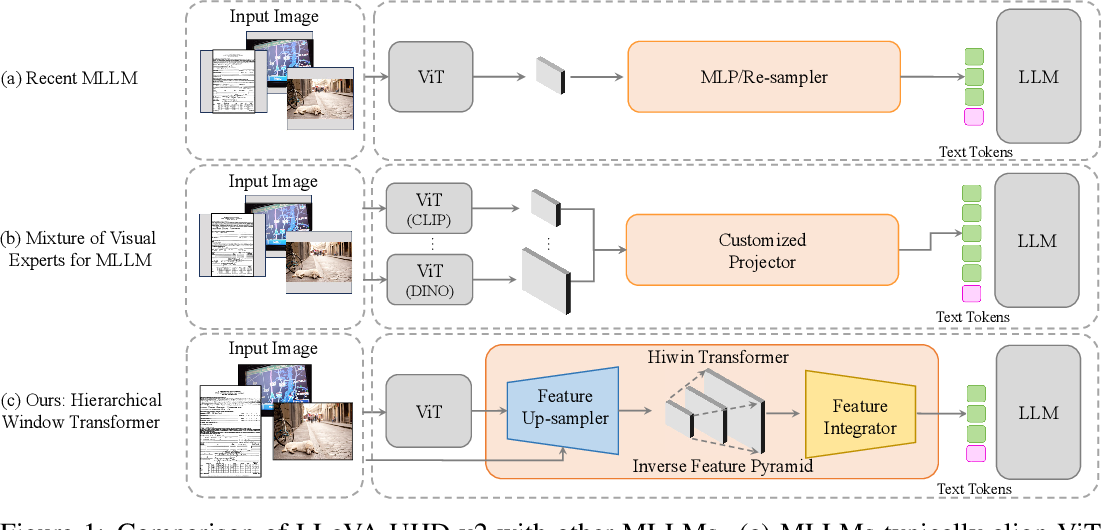
Figure 1 from LLaVA-UHD v2: an MLLM Integrating High-Resolution Feature ...
Advertisement Space (300x250)
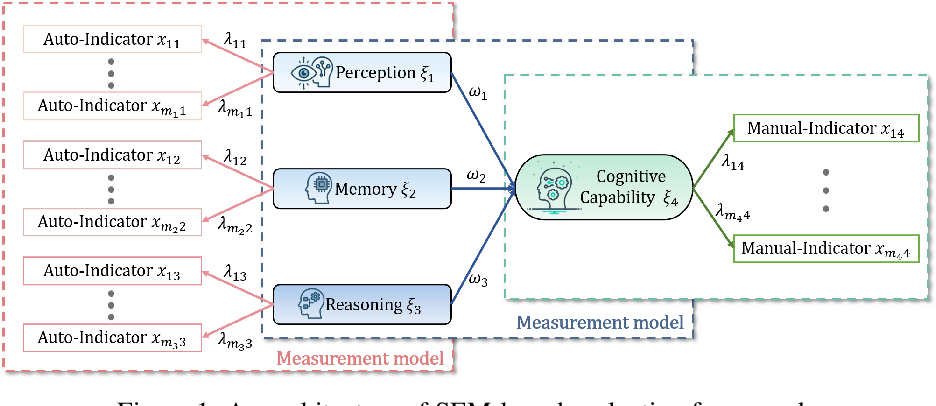
Figure 1 from Aligning MLLM Benchmark With Human Preferences via ...
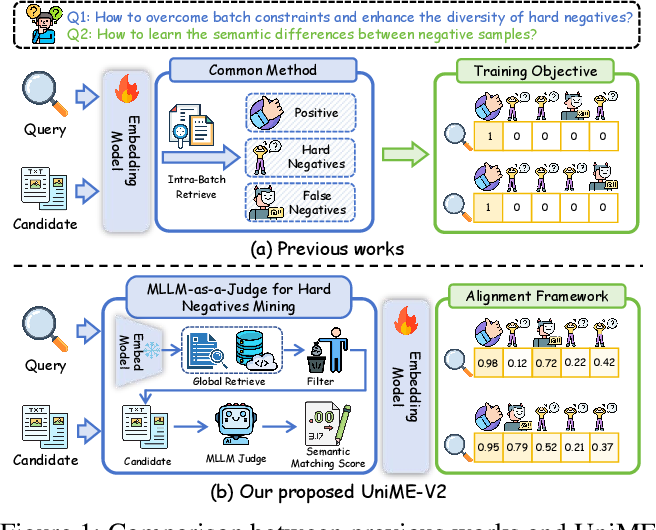
Figure 1 from UniME-V2: MLLM-as-a-Judge for Universal Multimodal ...
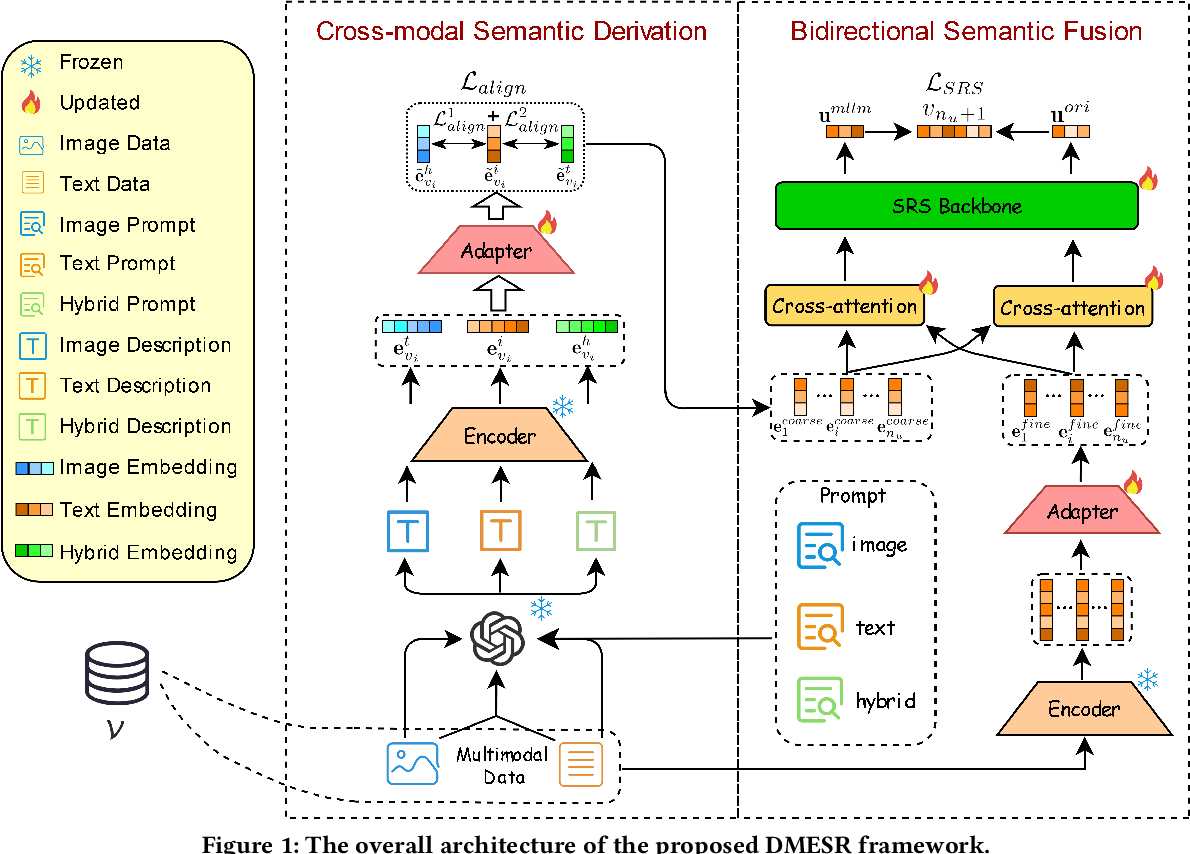
Figure 1 from DMESR: Dual-view MLLM-based Enhancing Framework for ...
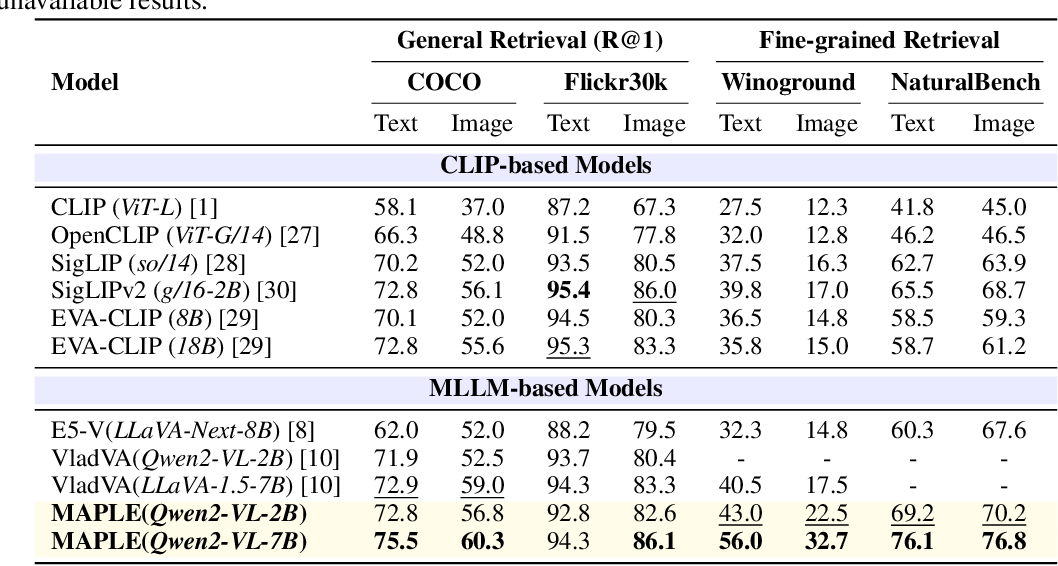
Table 1 from Guiding Cross-Modal Representations with MLLM Priors via ...

Figure 1 from OCC-MLLM:Empowering Multimodal Large Language Model For ...

Figure 1 from Natural Language Understanding and Inference with MLLM in ...
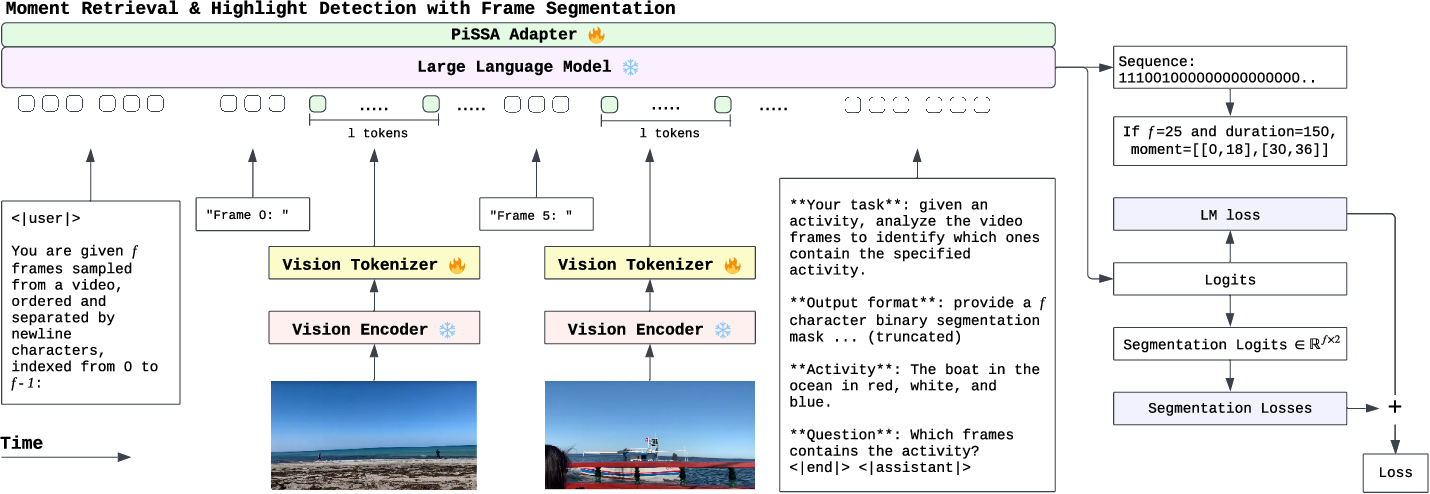
Figure 1 from Moment and Highlight Detection via MLLM Frame ...

Don't Just Follow MLLM Plans: Robust and Efficient Planning for Open ...
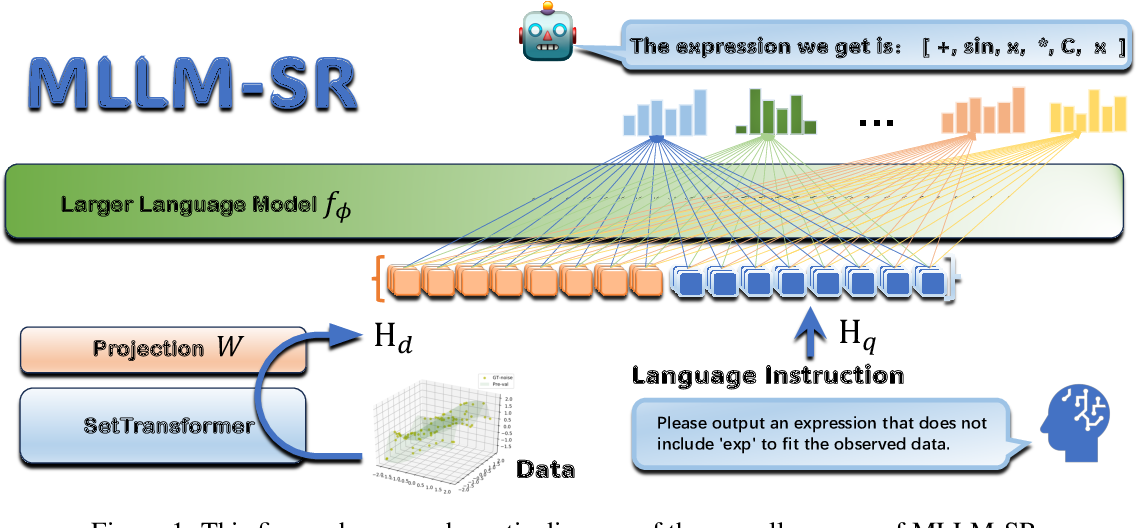
Figure 1 from MLLM-SR: Conversational Symbolic Regression base Multi ...
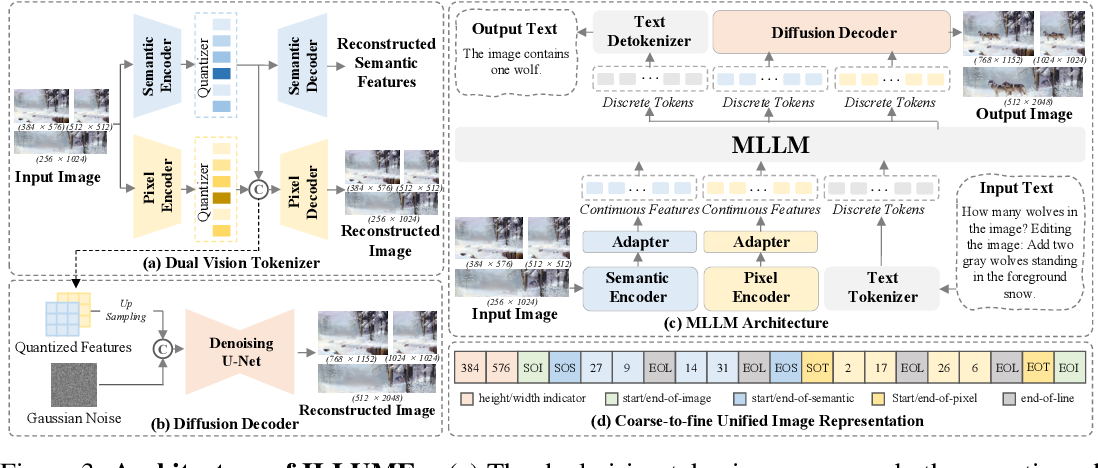
Figure 3 from ILLUME+: Illuminating Unified MLLM with Dual Visual ...
Advertisement Space (336x280)

Figure 1 from MLLM-based Speech Recognition: When and How is ...

Figure 1 from LLMI3D: MLLM-based 3D Perception from a Single 2D Image ...

Figure 1 from Survey on AI-Generated Media Detection: From Non-MLLM to ...

Figure 1 from ROD-MLLM: Towards More Reliable Object Detection in ...

MSJoE: Jointly Evolving MLLM and Sampler for Efficient Long-Form Video ...

DRIFT: Transferring Reasoning Priors for Efficient MLLM Fine-Tuning
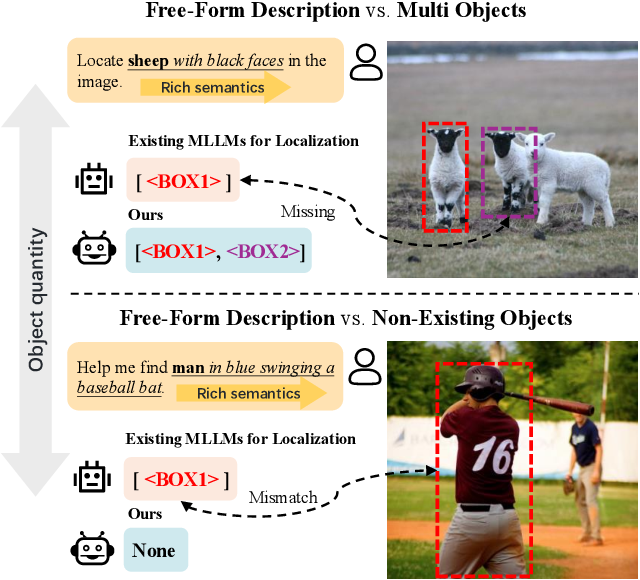
Figure 1 from ROD-MLLM: Towards More Reliable Object Detection in ...

VideoChat3:Fully Open Video MLLM for Efficient and Generalist Video ...

LLMs From Scratch - Chapter 7: Fine-tuning for Instruction Following ...
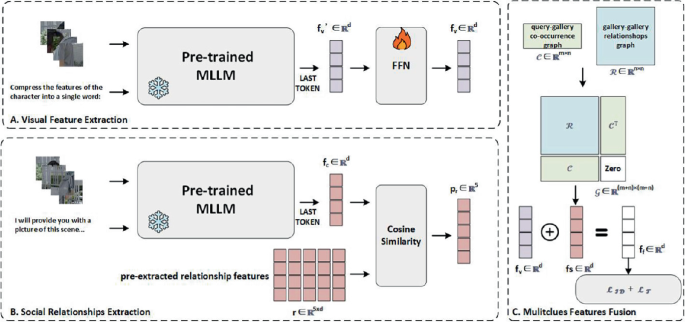
SoMORE: Social Context-Aware MLLM for Video Character Search | Springer ...
Advertisement Space (336x280)
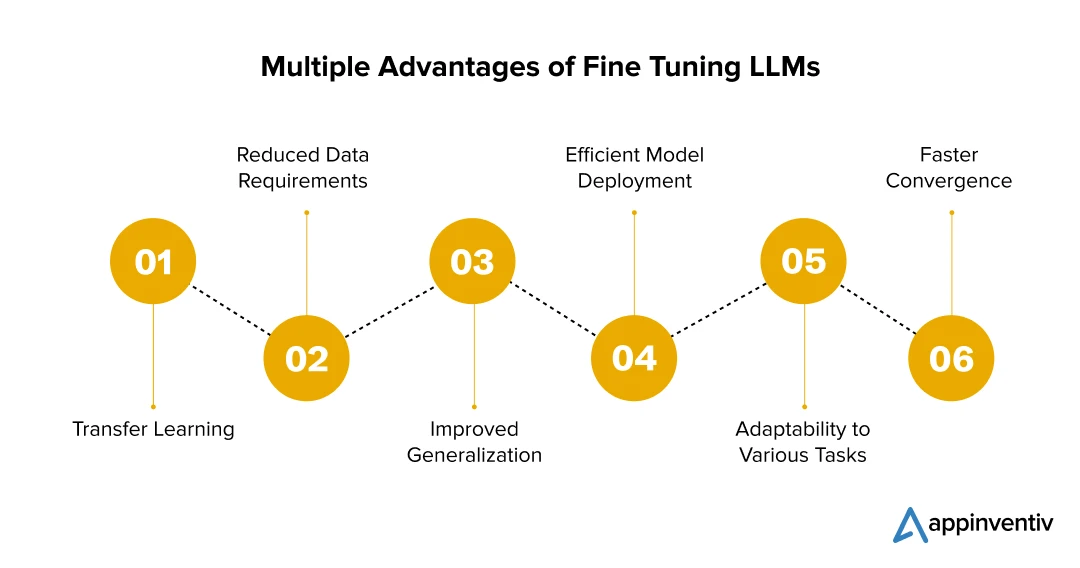
LLM Fine Tuning: Enhancing Your AI Projects for Optimal Efficiency

[논문 리뷰] Efficient Motion-Aware Video MLLM
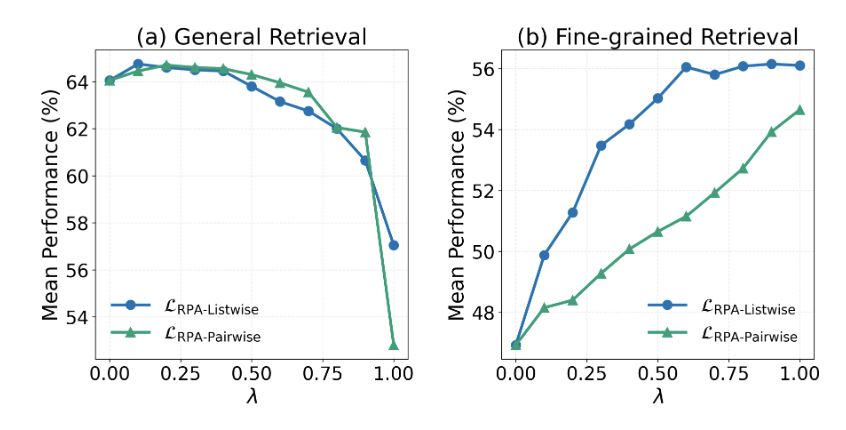
Guiding Cross-Modal Representations with MLLM Priors via Preference ...

Efficient Fine Tuning LLM | PDF
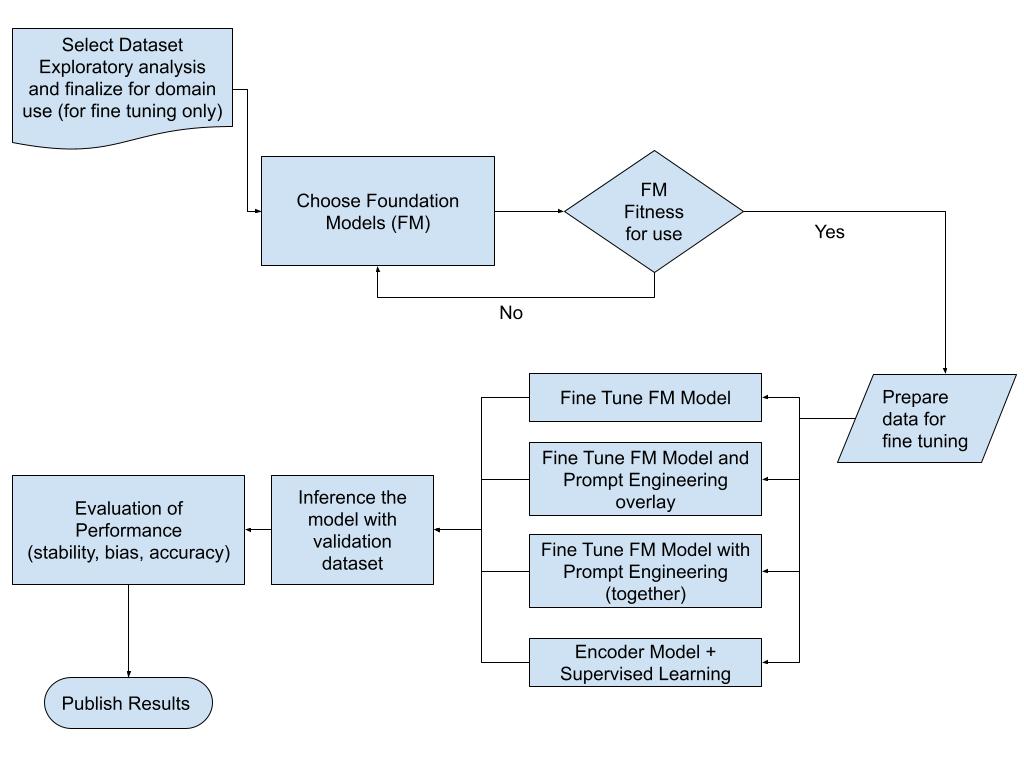
Practical insights and best practices for Fine Tuned LLM based use ...
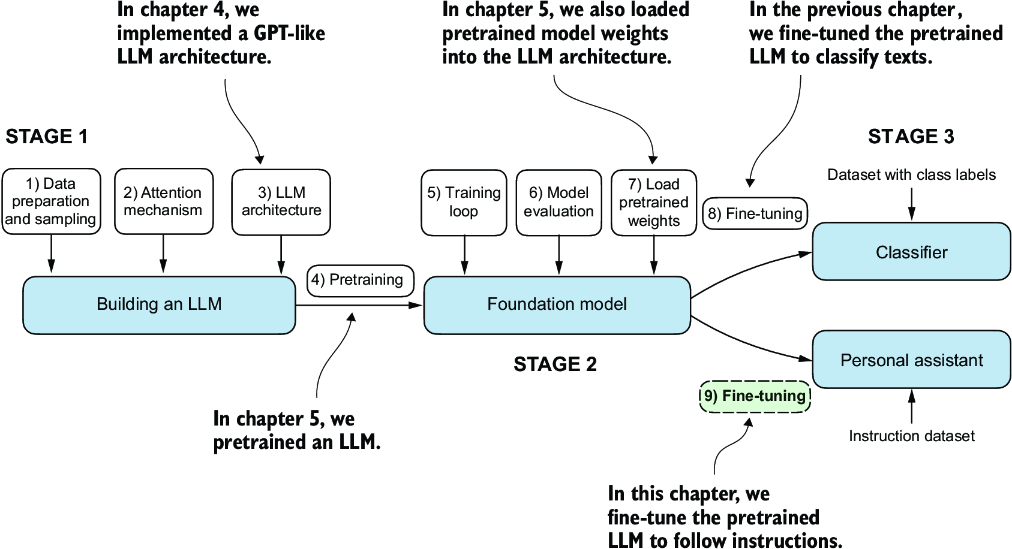
LLMs From Scratch - Chapter 7: Fine-tuning for Instruction Following ...