
Figure 1 From Free The Foundational Semantic Recognition For Modeling
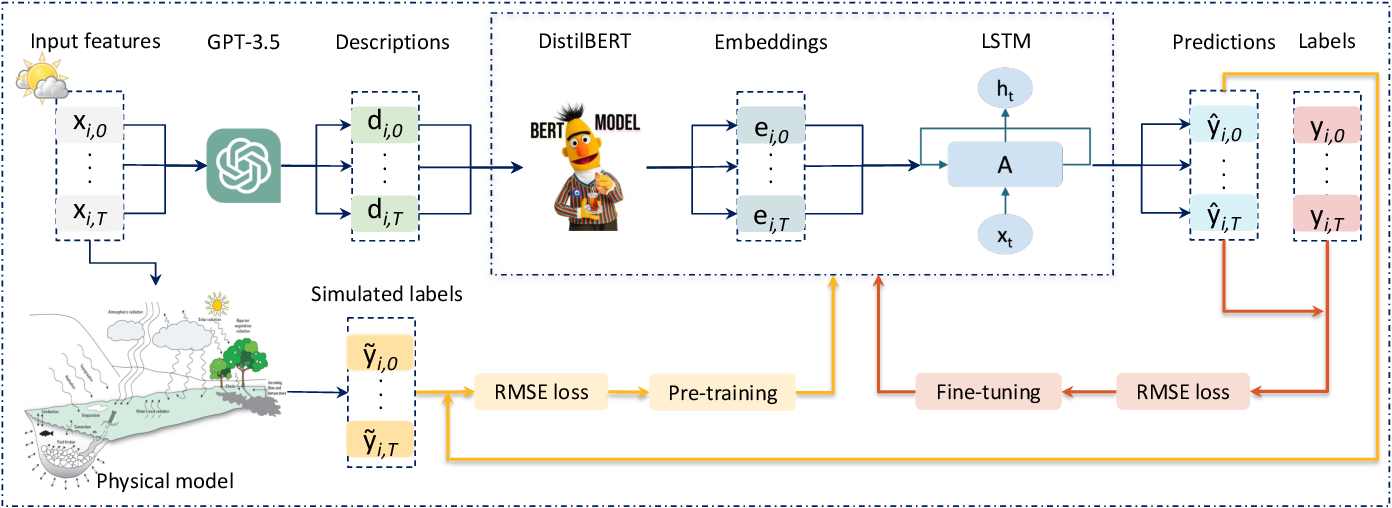
Figure 1 from FREE: The Foundational Semantic Recognition for Modeling ...
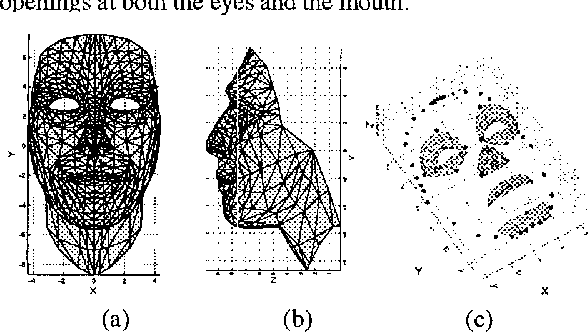
Figure 1 from Face modeling for recognition | Semantic Scholar

Figure 1 from Semantic Neural Model Approach for Face Recognition from ...

Figure 1 from Co-Driven Recognition of Semantic Consistency via the ...
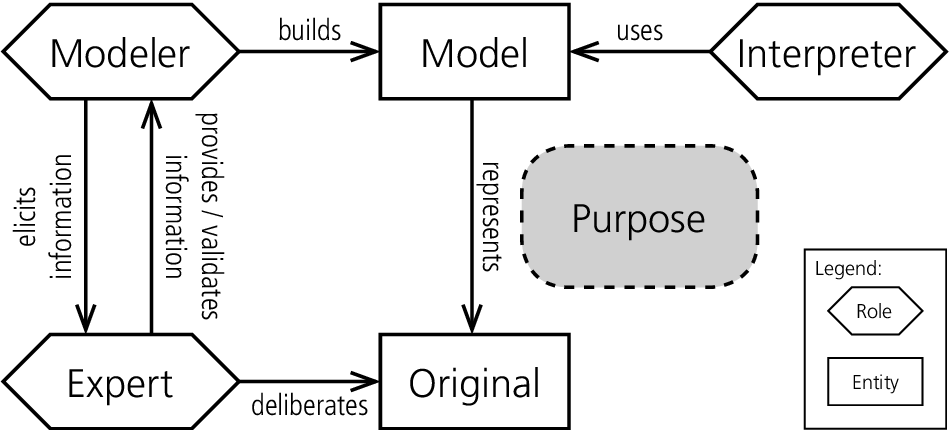
Figure 1 from Modeling the Purposes of Models | Semantic Scholar
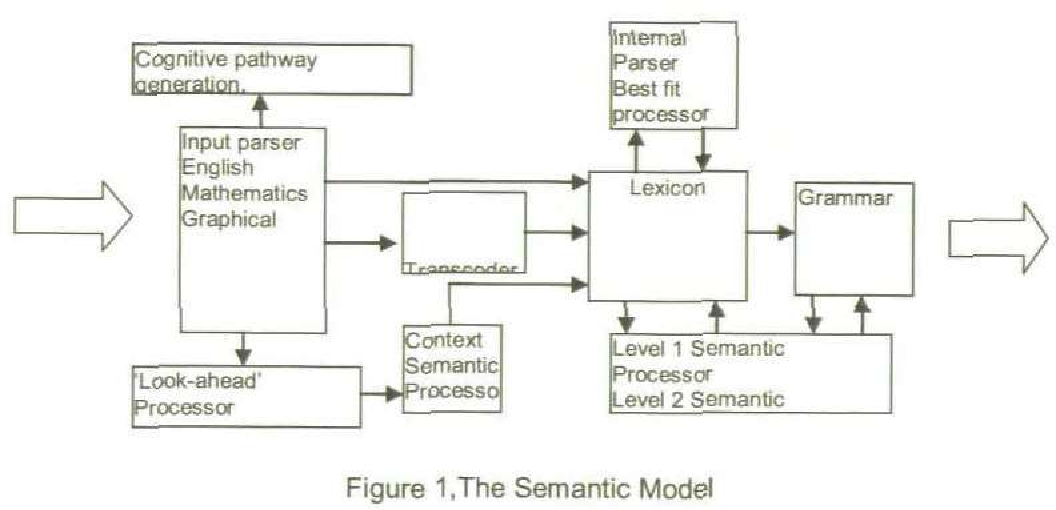
Figure 1 from The Development of a Semantic Model for the ...
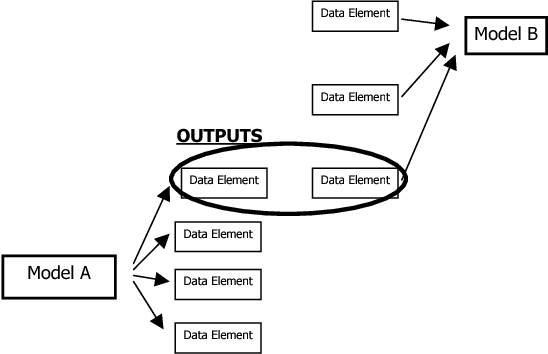
Figure 1 from An Introduction to Semantic Modeling for Logistical ...

Figure 1 from A Framework for semantic modeling of images | Semantic ...

Figure 1 from Semantic Recognition of Human-Object Interactions via ...

Figure 1 from Semantic Modeling and Knowledge Representation in ...
Advertisement Space (300x250)

Figure 1 from LLM-Guided Semantic Relational Reasoning for Multimodal ...
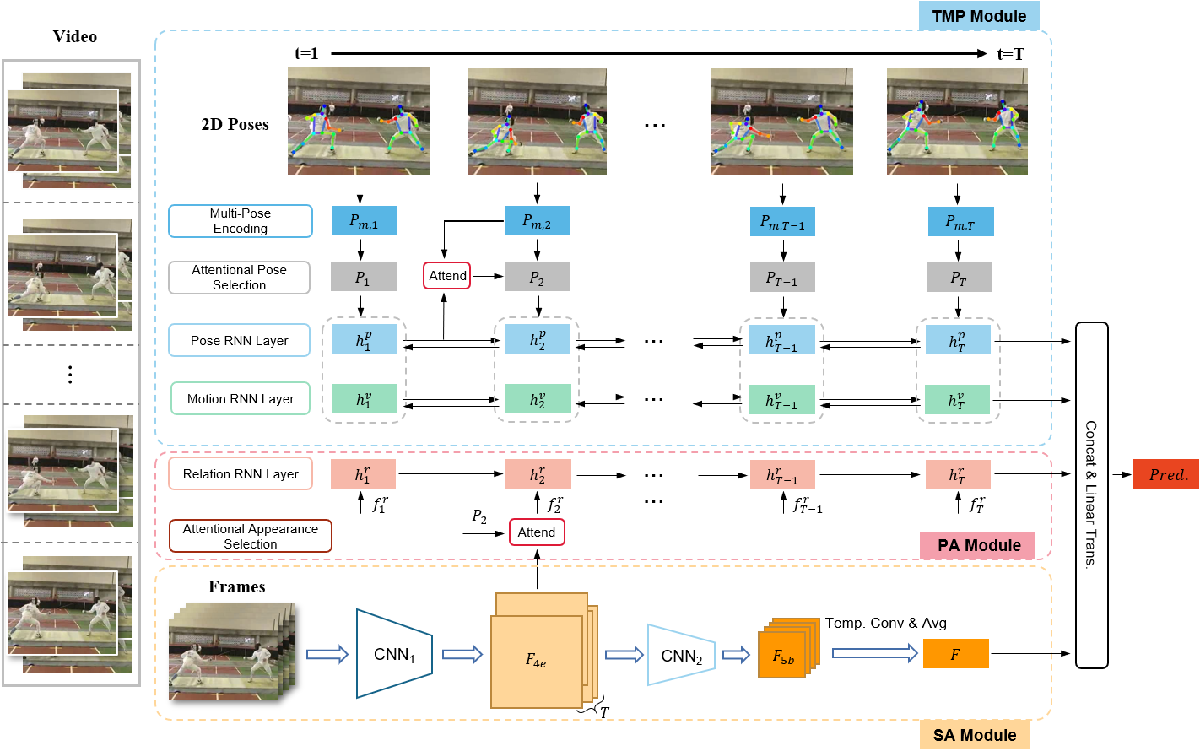
Figure 1 from Pose-Appearance Relational Modeling for Video Action ...
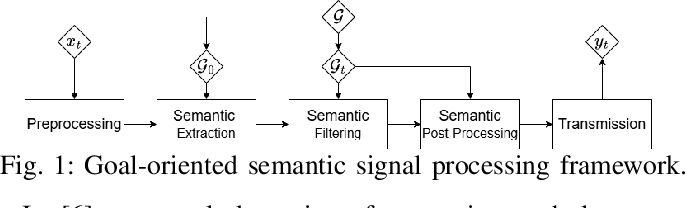
Figure 1 from Learning the Underlying Semantic Model Using Multi-Sensor ...
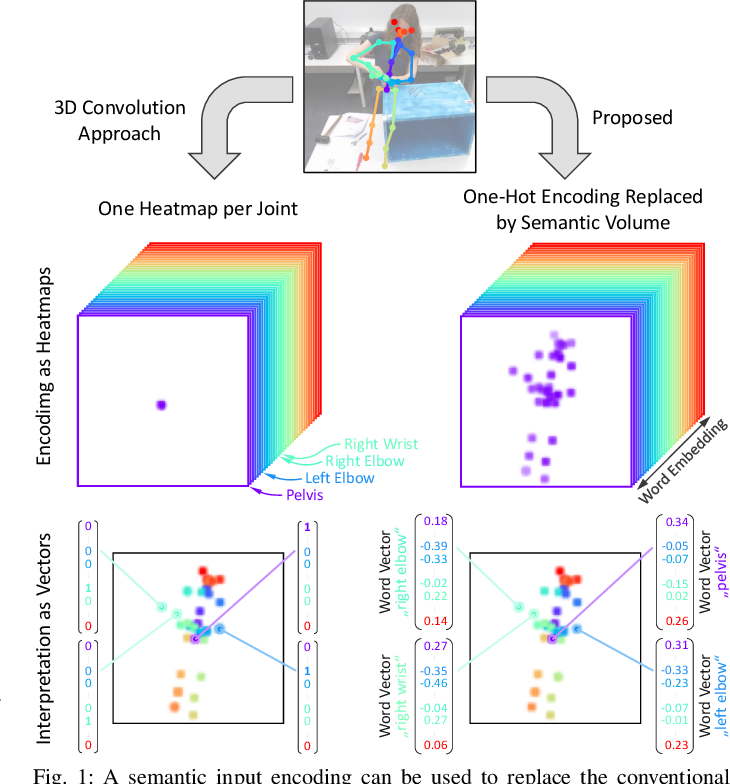
Figure 1 from Including Semantic Information via Word Embeddings for ...

Figure 1 from Exploring Rich Semantics for Open-Set Action Recognition ...
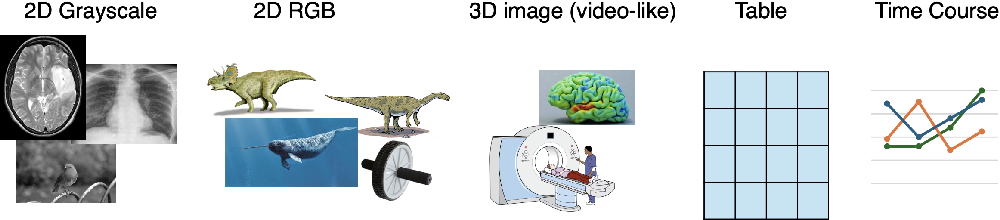
Figure 1 from A Foundational Multi-Modal Model for Few-Shot Learning ...
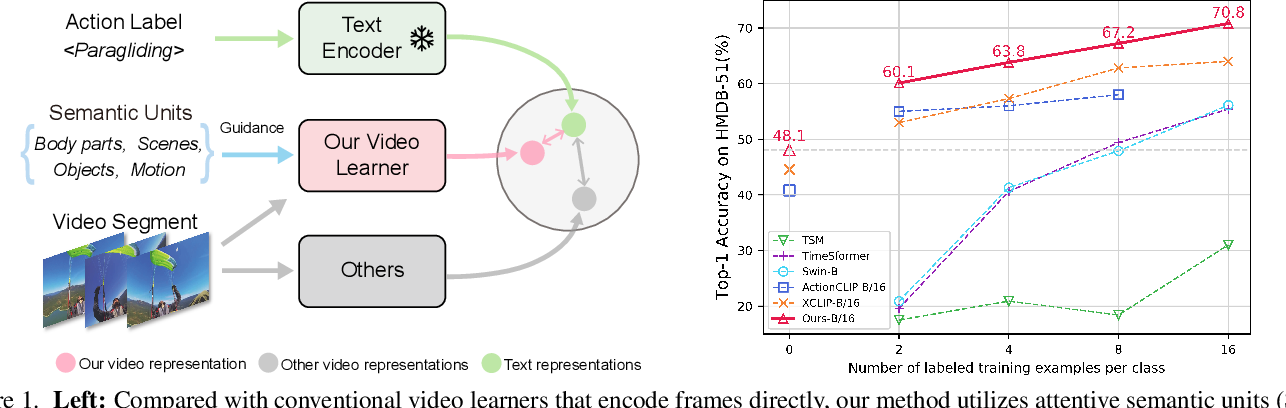
Figure 1 from Video Action Recognition with Attentive Semantic Units ...
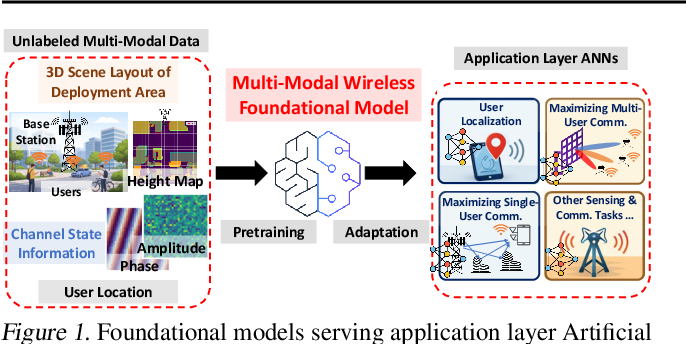
Figure 1 from A Multi-Modal Foundational Model for Wireless ...

Figure 1 from IQFM A Wireless Foundational Model for I/Q Streams in AI ...

Figure 1 from Exploring Semantic Attributes from A Foundation Model for ...
Advertisement Space (336x280)
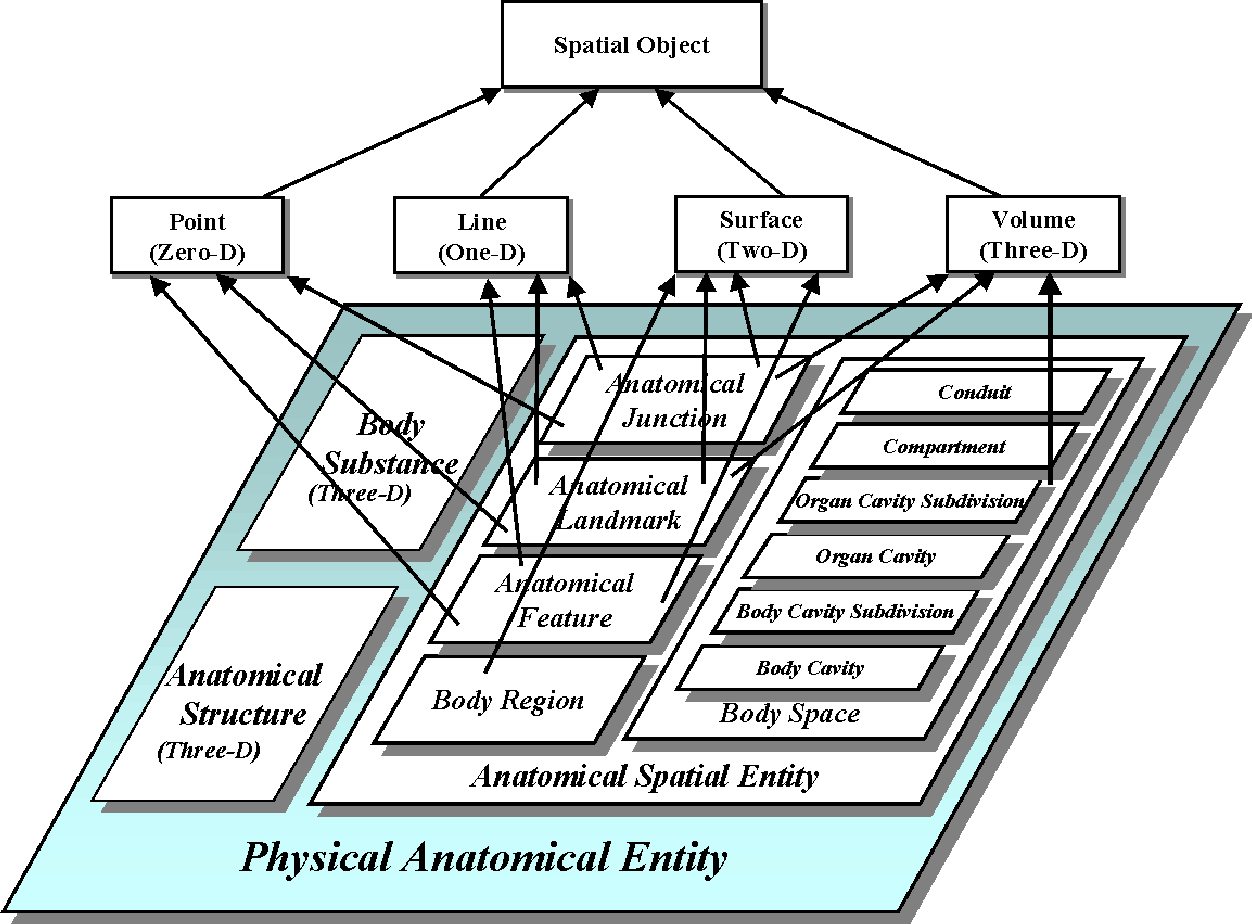
Figure 1 from The Digital Anatomist Foundational Model Server ...

Figure 1 from Image Semantic Recognition and Segmentation Algorithm of ...

Figure 1 from Learning Adversarial Semantic Embeddings for Zero-Shot ...

Figure 1 from Explicitly Semantic Guidance for Face Sketch Attribute ...

Figure 1 from Modeling speech recognition and synthesis simultaneously ...
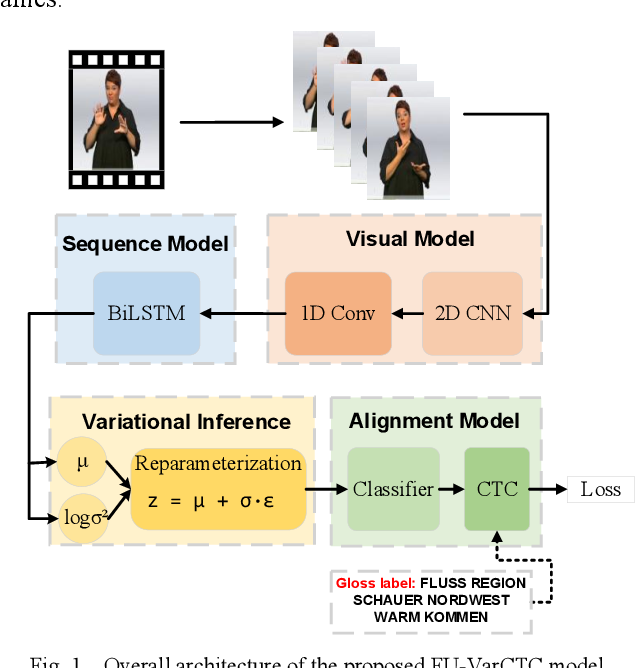
Figure 1 from Frame-wise Uncertainty Modeling with Variational CTC for ...
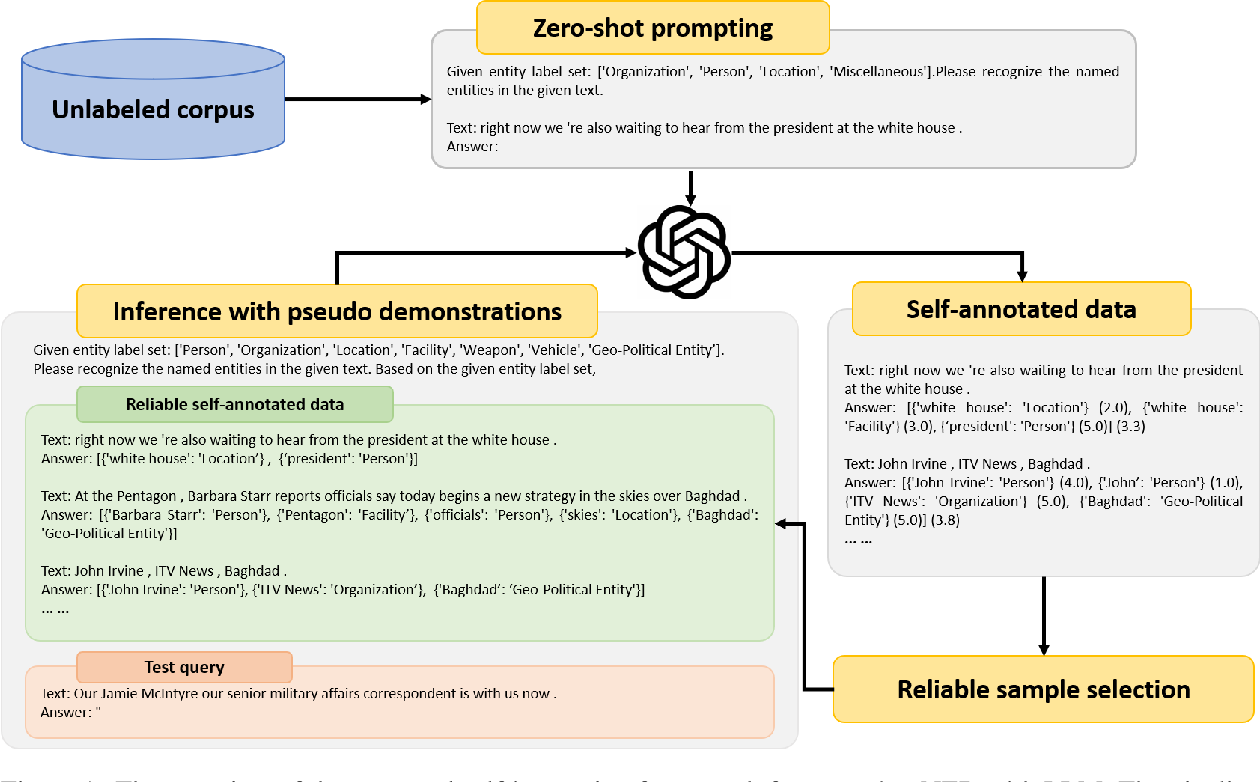
Figure 1 from Self-Improving for Zero-Shot Named Entity Recognition ...
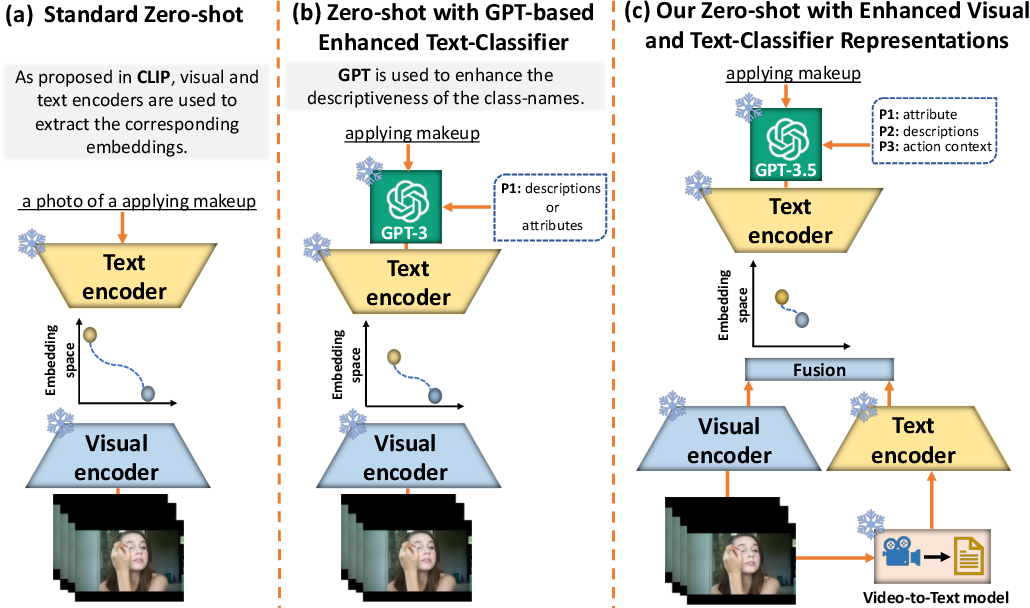
Figure 1 from Videoprompter: an ensemble of foundational models for ...
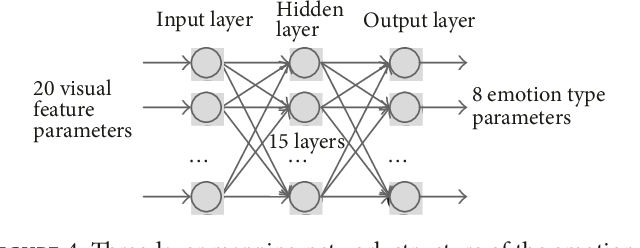
Figure 1 from Emotional Semantic Recognition of Visual Scene in Flash ...

Figure 1 from Semantic Tree-Based 3D Scene Model Recognition | Semantic ...
Advertisement Space (336x280)

Figure 1 from Exploring Semantic Attributes from A Foundation Model for ...

Figure 1 from LLM-Based Semantic Communication: The Way From Task ...

Figure 1 from Ethical Framework for Responsible Foundational Models in ...

Figure 1 from Dynamic Label Smoothing and Semantic Transport for ...
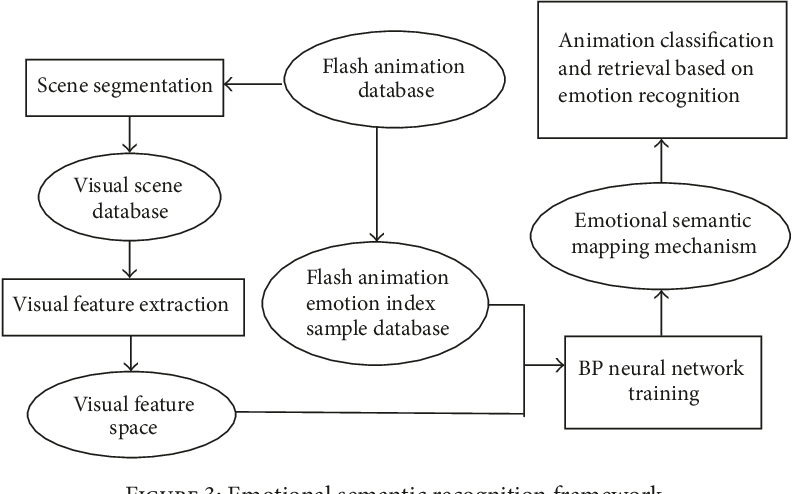
Figure 1 from Emotional Semantic Recognition of Visual Scene in Flash ...
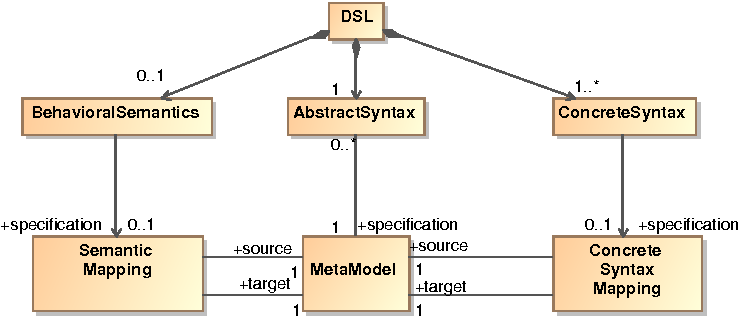
Figure 1 from A Journey through the Secret Life of Models | Semantic ...