
Figure 1 From Improving Zero Shot Voice Style Transfer Via Disentangled

Figure 1 from Improving Zero-shot Voice Style Transfer via Disentangled ...

Figure 1 from Improving Zero-shot Voice Style Transfer via Disentangled ...

Table 1 from Improving Zero-shot Voice Style Transfer via Disentangled ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from Zero-Shot Voice Style Transfer with Only Autoencoder Loss ...
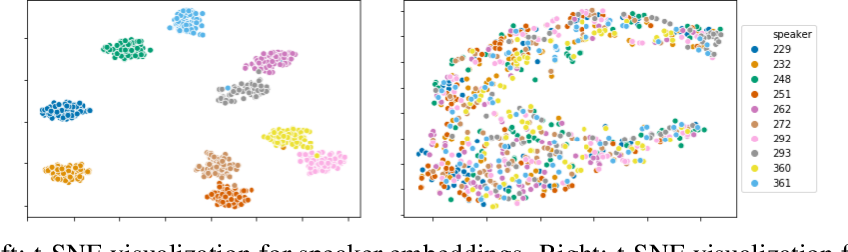
Improving Zero-shot Voice Style Transfer via Disentangled ...
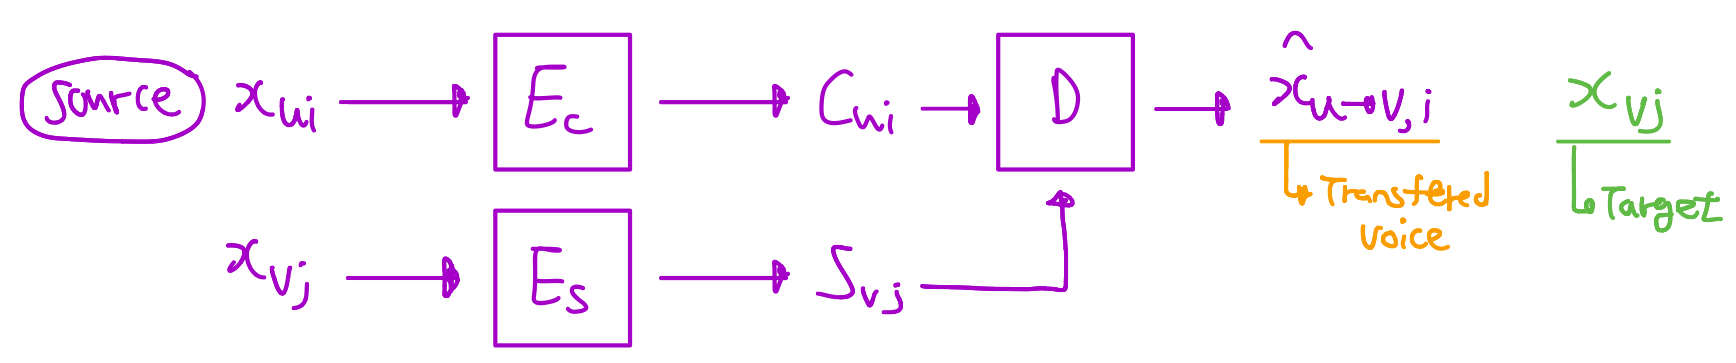
Improving Zero-Shot Voice Style Transfer via Disentangled ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...
Advertisement Space (300x250)

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...

Figure 1 from HierVST: Hierarchical Adaptive Zero-shot Voice Style ...
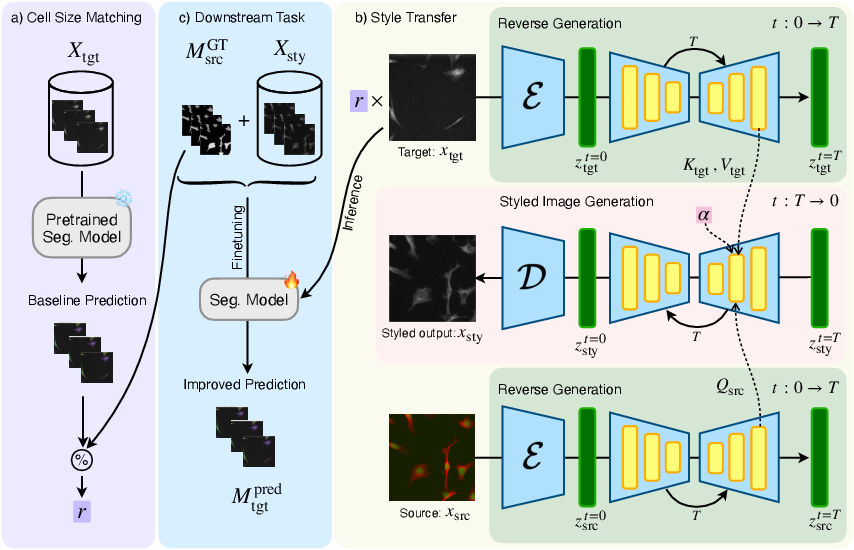
Figure 1 from CellStyle: Improved Zero-Shot Cell Segmentation via Style ...

Figure 1 from Zero-shot Cross-lingual Voice Transfer for TTS | Semantic ...
Advertisement Space (336x280)

Figure 1 from Zero-shot Voice Conversion via Self-supervised Prosody ...
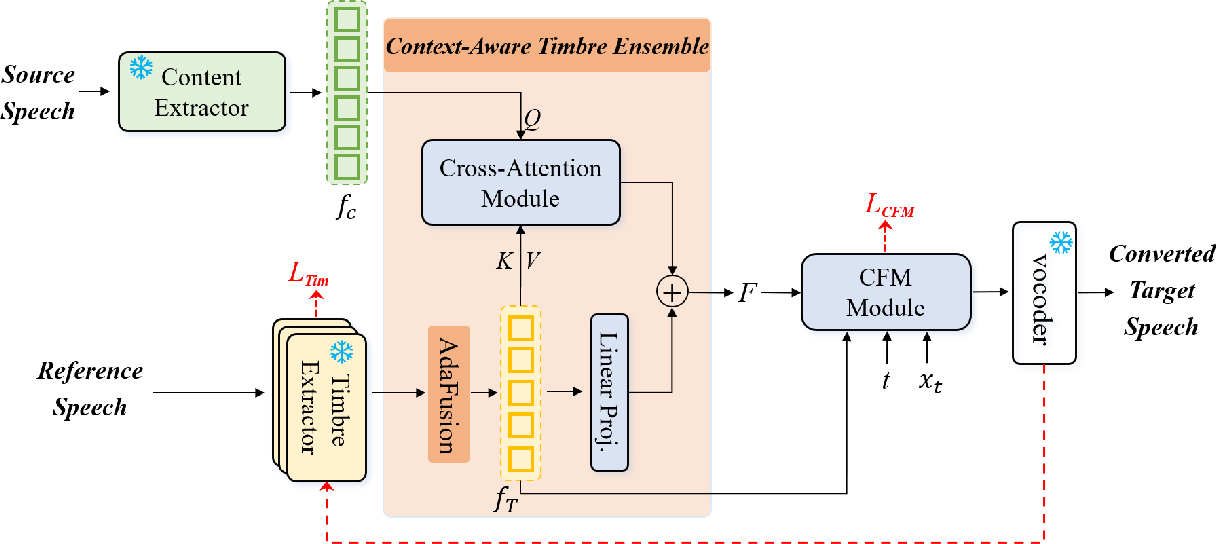
Figure 1 from Zero-Shot Voice Conversion via Content-Aware Timbre ...
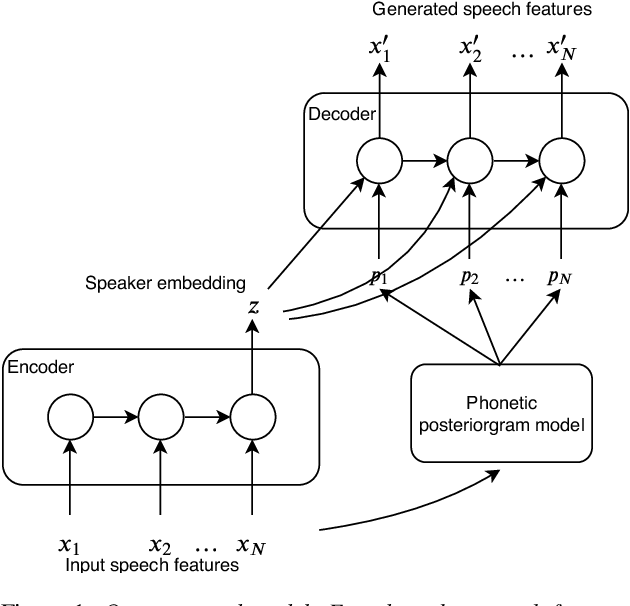
Figure 1 from One-Shot Voice Conversion with Disentangled ...

Figure 1 from Robust Disentangled Variational Speech Representation ...

Figure 1 from DVQVC: An Unsupervised Zero-Shot Voice Conversion ...

Figure 1 from End-to-End Zero-Shot Voice Conversion Using a DDSP ...

Improving zero-shot style transfer text-to-speech by disentangled fine ...

Figure 1 from Zero-Shot Emotion Transfer for Cross-Lingual Speech ...
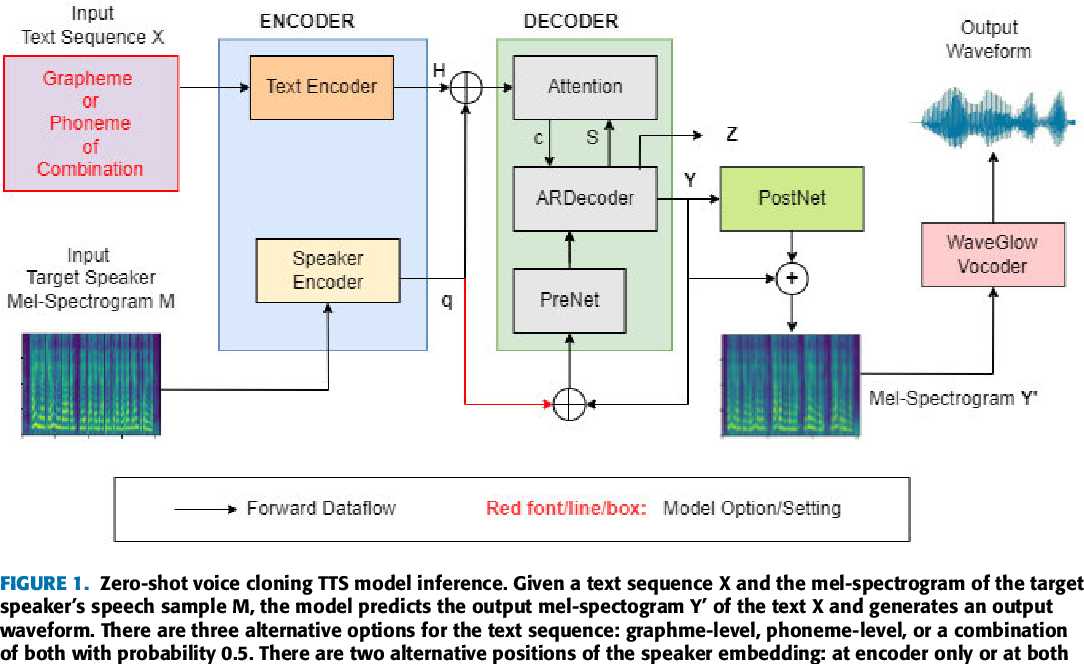
Figure 1 from Zero-Shot Voice Cloning Text-to-Speech for Dysphonia ...
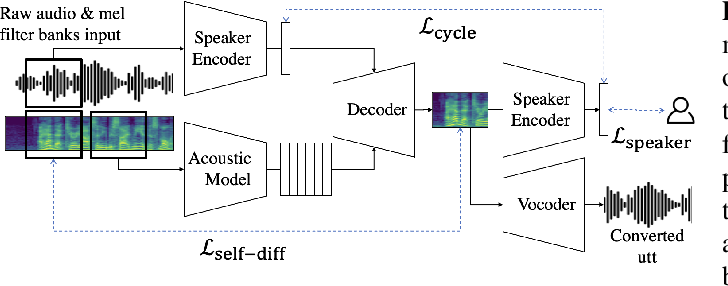
Figure 1 from Training Robust Zero-Shot Voice Conversion Models with ...
Advertisement Space (336x280)

Figure 1 from Zero-Shot Long-Form Voice Cloning with Dynamic ...

Figure 1 from Improving Zero-Shot Models with Label Distribution Priors ...
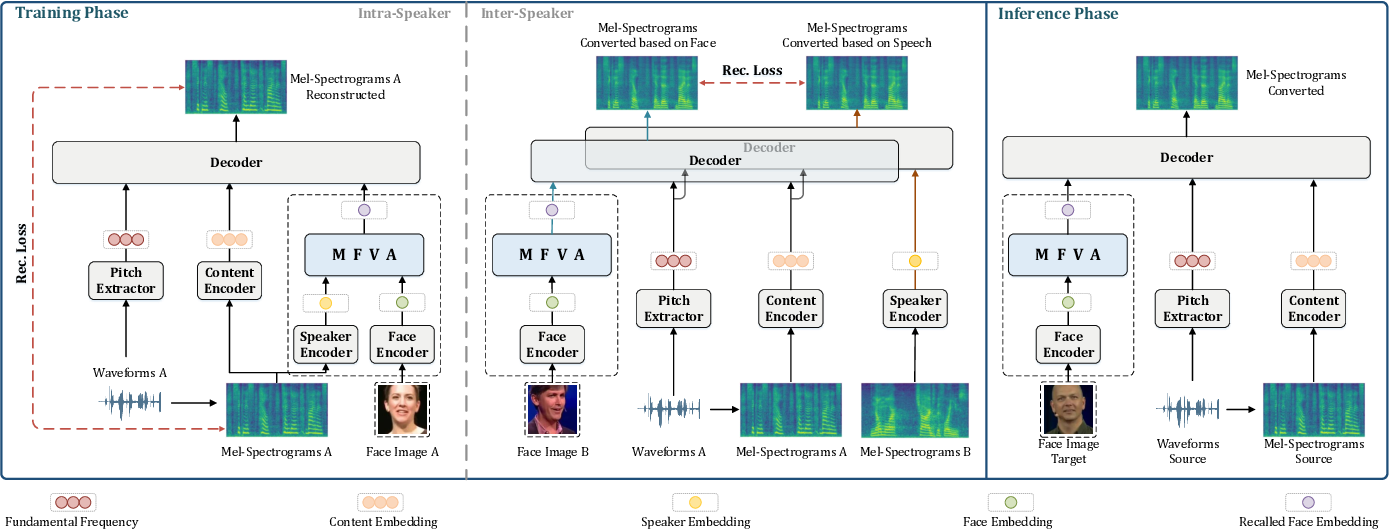
Figure 1 from Face-Driven Zero-Shot Voice Conversion with Memory-based ...

Figure 2 from Zero-shot Voice Conversion via Self-supervised Prosody ...
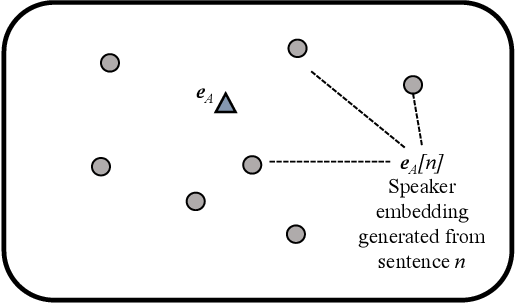
Figure 1 from Zero-Shot Voice Conversion with Adjusted Speaker ...

Figure 1 from Preventing Zero-Shot Transfer Degradation in Continual ...