
Figure 1 From Joint Token And Feature Alignment Framework For Text

Figure 1 from Joint Token and Feature Alignment Framework for Text ...

Figure 1 from Joint Token and Feature Alignment Framework for Text ...

Figure 2 from Joint Token and Feature Alignment Framework for Text ...

Figure 1 from Joint Learning of Token Context and Span Feature for Span ...

Figure 1 from Joint Path Alignment Framework for 3D Human Pose and ...

Figure 1 from Cross-modal Feature Alignment and Fusion for Composed ...

Figure 3 from Joint Path Alignment Framework for 3D Human Pose and ...

Figure 1 from Joint Instance Reconstruction and Feature Subspace ...
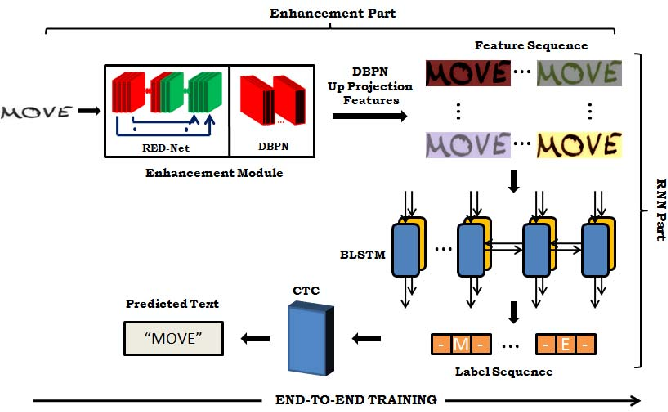
Figure 1 from An End-to-End Trainable Framework for Joint Optimization ...

Figure 1 from Pose-Guided Modality-Invariant Feature Alignment for ...
Advertisement Space (300x250)

Figure 1 from Face Shape-Guided Deep Feature Alignment for Face ...

Figure 1 from Simple and Effective Text Matching with Richer Alignment ...

Figure 1 from Adversarially Smoothed Feature Alignment for Visual ...

Figure 1 from CMFAN: Cross-Modal Feature Alignment Network for Few-Shot ...

Figure 1 from Representative Feature Alignment for Adaptive Object ...

Figure 2 from Siamese Learning with Joint Alignment and Regression for ...

Figure 1 from Heterogeneous Feature Alignment and Fusion in Cross-Modal ...

Figure 1 from Unsupervised Multi-modal Feature Alignment for Time ...

Figure 1 from Learning Feature Alignment Architecture for Domain ...
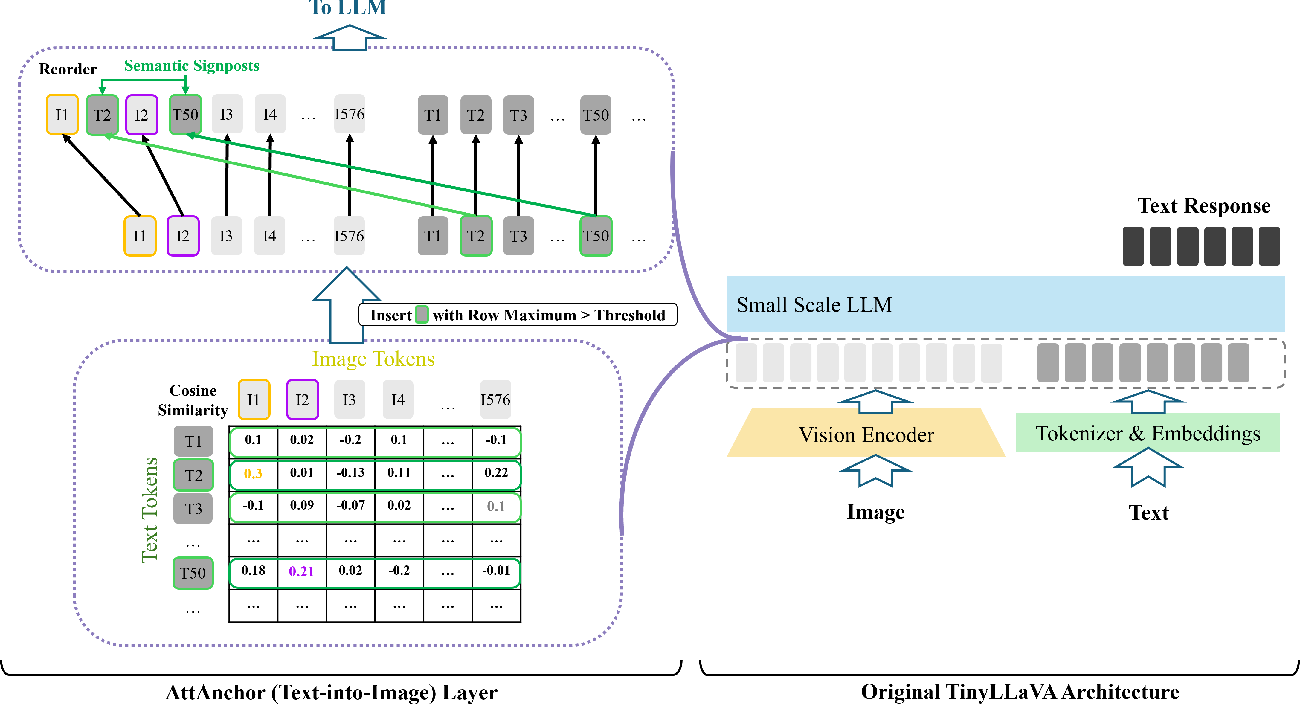
Figure 1 from AttAnchor: Guiding Cross-Modal Token Alignment in VLMs ...
Advertisement Space (336x280)

Figure 1 from Token-Label Alignment for Vision Transformers | Semantic ...
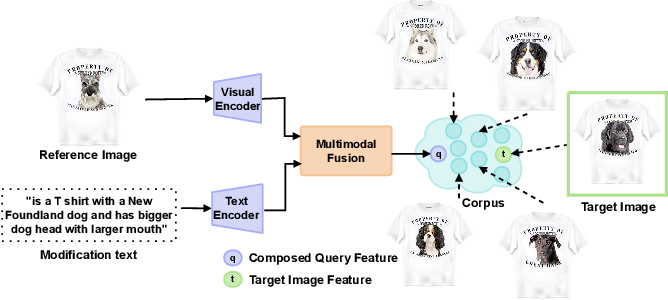
Figure 1 from Text-Guided Attribute Enhancement Framework for Composed ...

(PDF) Joint Instance Reconstruction and Feature Subspace Alignment for ...
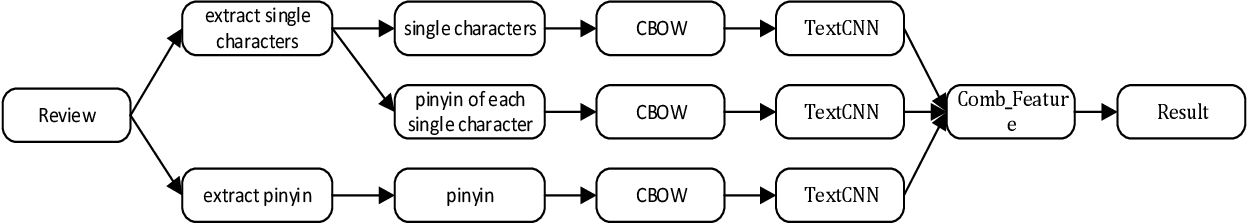
Figure 1 from A Novel Text Features Jointing Model for Review Spam ...

Joint Modal Alignment and Feature Enhancement for Visible-Infrared ...

(PDF) View Intervention and Feature Alignment Aggregation Framework for ...

Joint Modal Alignment and Feature Enhancement for Visible-Infrared ...

Figure 1 from Textual Tokens Classification for Multi-Modal Alignment ...

Figure 1 from FGPLFA: Fine-Grained Pseudo-Labeling and Feature ...
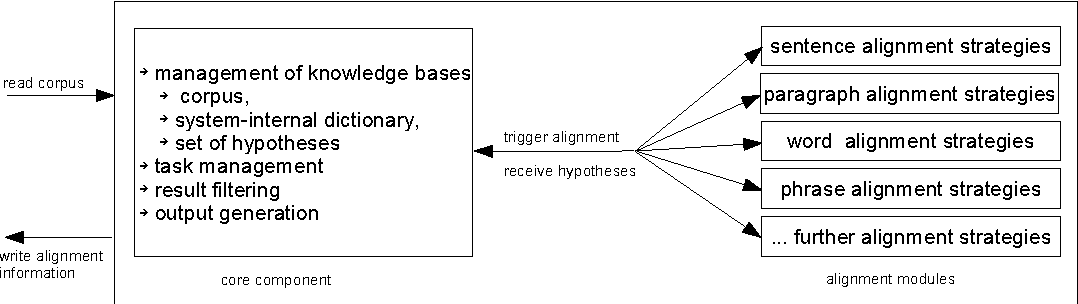
Figure 1 from ATLAS – A New Text Alignment Architecture | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from Text-centric Alignment for Multi-Modality Learning ...
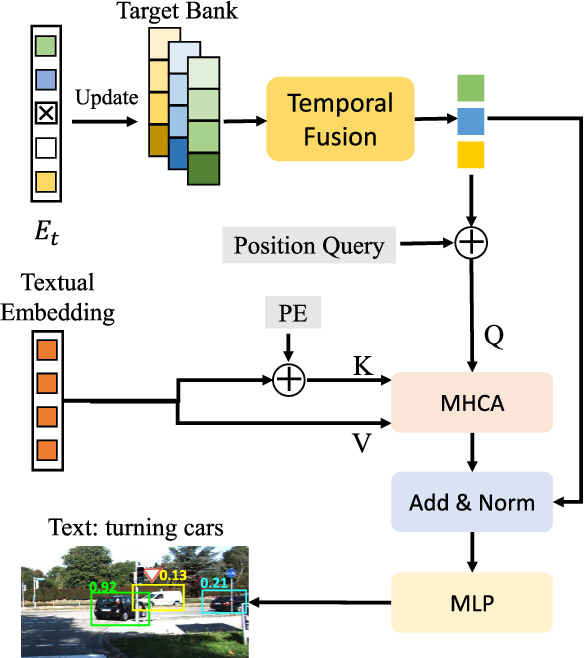
Figure 3 from Visual-Linguistic Feature Alignment With Semantic and ...
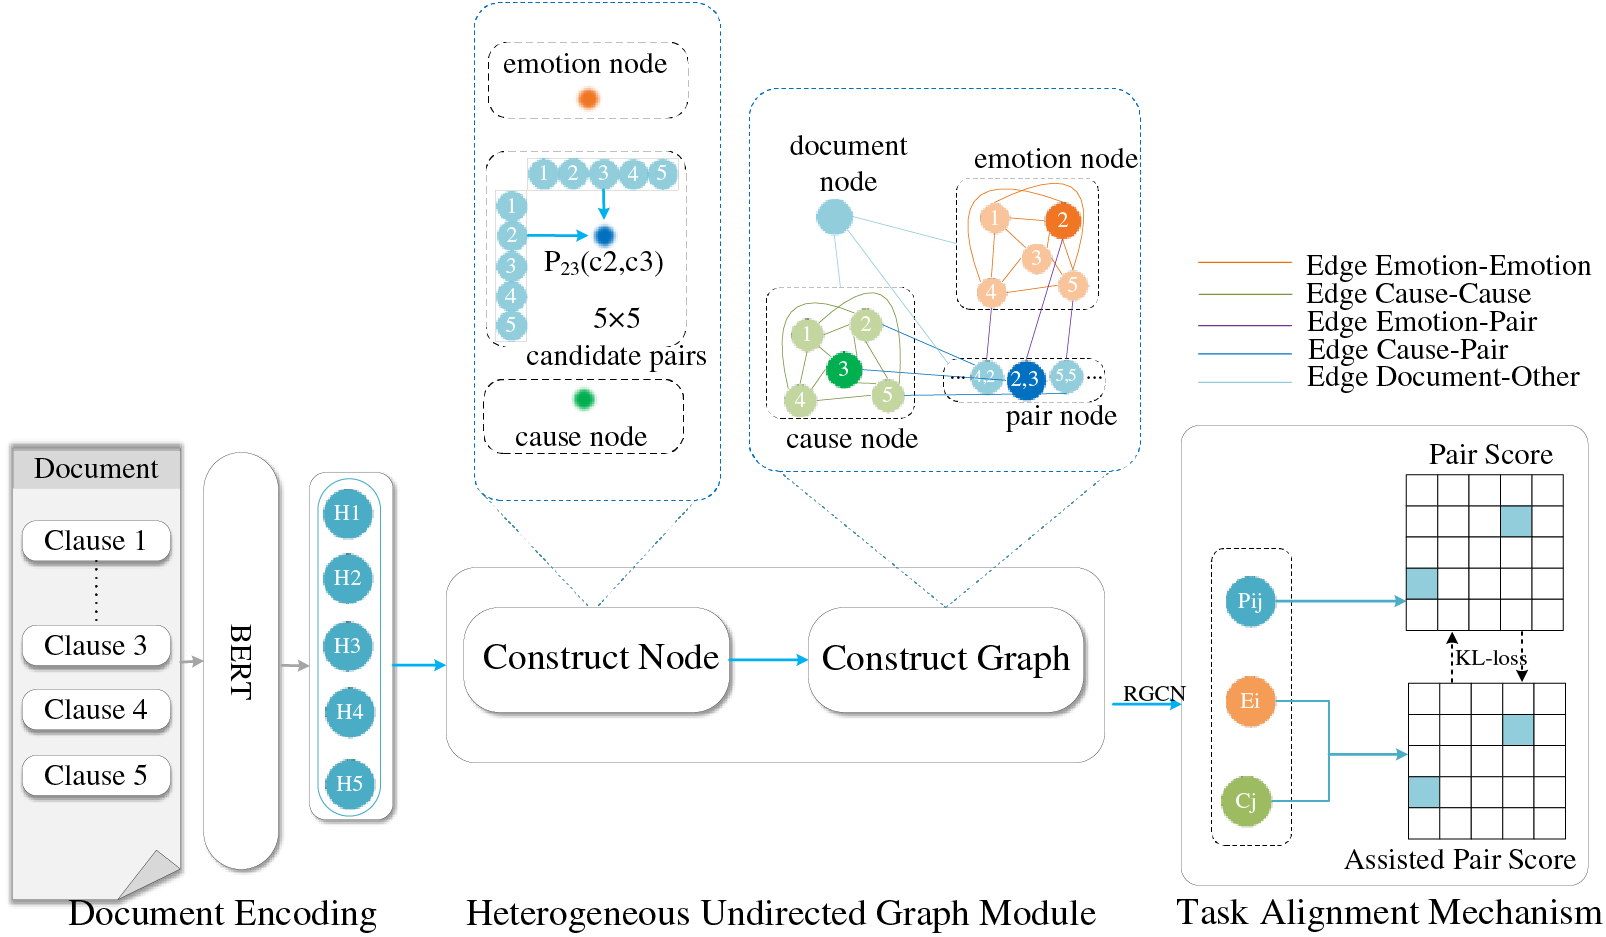
CMC | Free Full-Text | Joint Feature Encoding and Task Alignment ...
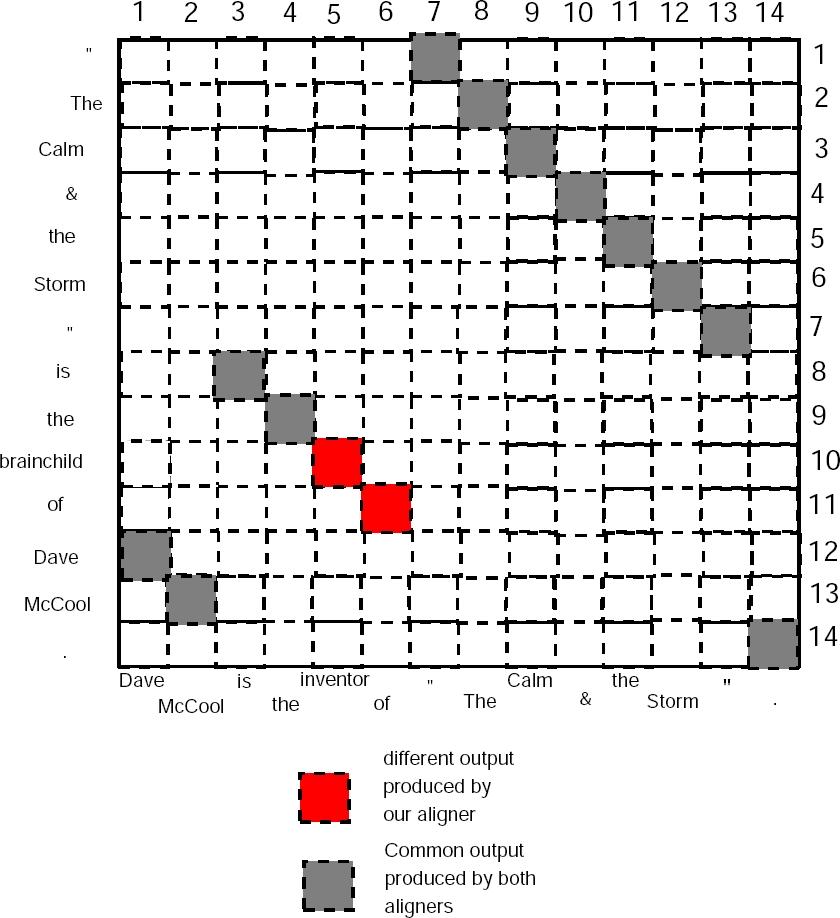
Feature Extraction for Token Based Word Alignment for Question ...

Feature Extraction for Token Based Word Alignment for Question ...

Figure 1 from Contrastive Learning-Based Multi-Modal Entity Alignment ...