
Figure 1 From Label Efficient Self Supervised Speaker Verification With

Figure 1 from Label-Efficient Self-Supervised Speaker Verification With ...

Figure 1 from Self-Supervised Speaker Verification with Adaptive ...
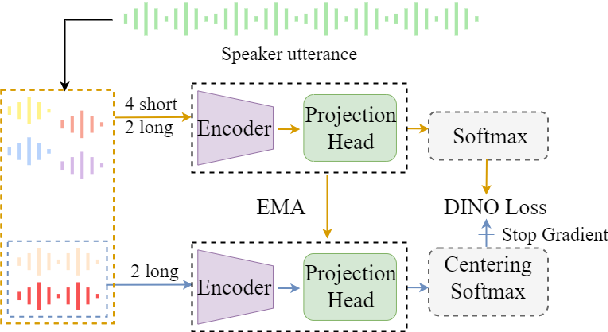
Figure 1 from Self-Supervised Speaker Verification with Mini-Batch ...
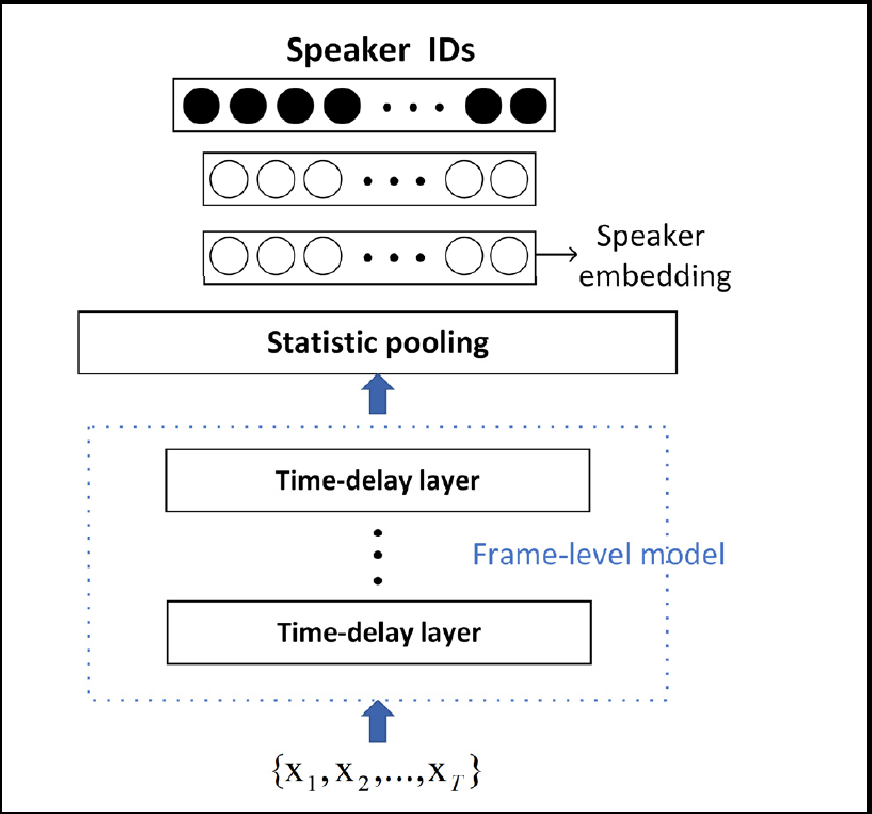
Figure 1 from A speaker verification method using frame-level self ...
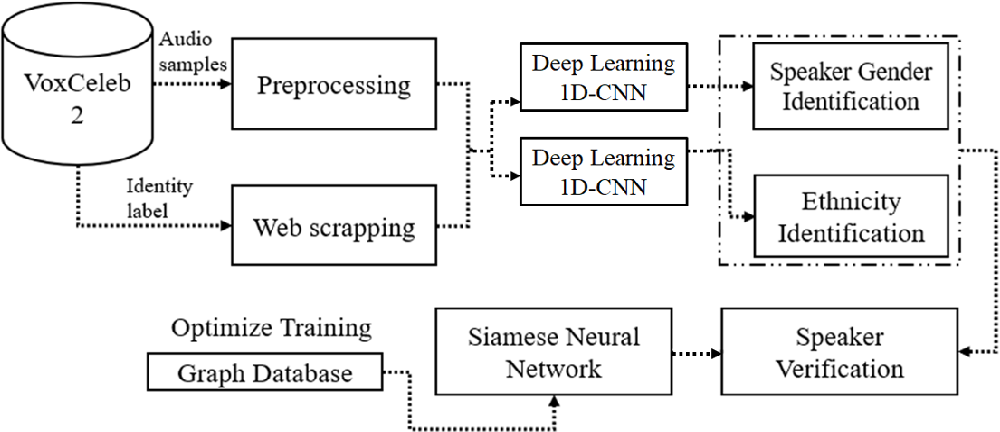
Figure 1 from Enhancing speaker verification accuracy with deep ...

Figure 1 from Label-Efficient Self-Supervised Speaker Verification With ...
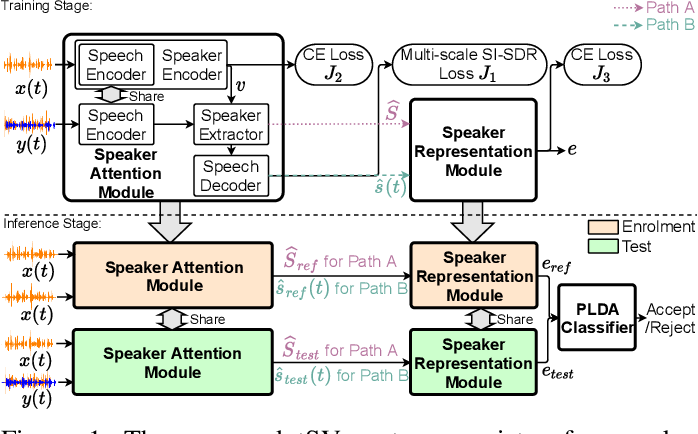
Figure 1 from Target Speaker Verification With Selective Auditory ...

Figure 1 from Self-Supervised Speaker Verification Using Dynamic Loss ...

Figure 1 from Self-Supervised Open-Set Speaker Recognition with ...

Figure 1 from Self-Supervised Speaker Verification Using Dynamic Loss ...
Advertisement Space (300x250)

Figure 1 from Self-Supervised Speaker Verification Using Dynamic Loss ...

Figure 1 from Self-Supervised Speaker Verification Using Dynamic Loss ...
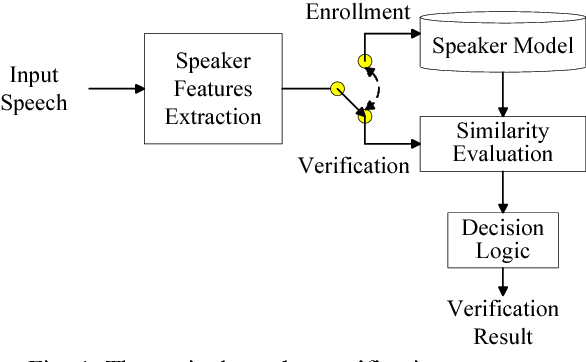
Figure 1 from Speaker Verification Using Line Spectrum Frequency ...
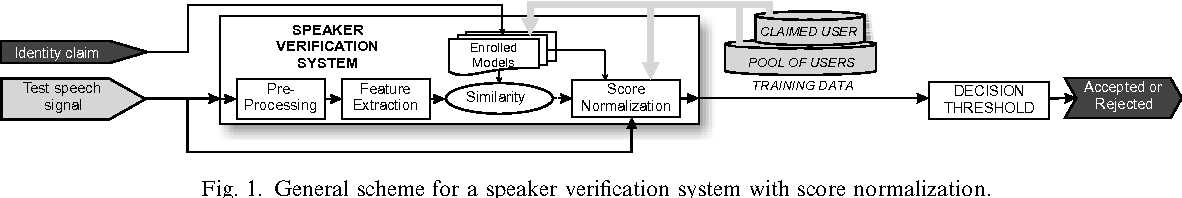
Figure 1 from Speaker verification using speaker- and test-dependent ...

Figure 1 from Speaker Change Detection with Weighted-sum Knowledge ...
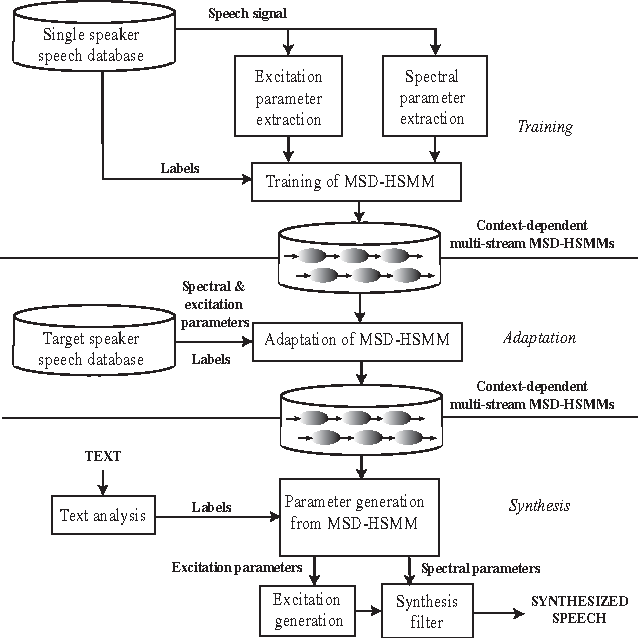
Figure 1 from Revisiting the security of speaker verification systems ...

[论文评述] Towards Supervised Performance on Speaker Verification with Self ...

Figure 1 from A segment-based speaker verification system using SUMMIT ...
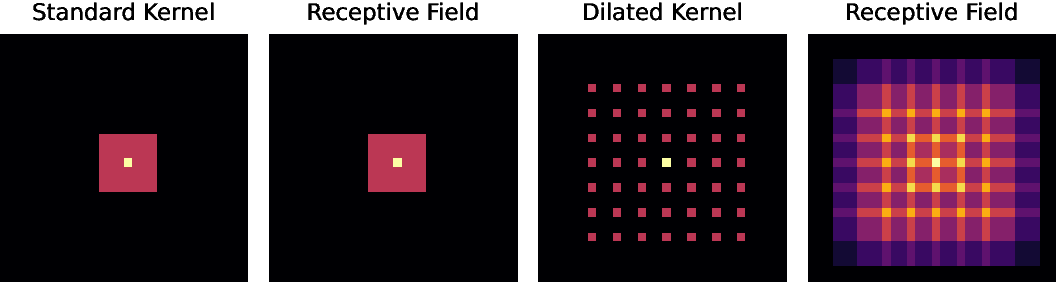
Figure 1 from Self-Supervised Open-Set Speaker Recognition with ...

Figure 1 from Self-Supervised Audio-Visual Speaker Representation with ...
Advertisement Space (336x280)

Figure 1 from Contrastive Self-Supervised Speaker Embedding With ...

Figure 2 from Raw waveform speaker verification for supervised and self ...
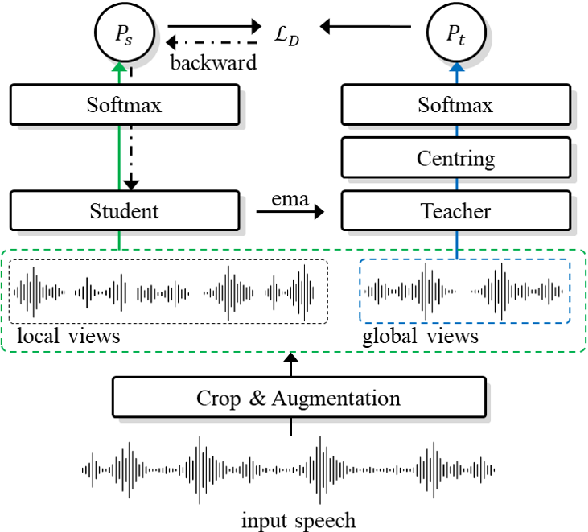
Figure 1 from Self-supervised curriculum learning for speaker ...

Figure 1 from The DKU-DukeECE System for the Self-Supervision Speaker ...

Figure 1 from Self-supervised learning with diffusion-based ...
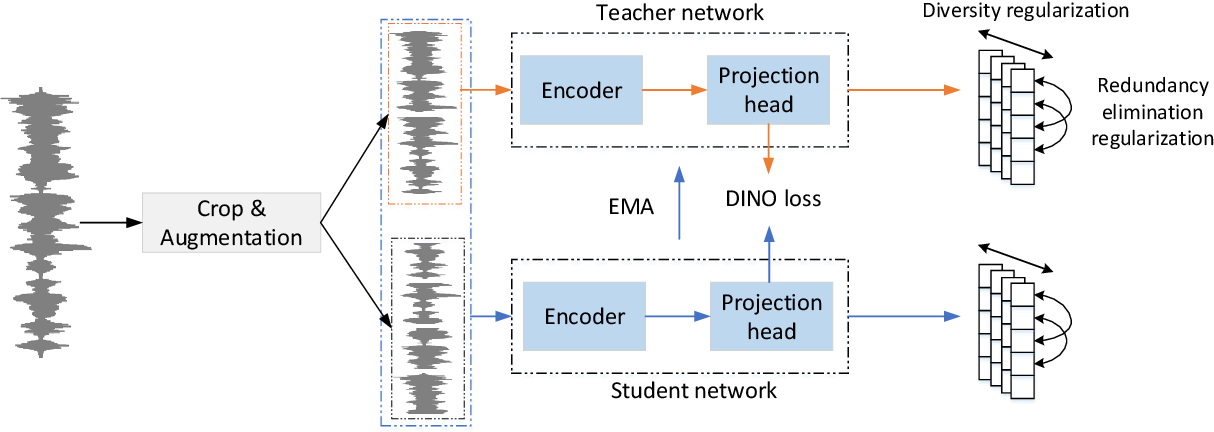
Figure 1 from Pushing the Limits of Self-Supervised Speaker ...
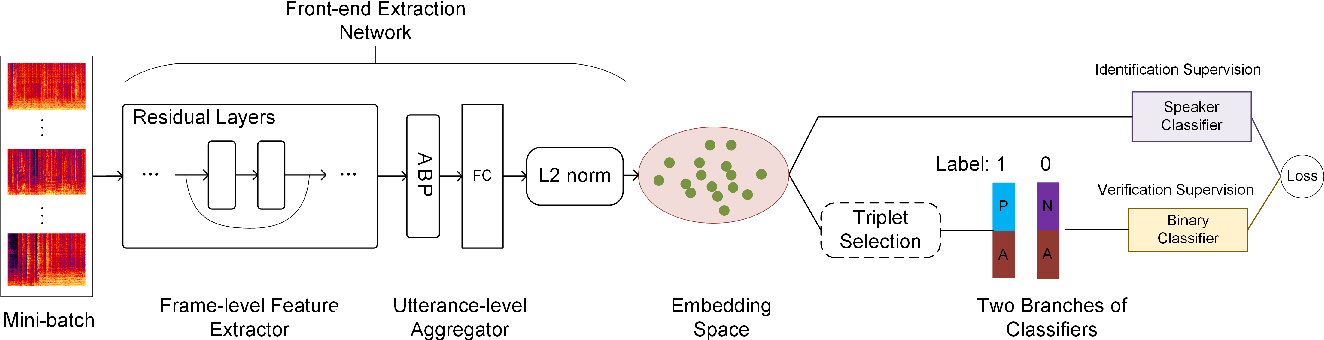
Figure 1 from An Effective Speaker Recognition Method Based on Joint ...
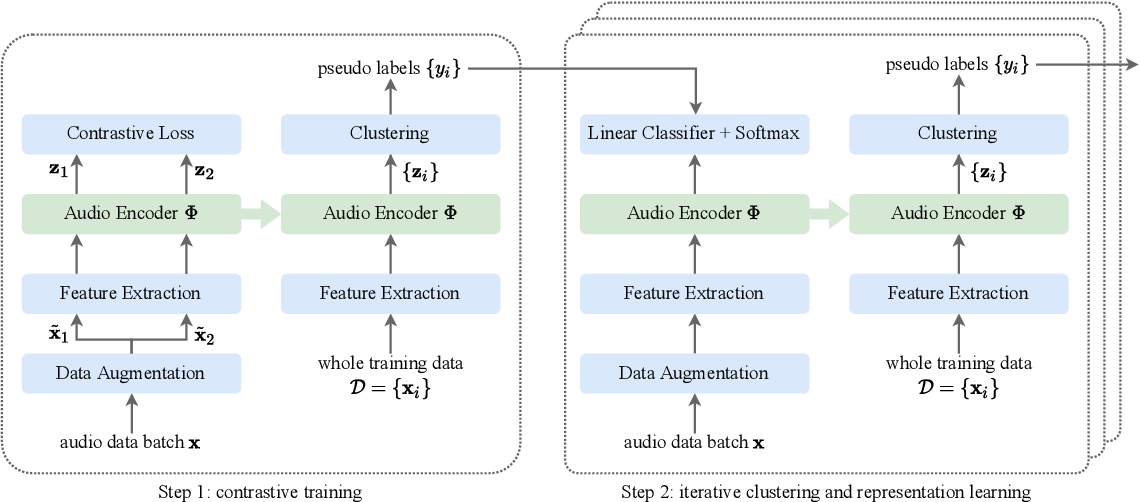
Figure 1 from Incorporating Visual Information in Audio Based Self ...
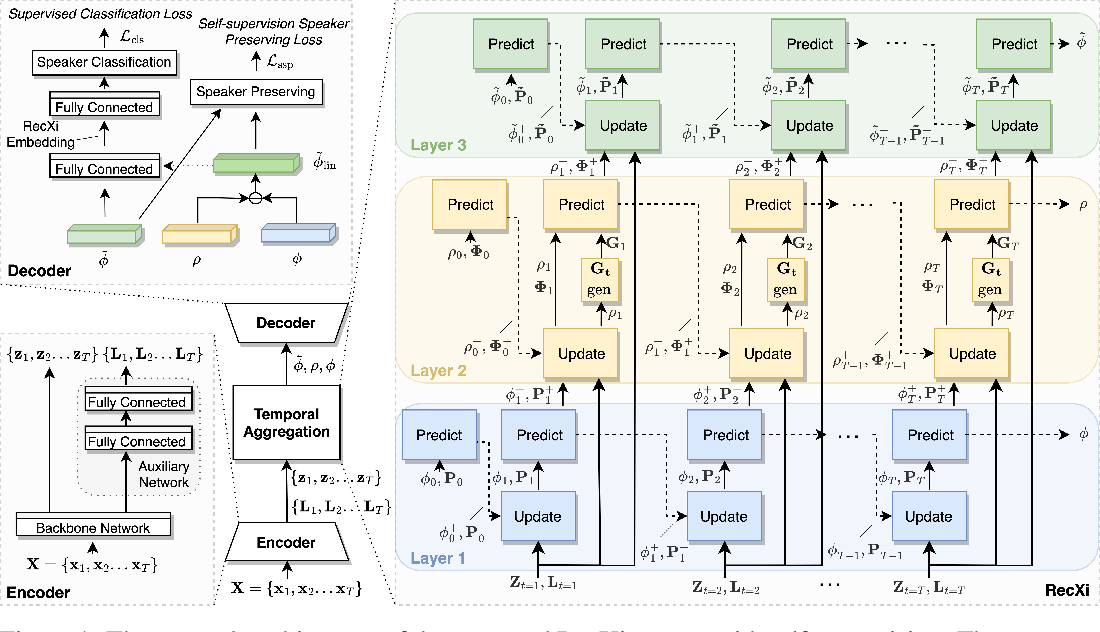
Figure 1 from Disentangling Voice and Content with Self-Supervision for ...
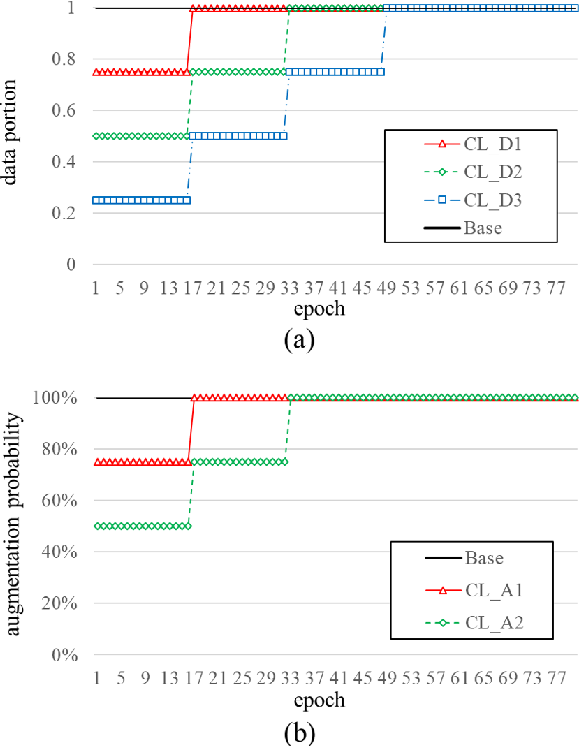
Figure 1 from Self-supervised curriculum learning for speaker ...
Advertisement Space (336x280)

Figure 1 from Self-Supervised Vision Transformers Are Efficient ...
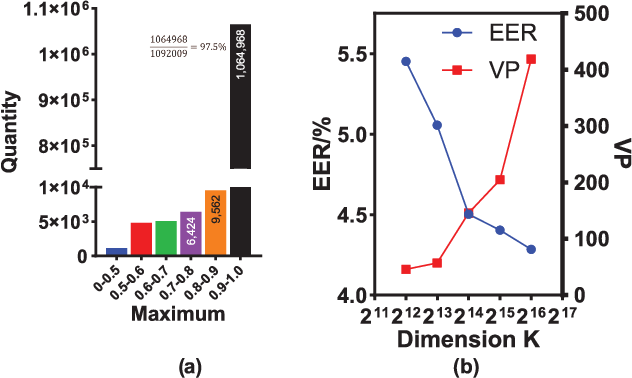
Figure 1 from Prototype Division for Self-Supervised Speaker ...

Figure 1 from Efficient Self-Supervised Learning Representations for ...
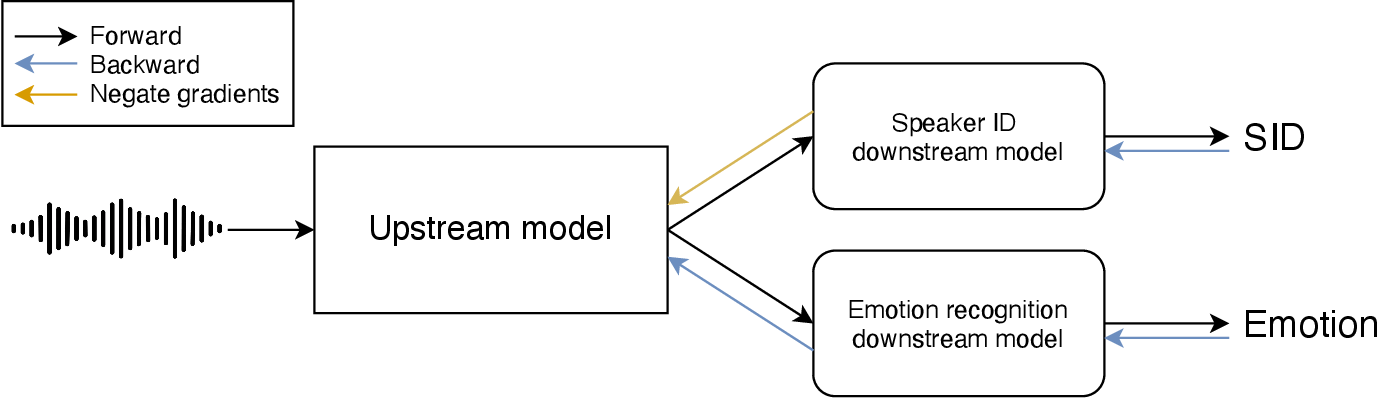
Figure 1 from Speaker Normalization for Self-Supervised Speech Emotion ...

Figure 1 from Enhanced Self-Supervised Speaker Diarization Framework ...
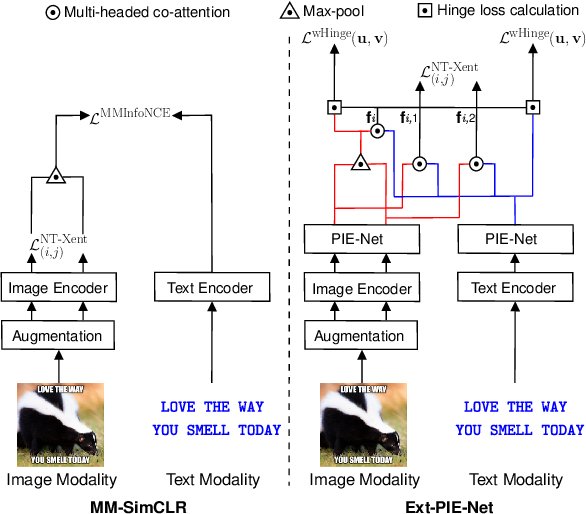
Figure 1 from Domain-aware Self-supervised Pre-training for Label ...