
Figure 1 From Learning To Paraphrase For Alignment With Llm Preference
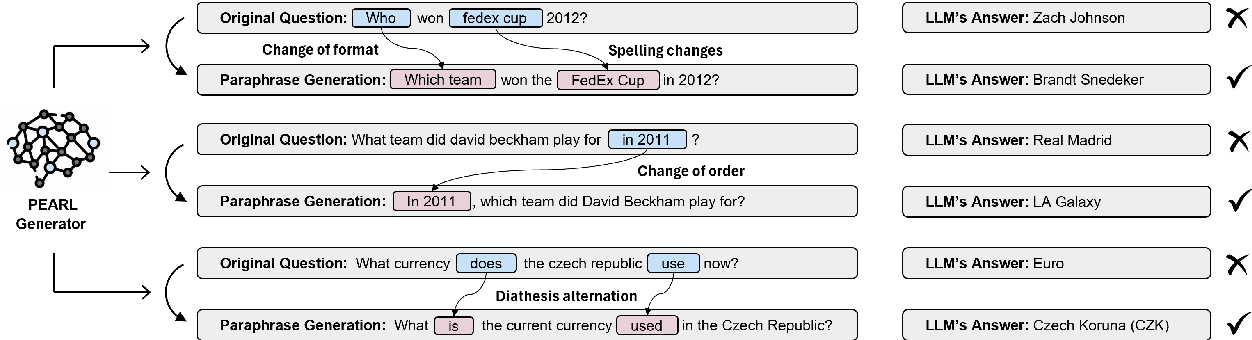
Figure 1 from Learning to Paraphrase for Alignment with LLM Preference ...

Learning to Paraphrase for Alignment with LLM Preference - ACL Anthology
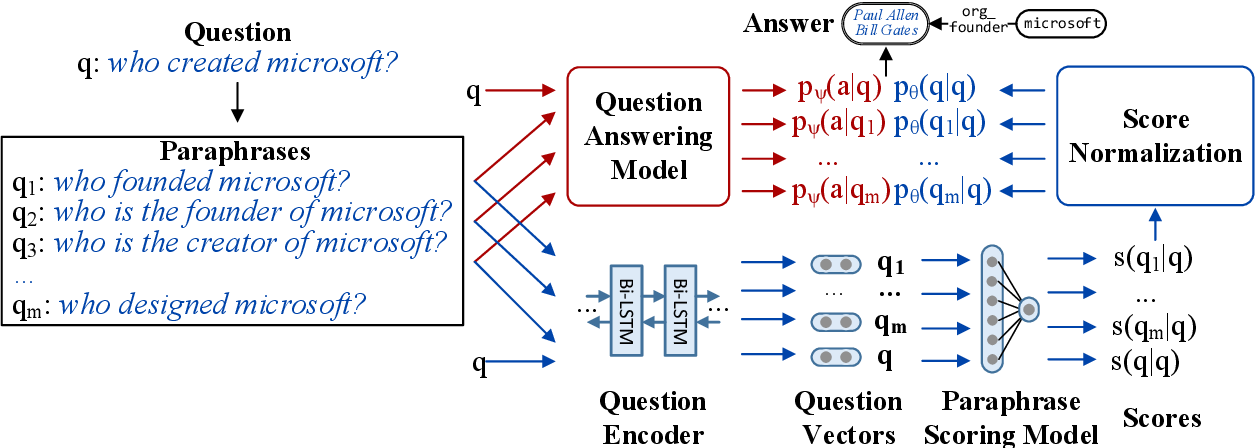
Figure 1 from Learning to Paraphrase for Question Answering | Semantic ...

Figure 1 from Your Weak LLM is Secretly a Strong Teacher for Alignment ...
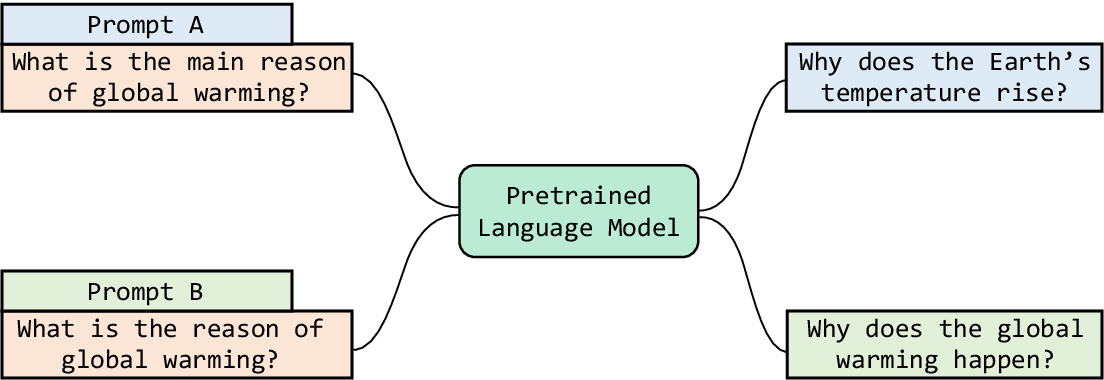
Figure 1 from Vector-Quantized Prompt Learning for Paraphrase ...
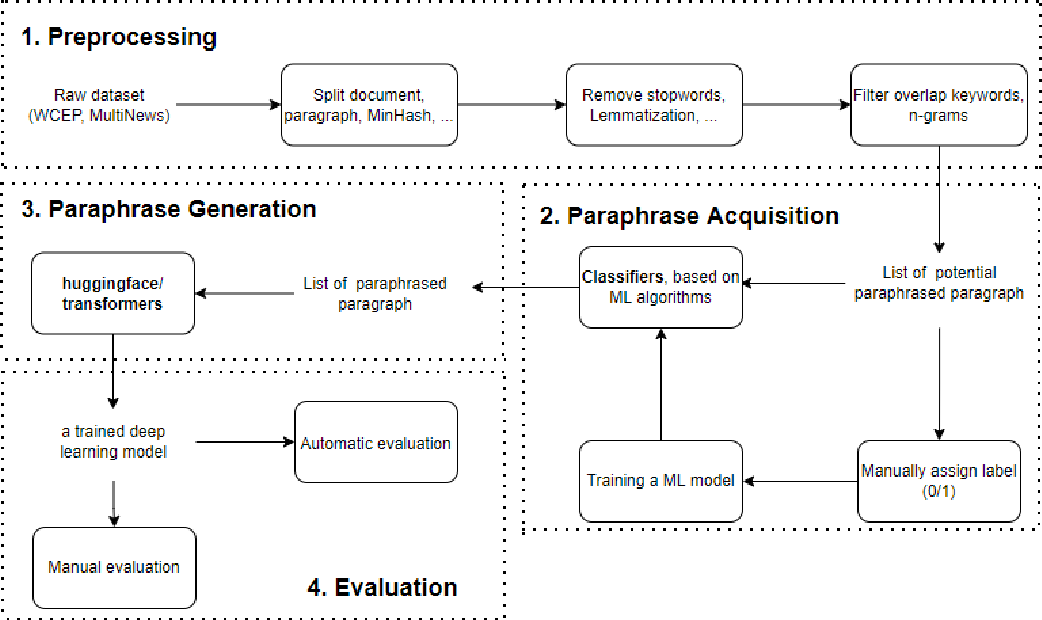
Figure 1.1 from Learning to Paraphrase from Multi-Document ...
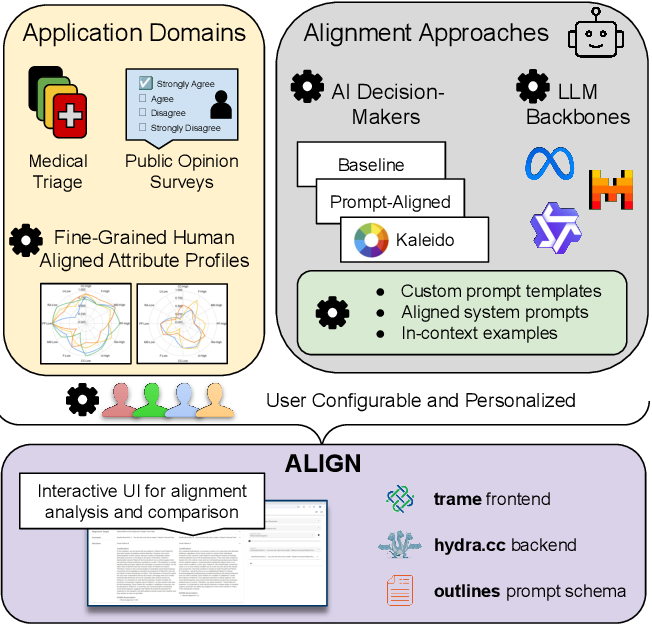
Figure 1 from ALIGN: Prompt-based Attribute Alignment for Reliable ...

Figure 1 from Inference time LLM alignment in single and multidomain ...

Table 1 from Aligning LLM Agents by Learning Latent Preference from ...
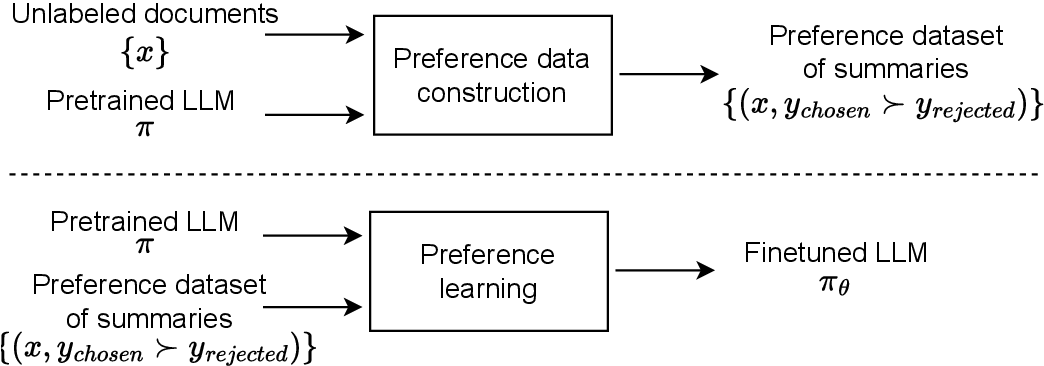
Figure 1 from Learning from Self Critique and Refinement for Faithful ...
Advertisement Space (300x250)

(PDF) Adversarial Preference Learning for Robust LLM Alignment

Figure 1 from Diversity-Enhanced Learning for Unsupervised ...

Figure 1 from Unintended Impacts of LLM Alignment on Global ...

Figure 1 from Diversity-Enhanced Learning for Unsupervised ...

Figure 1 from Learning From Mistakes Makes LLM Better Reasoner ...

Figure 1 from Learning Structural Information for Syntax-Controlled ...

Figure 1 from Which is better? Exploring Prompting Strategy For LLM ...

Figure 1 from Integrating Transformer and Paraphrase Rules for Sentence ...

Figure 1 from Exploring LLM-based Data Annotation Strategies for ...
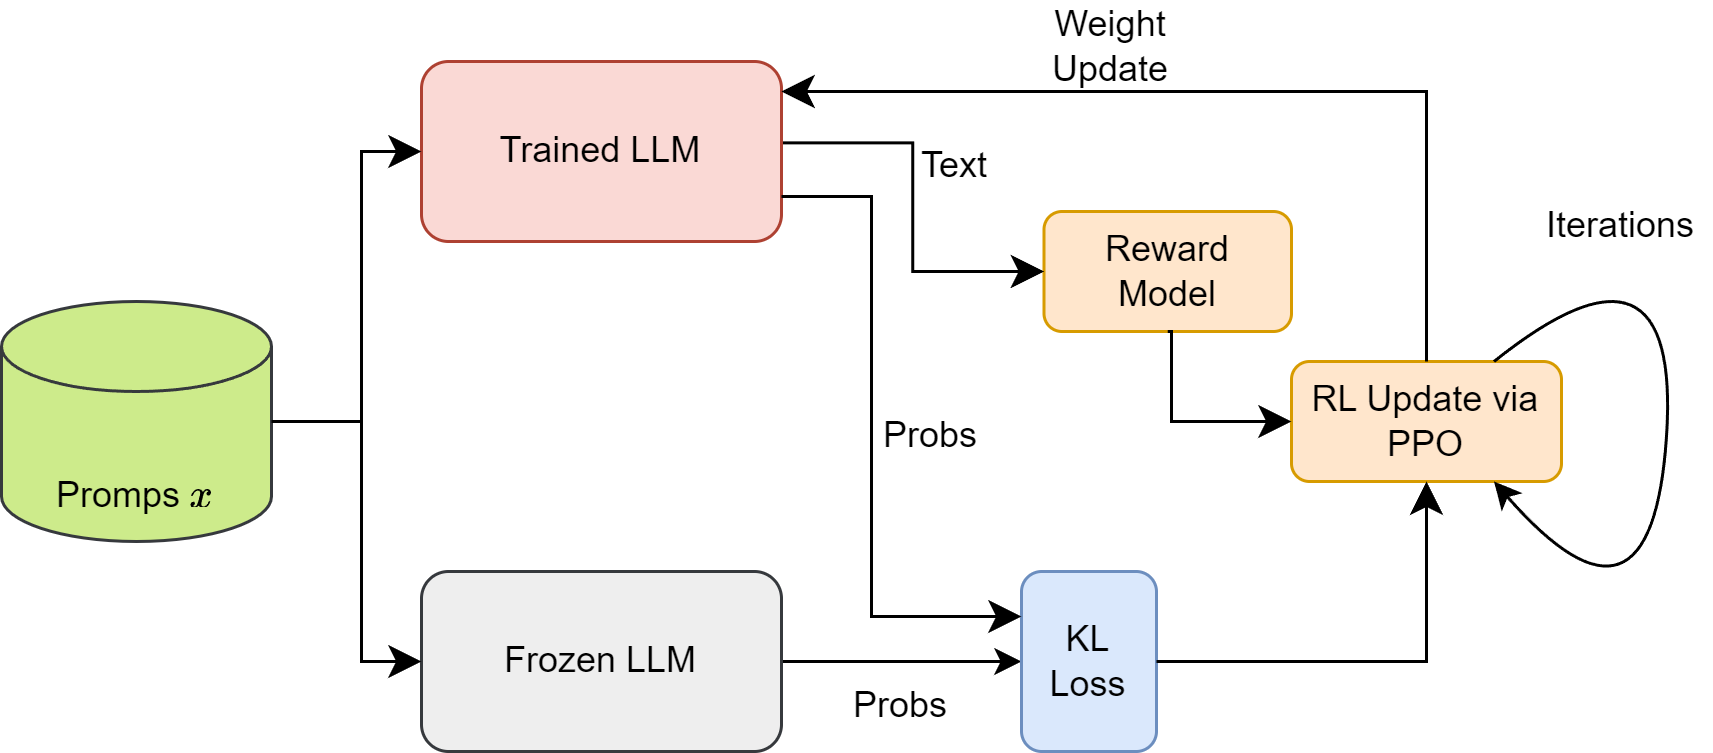
13. LLM Alignment and Preference Learning — LLM Foundations
Advertisement Space (336x280)

A Grounded Preference Model for LLM Alignment - ACL Anthology
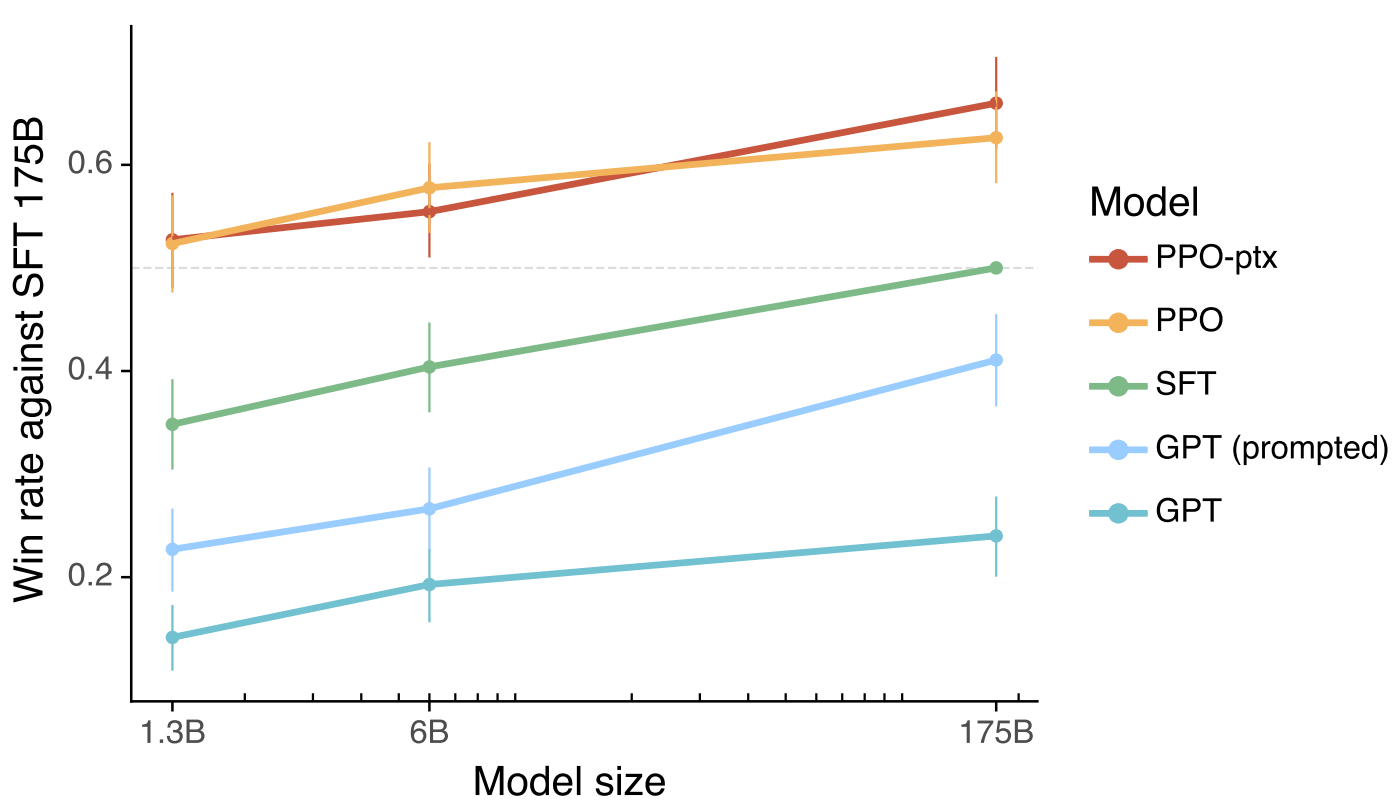
13. LLM Alignment and Preference Learning — LLM Foundations

Table 6 from Aligning LLM Agents by Learning Latent Preference from ...
Nearly Optimal Active Preference Learning and Its Application to LLM ...

Figure 2 from A Practice-Friendly LLM-Enhanced Paradigm with Preference ...

Figure 1 from Expanding Paraphrase Lexicons by Exploiting Generalities ...

Improving Preference Alignment of LLM with Inference-Free Self ...
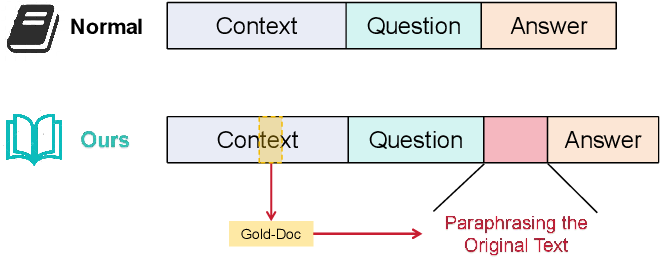
Figure 1 from Training with "Paraphrasing the Original Text" Teaches ...

Figure 1 from An Enhanced Prompt-Based LLM Reasoning Scheme via ...
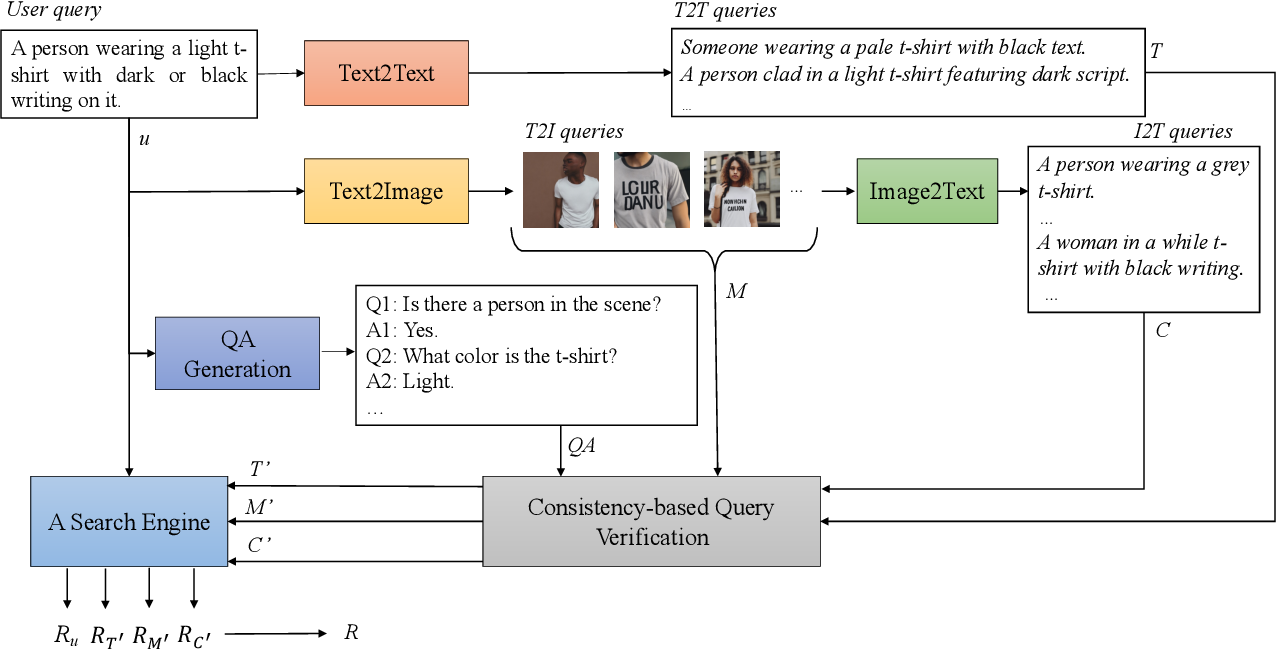
Figure 1 from Multimodal LLM-based Query Paraphrasing for Video Search ...
Advertisement Space (336x280)

From Prompting to Preference Optimization: A Comparative Study of LLM ...

Aligning LLM Agents by Learning Latent Preference From User Edits | PDF ...

(PDF) Learning Paraphrase Identification with Structural Alignment

Self-Adaptive Paraphrasing and Preference Learning for Improved Claim ...
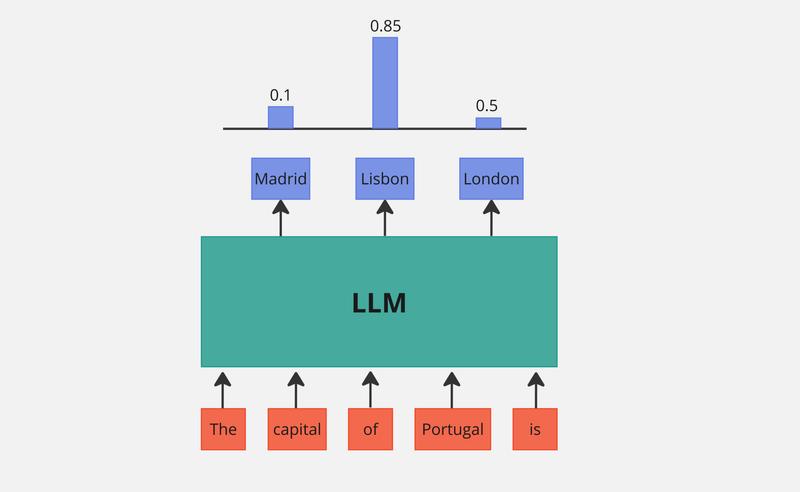
LLM Preference Alignment

Reinforcement learning with human feedback (RLHF) for LLMs | SuperAnnotate