
Figure 1 From Low Complexity Multi Channel Speaker Extraction With Pure

Figure 1 from Low-complexity Multi-Channel Speaker Extraction with Pure ...
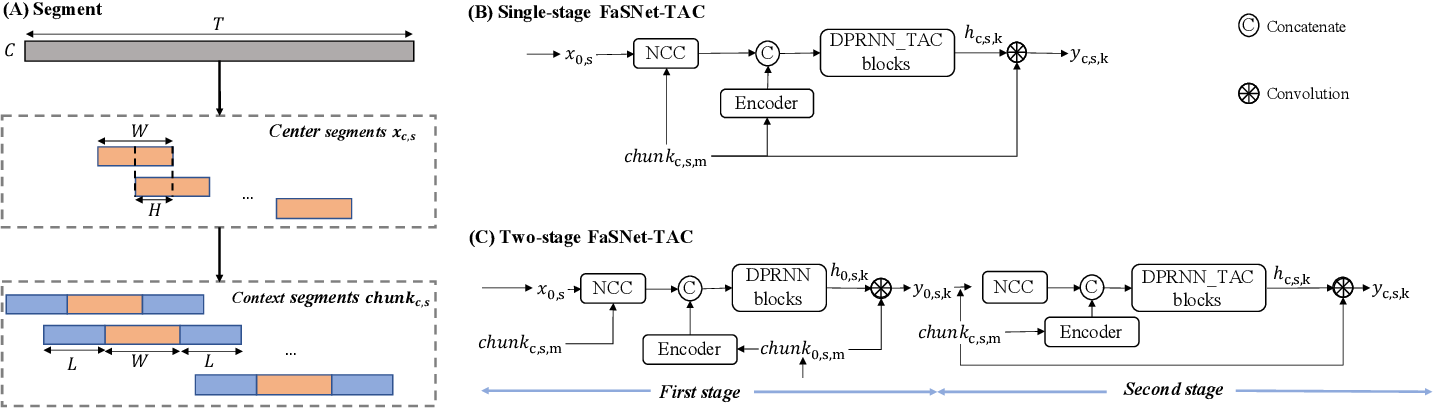
Figure 1 from Low-complexity Multi-Channel Speaker Extraction with Pure ...
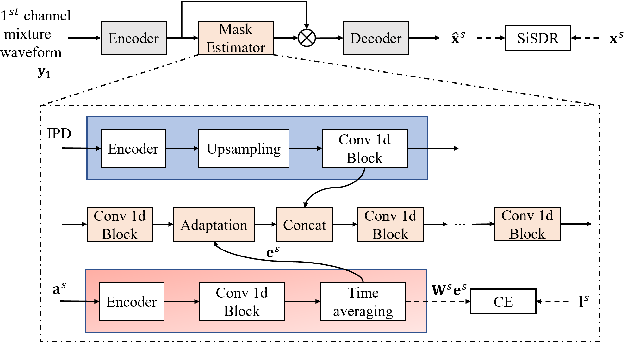
Figure 1 from Multi-Channel Target Speech Extraction with Channel ...

Figure 1 from Multi-Stage Speaker Extraction with Utterance and Frame ...
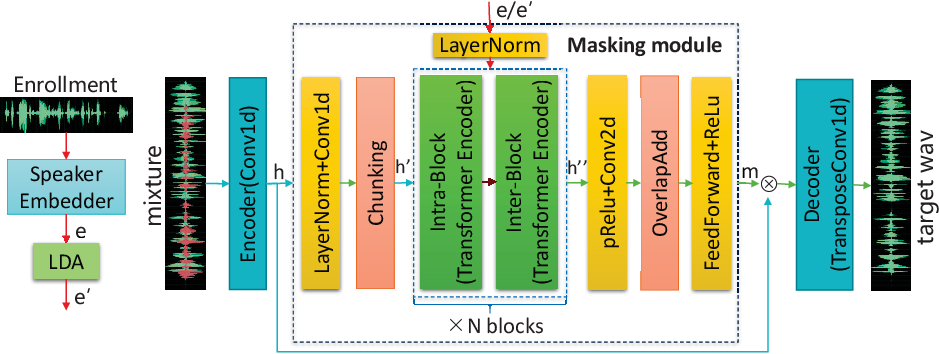
Figure 1 from Improving Target Speaker Extraction with Sparse LDA ...

Figure 1 from Multi-Channel Target Speaker Extraction with Refinement ...
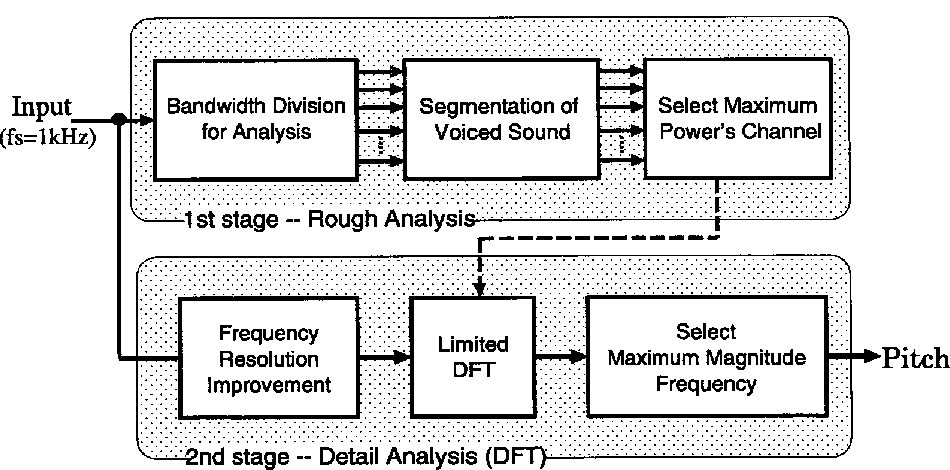
Figure 1 from A pitch extraction method using multi channel modulation ...
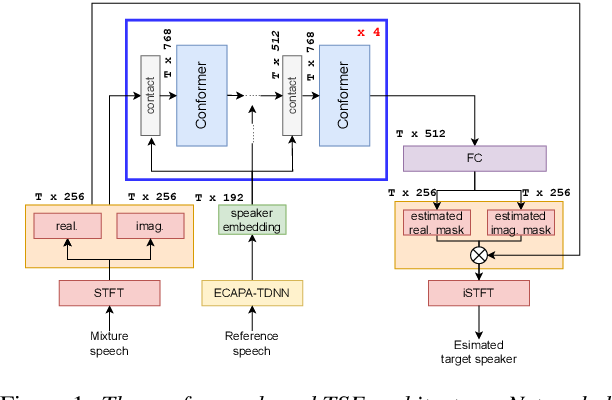
Figure 1 from Target Speaker Extraction with Curriculum Learning ...

Figure 1 from Target Speaker Extraction with Attention Enhancement and ...

Figure 1 from Speaker Extraction with Detection of Presence and Absence ...
Advertisement Space (300x250)

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...

Figure 1 from Single Channel Target Speaker Extraction Based on Deep ...
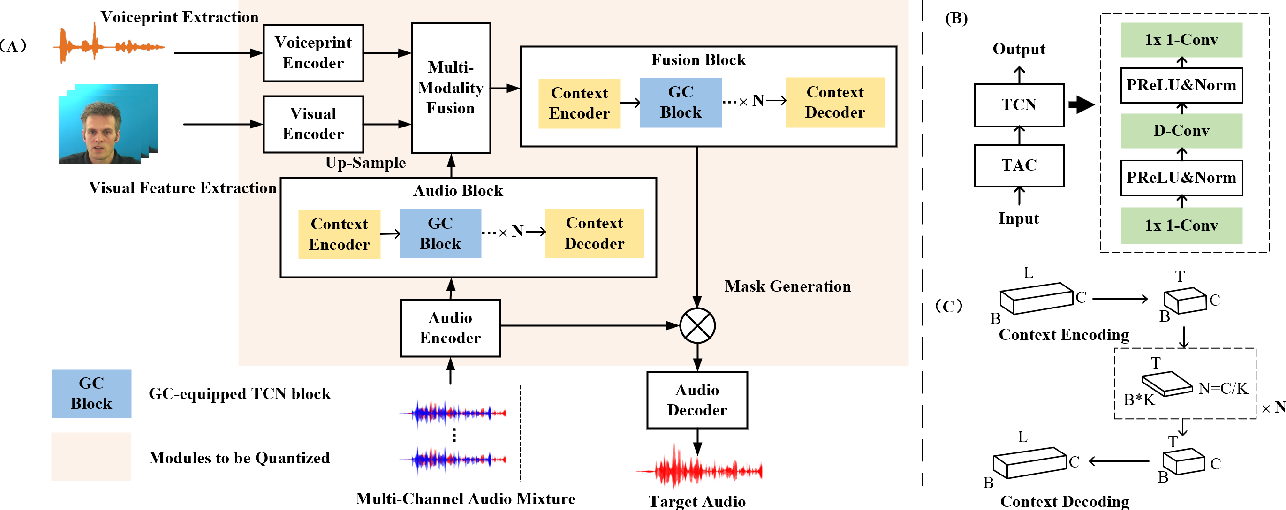
Figure 1 from LiMuSE: Lightweight Multi-Modal Speaker Extraction ...

Figure 1 from Target Speaker Extraction for Multi-Talker Speaker ...
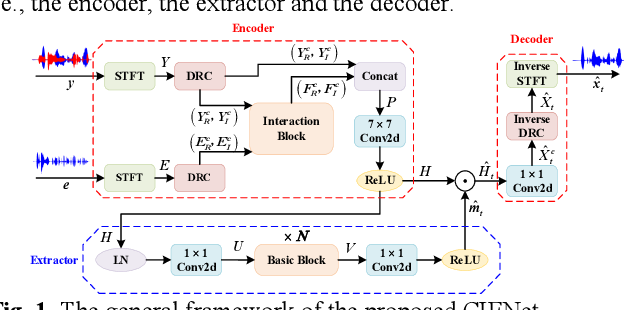
Figure 1 from Target Speaker Extraction by Directly Exploiting ...

Figure 1 from Voice Feature Extraction Method Analysis for Speaker ...

Figure 4 from Enhancing Real-World Active Speaker Detection with Multi ...

Figure 1 from Investigation on Deep Speaker Embedding Extraction ...
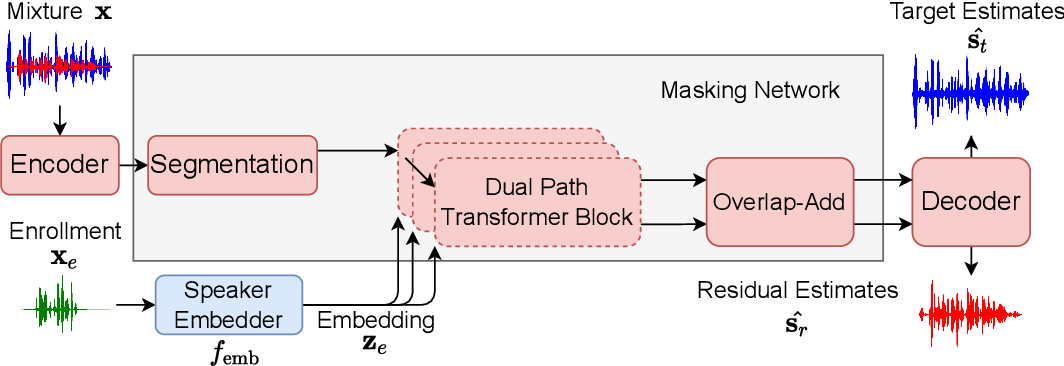
Figure 1 from Semi-supervised Time Domain Target Speaker Extraction ...
Advertisement Space (336x280)
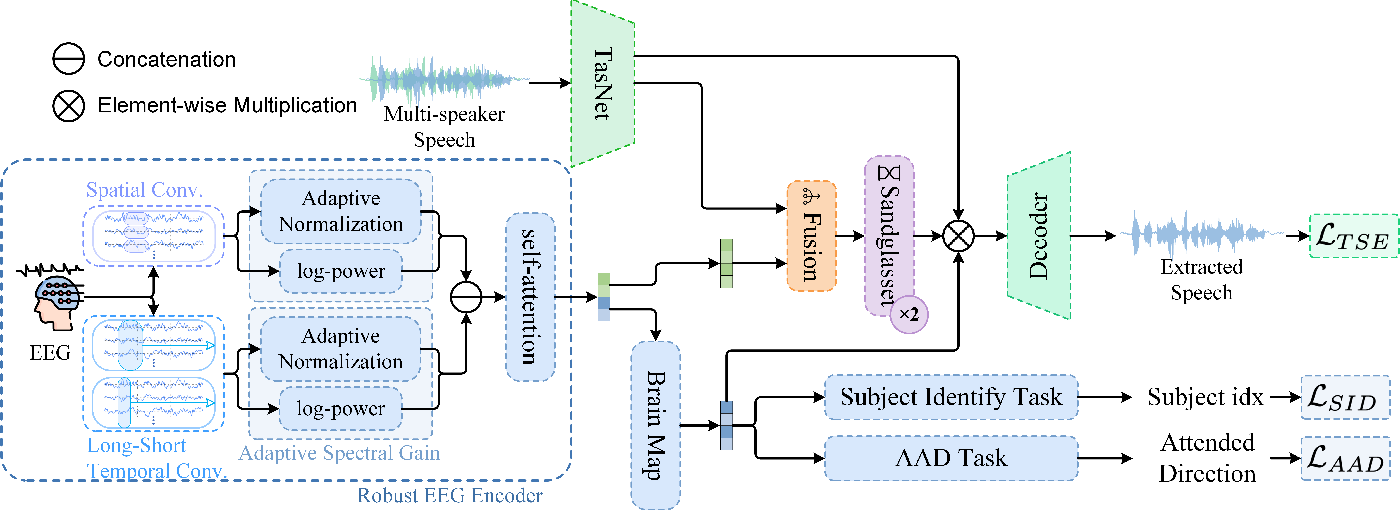
Figure 1 from Brainprint-Modulated Target Speaker Extraction | Semantic ...
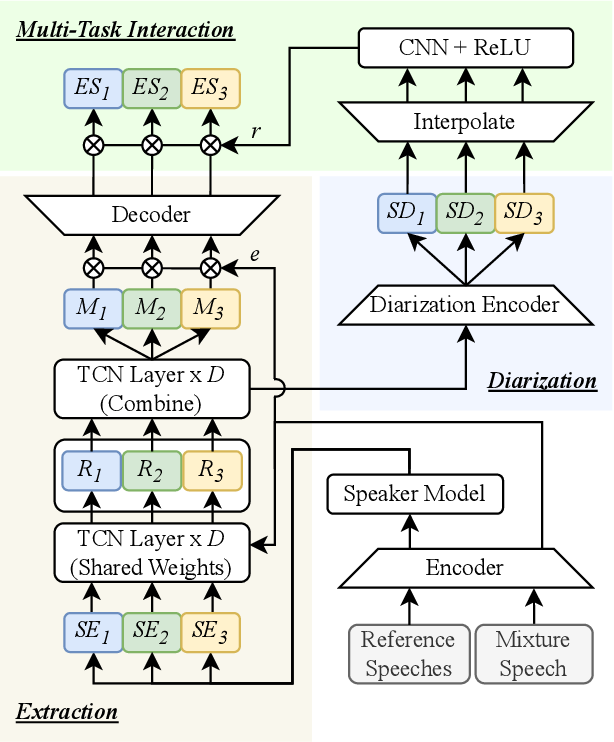
Figure 1 from USED: Universal Speaker Extraction and Diarization ...

Figure 1 from Universal Speaker Extraction in the Presence and Absence ...

Figure 11 from Audio-Visual Target Speaker Extraction with Reverse ...
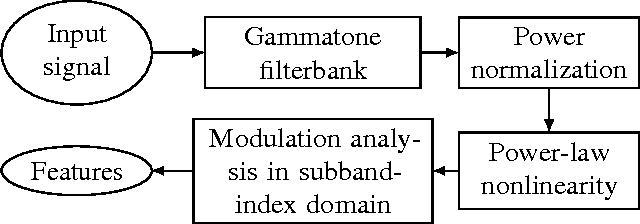
Figure 1 from Feature extraction with a multiscale modulation analysis ...
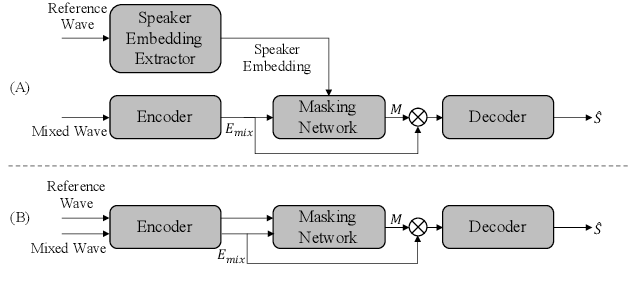
Figure 1 from SEF-Net: Speaker Embedding Free Target Speaker Extraction ...

Figure 1 from Speech Rhythm-Based Speaker Embeddings Extraction from ...
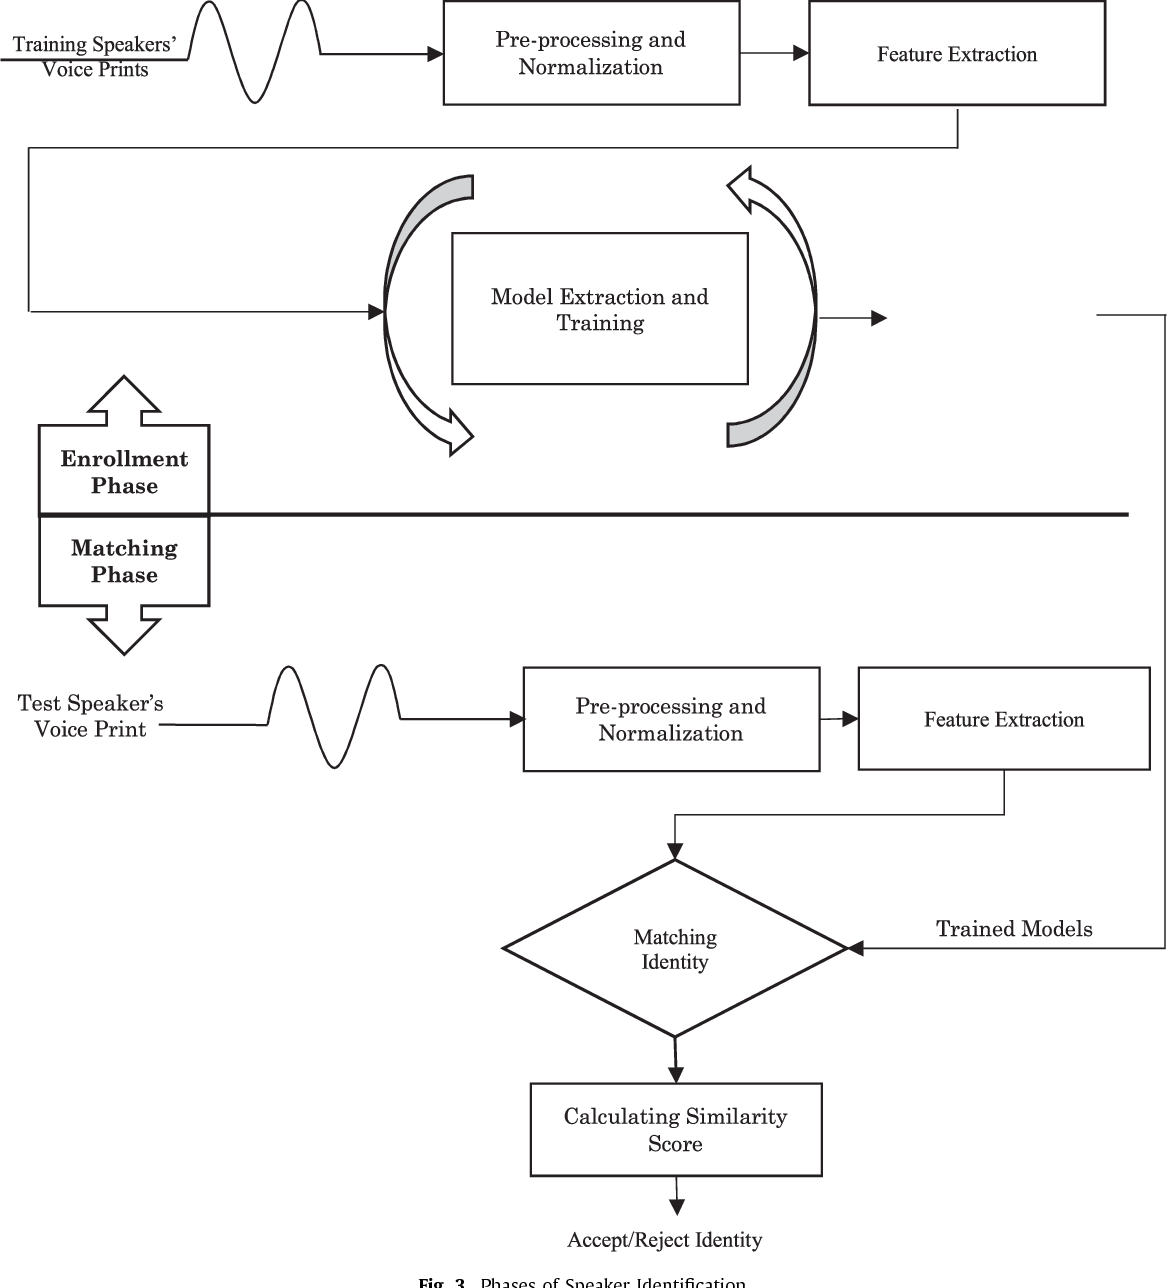
Figure 1 from Speaker identification features extraction methods: A ...
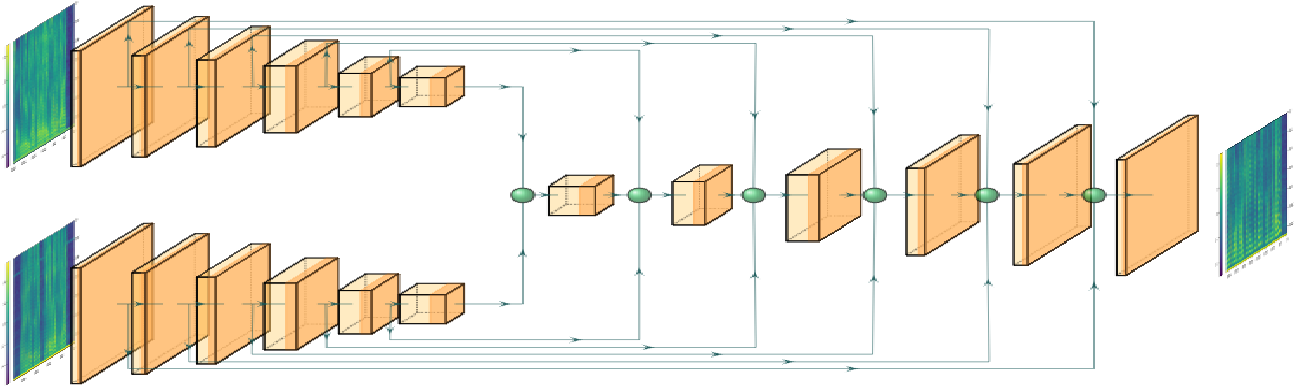
Figure 1 from Single microphone speaker extraction using unified time ...

Figure 1 from Physiologically-motivated feature extraction for speaker ...
Advertisement Space (336x280)

Figure 1 from Binaural Target Speaker Extraction using Individualized ...
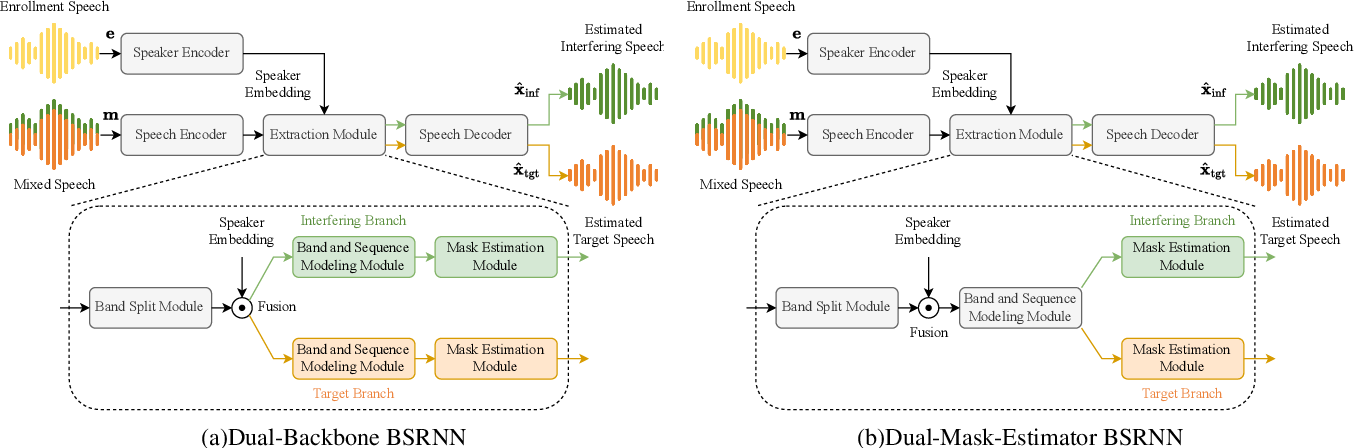
Figure 1 from Enhancing Speaker Extraction Through Rectifying Target ...
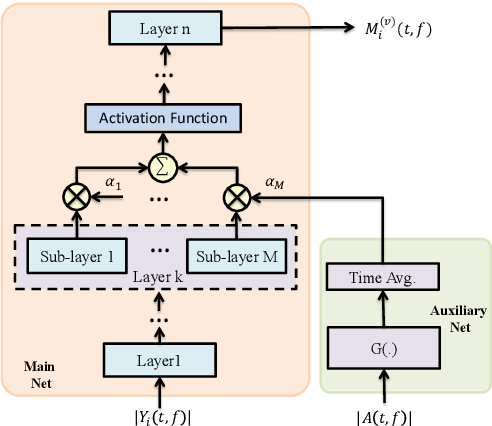
Figure 1 from Direction-Aware Speaker Beam for Multi-Channel Speaker ...
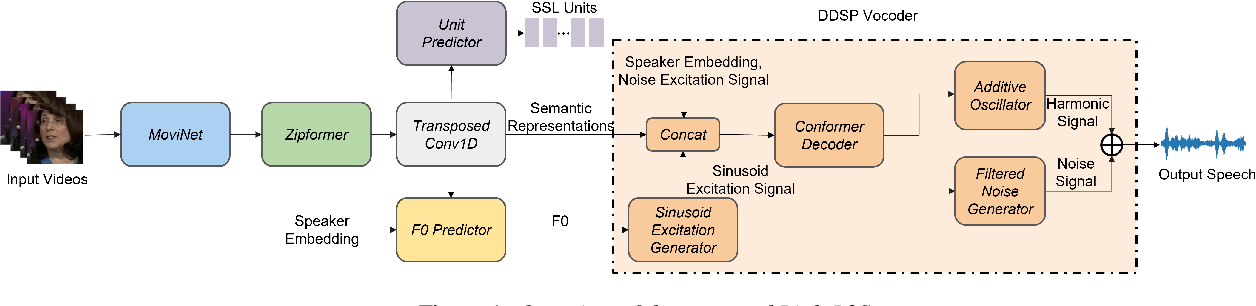
Figure 1 from LightL2S: Ultra-Low Complexity Lip-to-Speech Synthesis ...
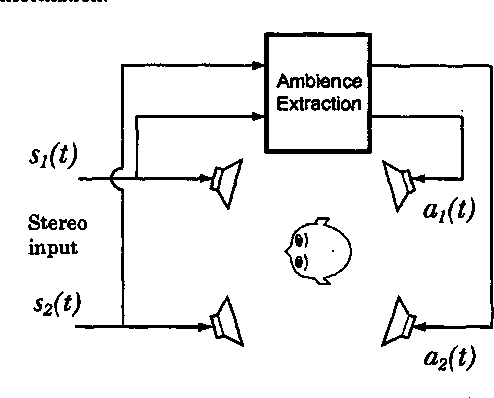
Figure 1 from Ambience extraction and synthesis from stereo signals for ...
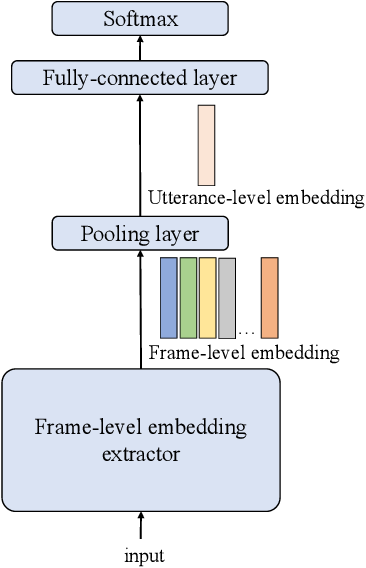
Figure 1 from Spatial-temporal Graph Based Multi-channel Speaker ...