
Figure 1 From Many To One Voice Conversion Using Exemplar Based Sparse
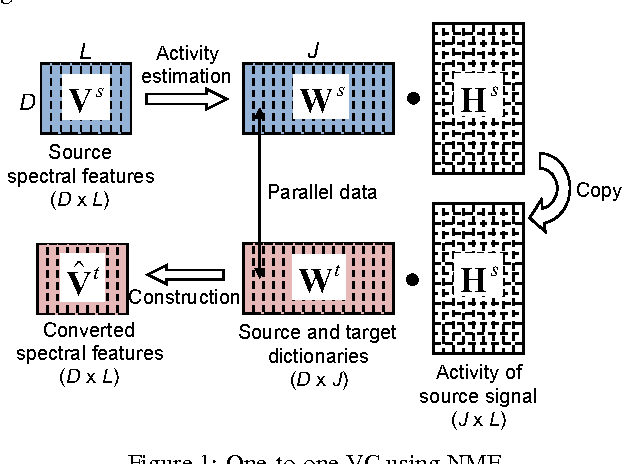
Figure 1 from Many-to-one voice conversion using exemplar-based sparse ...
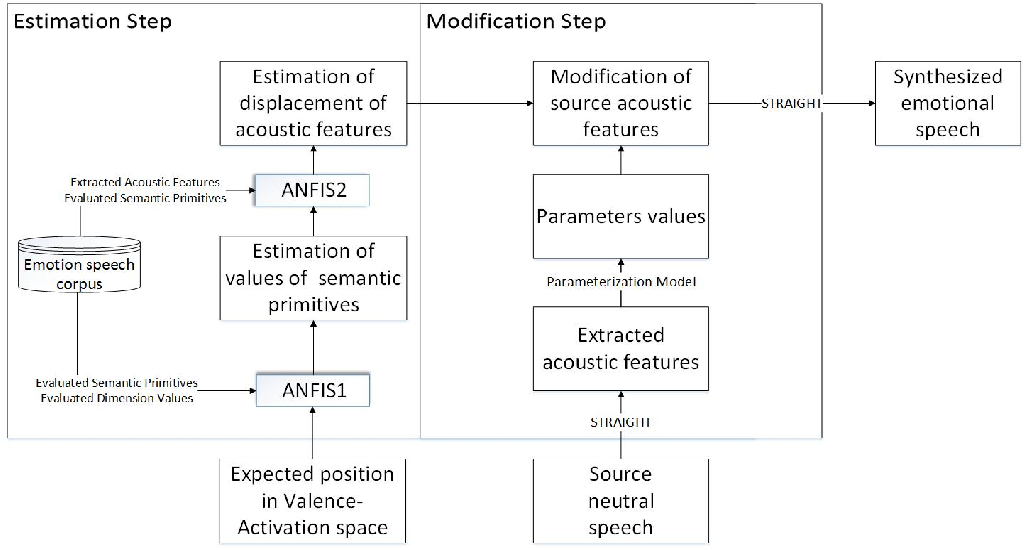
Figure 1 from Voice conversion to emotional speech based on three ...

Figure 1 from A Voice Conversion Framework with Tandem Feature Sparse ...

Figure 1 from Any-to-One Sequence-to-Sequence Voice Conversion Using ...

Figure 1 from Many-to-many voice conversion based on multiple non ...

Figure 1 from Non-parallel and Many-to-Many Voice Conversion Using ...

Figure 2 from Enhancing Zero-Shot Many to Many Voice Conversion with ...
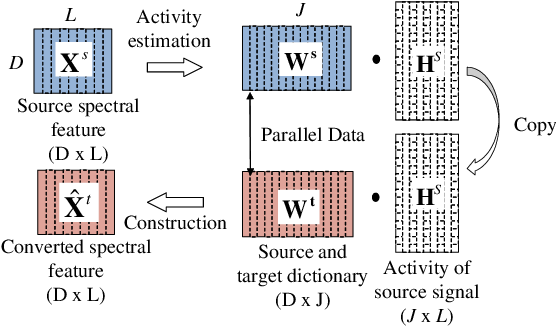
Figure 1 from Multimodal exemplar-based voice conversion using lip ...

Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

Figure 1 from Average Modeling Approach to Voice Conversion with Non ...
Advertisement Space (300x250)
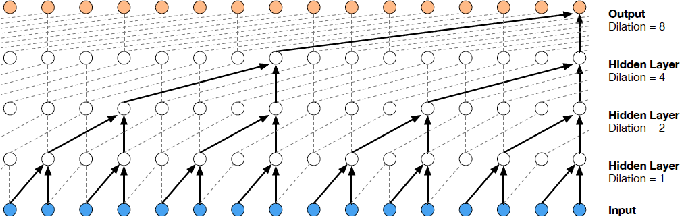
Figure 1 from A Survey on Voice Conversion using Deep Learning ...

Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from Statistical Voice Conversion Based on Wavenet | Semantic ...
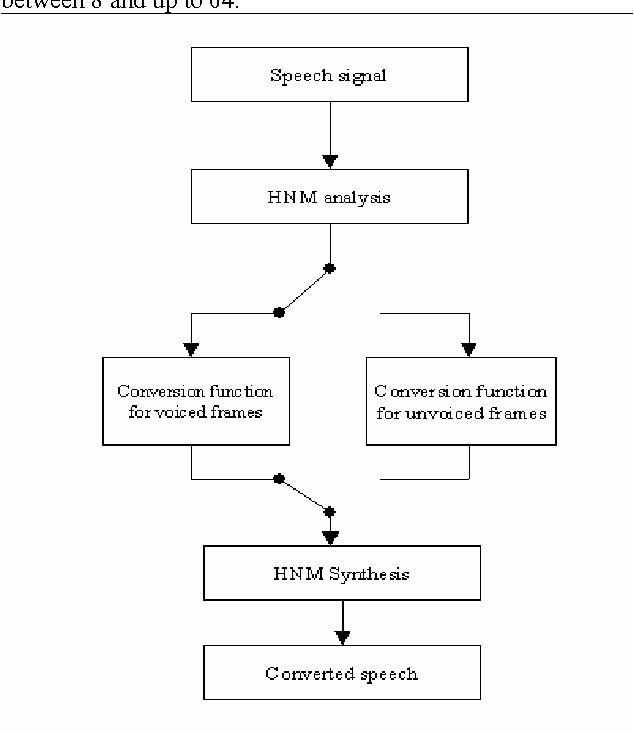
Figure 1 from A voice conversion method based on joint pitch and ...

Figure 1 from An evaluation of many-to-one voice conversion algorithms ...
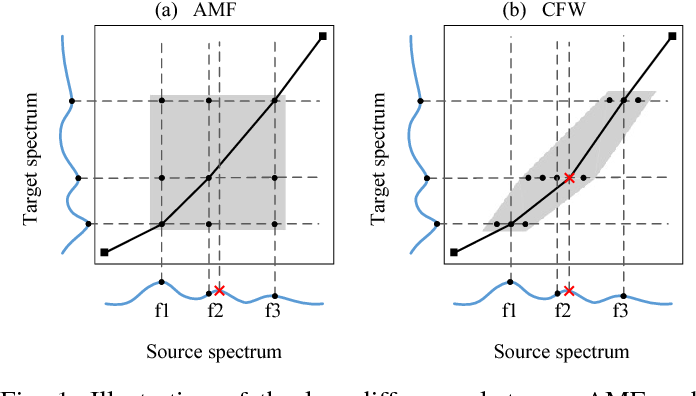
Figure 1 from An Exemplar-Based Approach to Frequency Warping for Voice ...

Figure 1 from An overview of voice conversion systems | Semantic Scholar

Figure 1 from Nonparallel Training of Exemplar-Based Voice Conversion ...
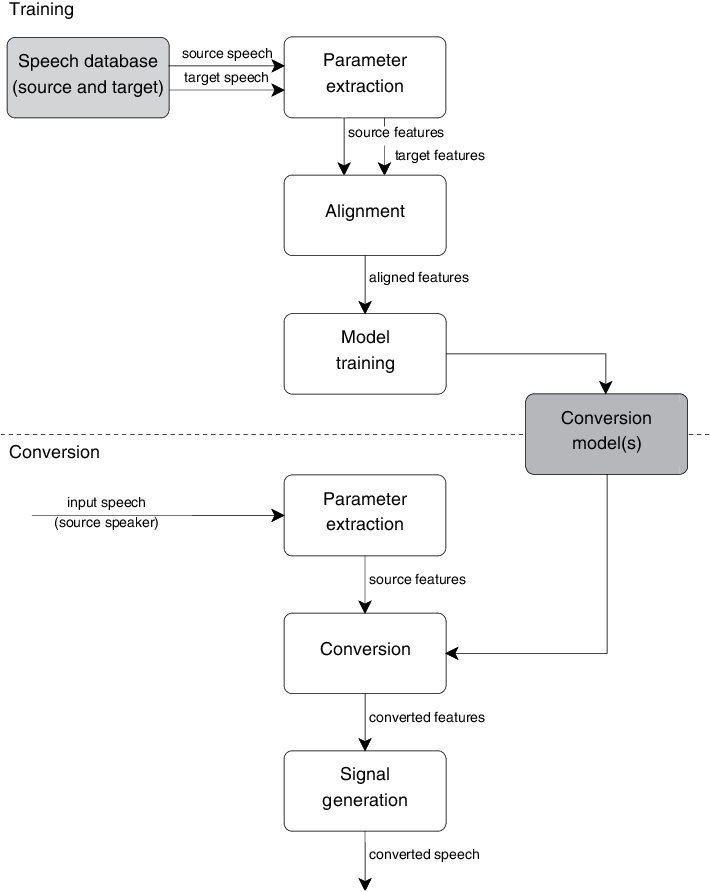
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...
Advertisement Space (336x280)

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from F0-Consistent Many-To-Many Non-Parallel Voice Conversion ...
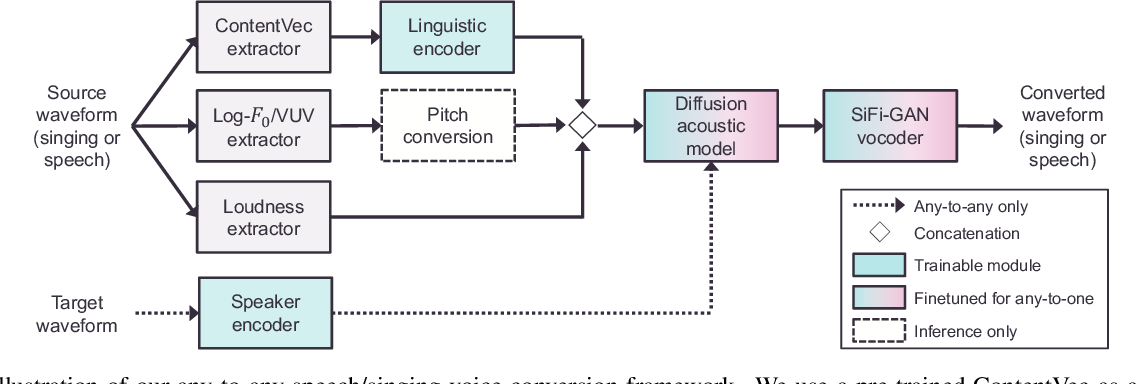
Figure 1 from A Comparative Study of Voice Conversion Models with Large ...

Figure 1 from Text-Free Non-Parallel Many-To-Many Voice Conversion ...
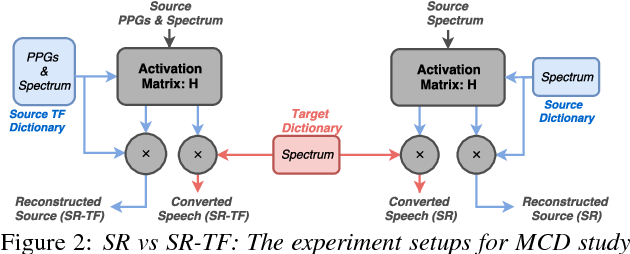
Figure 2 from A Voice Conversion Framework with Tandem Feature Sparse ...

Figure 1 from Voice Conversion Augmentation for Speaker Recognition on ...
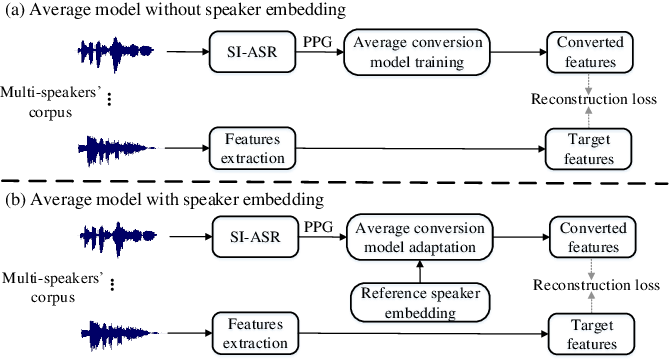
Figure 1 from Optimizing Voice Conversion Network with Cycle ...

Figure 1 from Statistical singing voice conversion with direct waveform ...
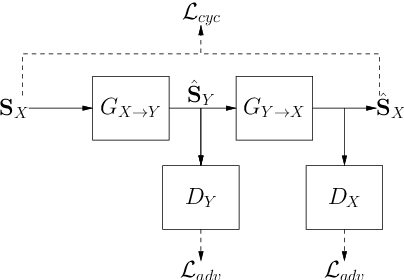
Figure 1 from The UFRJ Entry for the Voice Conversion Challenge 2020 ...
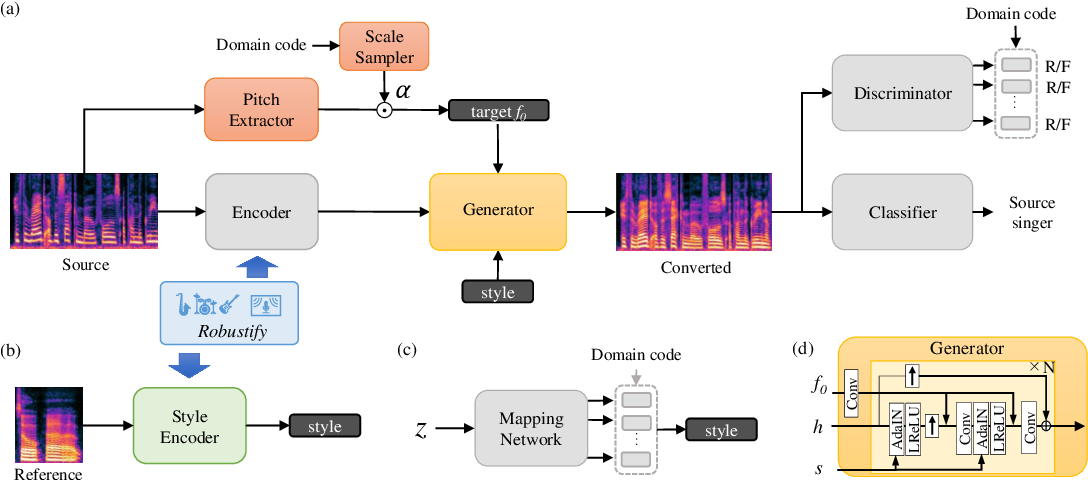
Figure 1 from Robust One-Shot Singing Voice Conversion | Semantic Scholar
Advertisement Space (336x280)
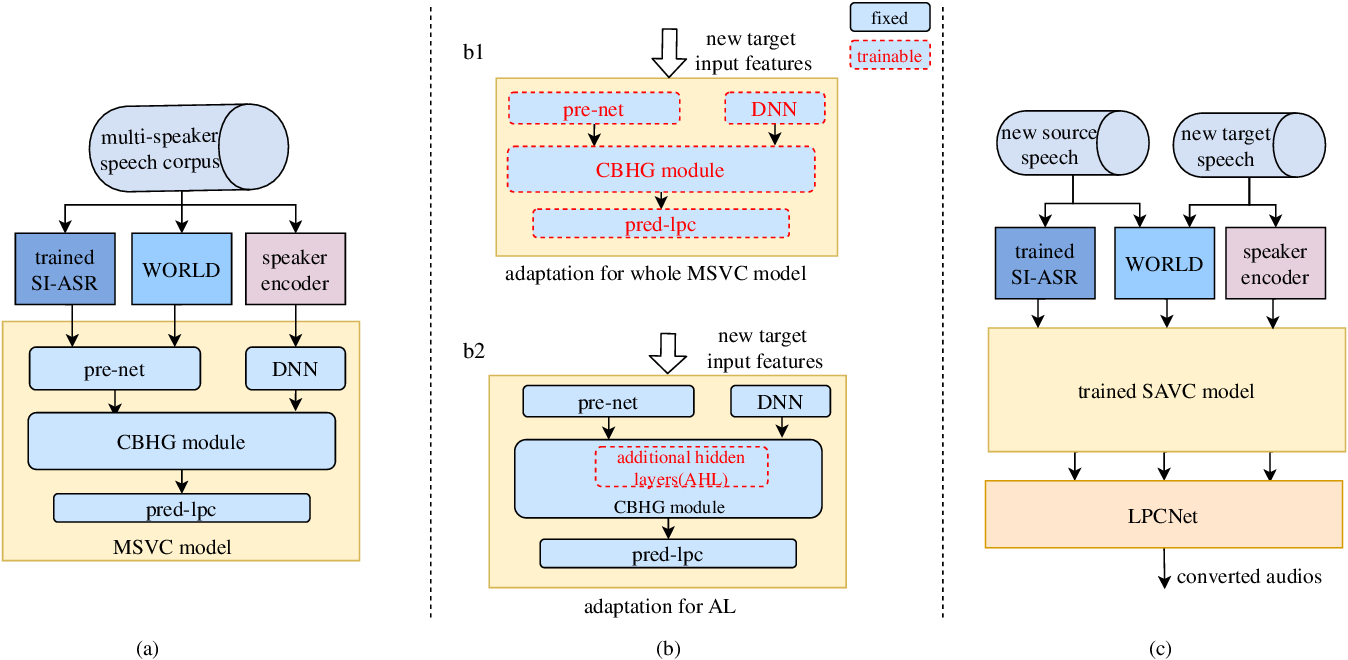
Figure 1 from Voice Conversion towards Arbitrary Speakers With Limited ...

Figure 2 from Voice Conversion Using Sequence-to-Sequence Learning of ...

Figure 2 from Many-to-Many Voice Conversion Using Cycle-Consistent ...

Figure 1 from Improving robustness of one-shot voice conversion with ...
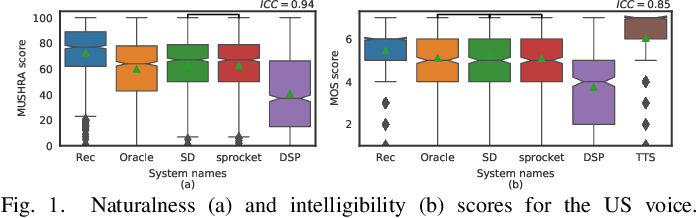
Figure 1 from Voice Conversion for Whispered Speech Synthesis ...
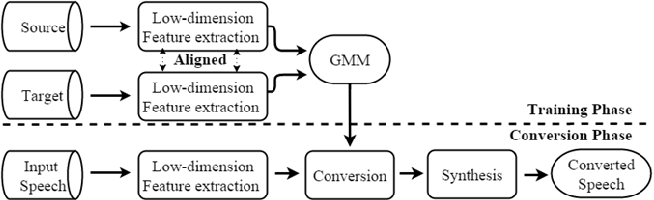
Figure 1 from Mandarin electrolaryngeal voice conversion with ...