
Figure 1 From Modeling Consistency In A Speaker Independent Continuous
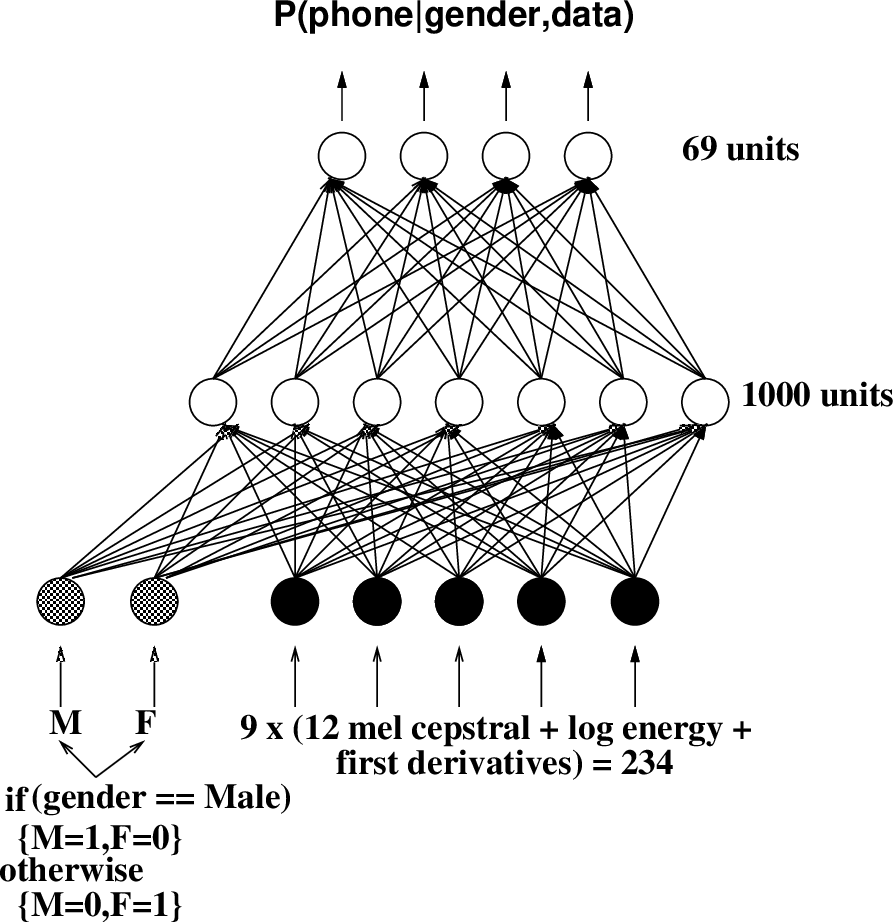
Figure 1 from Modeling Consistency in a Speaker Independent Continuous ...

Figure 1 from Towards Model Consistency Representations in a Multi ...
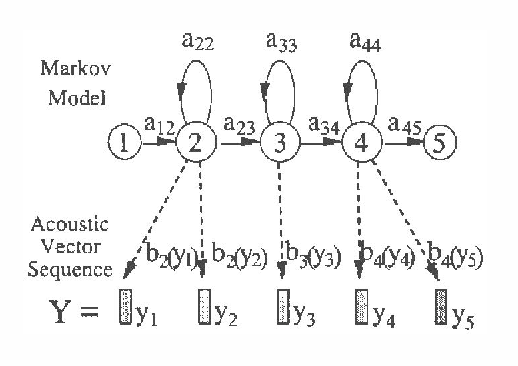
Figure 1 from Statistical Modeling in Continuous Speech Recognition ...
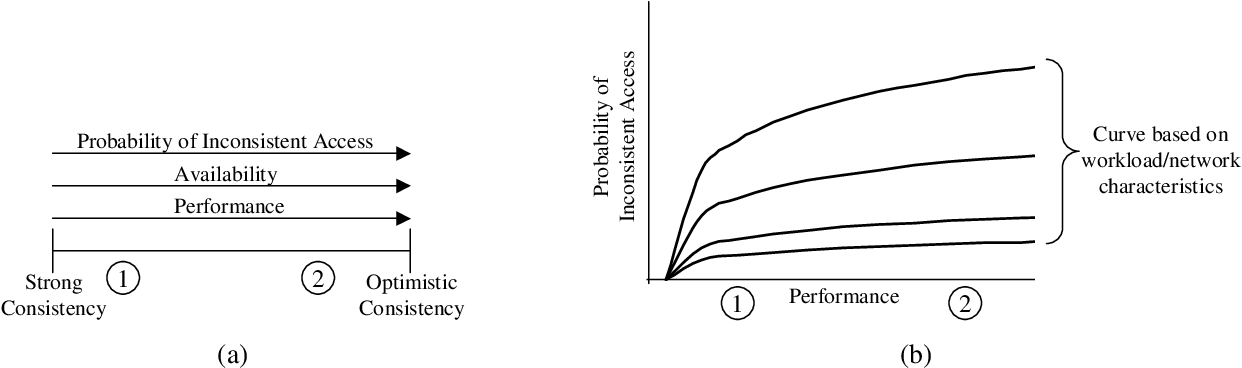
Figure 1 from Design and evaluation of a continuous consistency model ...
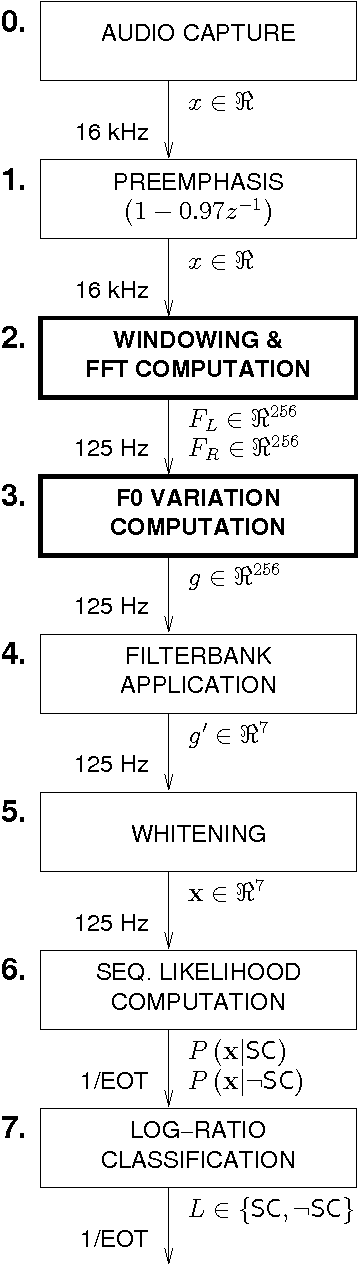
Figure 1 from Continuous Modeling of Intonation in Natural Speech Has ...
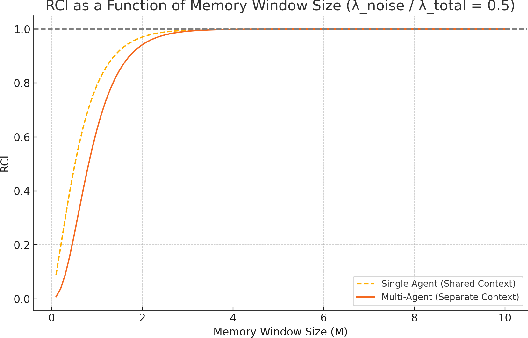
Figure 1 from Modeling Response Consistency in Multi-Agent LLM Systems ...
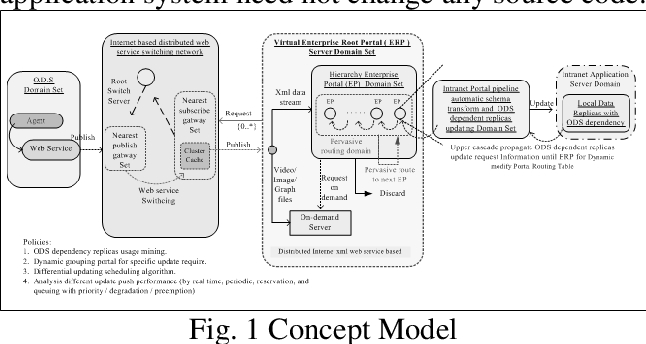
Figure 1 from A consistency maintenance project independent ...
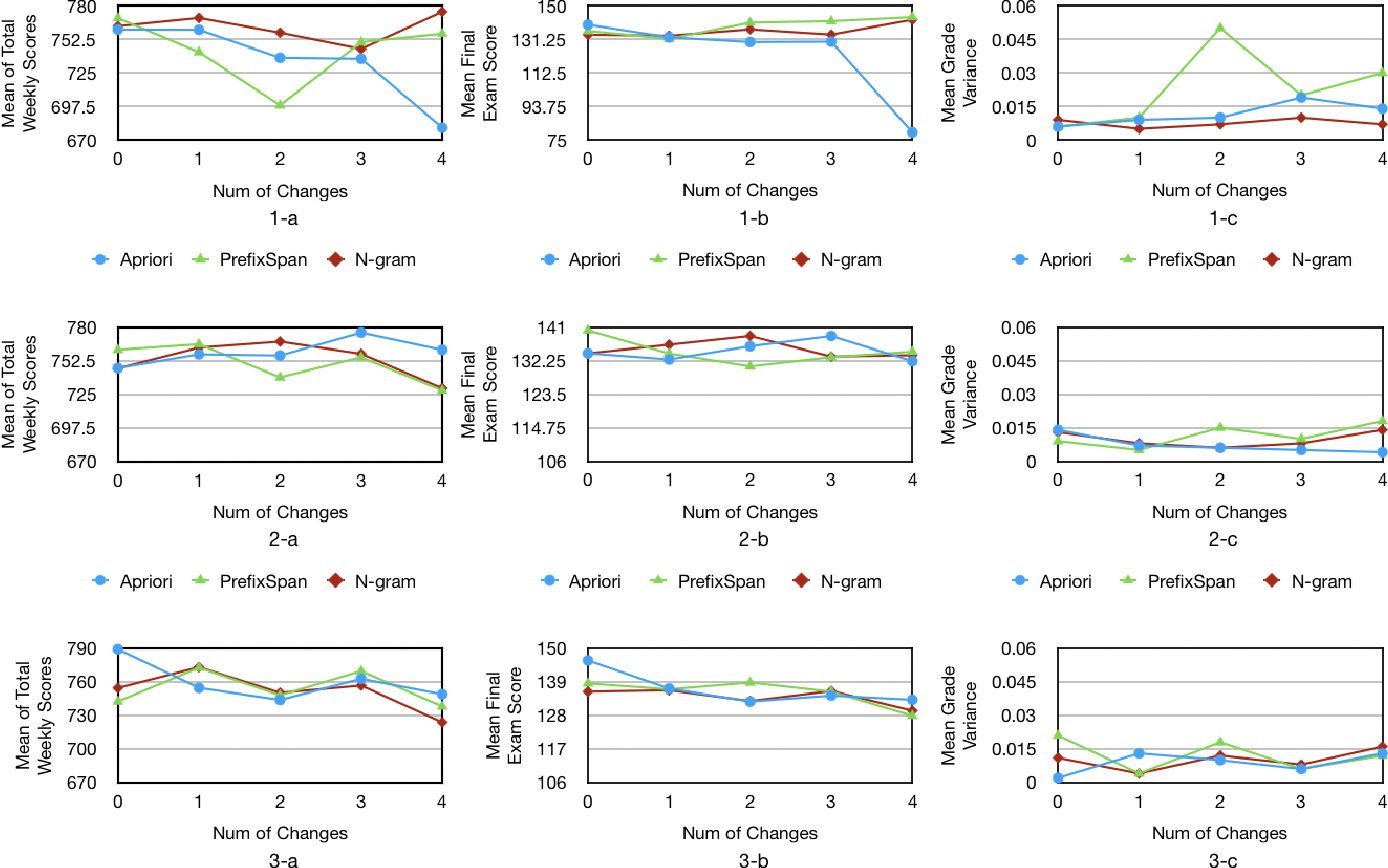
Figure 1 from Modeling Consistency Using Engagement Patterns in Online ...

Figure 1 from Modeling inter-speaker variability in speech recognition ...

Figure 1 from Automated modelling of Chinese intonation in continuous ...
Advertisement Space (300x250)

Figure 1 from Design and evaluation of a conit-based continuous ...

Figure 1 from Using Joint Training Speaker Encoder With Consistency ...

Figure 1 from Fostering Model Consistency in Interdisciplinary ...

Figure 1 from Cross-Sentence Gloss Consistency for Continuous Sign ...
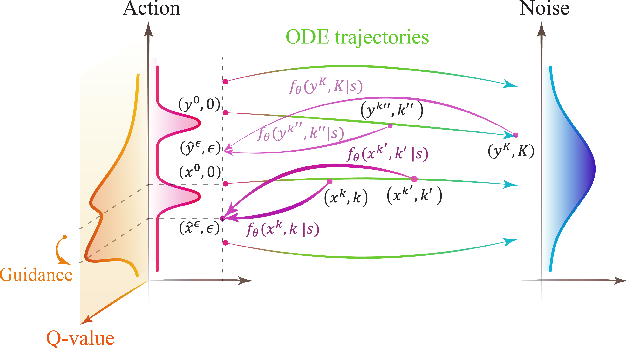
Figure 1 from Boosting Continuous Control with Consistency Policy ...

Figure 1 from Modeling Consistency Preference via Lexical Chains for ...

Figure 3 from Design and evaluation of a continuous consistency model ...
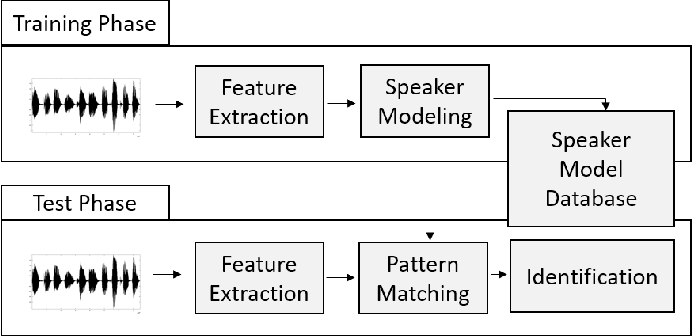
Figure 1 from Performance Analysis of Speaker Identification using ...

Figure 1 from Synthetic Speech Detection Based on Temporal Consistency ...

Figure 1 from Factual Consistency Oriented Speech Recognition ...
Advertisement Space (336x280)
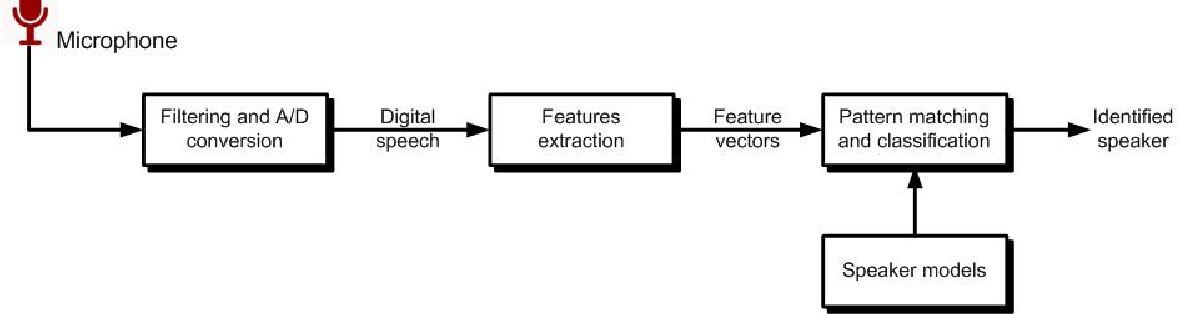
Figure 2.1 from Autoregressive models for text independent speaker ...

Figure 1 from Delayed Consistency Model for Distributed Interactive ...

Figure 1 from Multi-View Graph Learning by Joint Modeling of ...
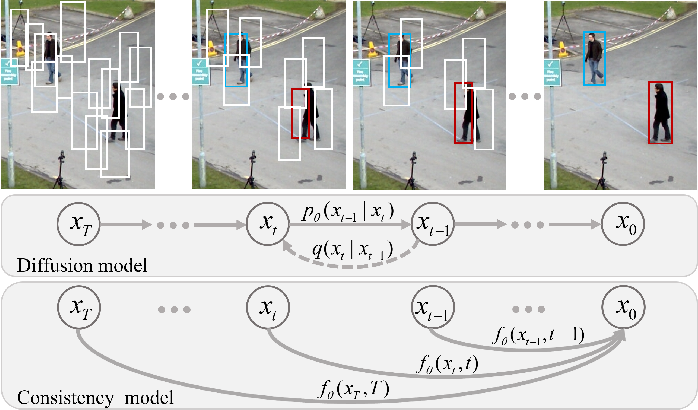
Figure 1 from ConsistencyDet: A Few-step Denoising Framework for Object ...

Figure 1 from Multi-View Graph Learning by Joint Modeling of ...
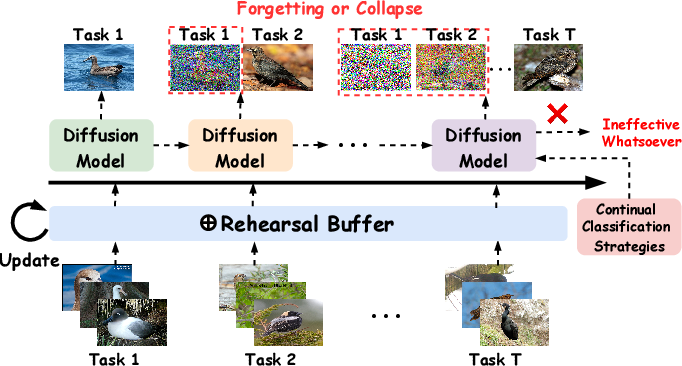
Figure 1 from CCD: Continual Consistency Diffusion for Lifelong ...
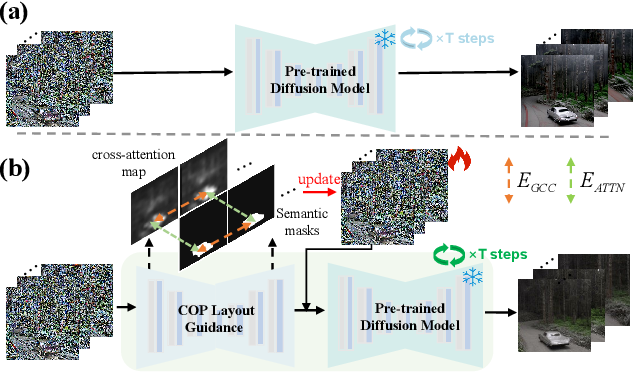
Figure 1 from CLGC: Continuous Layout Guidance for Consistent Text-to ...

Figure 1 from What Do Self-Supervised Speech and Speaker Models Learn ...
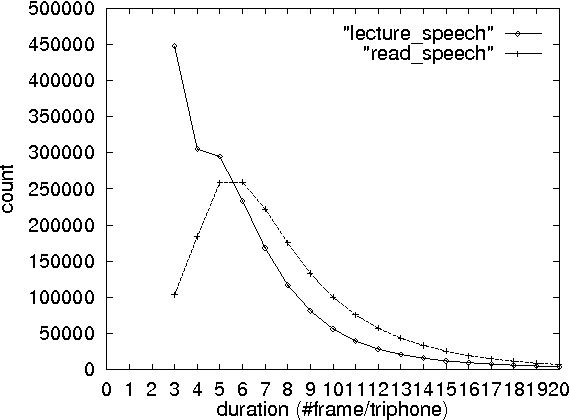
Figure 1 from Speaking rate dependent acoustic modeling for spontaneous ...
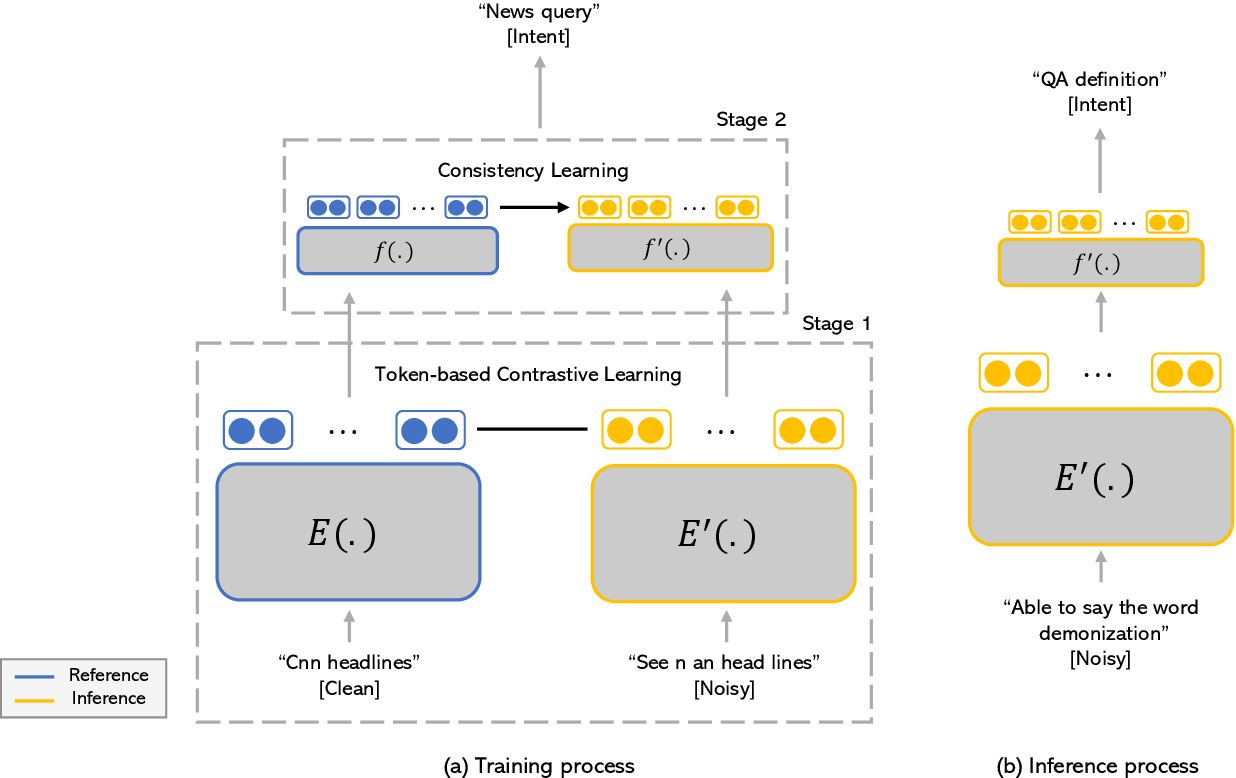
Figure 1 from Contrastive and Consistency Learning for Neural Noisy ...
Advertisement Space (336x280)
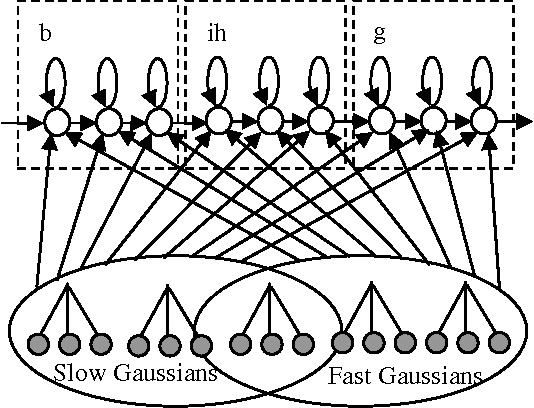
Figure 1 from Effective acoustic modeling for rate-of-speech variation ...
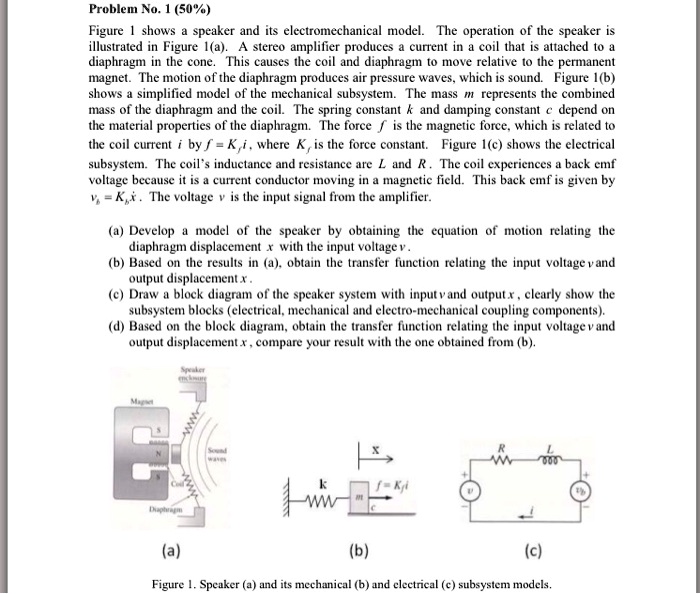
problem no1 50 figure 1 shows a speaker and its electromechanical model ...
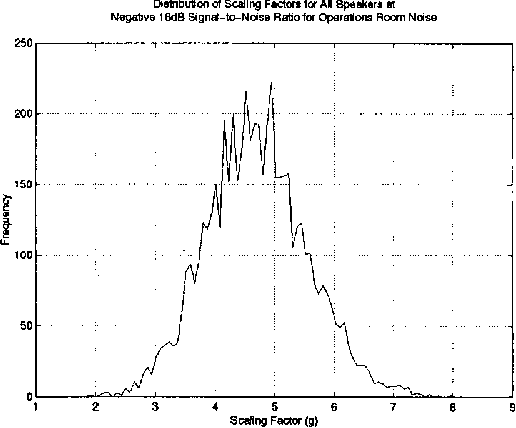
Figure 1 from Text-dependent speaker verification under noisy ...

Figure 1 from Quantifying Prediction Consistency Under Model ...

Figure 1 from Continuous Speech Separation: Dataset and Analysis ...
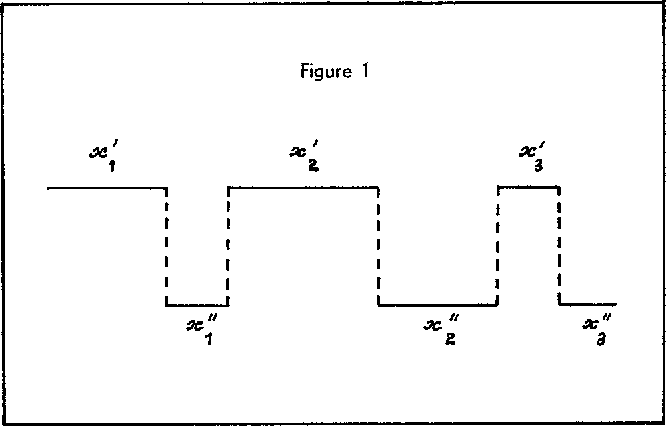
Figure 1 from A Stochastic Model of Radio Listening | Semantic Scholar