
Figure 1 From Mofo Motion Focused Self Supervision For Video
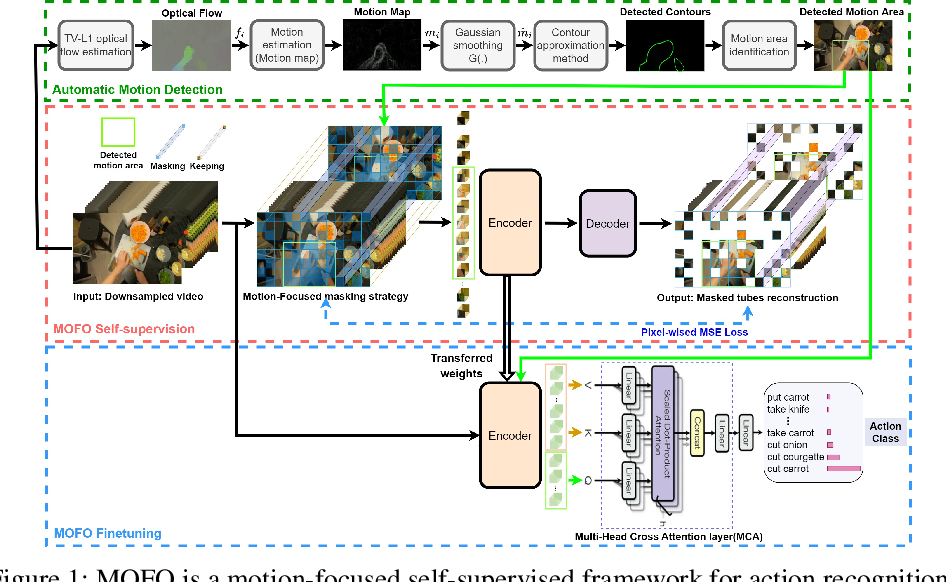
Figure 1 from MOFO: MOtion FOcused Self-Supervision for Video ...

Figure 1 from Masked Motion Encoding for Self-Supervised Video ...
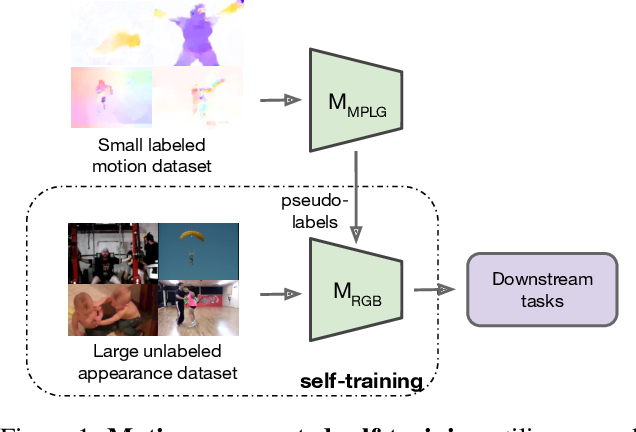
Figure 1 from Motion-Augmented Self-Training for Video Recognition at ...

Figure 1 from Motion Aware Self-Supervision for Generic Event Boundary ...

Figure 1 from Data-Efficient Masked Video Modeling for Self-supervised ...
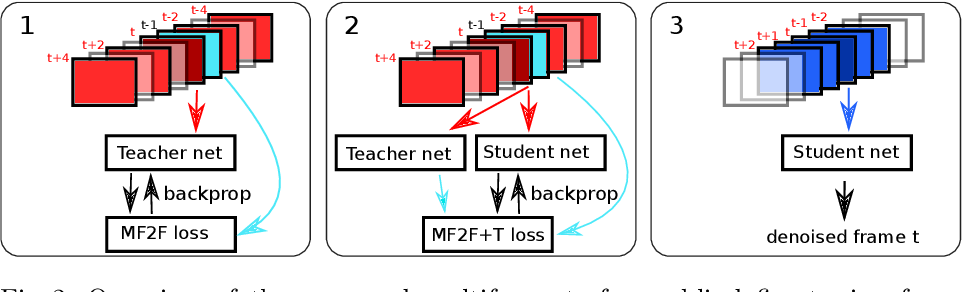
Figure 1 from Self-supervised training for blind multi-frame video ...
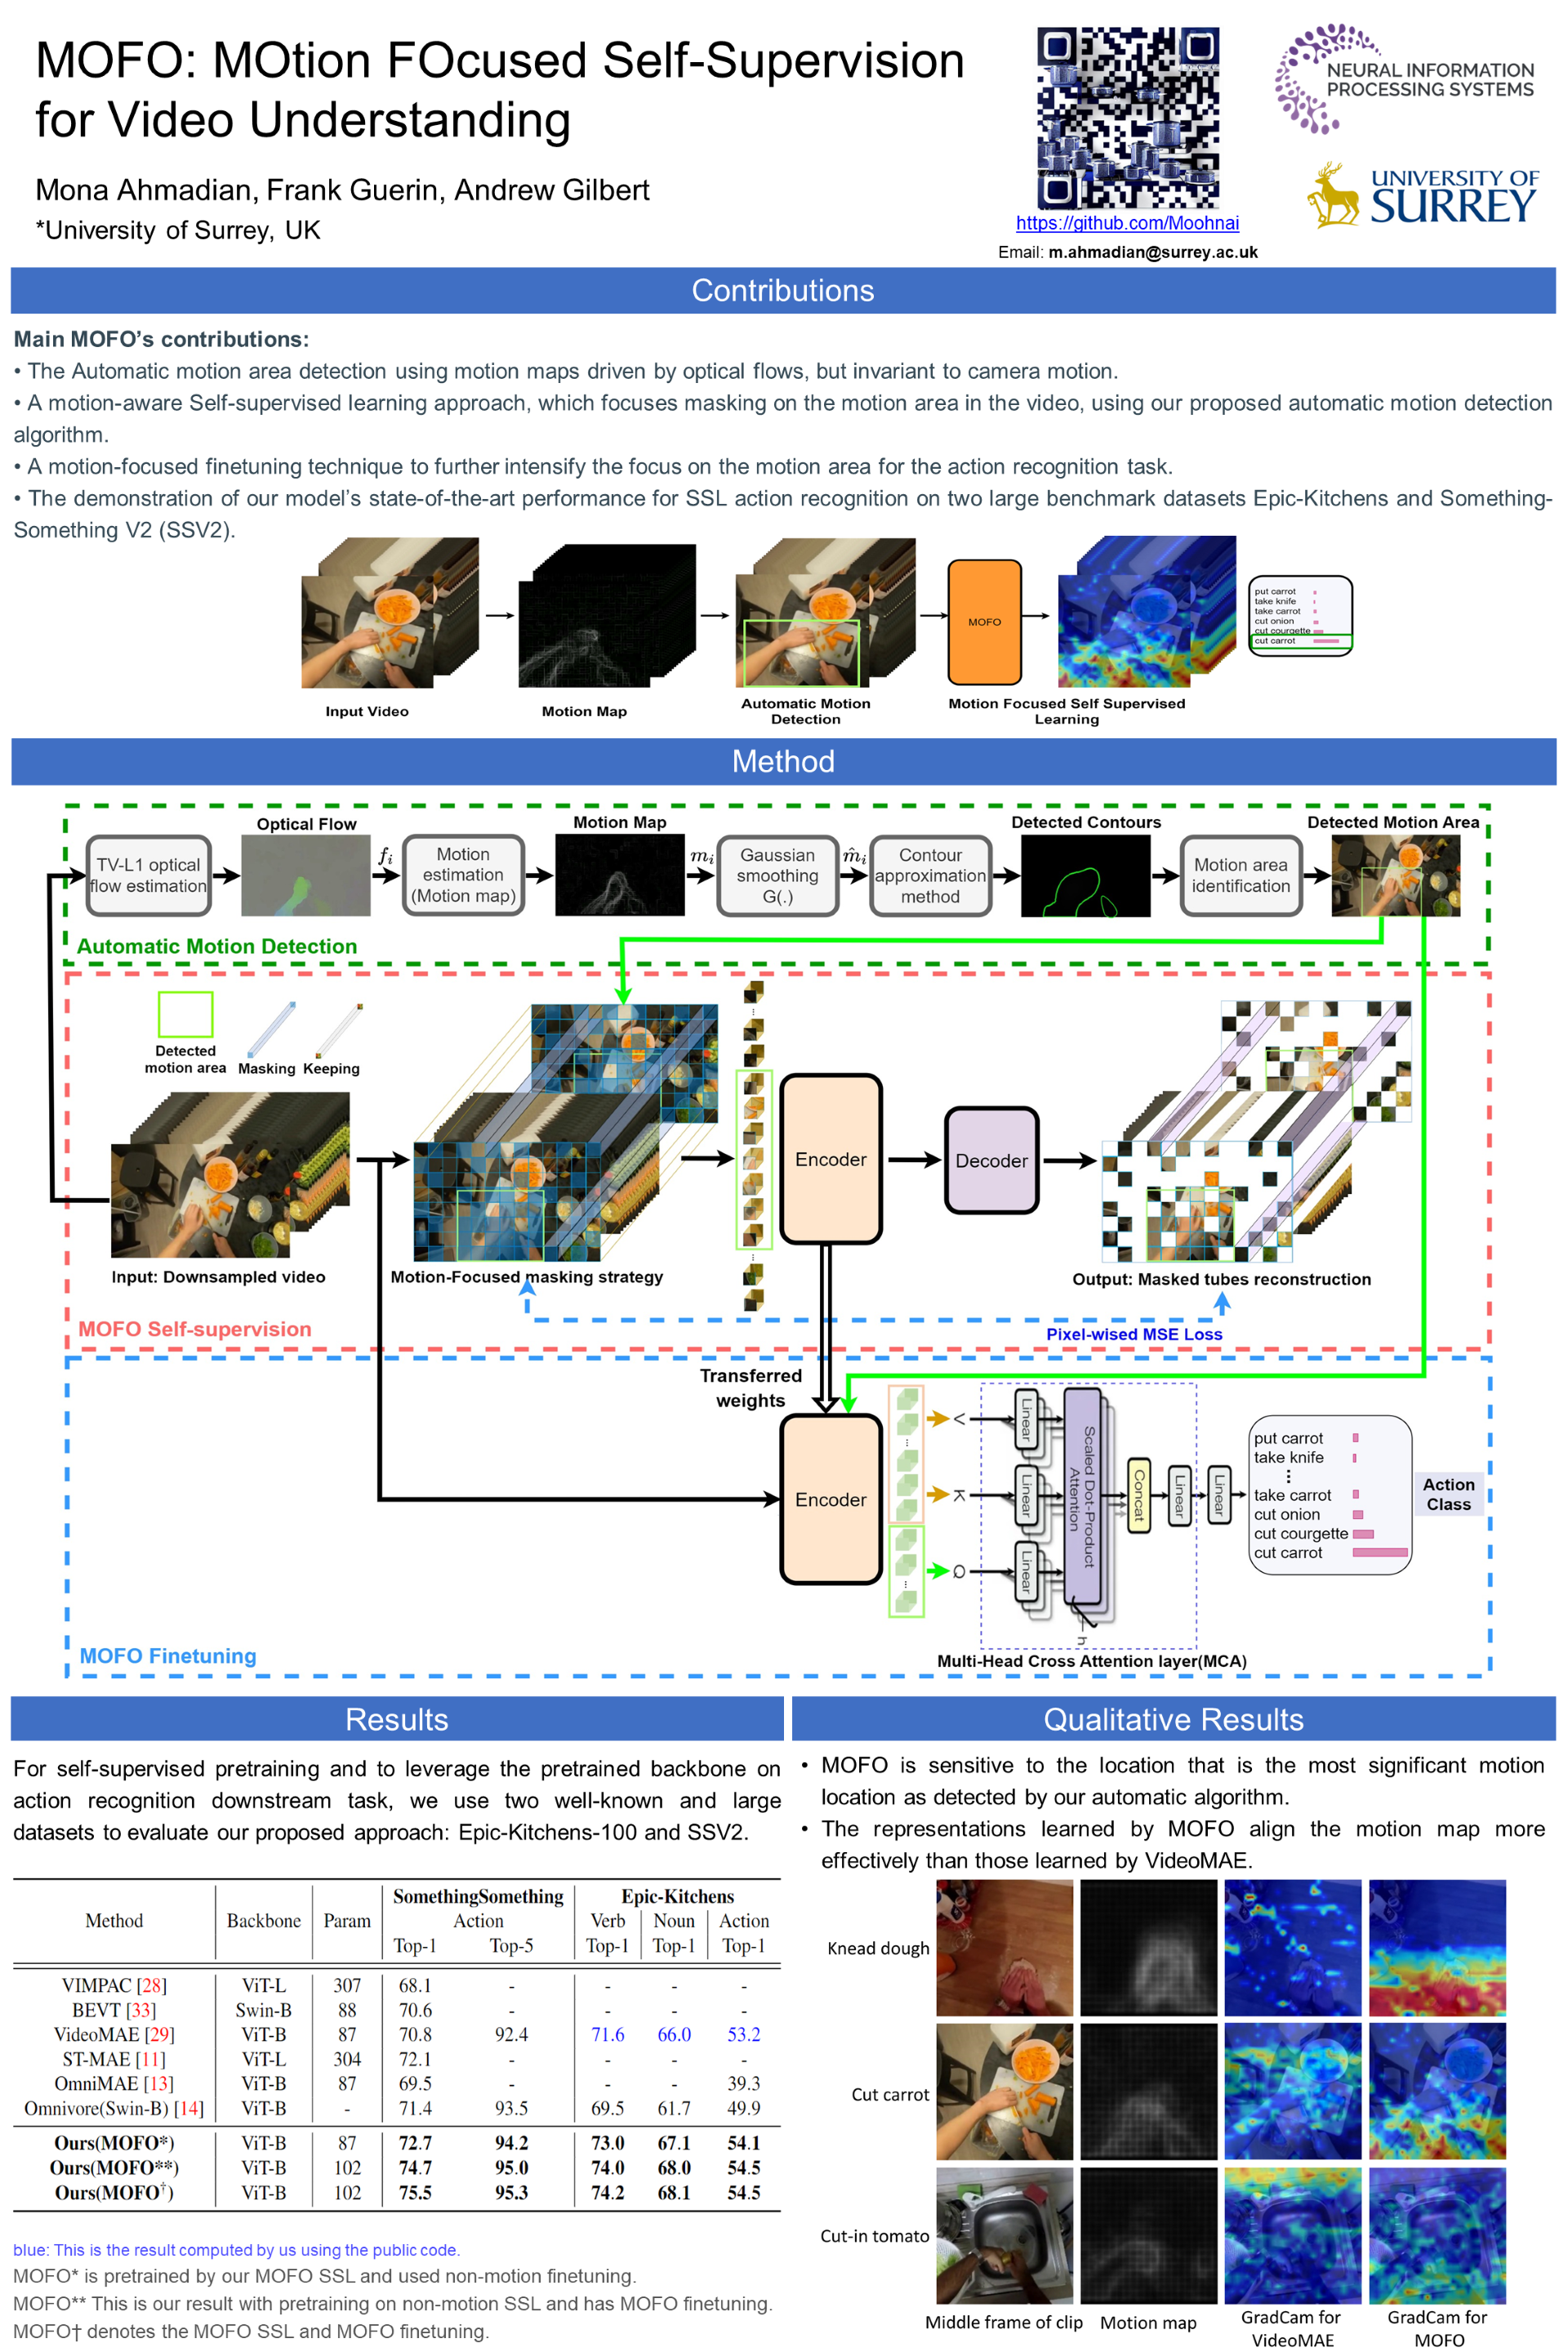
NeurIPS MOFO: MOtion FOcused Self-Supervision for Video Understanding

Figure 1 from Self-Supervised Human Pose based Multi-Camera Video ...

Figure 1 from Self-supervised Video Representation Learning by Context ...

Figure 1 from Self-supervised Learning of Motion Capture | Semantic Scholar
Advertisement Space (300x250)

Figure 1 from Self-Supervised Representation Learning From Videos for ...

Figure 1 from Tubelet-Contrastive Self-Supervision for Video-Efficient ...
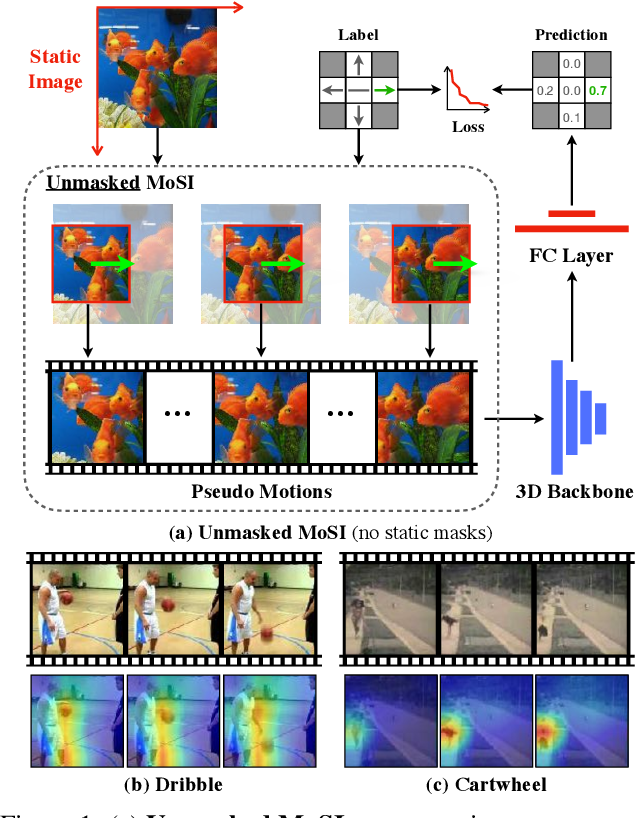
Figure 1 from Self-supervised Motion Learning from Static Images ...
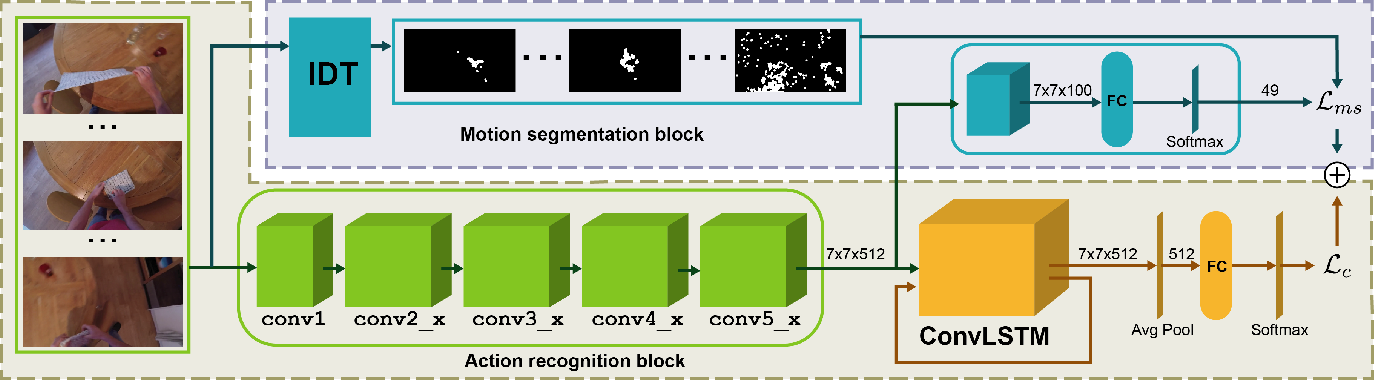
Figure 1 from Joint Encoding of Appearance and Motion Features with ...

Figure 1 from Motion-Focused Contrastive Learning of Video ...

AI Summary: MOFO: MOtion FOcused Self-Supervision for Video Understanding

Figure 1 from Multi-Task Multi-Modal Self-Supervised Learning for ...

Figure 1 from Framework for visual-feedback training based on a ...

Figure 1 from Using Motion Cues to Supervise Single-Frame Body Pose and ...

Figure 1 from Self-Supervised Video Object Segmentation by Motion-Aware ...
Advertisement Space (336x280)

Figure 1 from Viewpoint motion control by body position in immersive ...

Figure 2 from Self-supervised Video Representation Learning with Motion ...
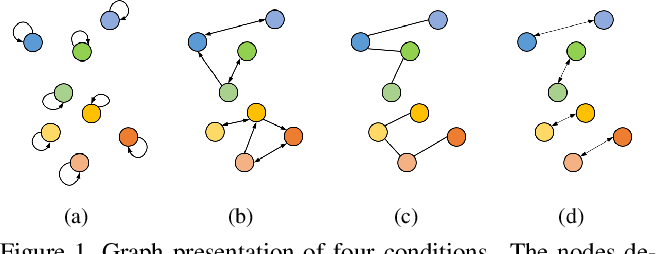
Figure 1 from Enhancing Self-supervised Video Representation Learning ...
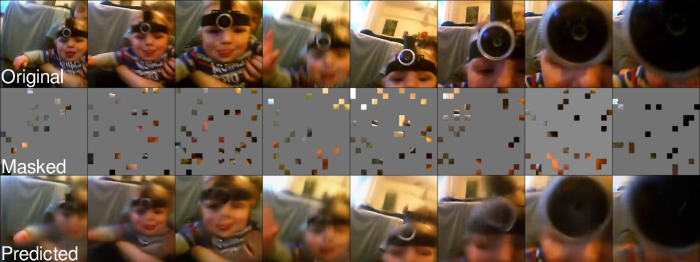
Figure 1 from Self-supervised learning of video representations from a ...
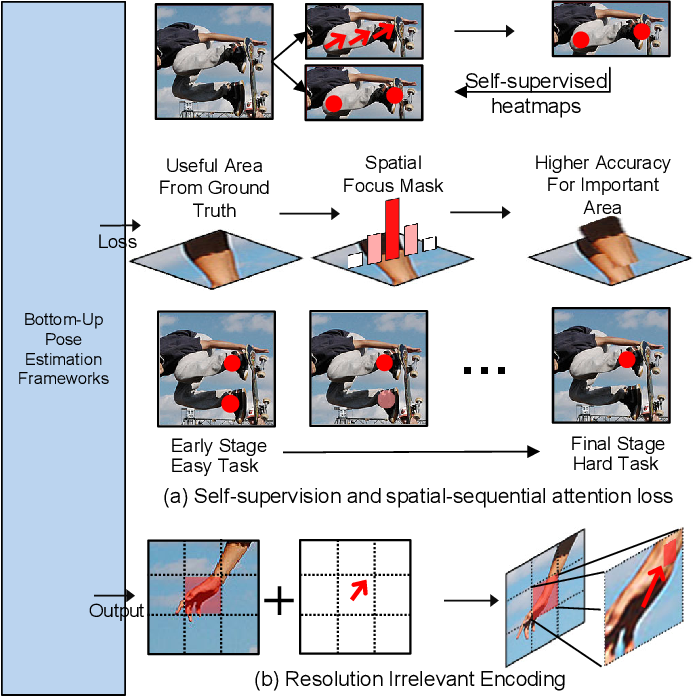
Figure 1 from Self-Supervision and Spatial-Sequential Attention Based ...

Figure 1 from Self-Supervised Video-Based Action Recognition With ...

Figure 1 from Self-Supervised Learning of Perceptually Optimized Block ...

Figure 1 from Forecasting of depth and ego-motion with transformers and ...

Figure 2 from Self-Supervised Video Object Segmentation by Motion-Aware ...

Figure 1 from EMR-MSF: Self-Supervised Recurrent Monocular Scene Flow ...
Advertisement Space (336x280)
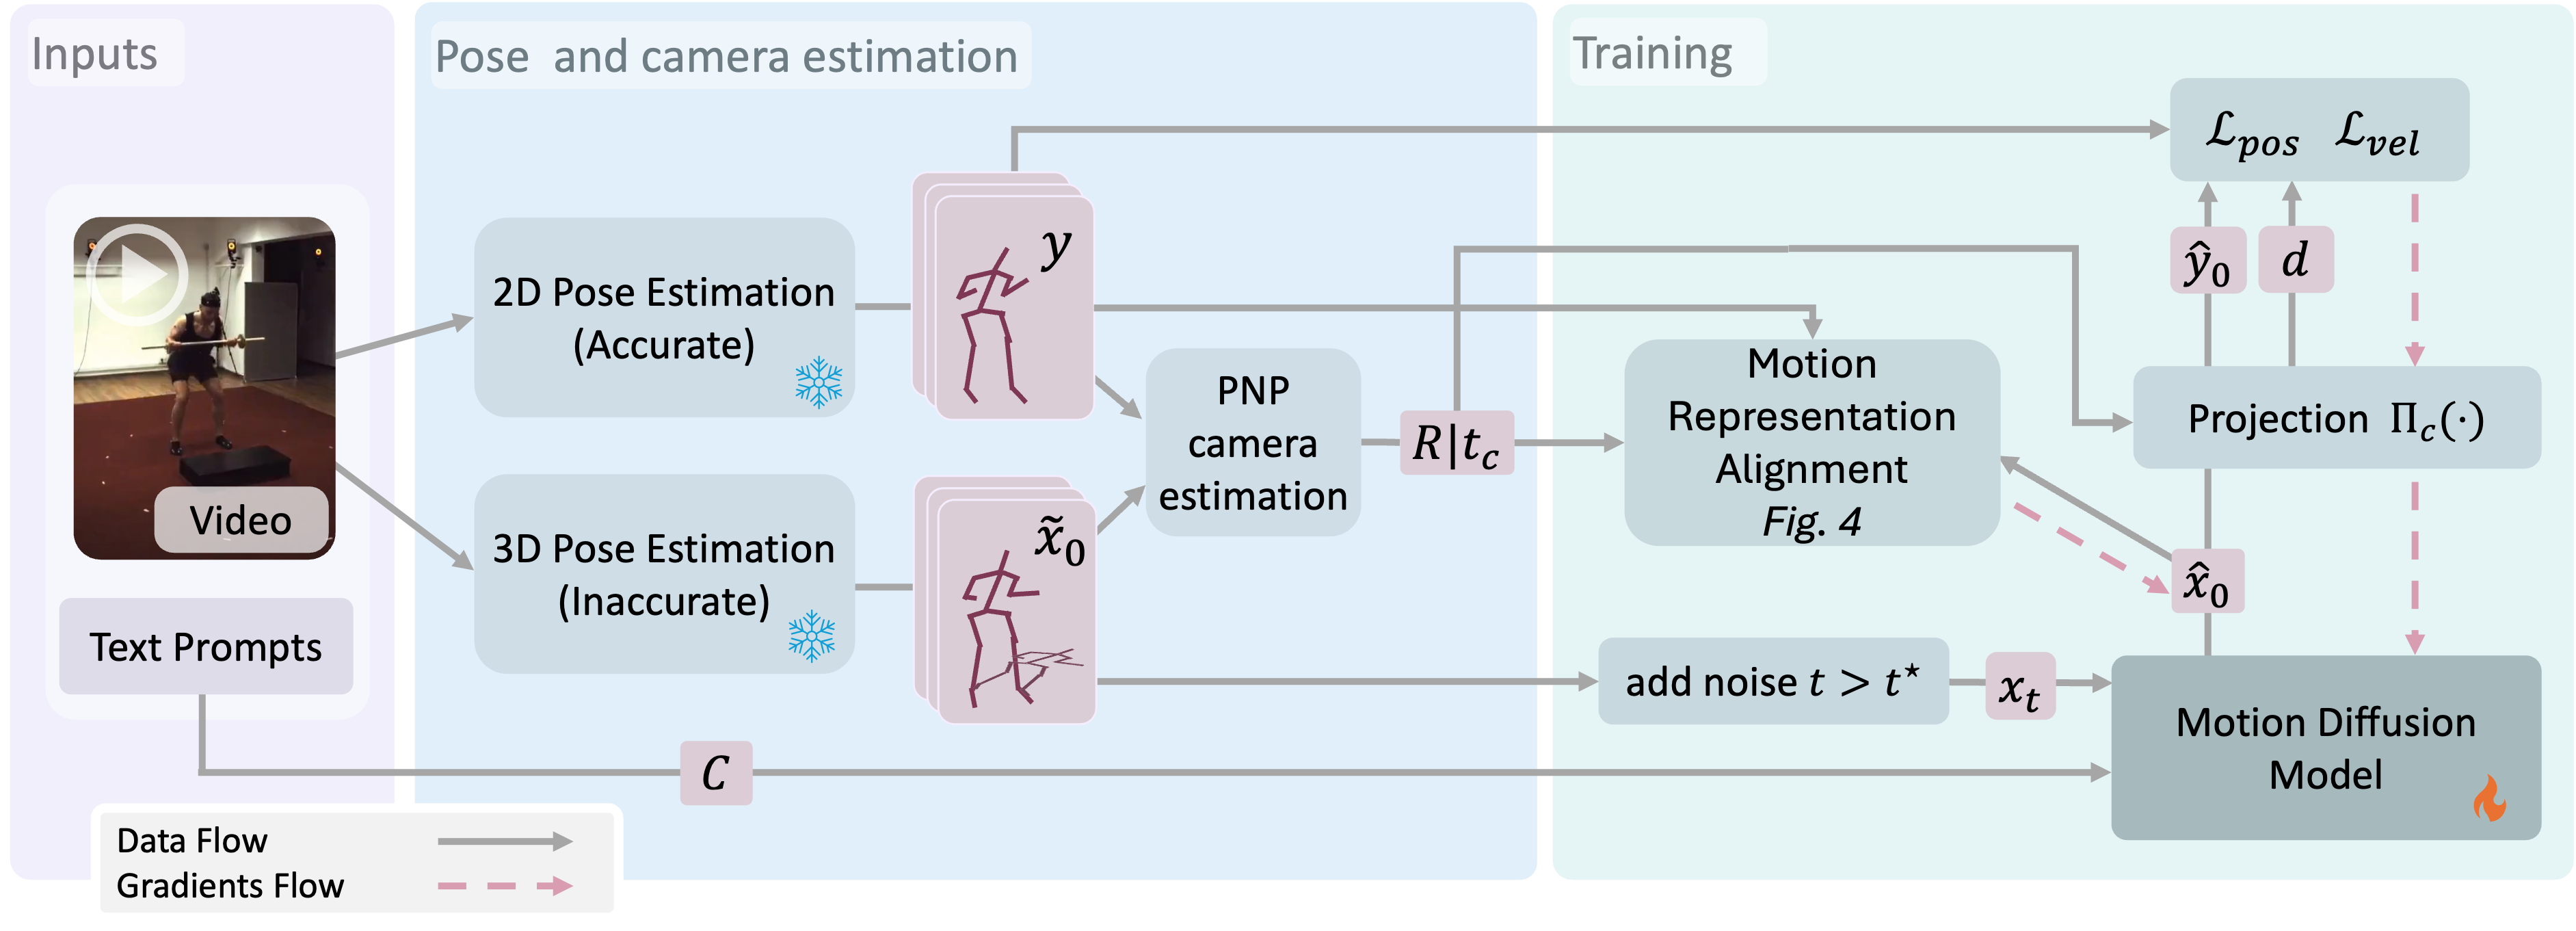
VideoMDM — 3D Human Motion Generation from 2D Supervision

Figure 1 from Self-Supervised Learning With Geometric Constraints in ...
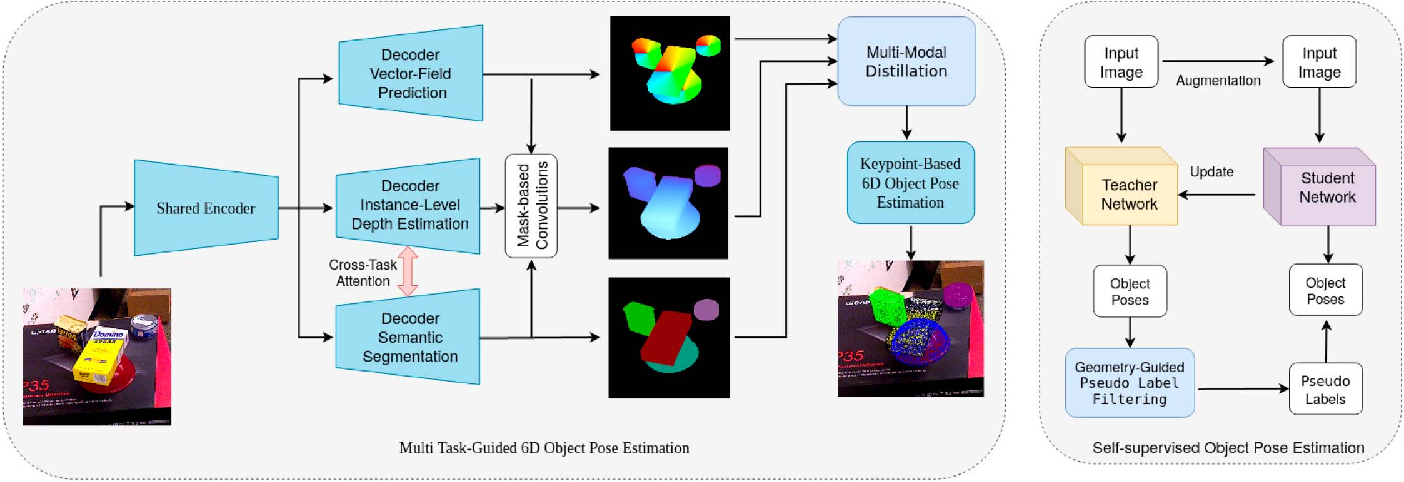
Figure 1 from Self-Supervised Object Pose Estimation With Multitask ...

Recently, I presented my recent work "MOFO: MOtion FOcused Self ...

(PDF) Maximizing Self-supervision from Thermal Image for Effective Self ...

Figure 1 from Forecasting of depth and ego-motion with transformers and ...