
Figure 1 From Multi Target Voice Conversion Without Parallel Data By

Figure 1 from Multi-target Voice Conversion without Parallel Data by ...

Figure 2 from Multi-target Voice Conversion without Parallel Data by ...

Multi-target Voice Conversion without Parallel Data by Adversarially ...
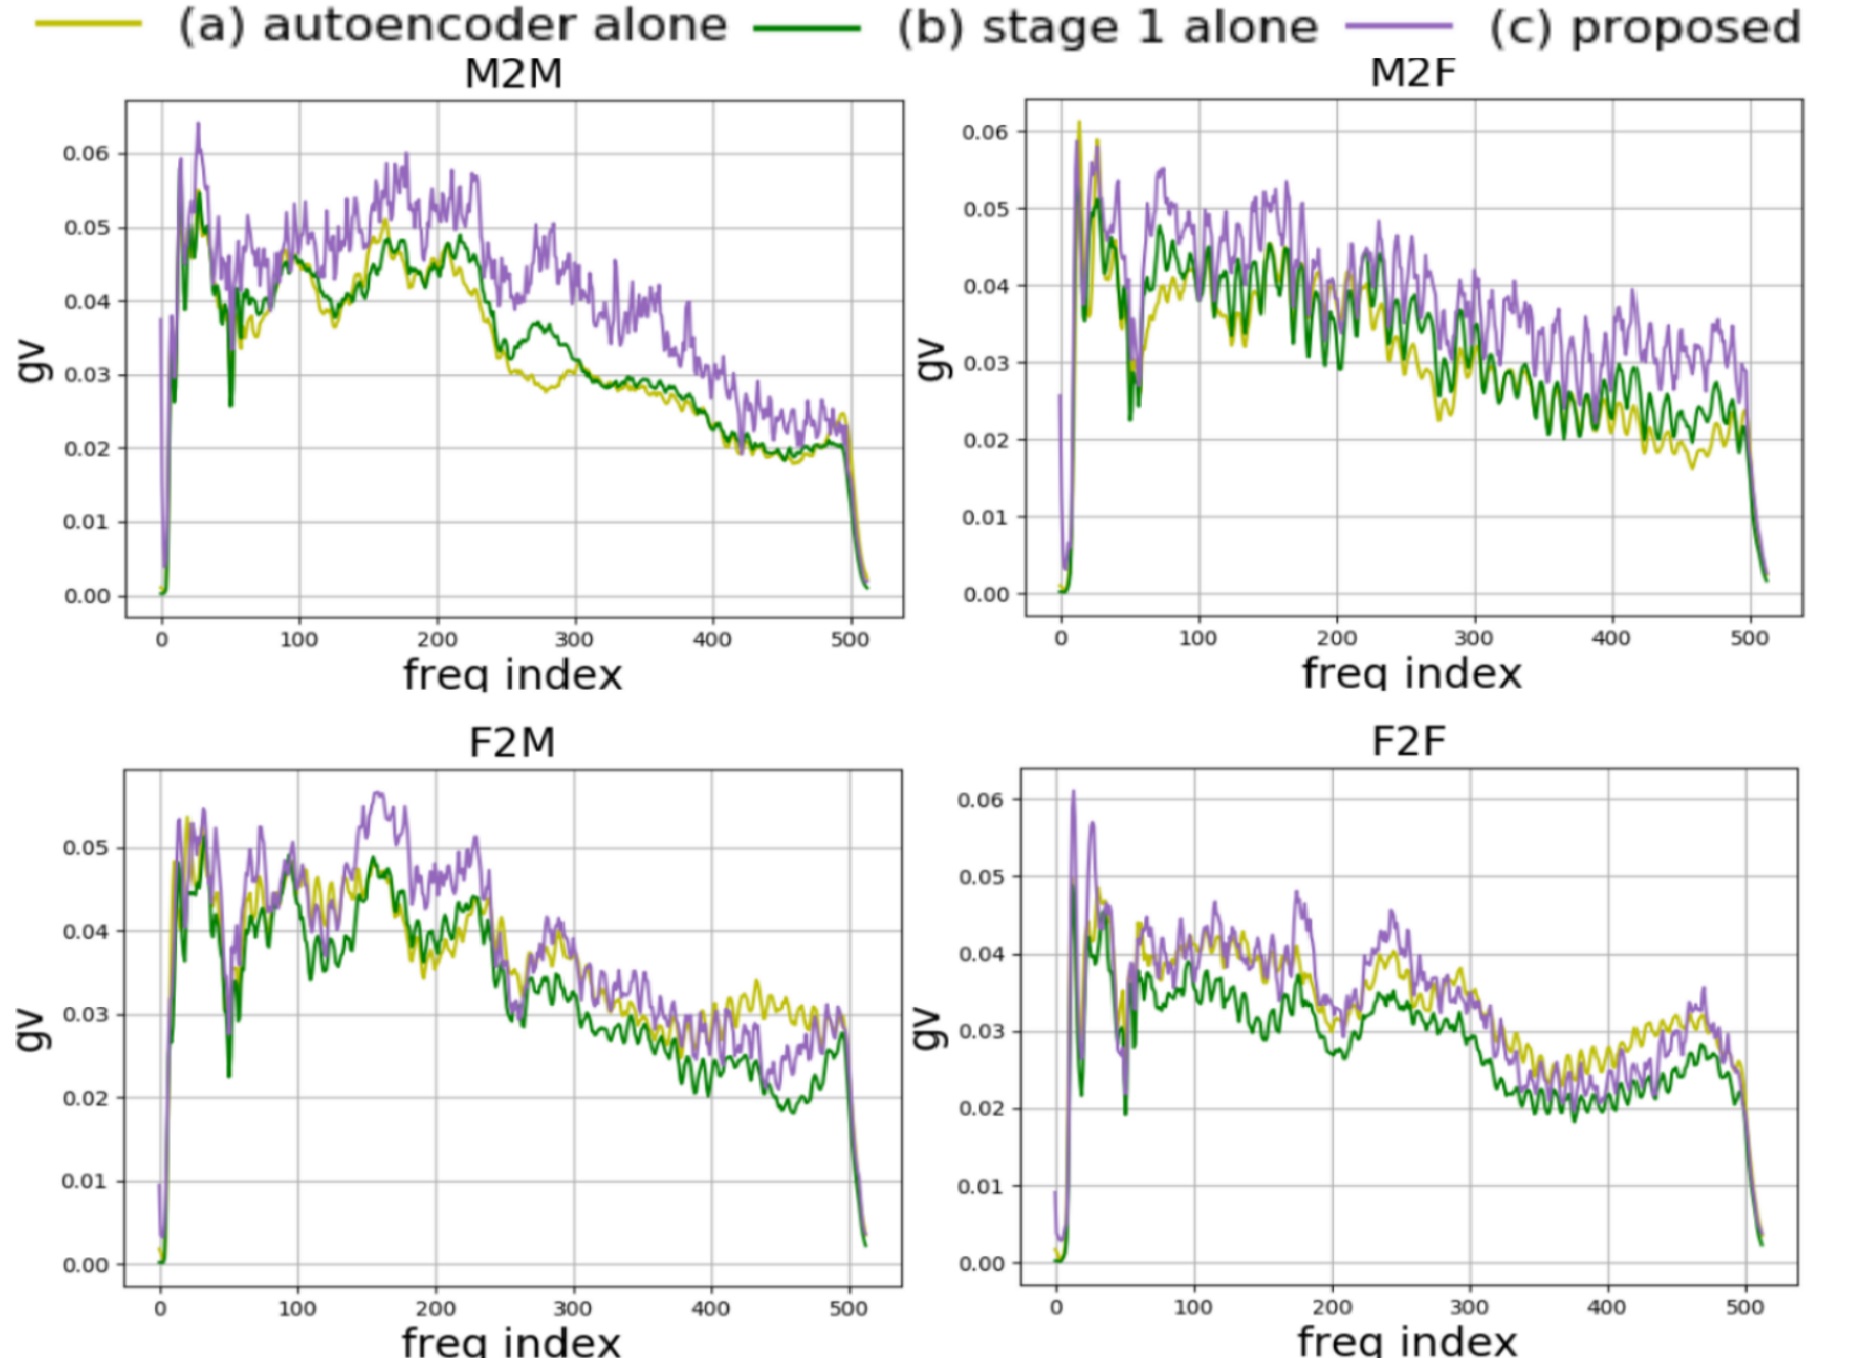
[1804.02812] Multi-target Voice Conversion without Parallel Data by ...
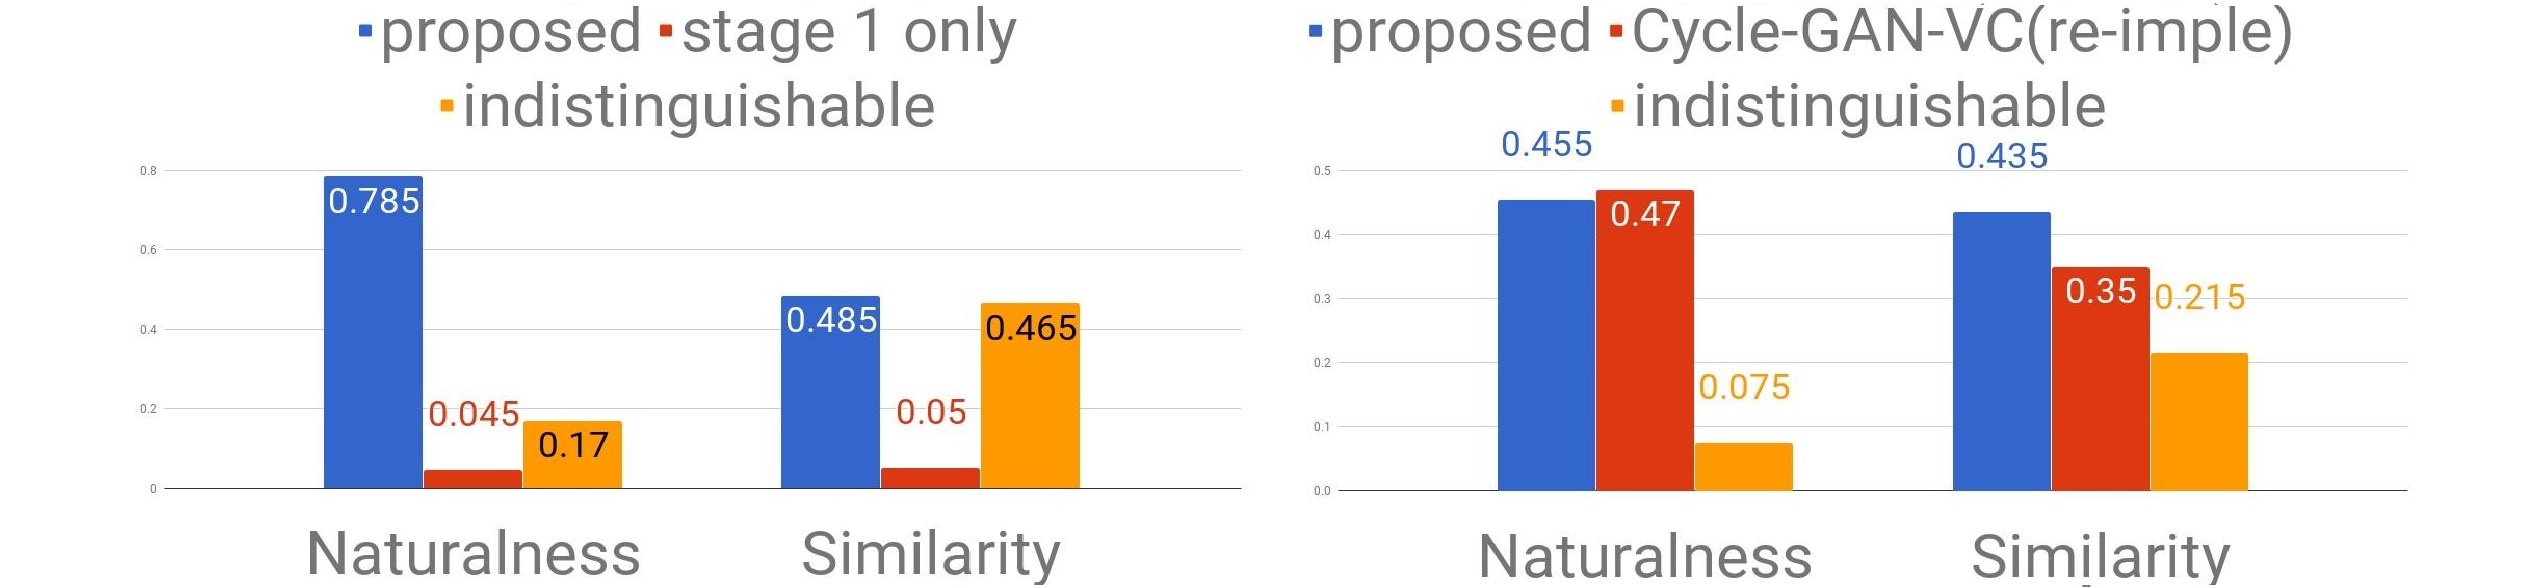
[1804.02812] Multi-target Voice Conversion without Parallel Data by ...
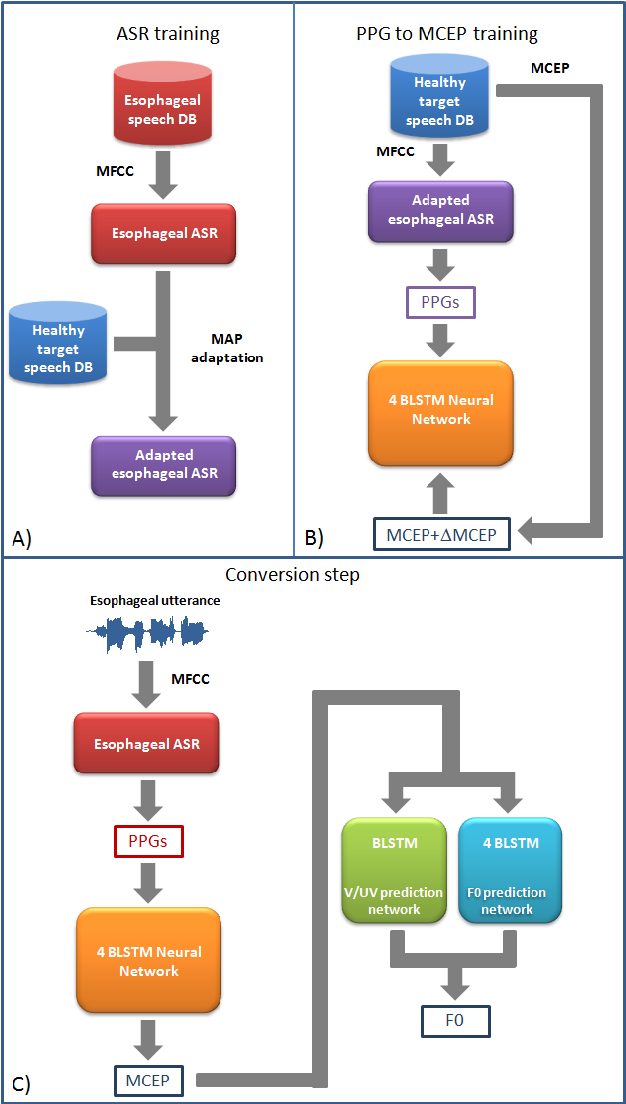
Figure 1 from Parallel vs. Non-Parallel Voice Conversion for Esophageal ...

Figure 1 from An Improved Frame-Unit-Selection Based Voice Conversion ...

Figure 1 from Non-Parallel Sequence-to-Sequence Voice Conversion With ...

Figure 1 from Average Modeling Approach to Voice Conversion with Non ...
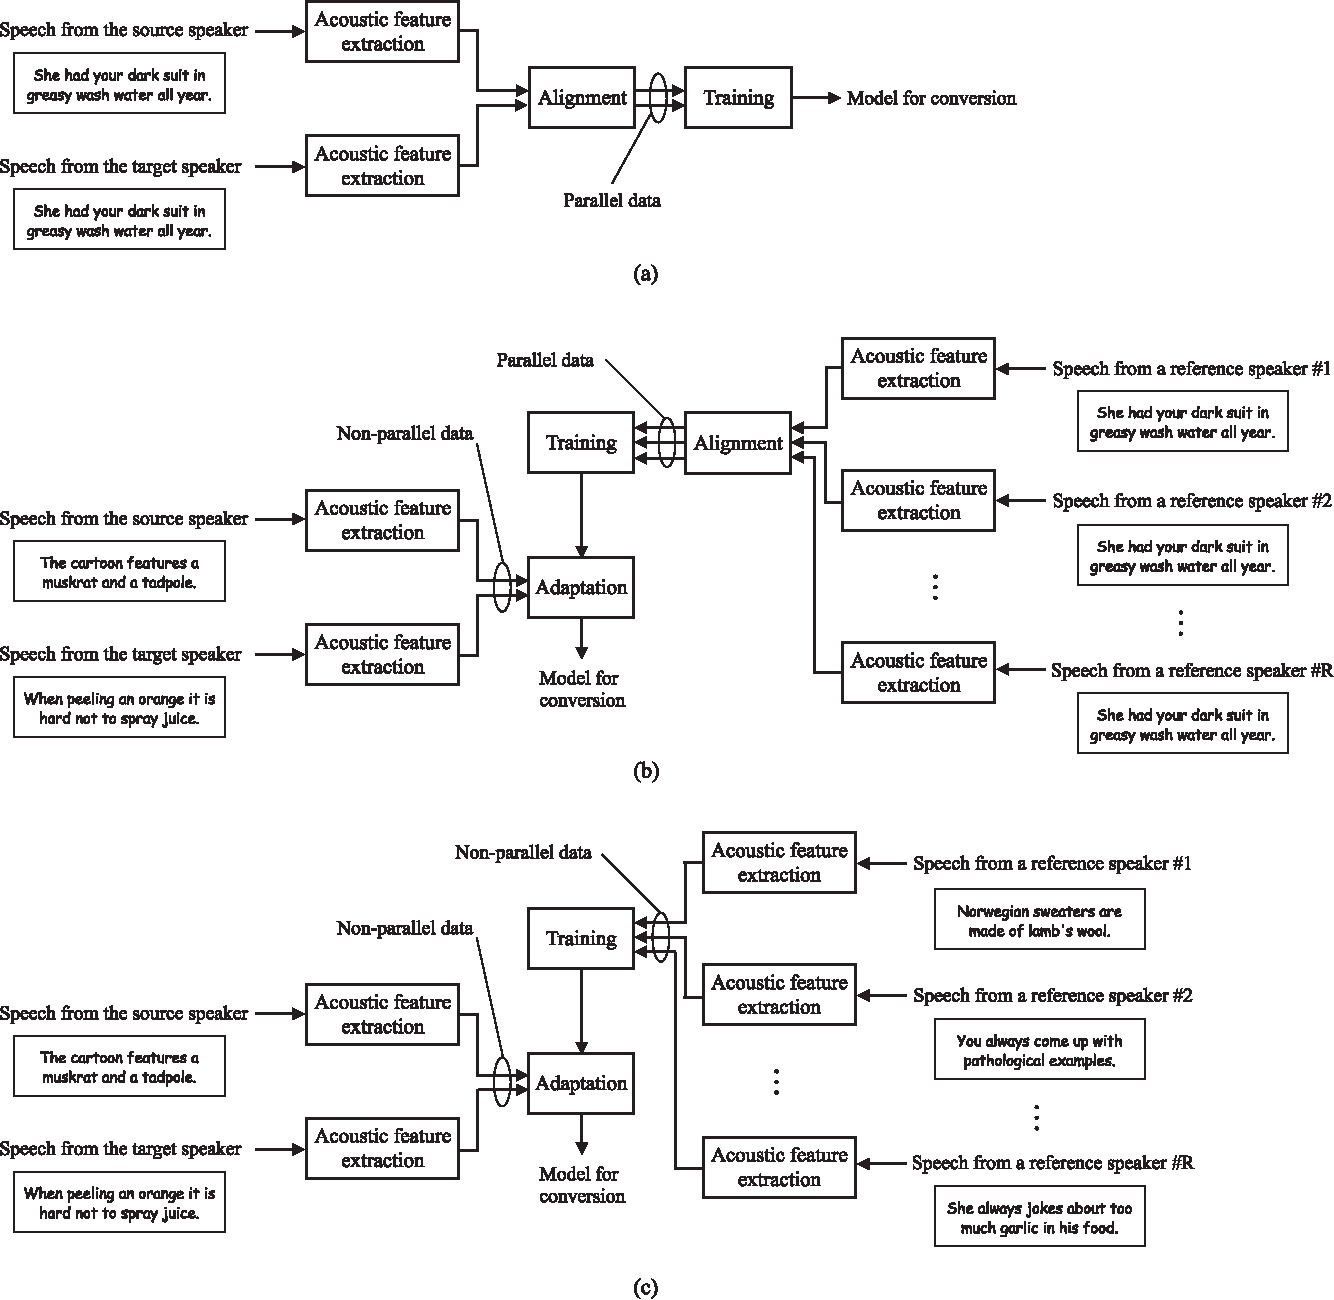
Figure 1 from Non-Parallel Training in Voice Conversion Using an ...
Advertisement Space (300x250)

Figure 1 from Non-Parallel Voice Conversion System Using An Auto ...

Figure 1 from The NU Non-Parallel Voice Conversion System for the Voice ...

Figure 1 from Non-parallel and Many-to-Many Voice Conversion Using ...

Figure 1 from A Voice Conversion Framework with Tandem Feature Sparse ...
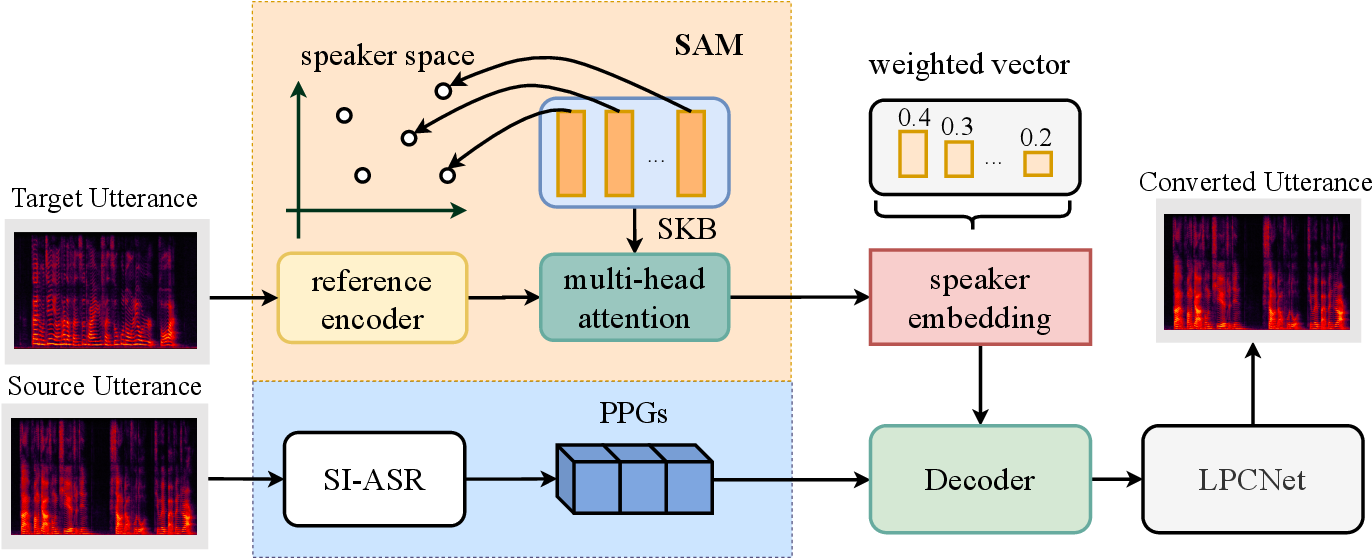
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from Many-to-many voice conversion based on multiple non ...

Figure 1 from Any-to-One Sequence-to-Sequence Voice Conversion Using ...

Figure 1 from CASIA Voice Conversion System for the Voice Conversion ...
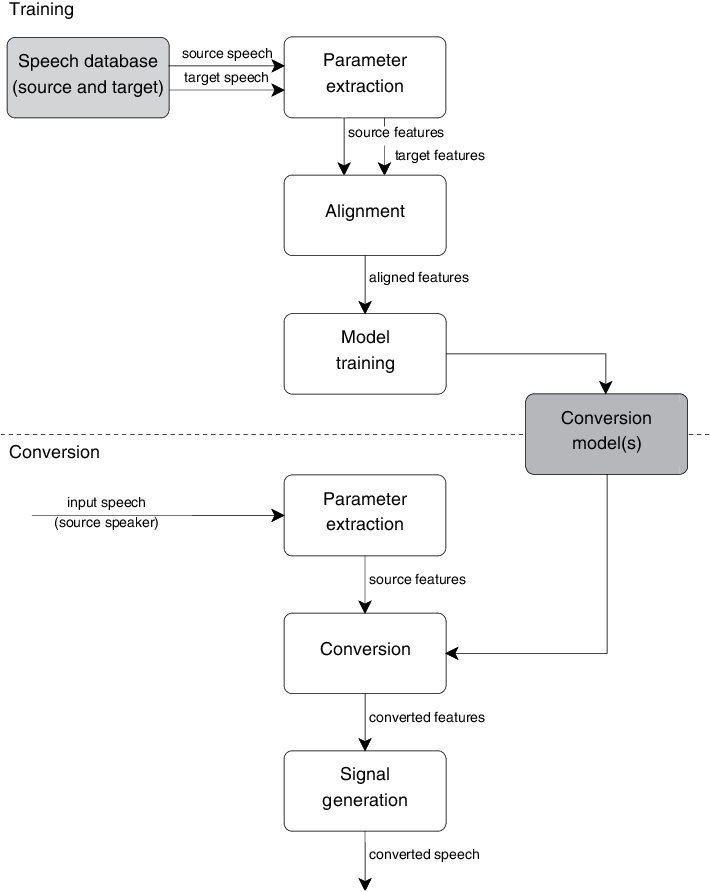
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from F0-Consistent Many-To-Many Non-Parallel Voice Conversion ...
Advertisement Space (336x280)

Figure 1 from Voice Conversion Using Input-to-Output Highway Networks ...

Figure 1 from An overview of voice conversion systems | Semantic Scholar

Figure 1 from Parallel-Data-Free Voice Conversion Using Cycle ...

Figure 1 from Voice conversion for non-parallel datasets using dynamic ...
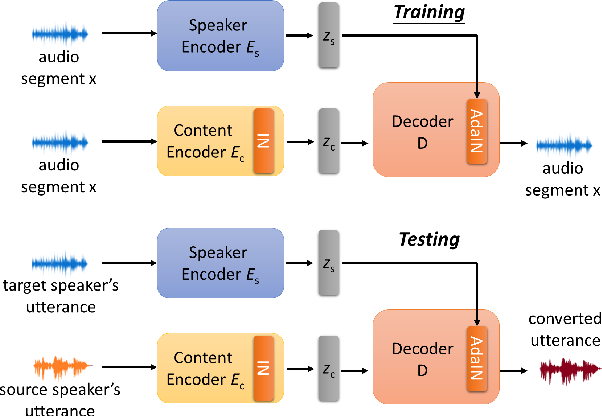
Table 1 from One-shot Voice Conversion by Separating Speaker and ...
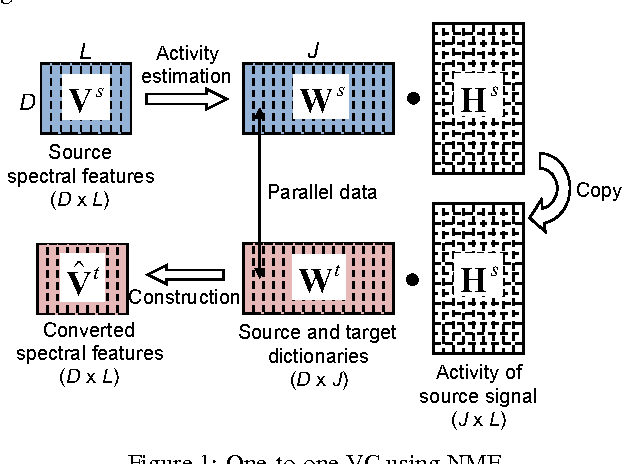
Figure 1 from Many-to-one voice conversion using exemplar-based sparse ...

Figure 1 from Rhythm Modeling for Voice Conversion | Semantic Scholar
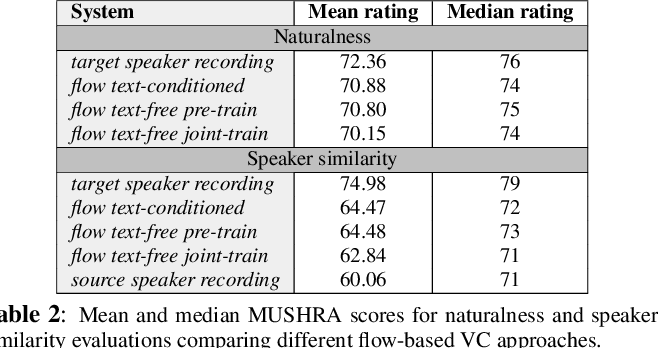
Figure 1 from Text-Free Non-Parallel Many-To-Many Voice Conversion ...

Figure 1 from Text-Free Non-Parallel Many-To-Many Voice Conversion ...
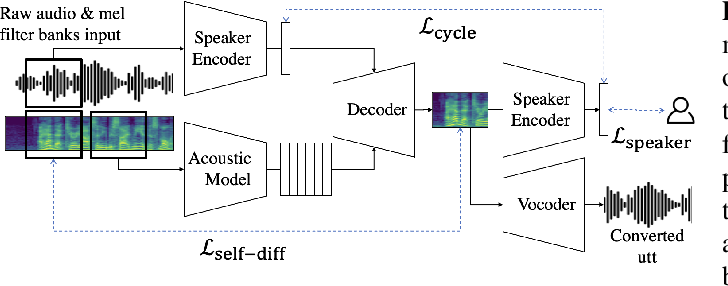
Figure 1 from Training Robust Zero-Shot Voice Conversion Models with ...
Advertisement Space (336x280)
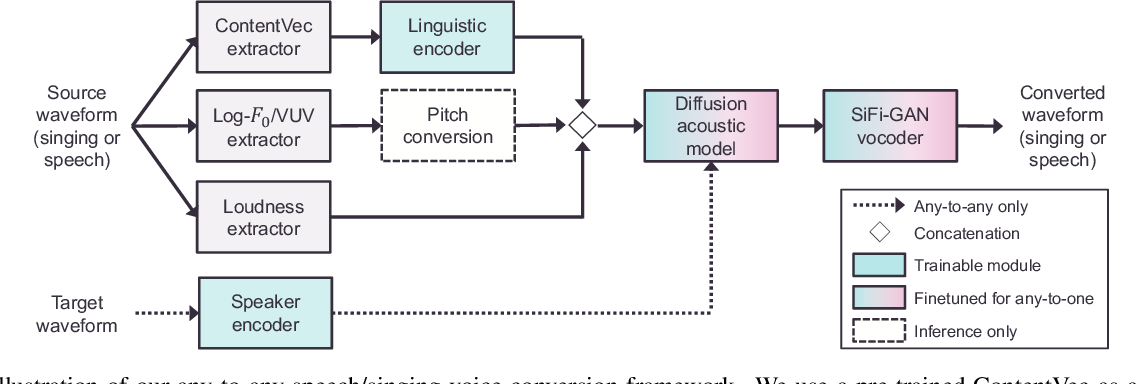
Figure 1 from A Comparative Study of Voice Conversion Models with Large ...
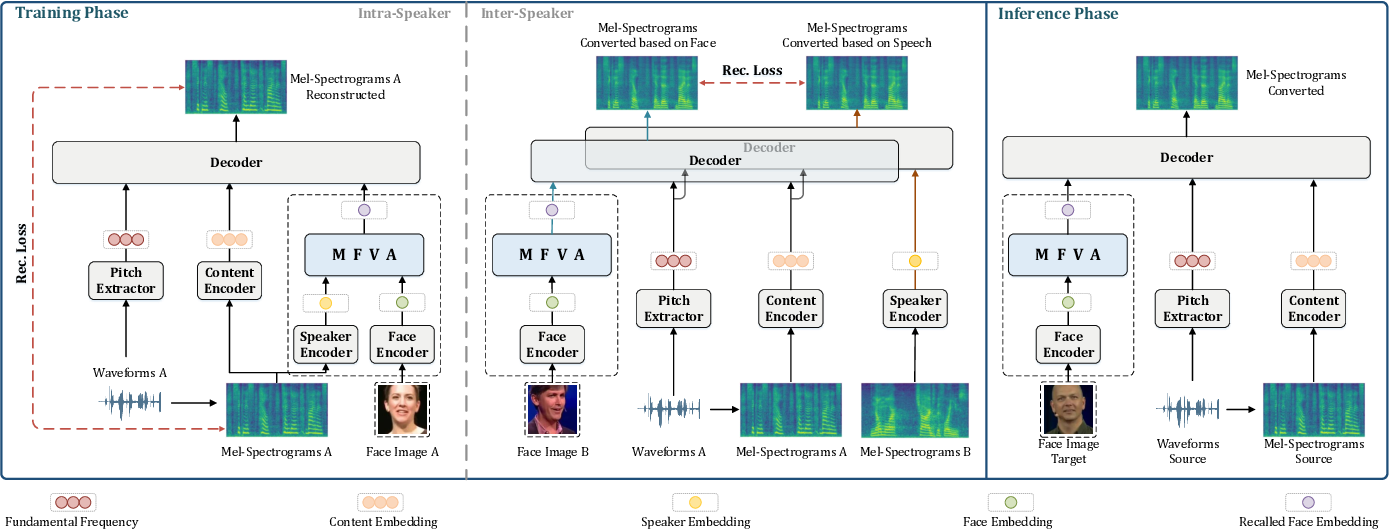
Figure 1 from Face-Driven Zero-Shot Voice Conversion with Memory-based ...

Figure 1 from Jointly Trained Conversion Model and WaveNet Vocoder for ...

Figure 1 from On the use of I-vectors and average voice model for voice ...
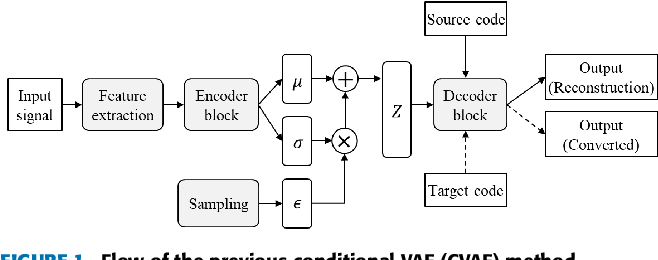
Figure 1 from Many-to-Many Unsupervised Speech Conversion From ...

Figure 1 from Generative Adversarial Networks for Singing Voice ...