
Figure 1 From Multimodal Speaker Adaptation Of Acoustic Model And

Figure 1 from Multimodal Speaker Adaptation of Acoustic Model and ...
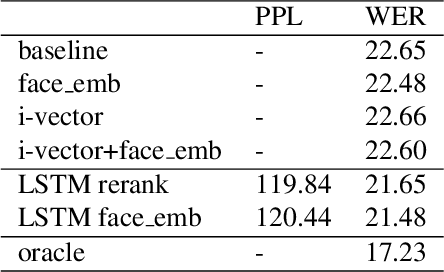
Table 1 from Multimodal Speaker Adaptation of Acoustic Model and ...
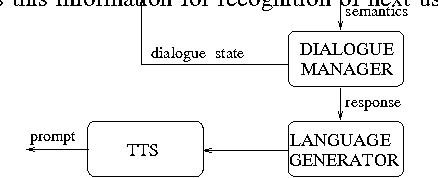
Figure 1 from Task adaptation of acoustic and language models based on ...
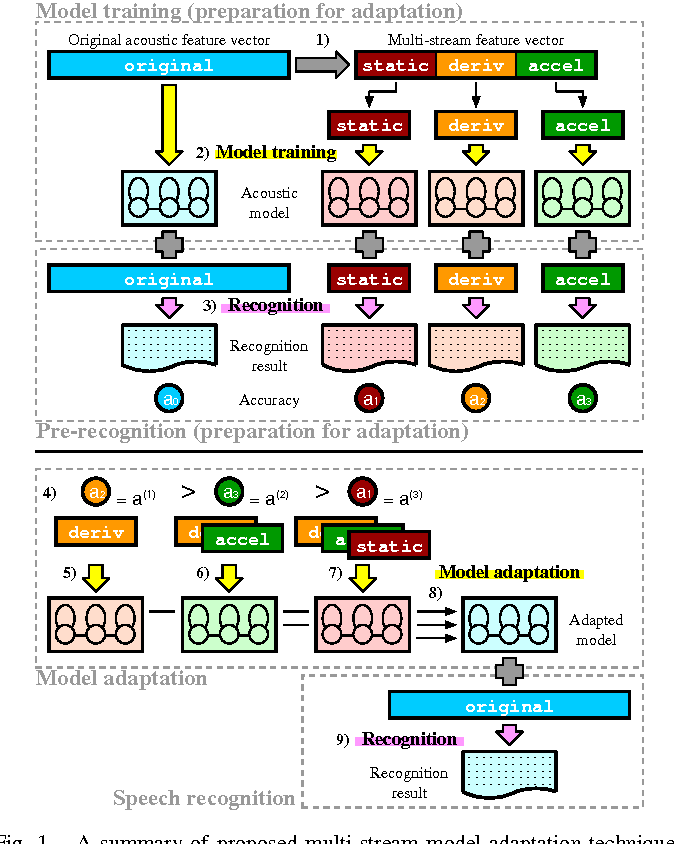
Figure 1 from Multi-stream acoustic model adaptation for noisy speech ...

Figure 1 from Speaker adaptation of an acoustic-articulatory inversion ...

Figure 1 from Empirical Evaluation of Speaker Adaptation on DNN based ...
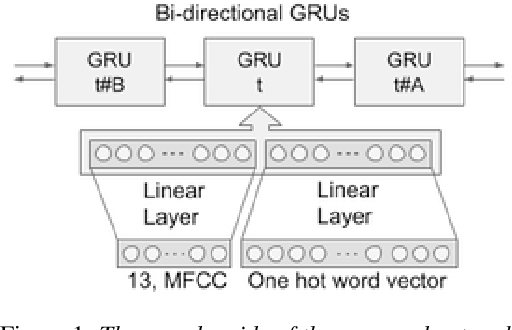
Figure 1 from Multimodal Speaker Segmentation and Diarization using ...

Figure 1 from 4D Multimodal Speaker Model for Remote Speech Diagnosis ...

Figure 1 from Effects of speaker's and listener's acoustic environments ...
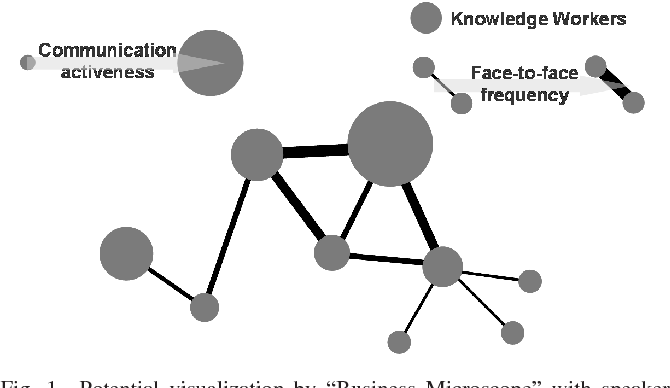
Figure 1 from Hybrid Speaker Recognition Using Universal Acoustic Model ...
Advertisement Space (300x250)

Figure 1 from Acoustic Model Adaptation Using First-Order Linear ...
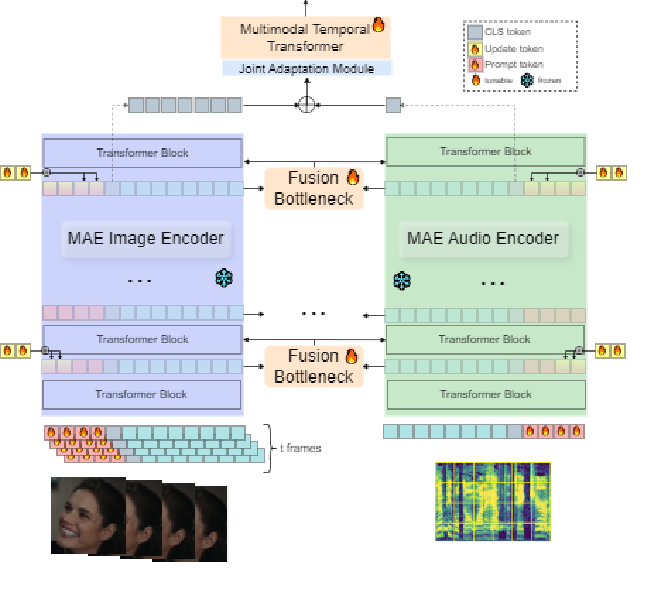
Figure 1 from MMA-DFER: MultiModal Adaptation of unimodal models for ...

Figure 7 from A Hybrid Acoustic and Pronunciation Model Adaptation ...
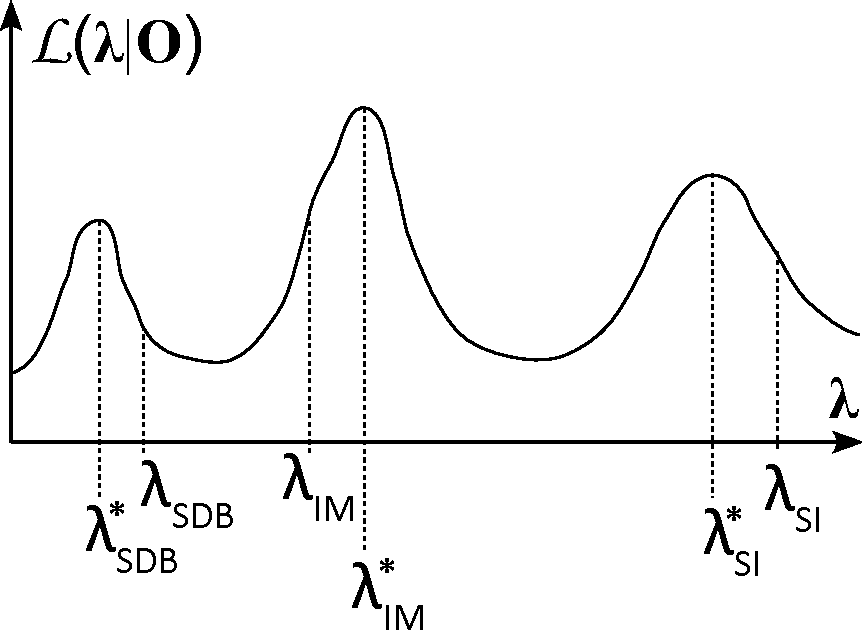
Figure 1 from Acoustic model adaptation using in-domain background ...
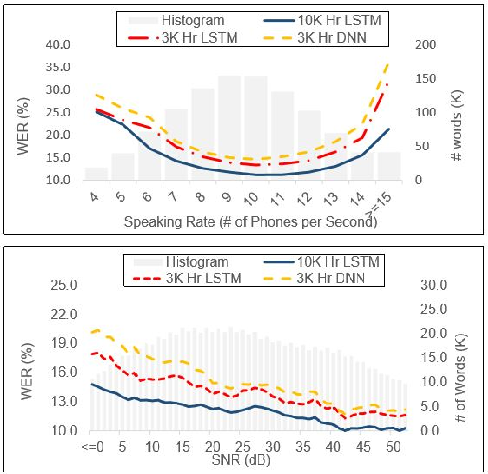
Figure 1 from Acoustic Model Adaptation for Presentation Transcription ...

Acoustic model training of the offline to online speaker adaptation ...
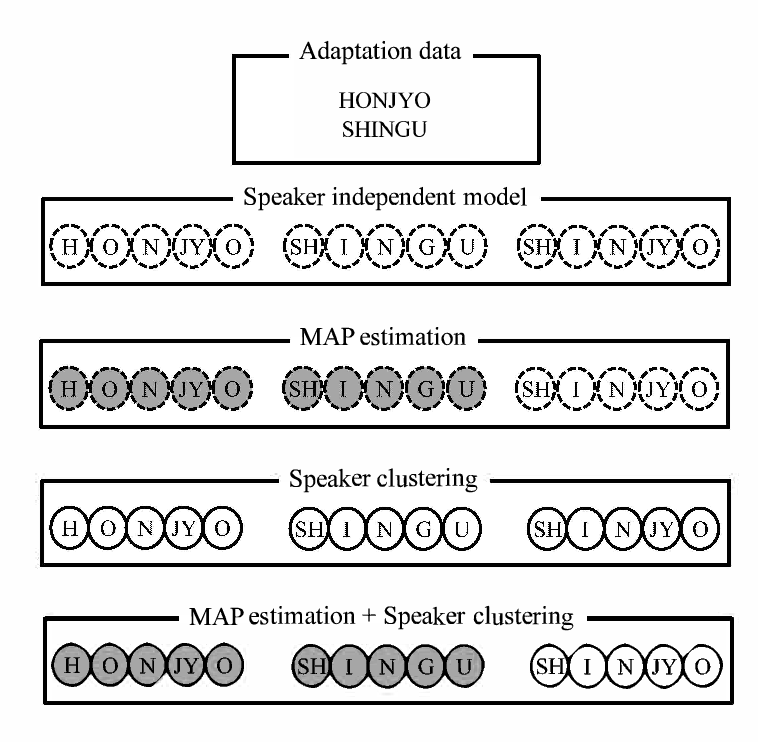
Figure 1 from Speaker adaptation using improved MAP estimation with ...
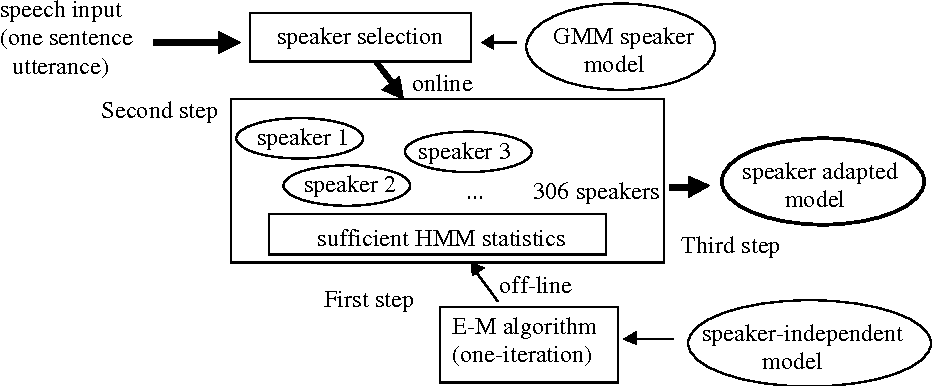
Figure 1 from Evaluation on unsupervised speaker adaptation based on ...

Acoustic model training of the offline to online speaker adaptation ...

Figure 1 from Hybrid acoustic models for distant and multichannel large ...
Advertisement Space (336x280)
(PDF) Online Speaker Adaptation of an Acoustic Model Using Face Recognition

Figure 1 from Multimodal active speaker detection using cross-attention ...

Figure 1 from CAT: Enhancing Multimodal Large Language Model to Answer ...
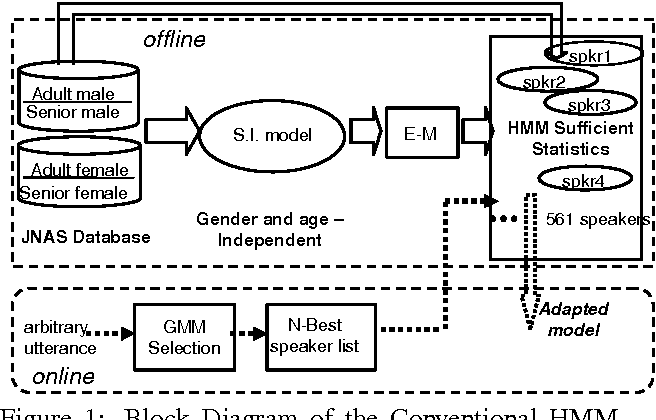
Figure 1 from Rapid unsupervised speaker adaptation based on multi ...

Figure 1 from Multimodal Acoustic Trapping Display | Semantic Scholar
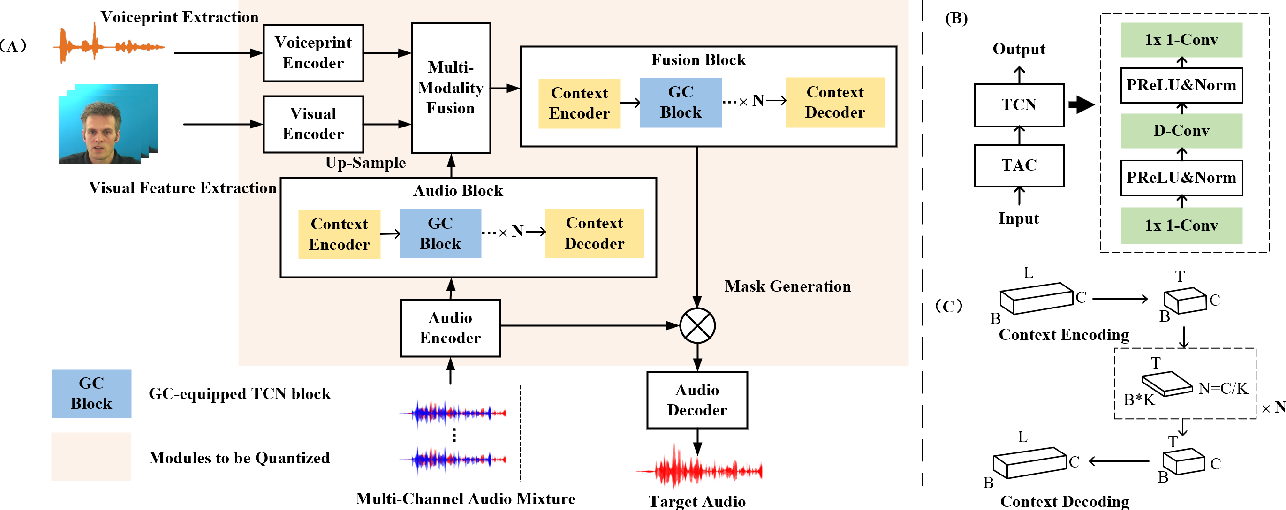
Figure 1 from LiMuSE: Lightweight Multi-Modal Speaker Extraction ...

Figure 1 from Multi-Speaker End-to-End Multi-Modal Speaker Diarization ...
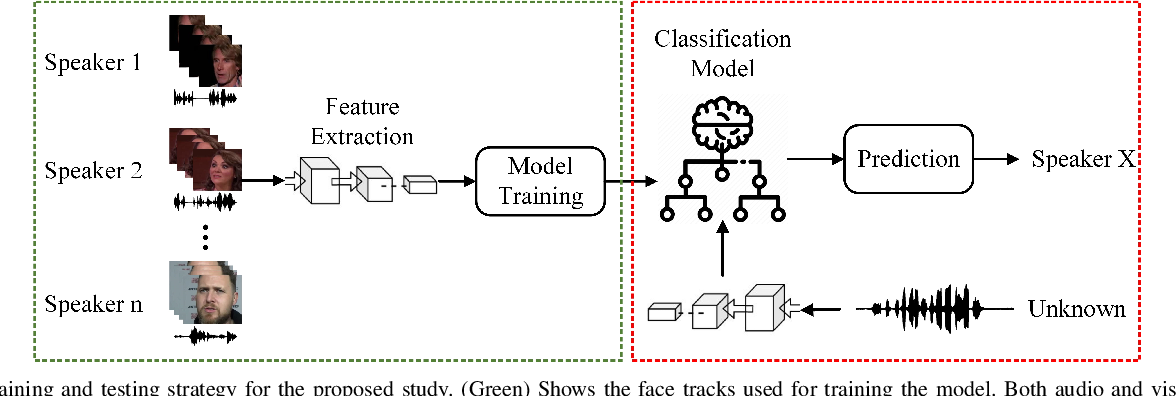
Figure 1 from Speaker Recognition in Realistic Scenario Using ...

Figure 1 from Multimodal speech synthesis architecture for unsupervised ...
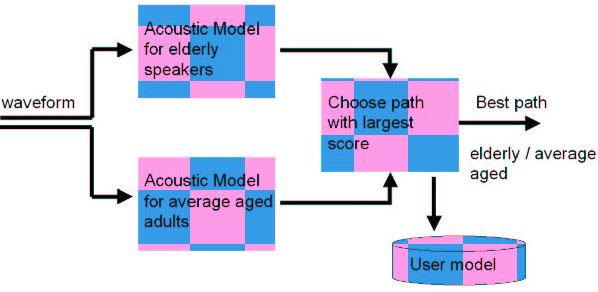
Figure 1 from Adapting multimodal dialog for the elderly | Semantic Scholar
Advertisement Space (336x280)

(PDF) Discriminative MCE-based speaker adaptation of acoustic models ...

Figure 1 from Multimodal speech synthesis architecture for unsupervised ...
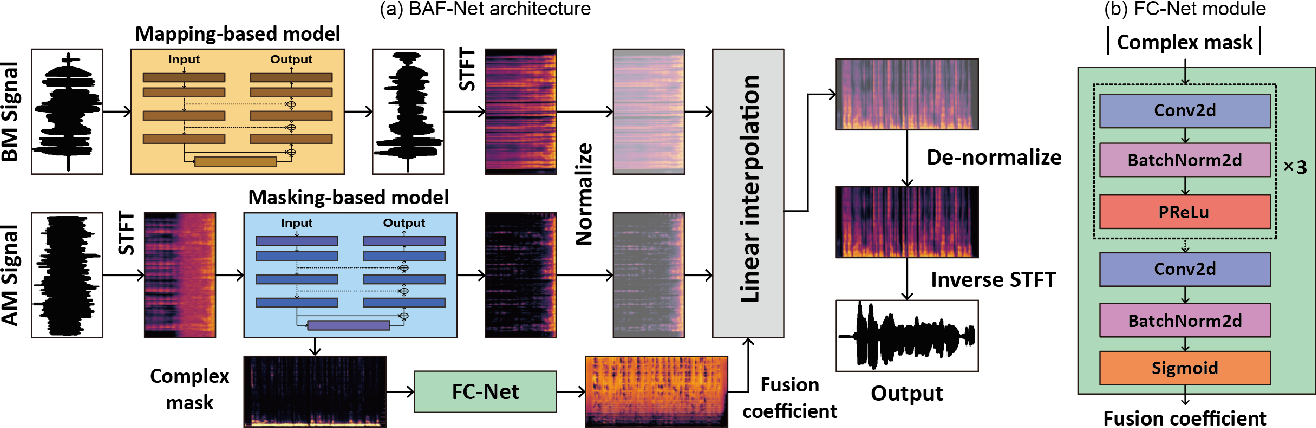
Figure 1 from Modality-Specific Speech Enhancement and Noise-Adaptive ...

Figure 1 from Improving Multimodal Movie Scene Segmentation Using ...

Figure 1 from Multimodal speech synthesis architecture for unsupervised ...
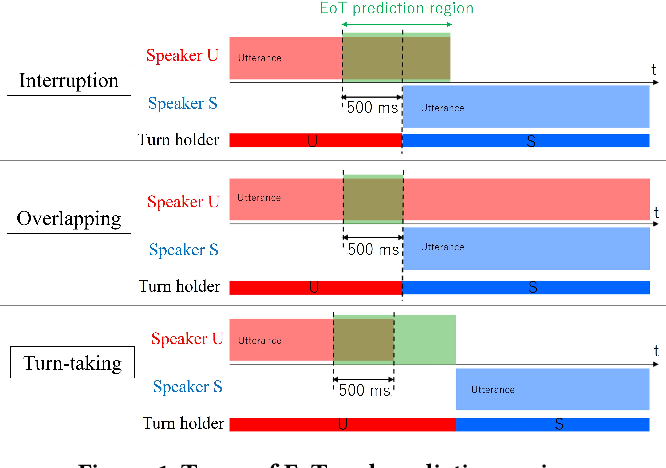
Figure 1 from Predicting End-of-turn and Backchannel Based on ...