
Figure 1 From On The Language Encoder Of Contrastive Cross Modal Models

Figure 1 from On the Language Encoder of Contrastive Cross-modal Models ...

Table 1 from On the Language Encoder of Contrastive Cross-modal Models ...
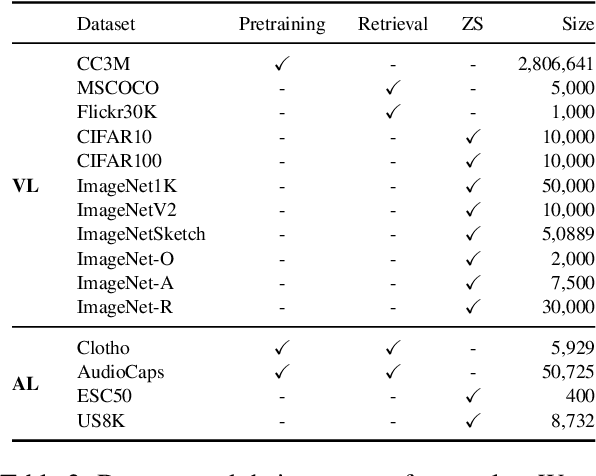
Table 2 from On the Language Encoder of Contrastive Cross-modal Models ...

On the Language Encoder of Contrastive Cross-modal Models - ACL Anthology

Figure 1 from The time course of cross-modal representations of ...

Figure 1 from Cross-modal Retrieval Using Contrastive Learning of ...

Figure 1 from Contrastive Label Correlation Enhanced Unified Hashing ...

Figure 1 from Cross-Modal Contrastive Learning for Robust Reasoning in ...

Figure 1 from Contrastive Transformer Cross-Modal Hashing for Video ...

Figure 1 from Cross-Modal Contrastive Learning for Remote Sensing Image ...
Advertisement Space (300x250)

Figure 1 from Multimodal Contrastive Learning via Uni-Modal Coding and ...

Figure 1 from Cross-Modal Label Contrastive Learning for Unsupervised ...

Figure 1 from Self-Supervised Multi-Modal Knowledge Graph Contrastive ...

Figure 1 from Cross-Modal Alignment Learning of Vision-Language ...
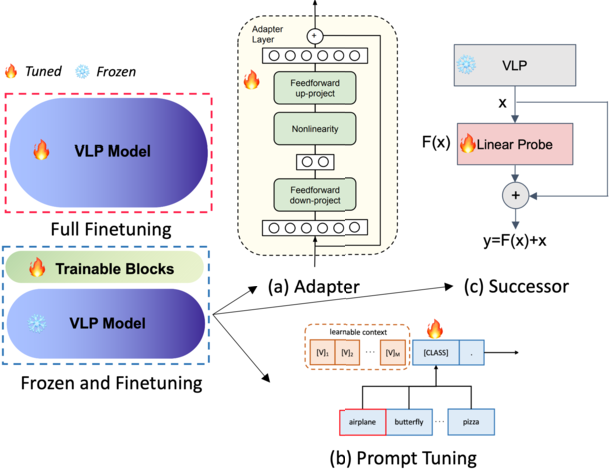
Figure 1 from Using Self-Supervised Dual Constraint Contrastive ...
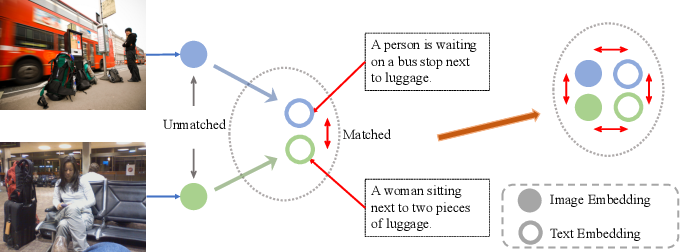
Figure 1 from Contrastive Cross-Modal Knowledge Sharing Pre-training ...

Figure 1 from Text encoders bottleneck compositionality in contrastive ...
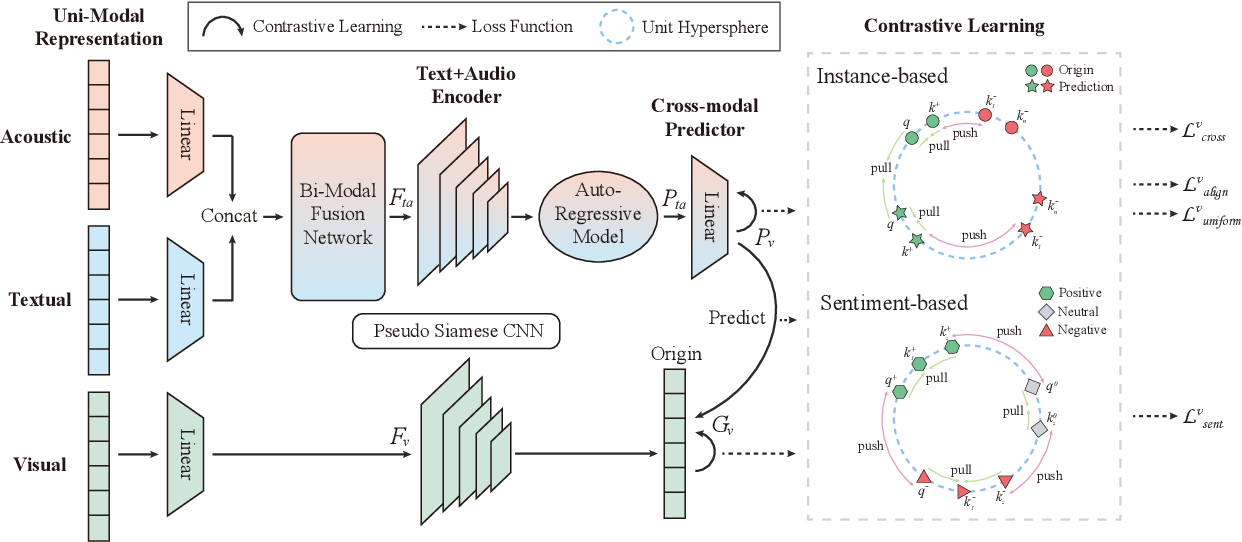
Figure 1 from Multimodal Contrastive Learning via Uni-Modal Coding and ...

Figure 1 from Unsupervised Contrastive Cross-Modal Hashing | Semantic ...
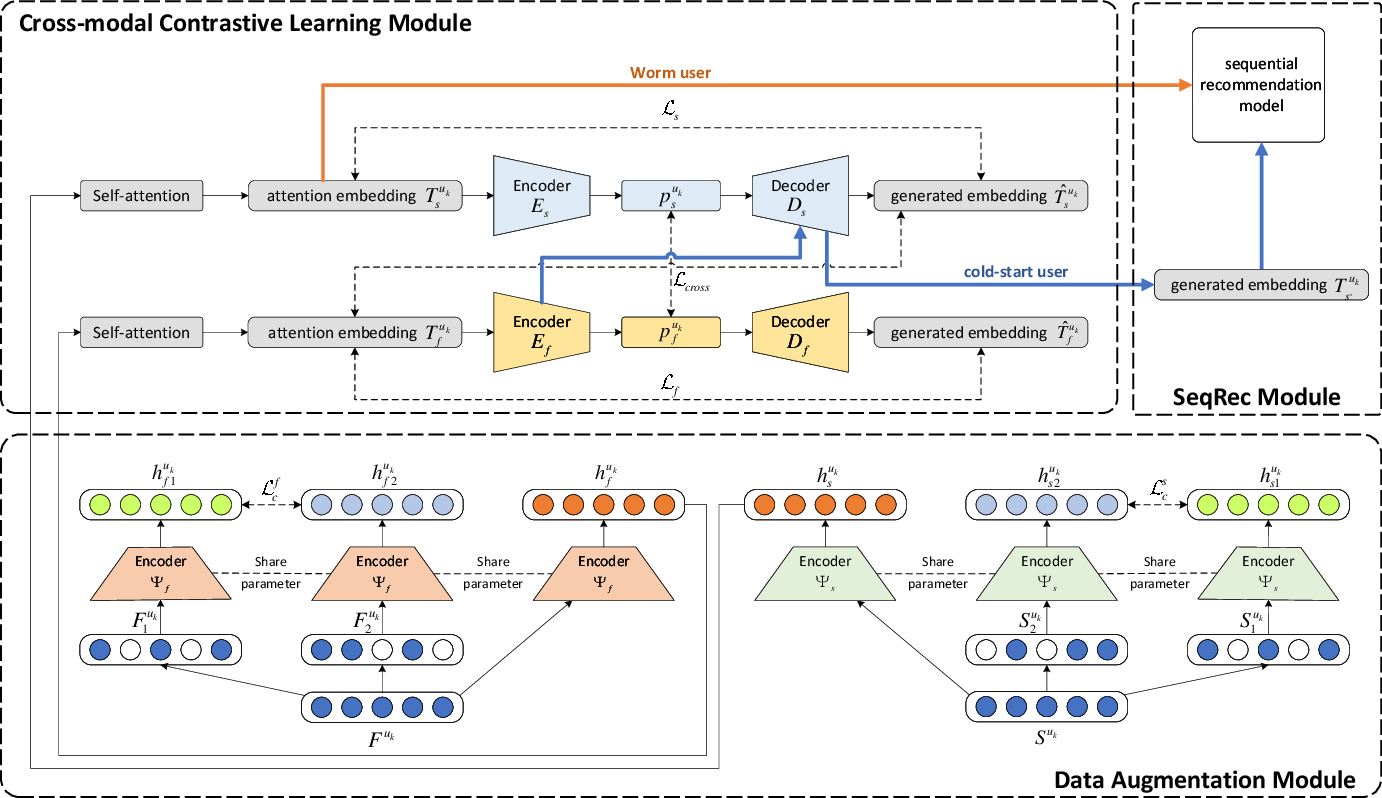
Figure 1 from CMCLRec: Cross-modal Contrastive Learning for User Cold ...
Advertisement Space (336x280)

Figure 1 from Contrastive Transformer Cross-Modal Hashing for Video ...
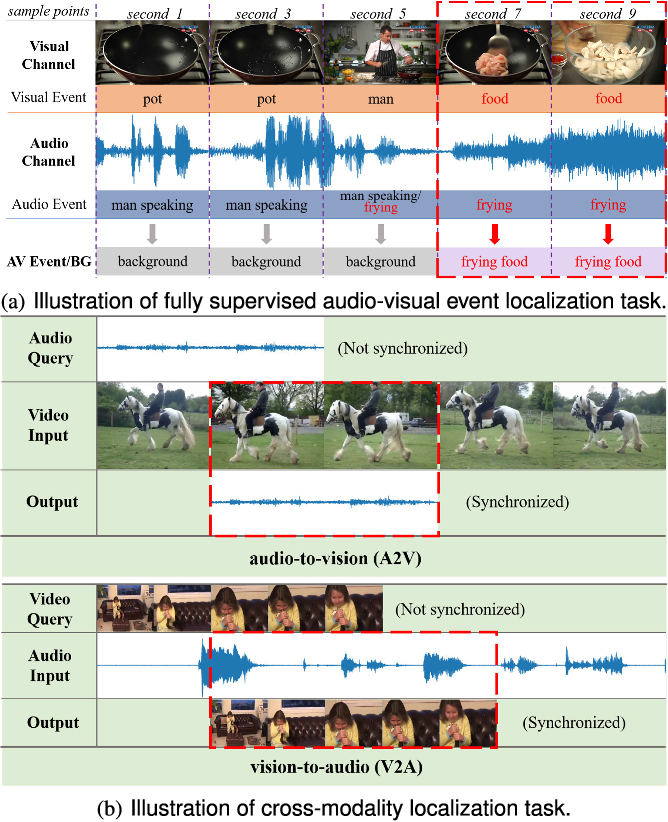
Figure 1 from Listen With Seeing: Cross-Modal Contrastive Learning for ...
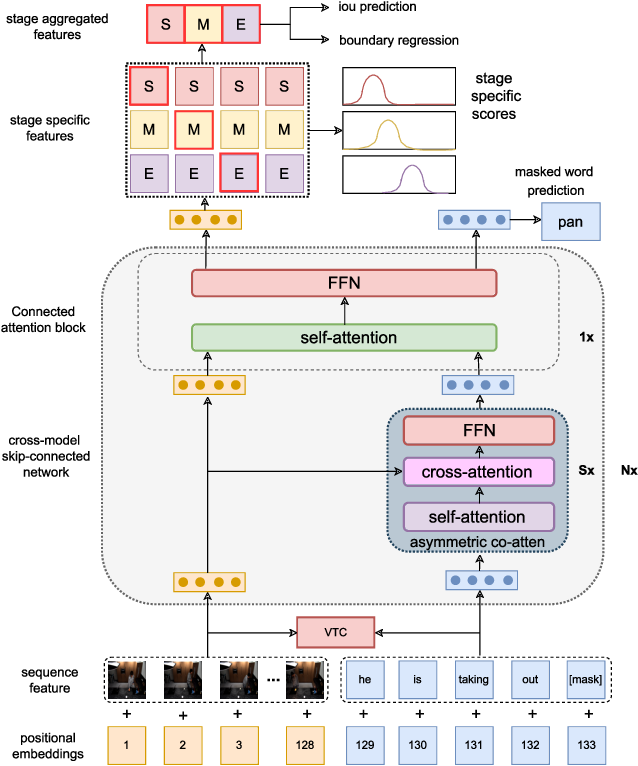
Figure 1 from Cross-modal Contrastive Learning with Asymmetric Co ...
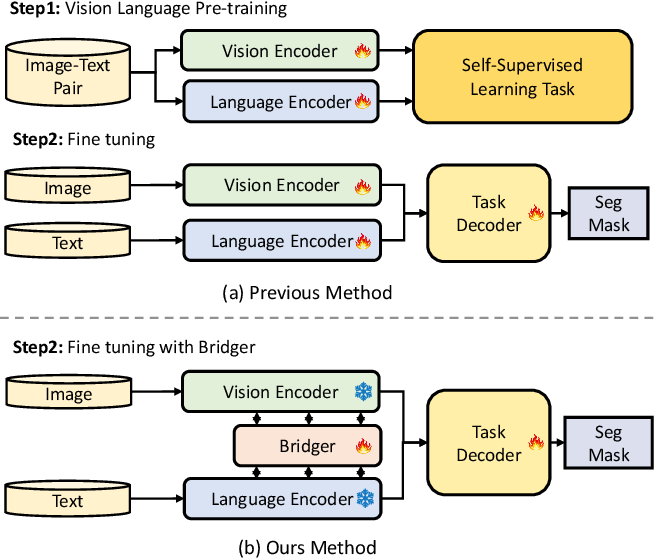
Figure 1 from Bridging Vision and Language Encoders: Parameter ...
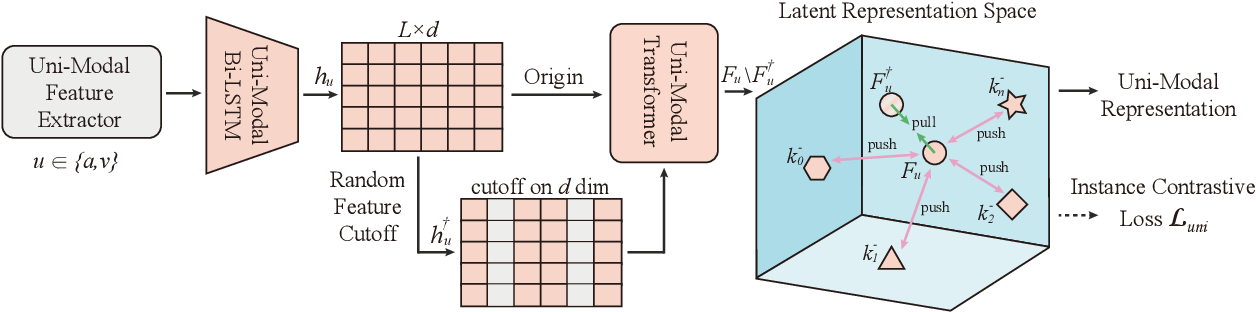
Figure 1 from Multimodal Contrastive Learning via Uni-Modal Coding and ...

Figure 1 from Deep Multi-Level Contrastive Clustering for Multi-Modal ...

Figure 1 from Masking-Based Cross-Modal Remote Sensing Image–Text ...

The architecture of our contrastive framework for cross-lingual NER ...

Overview of the proposed cross-modal contrastive learning. For the ...

Figure 1 from Medical Vision-Language Representation Learning with ...
Advertisement Space (336x280)
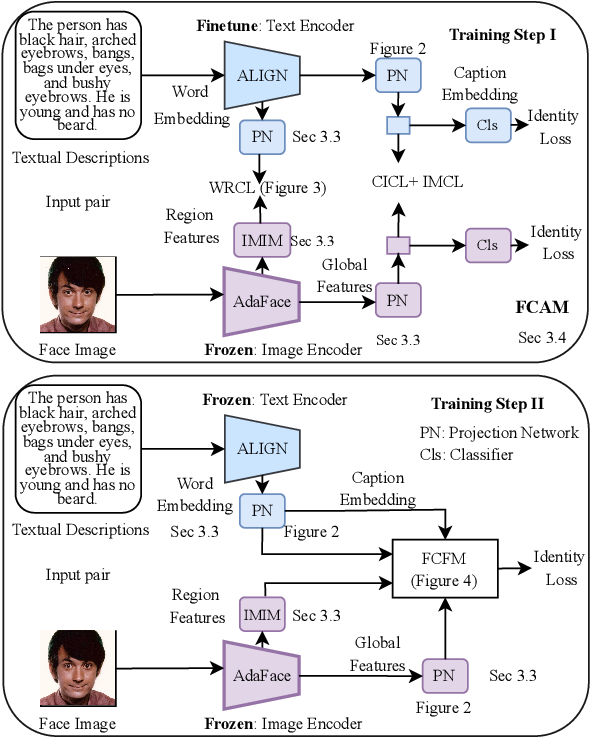
Figure 1 from Text-Guided Face Recognition using Multi-Granularity ...

The architecture of our contrastive framework for cross-lingual NER ...

Overview of the proposed cross-modal contrastive learning method. The ...

Figure 2 from Cross-Modal Contrastive Learning for Text-to-Image ...
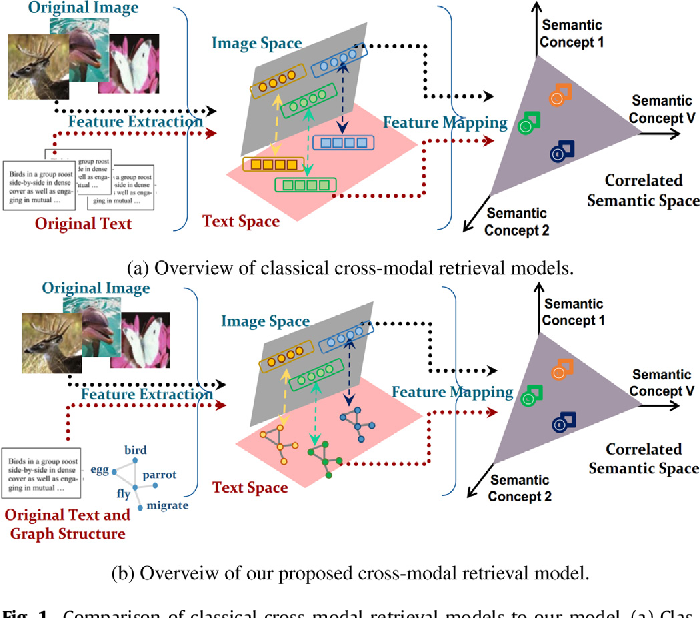
Figure 1 from Learning cross-modal correlations by exploring inter-word ...

Figure 1 from Cross-modal Variational Auto-encoder with Distributed ...