
Figure 1 From Prototype Guided Cross Modal Completion And Alignment For

Figure 1 from Prototype-guided Cross-modal Completion and Alignment for ...

Figure 1 from Prototype-guided Cross-modal Completion and Alignment for ...
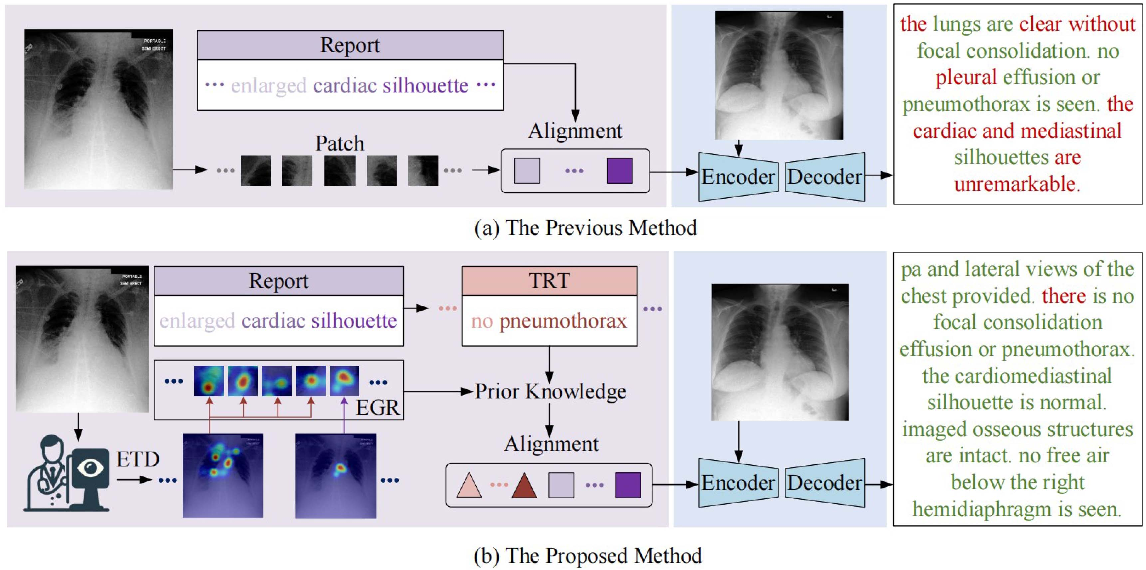
Figure 1 from Eye Gaze Guided Cross-Modal Alignment Network for ...

Figure 1 from Cross-Modal Translation and Alignment for Survival ...

Figure 2 from Enhancing Cross-modal Completion and Alignment for ...

Figure 3 from Prototype-guided Cross-modal Completion and Alignment for ...

Figure 1 from Cross-modal Feature Alignment and Fusion for Composed ...

Table 1 from Prototype-guided Cross-modal Completion and Alignment for ...

Table 1 from Prototype-guided Cross-modal Completion and Alignment for ...
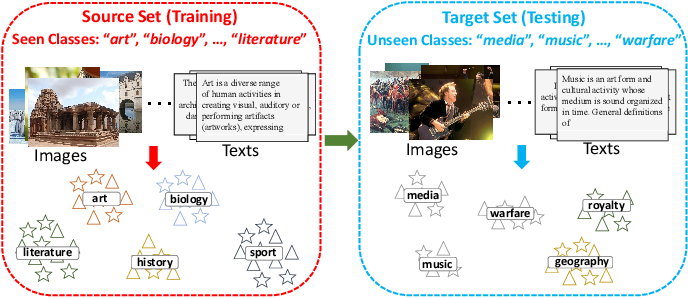
Figure 1 from Correlated Features Synthesis and Alignment for Zero-shot ...
Advertisement Space (300x250)
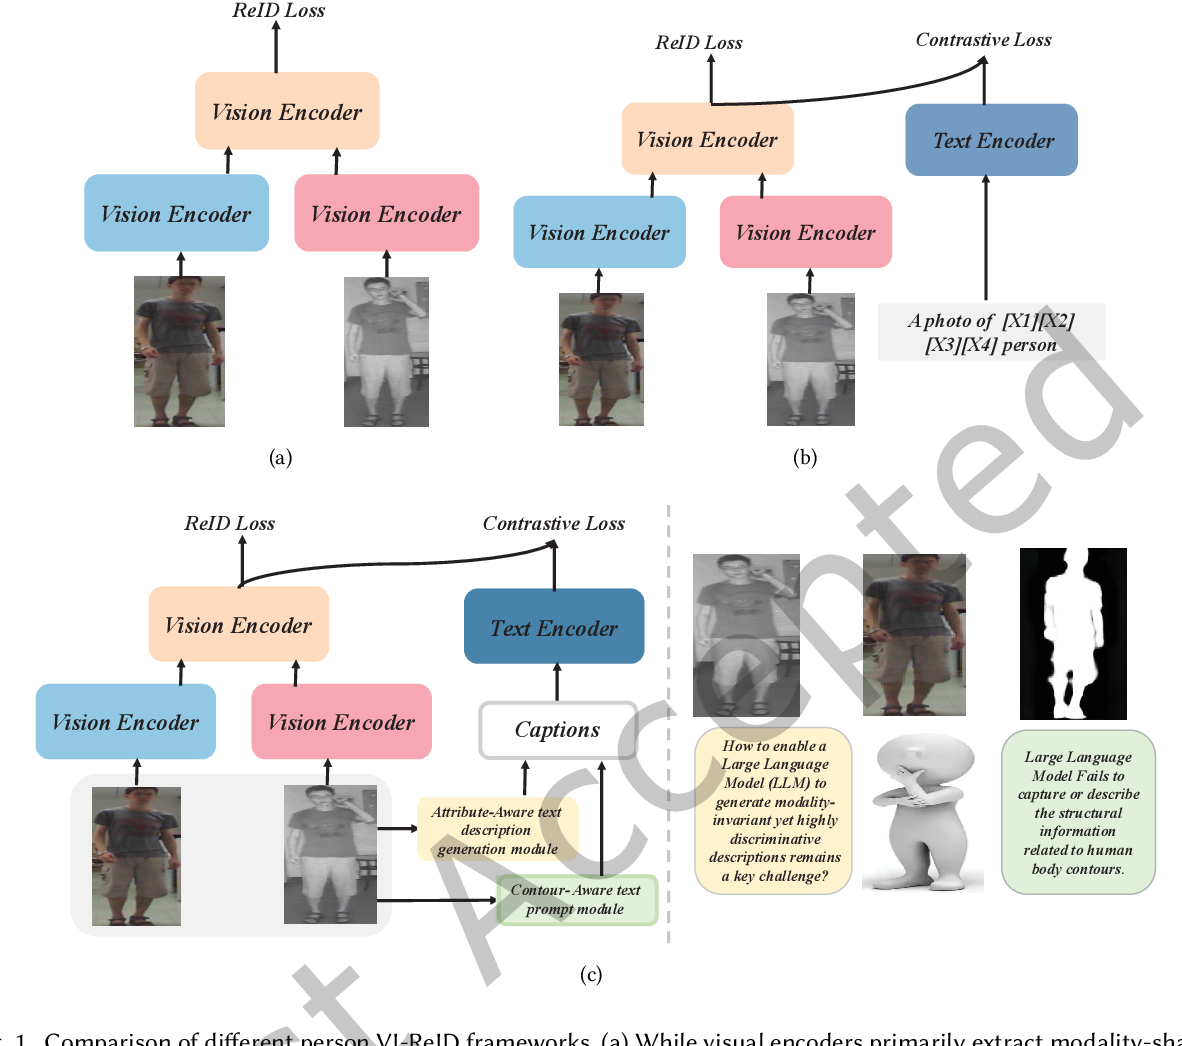
Figure 1 from Text-Guided Cross-Modal Alignment with Attribute and ...

Figure 1 from CA_DeepSC: Cross-Modal Alignment for Multi-Modal Semantic ...

Figure 1 from Improving Cross-modal Alignment for Text-Guided Image ...

Figure 1 from Cross-Modal Cross-Domain Moment Alignment Network for ...

Figure 1 from Learning Modality Knowledge Alignment for Cross-Modality ...
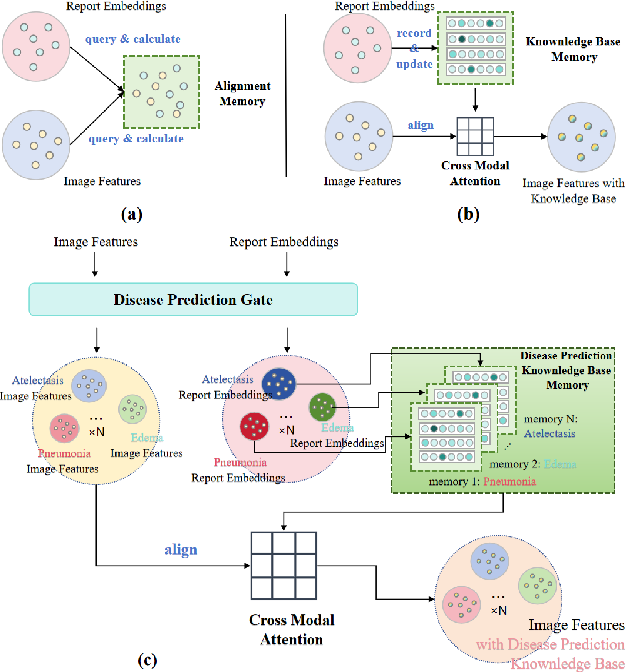
Figure 1 from Adaptive Semantic Alignment for Automated Radiology ...

Figure 1 from Cross-Modal Cross-Domain Dual Alignment Network for RGB ...

Figure 1 from Multi-modal Prototype Guided Few-shot Object Detection ...

Figure 1 from Discrete Joint Semantic Alignment Hashing for Cross-Modal ...

Figure 1 from Global Guided Cross-Modal Cross-Scale Network for RGB-D ...
Advertisement Space (336x280)

Figure 1 from Effectiveness Guided Cross-Modal Information Sharing for ...

Figure 4 from Multi-level Alignment Network for Domain Adaptive Cross ...

Figure 1 from Memory-Based Cross-Modal Semantic Alignment Network for ...

Figure 1 from Query-Guided Prototype Learning with Decoder Alignment ...

Figure 1 from Multi-Modal Cross-Domain Alignment Network for Video ...

Figure 3 from Multi-level Alignment Network for Domain Adaptive Cross ...

Figure 2 from Eye Gaze Guided Cross-Modal Alignment Network for ...
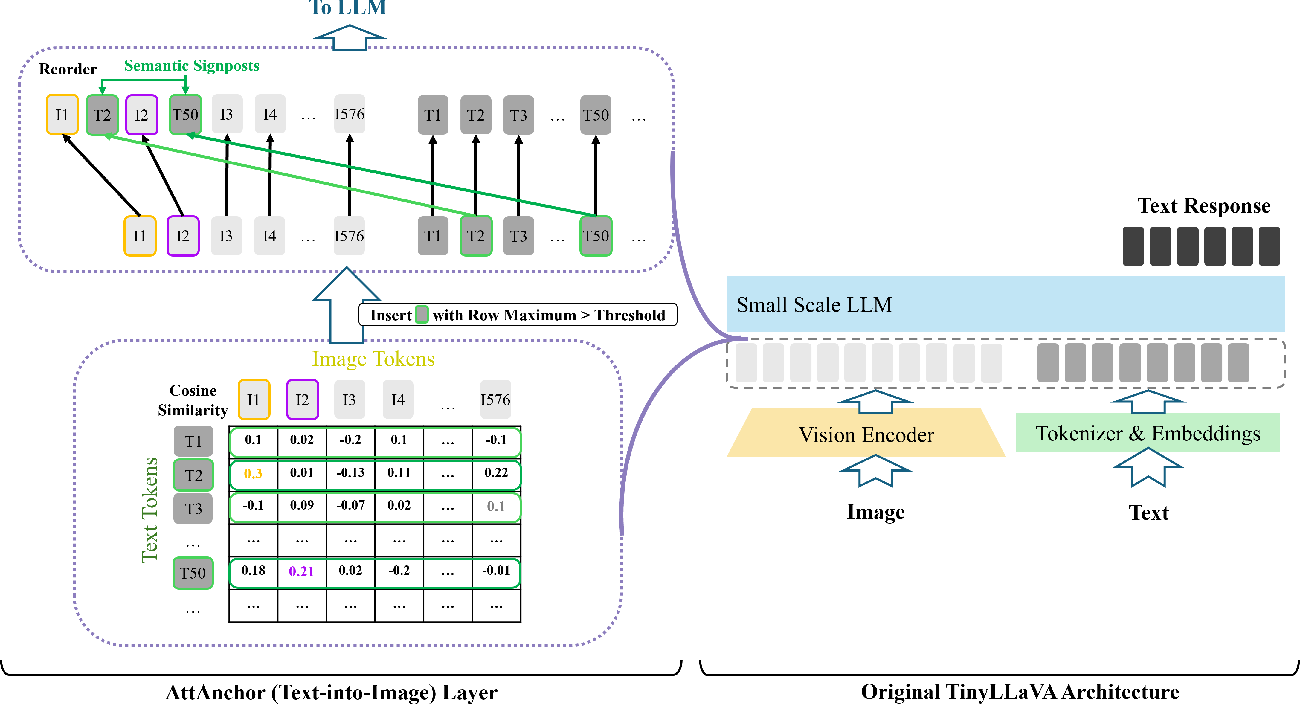
Figure 1 from AttAnchor: Guiding Cross-Modal Token Alignment in VLMs ...

Figure 1 from Enhancing LLMs for Time Series Forecasting via Structure ...
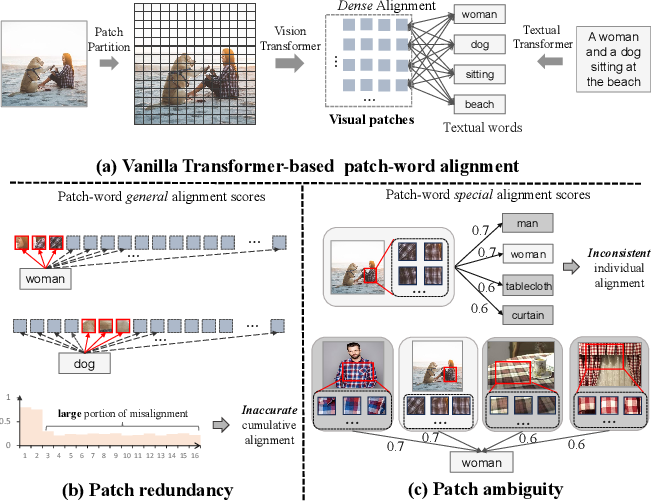
Figure 1 from Linguistic-Aware Patch Slimming Framework for Fine ...
Advertisement Space (336x280)
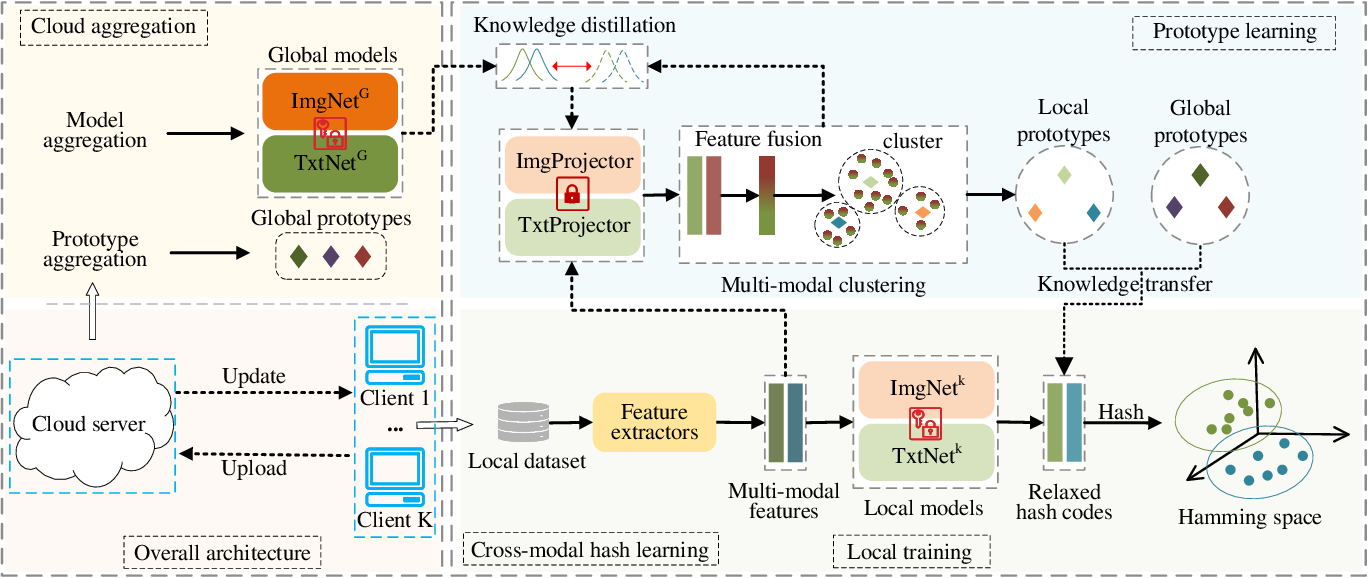
Figure 1 from Prototype-guided Knowledge Transfer for Federated ...
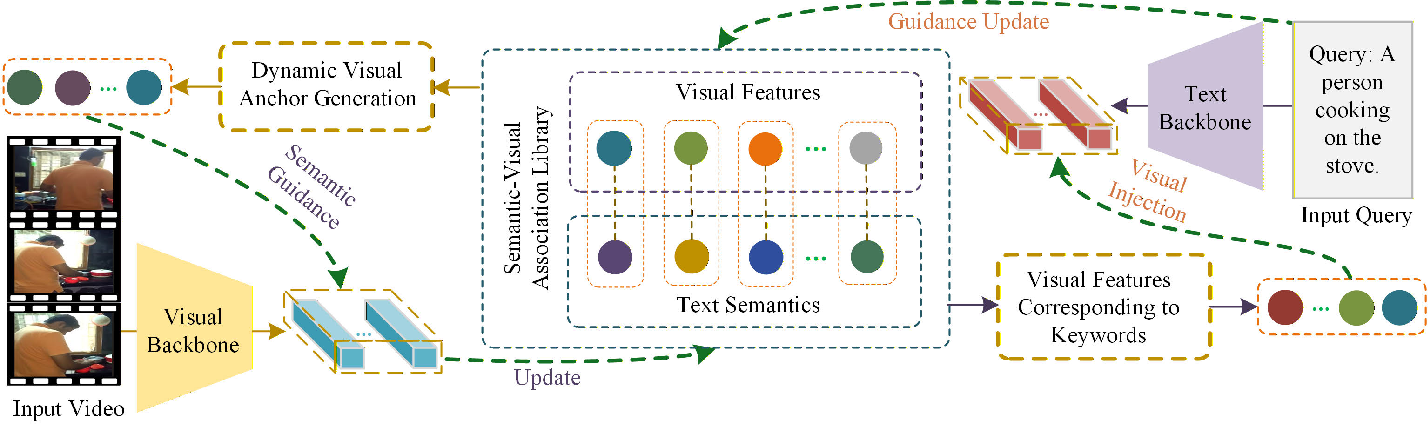
Figure 1 from Bidirectional Cross-Modal Collaborative Alignment via ...

Prototype-guided Cross-modal Completion and Alignment for Incomplete ...
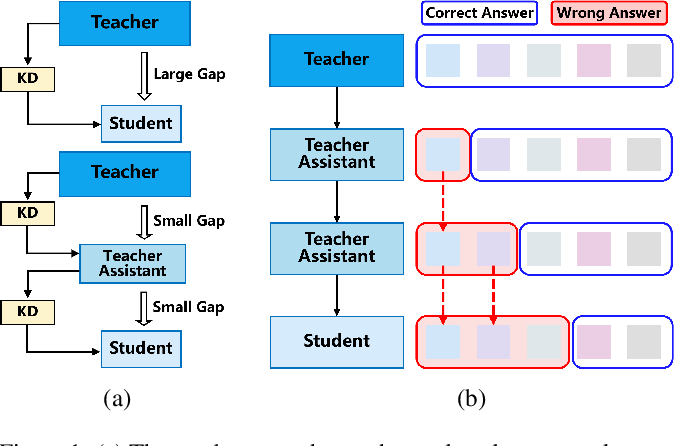
Figure 1 from A Cross-Modal Densely Guided Knowledge Distillation Based ...
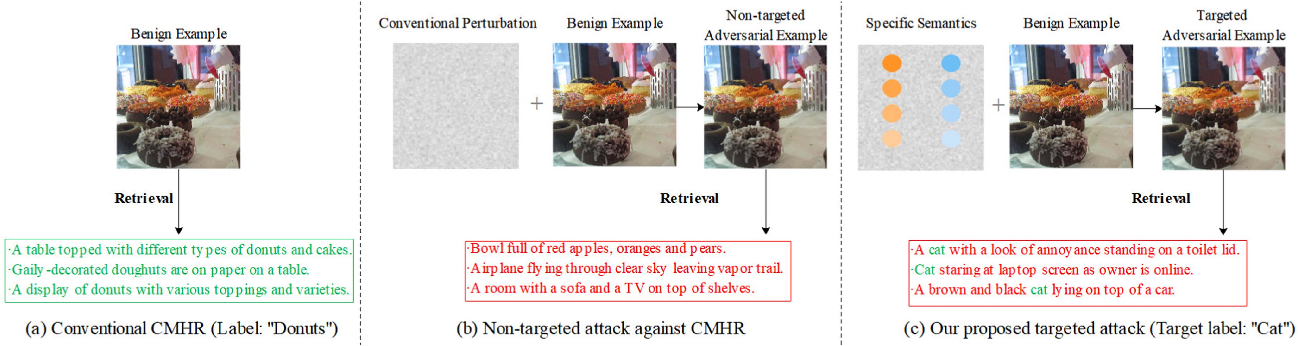
Figure 1 from Primary Code Guided Targeted Attack against Cross-modal ...

Figure 1 from Improved CLIP cross-modal retrieval model for fine ...