
Figure 1 From Recurrent Drafter For Fast Speculative Decoding In Large

Figure 1 from Recurrent Drafter for Fast Speculative Decoding in Large ...

Figure 1 from Recurrent Drafter for Fast Speculative Decoding in Large ...

Table 1 from Recurrent Drafter for Fast Speculative Decoding in Large ...
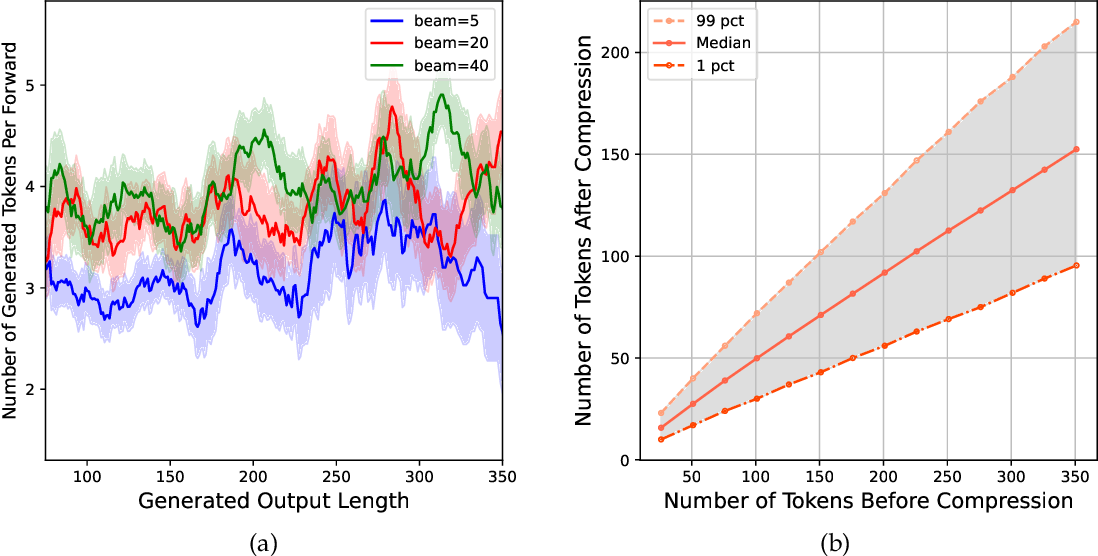
Figure 5 from Recurrent Drafter for Fast Speculative Decoding in Large ...
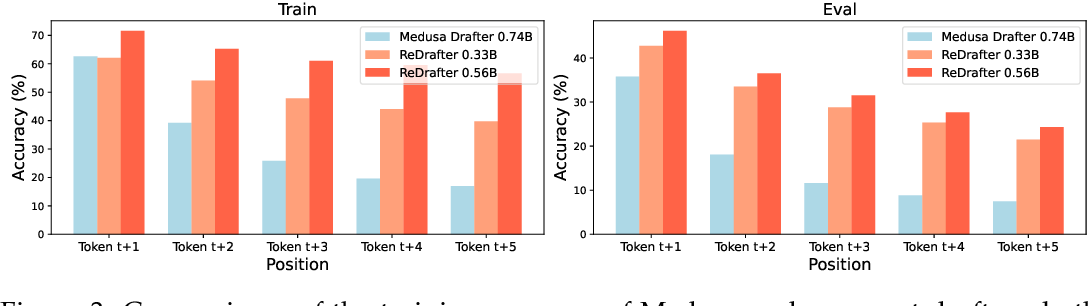
Figure 3 from Recurrent Drafter for Fast Speculative Decoding in Large ...

Recurrent Drafter for Fast Speculative Decoding in Large Language Models

Recurrent Drafter for Fast Speculative Decoding in Large Language ...

Recurrent Drafter for Fast Speculative Decoding in Large Language ...
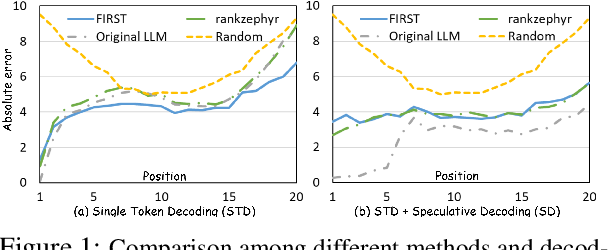
Figure 1 from Reinforcement Speculative Decoding for Fast Ranking ...
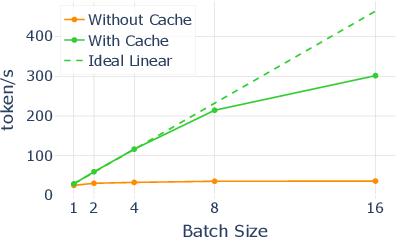
Figure 1 from Self Speculative Decoding for Diffusion Large Language ...
Advertisement Space (300x250)

Figure 1 from A Unified Framework for Speculative Decoding with ...

Figure 1 from EMS-SD: Efficient Multi-sample Speculative Decoding for ...

Figure 1 from The Synergy of Speculative Decoding and Batching in ...
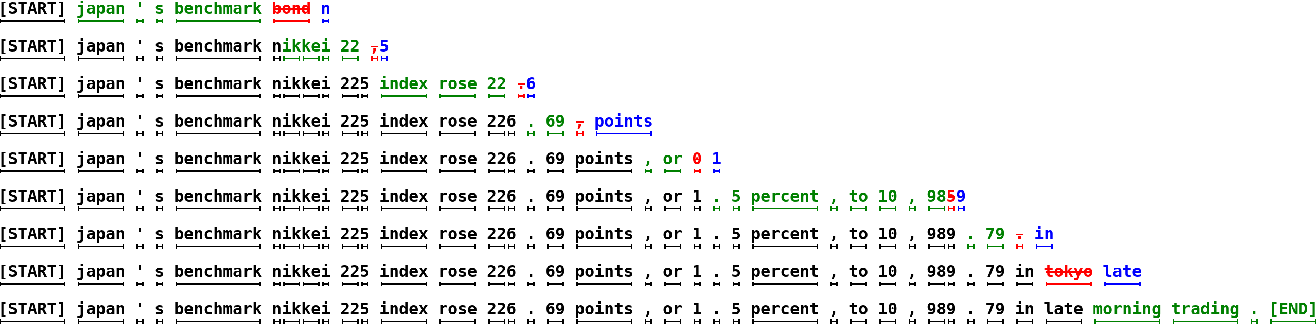
Figure 1 from Fast Inference from Transformers via Speculative Decoding ...

Figure 1 from Fast Inference from Transformers via Speculative Decoding ...

Figure 1 from Unlocking Efficiency in Large Language Model Inference: A ...

Figure 1 from Speculative Decoding with Big Little Decoder | Semantic ...

Figure 1 from Speculative Decoding with Big Little Decoder | Semantic ...
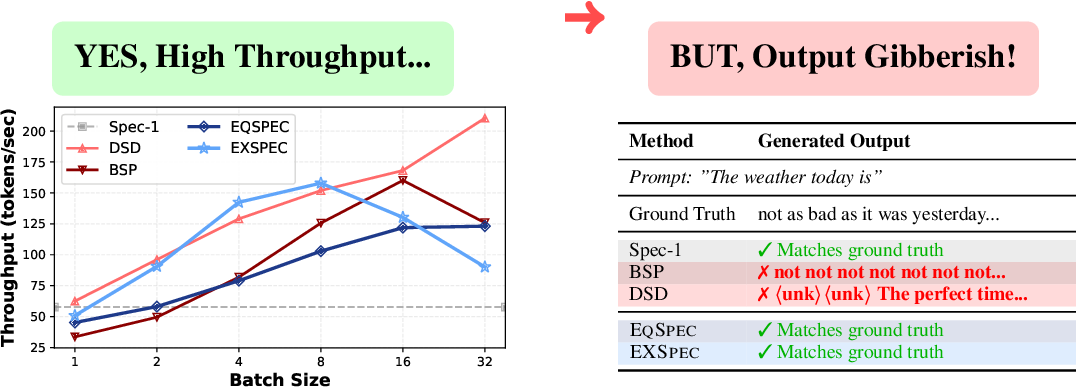
Figure 1 from Batch Speculative Decoding Done Right | Semantic Scholar

Figure 1 from How Speculative Can Speculative Decoding Be? | Semantic ...
Advertisement Space (336x280)

Doubleword | In the fast lane! Speculative decoding - 10x larger model ...

(PDF) Fast Inference from Transformers via Speculative Decoding

(PDF) ParallelSpec: Parallel Drafter for Efficient Speculative Decoding

Speculative Decoding for Fast Text Generation | PDF | Computing ...

Reinforcement Speculative Decoding for Fast Ranking

[논문 리뷰] ParallelSpec: Parallel Drafter for Efficient Speculative Decoding

An Introduction to Speculative Decoding for Reducing Latency in AI ...

[论文评述] SpecVLM: Fast Speculative Decoding in Vision-Language Models

An Introduction to Speculative Decoding for Reducing Latency in AI ...

Paper page - DART: Diffusion-Inspired Speculative Decoding for Fast LLM ...
Advertisement Space (336x280)
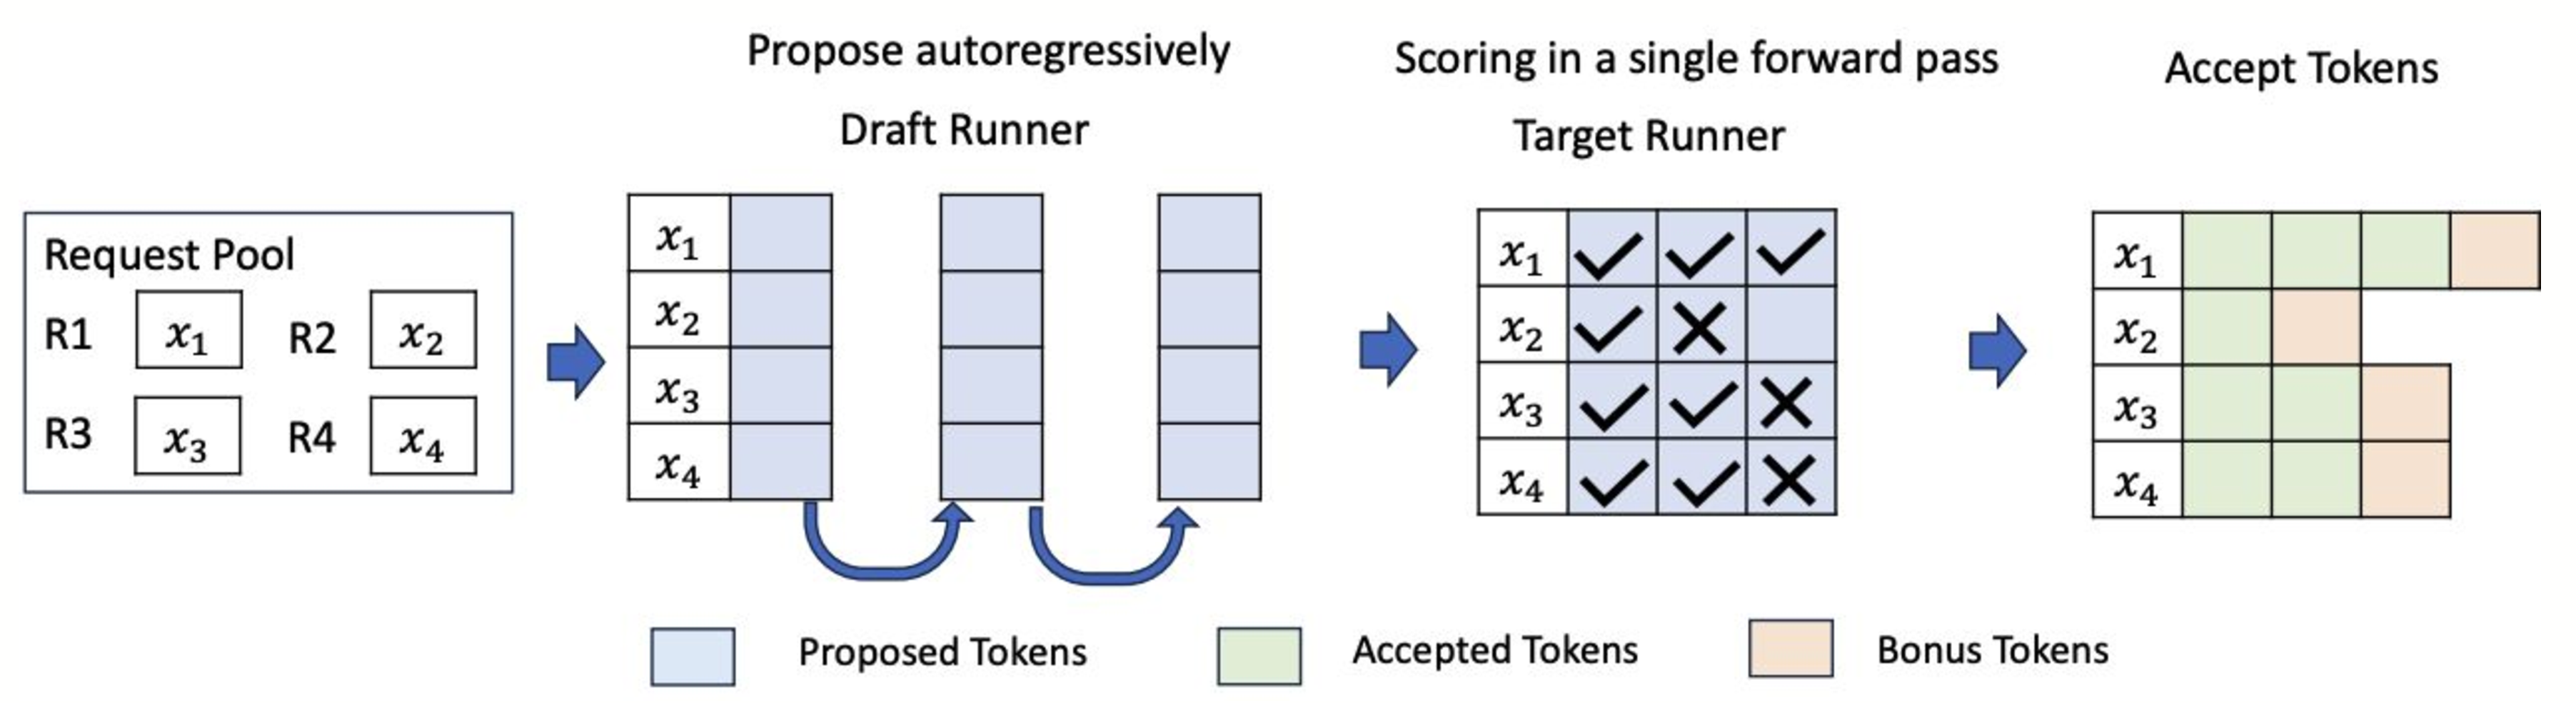
Speculative Decoding in vLLM | OpenLM.ai
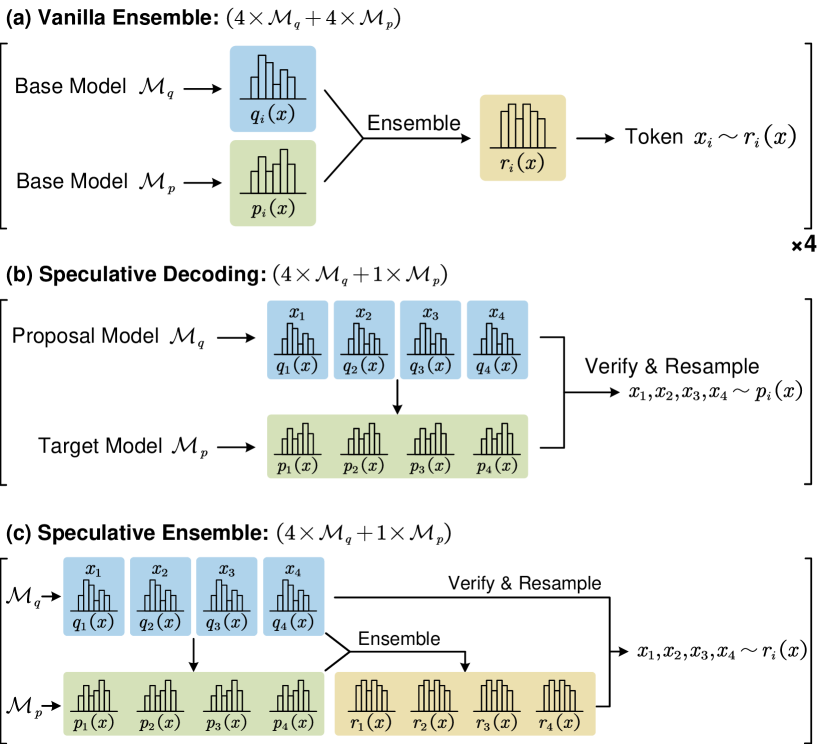
[2502.01662] Speculative Ensemble: Fast Large Language Model Ensemble ...
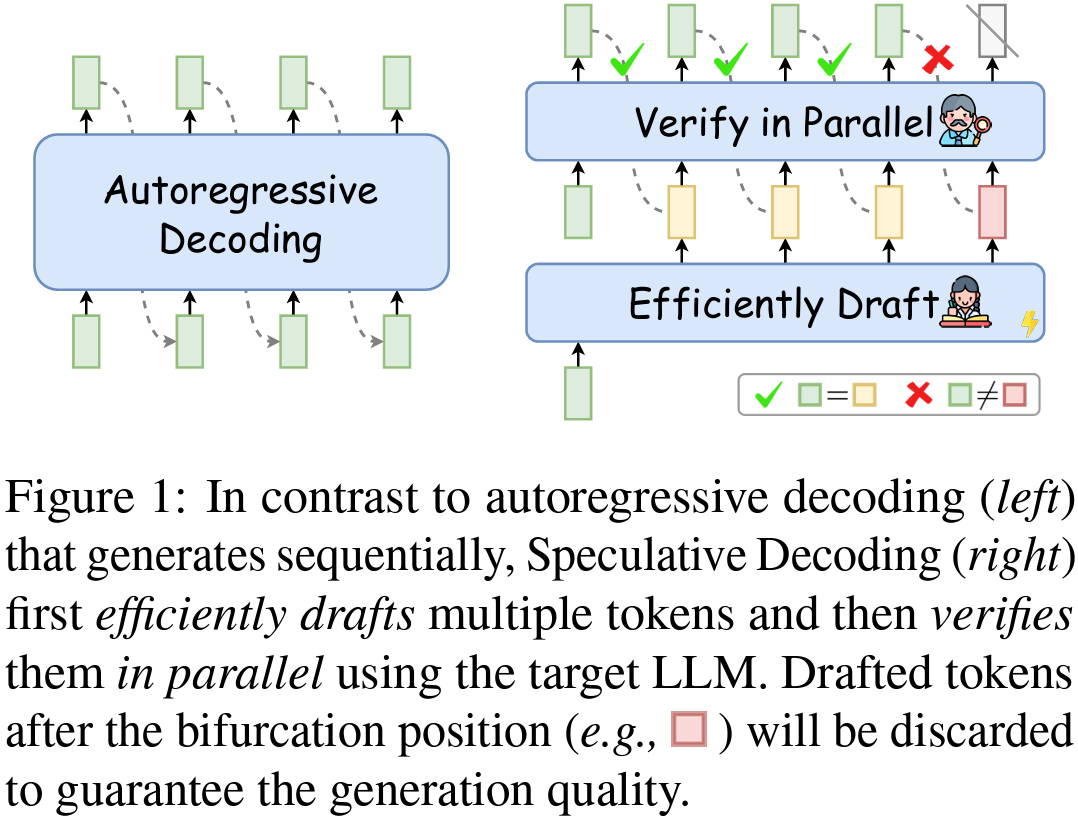
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
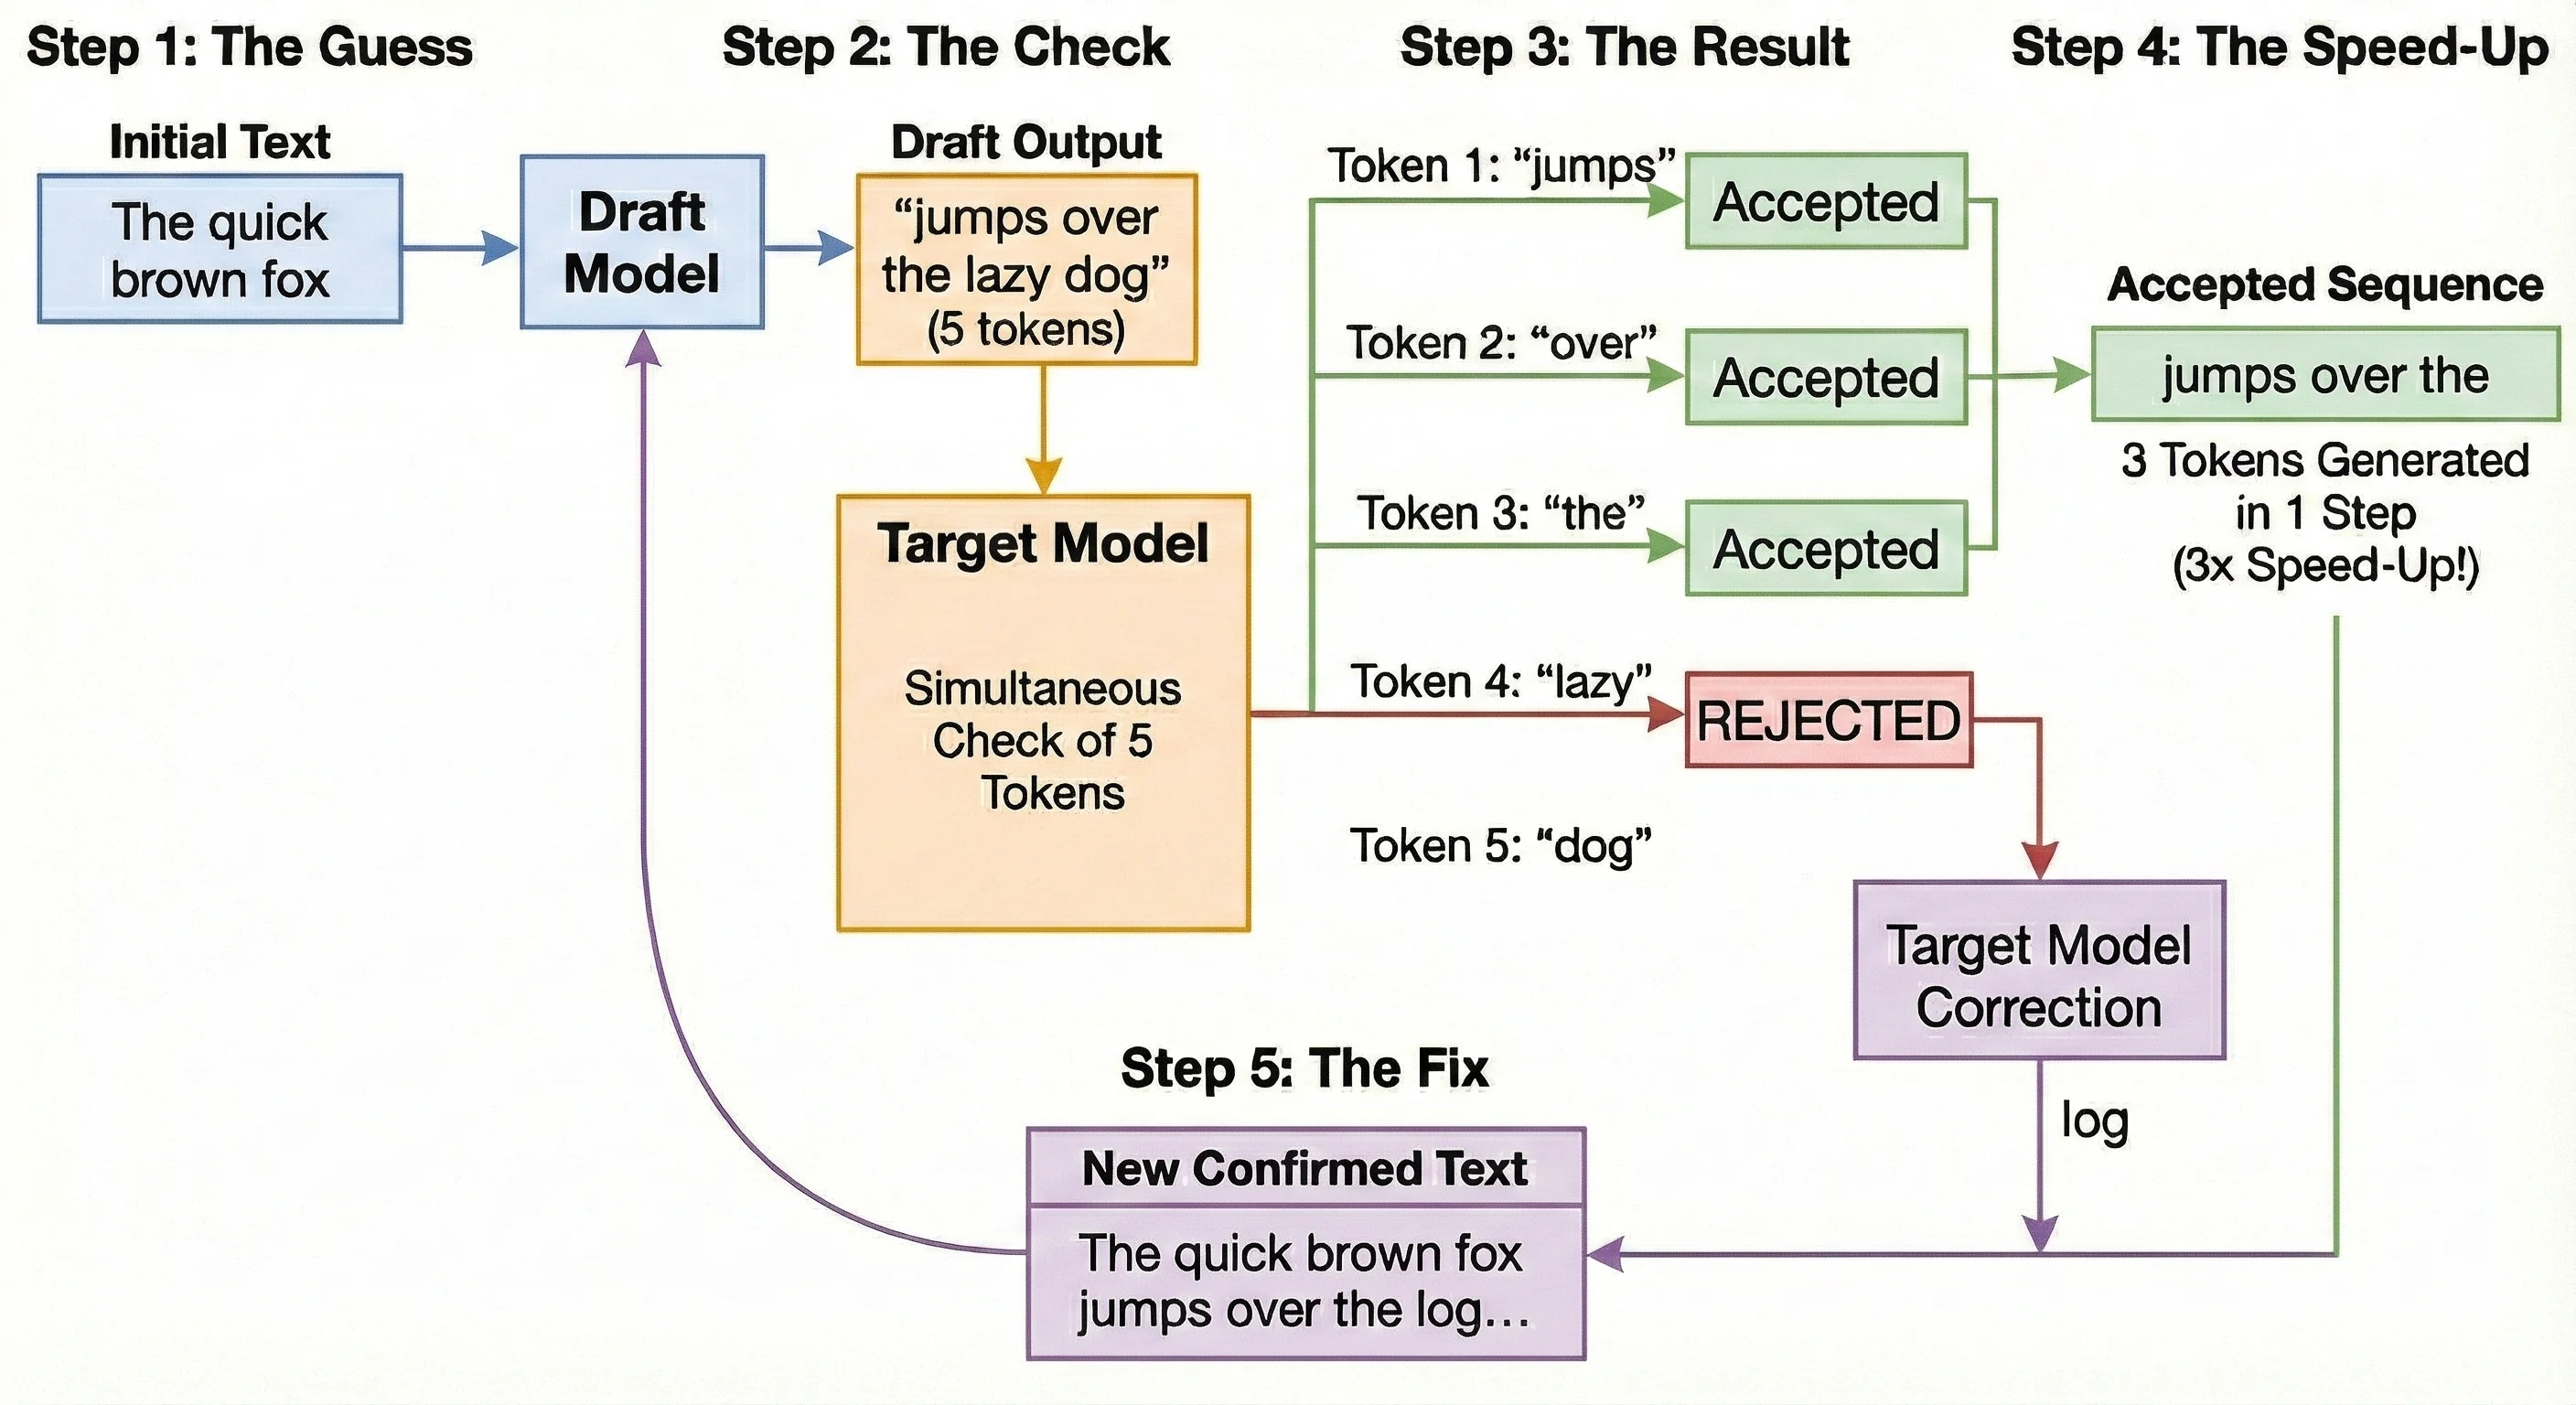
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
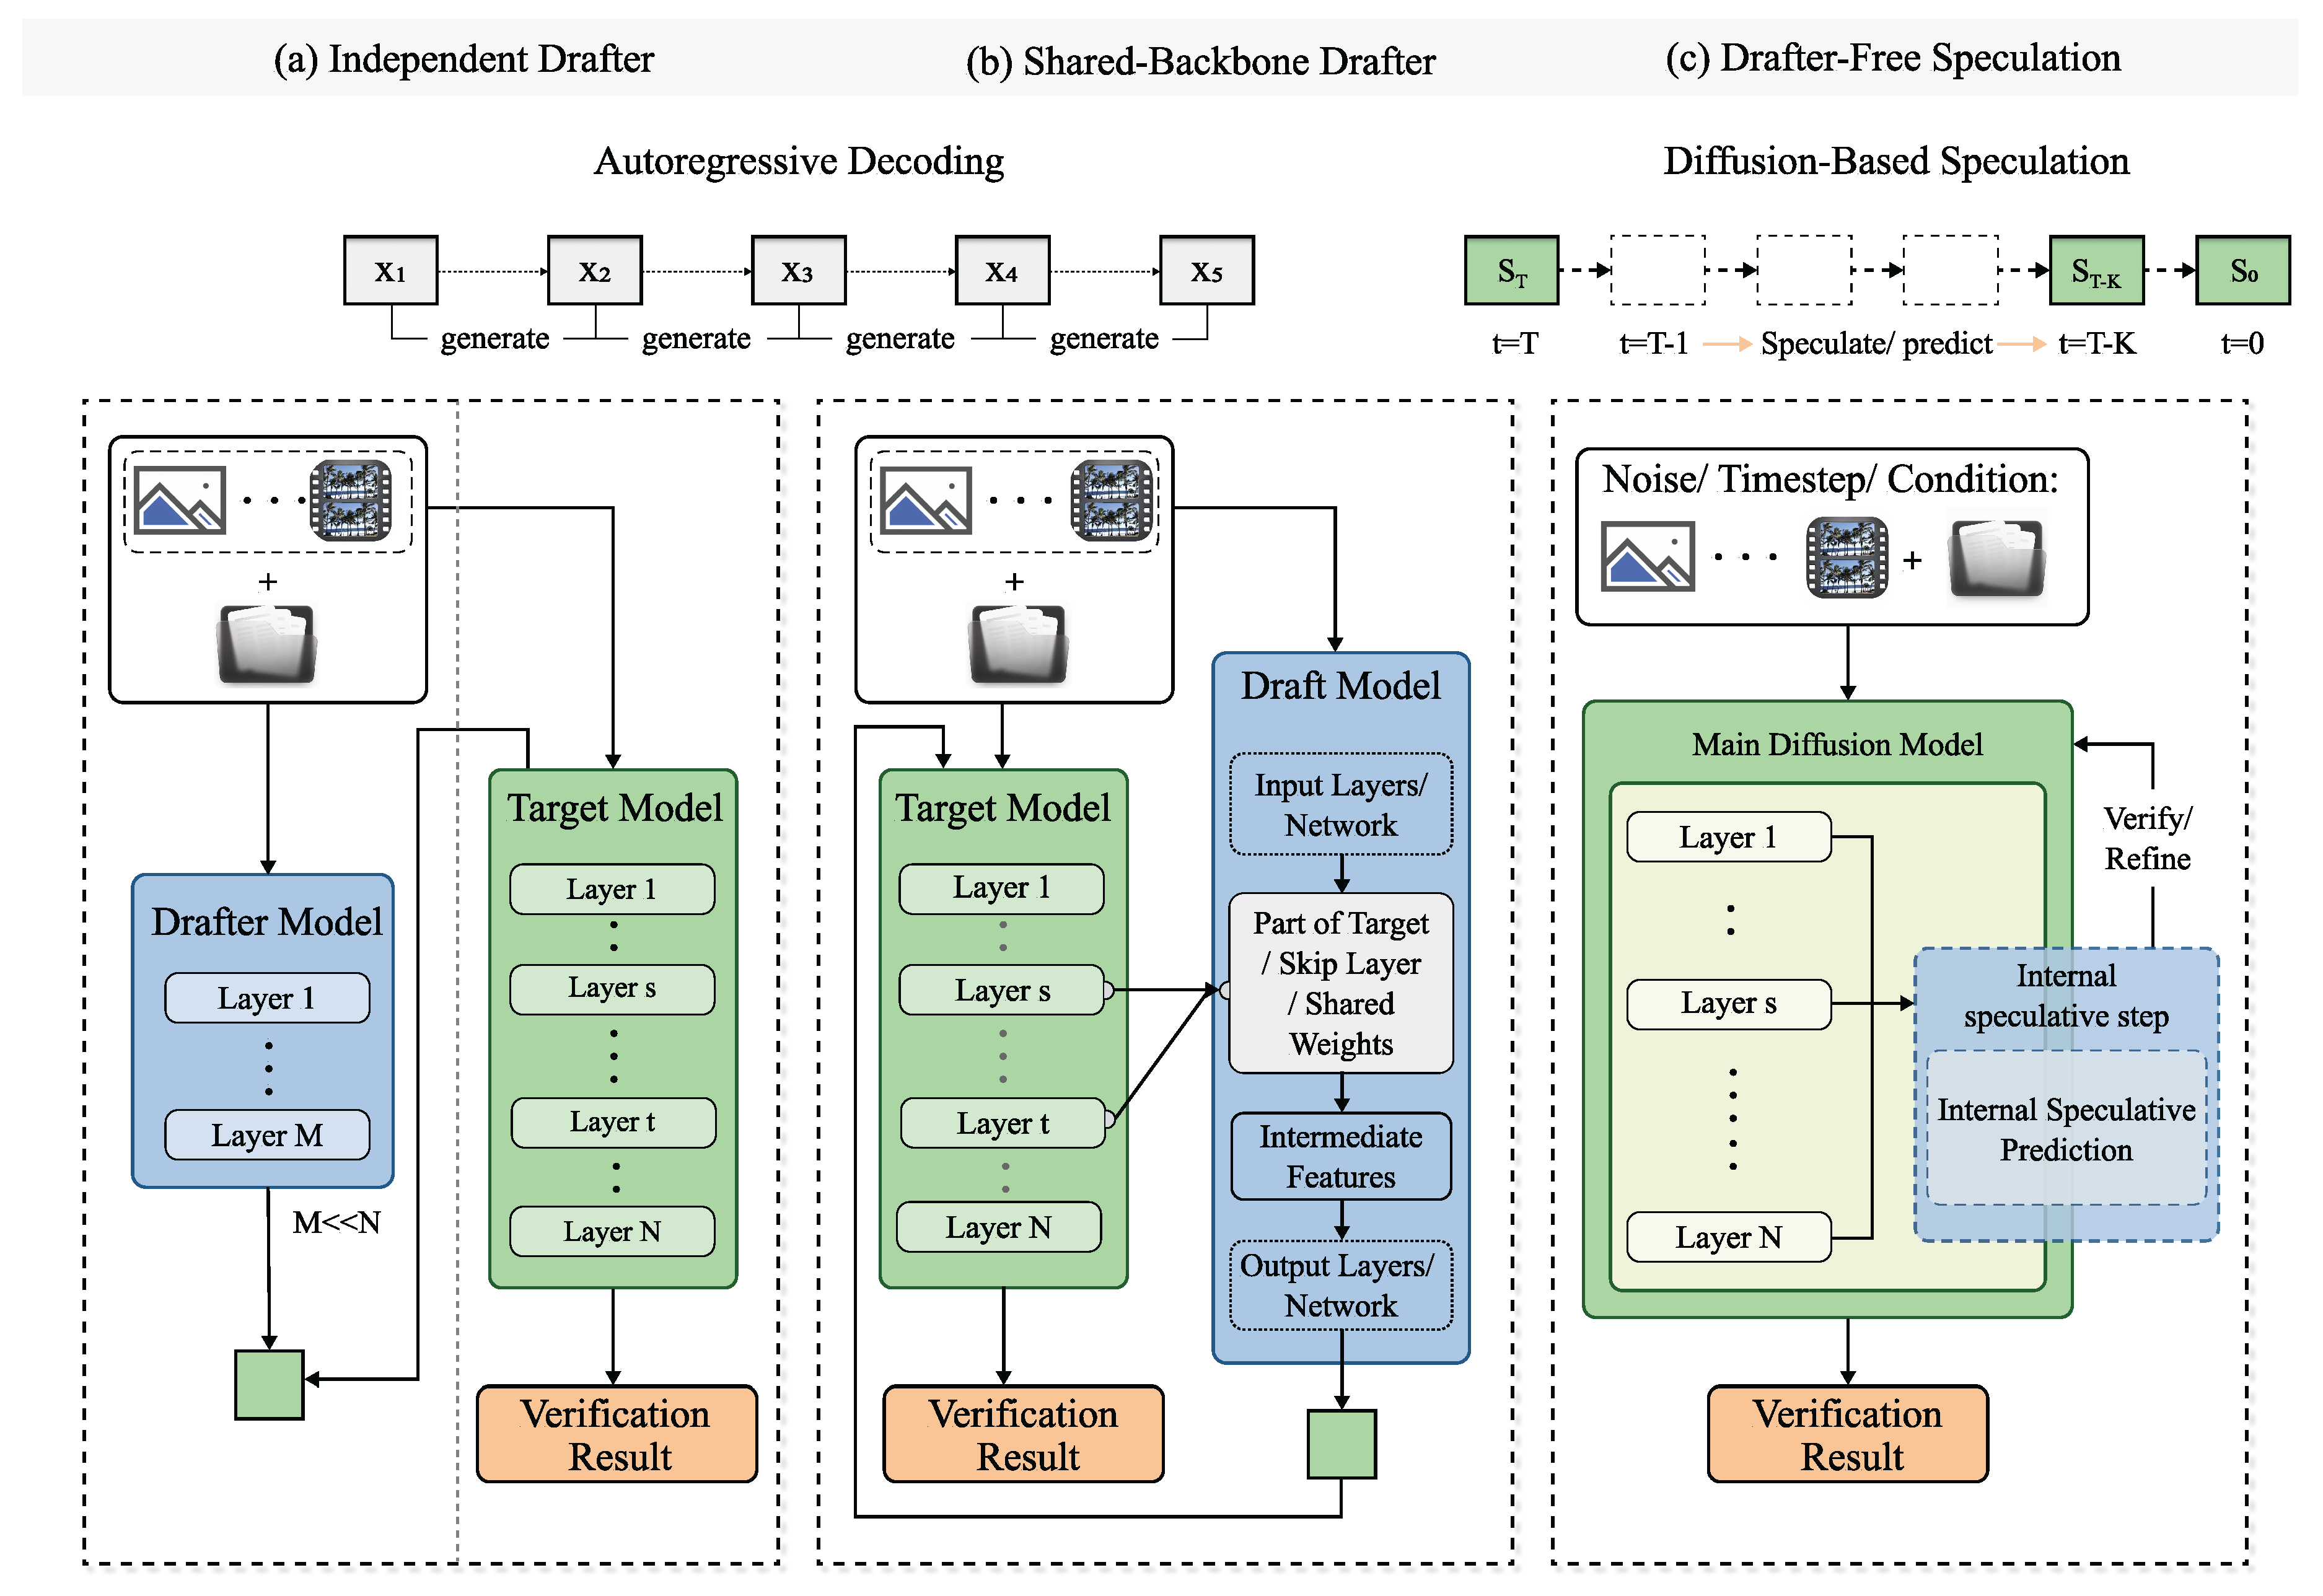
Speculative Decoding for Multimodal Models: A Survey[v2] | Preprints.org
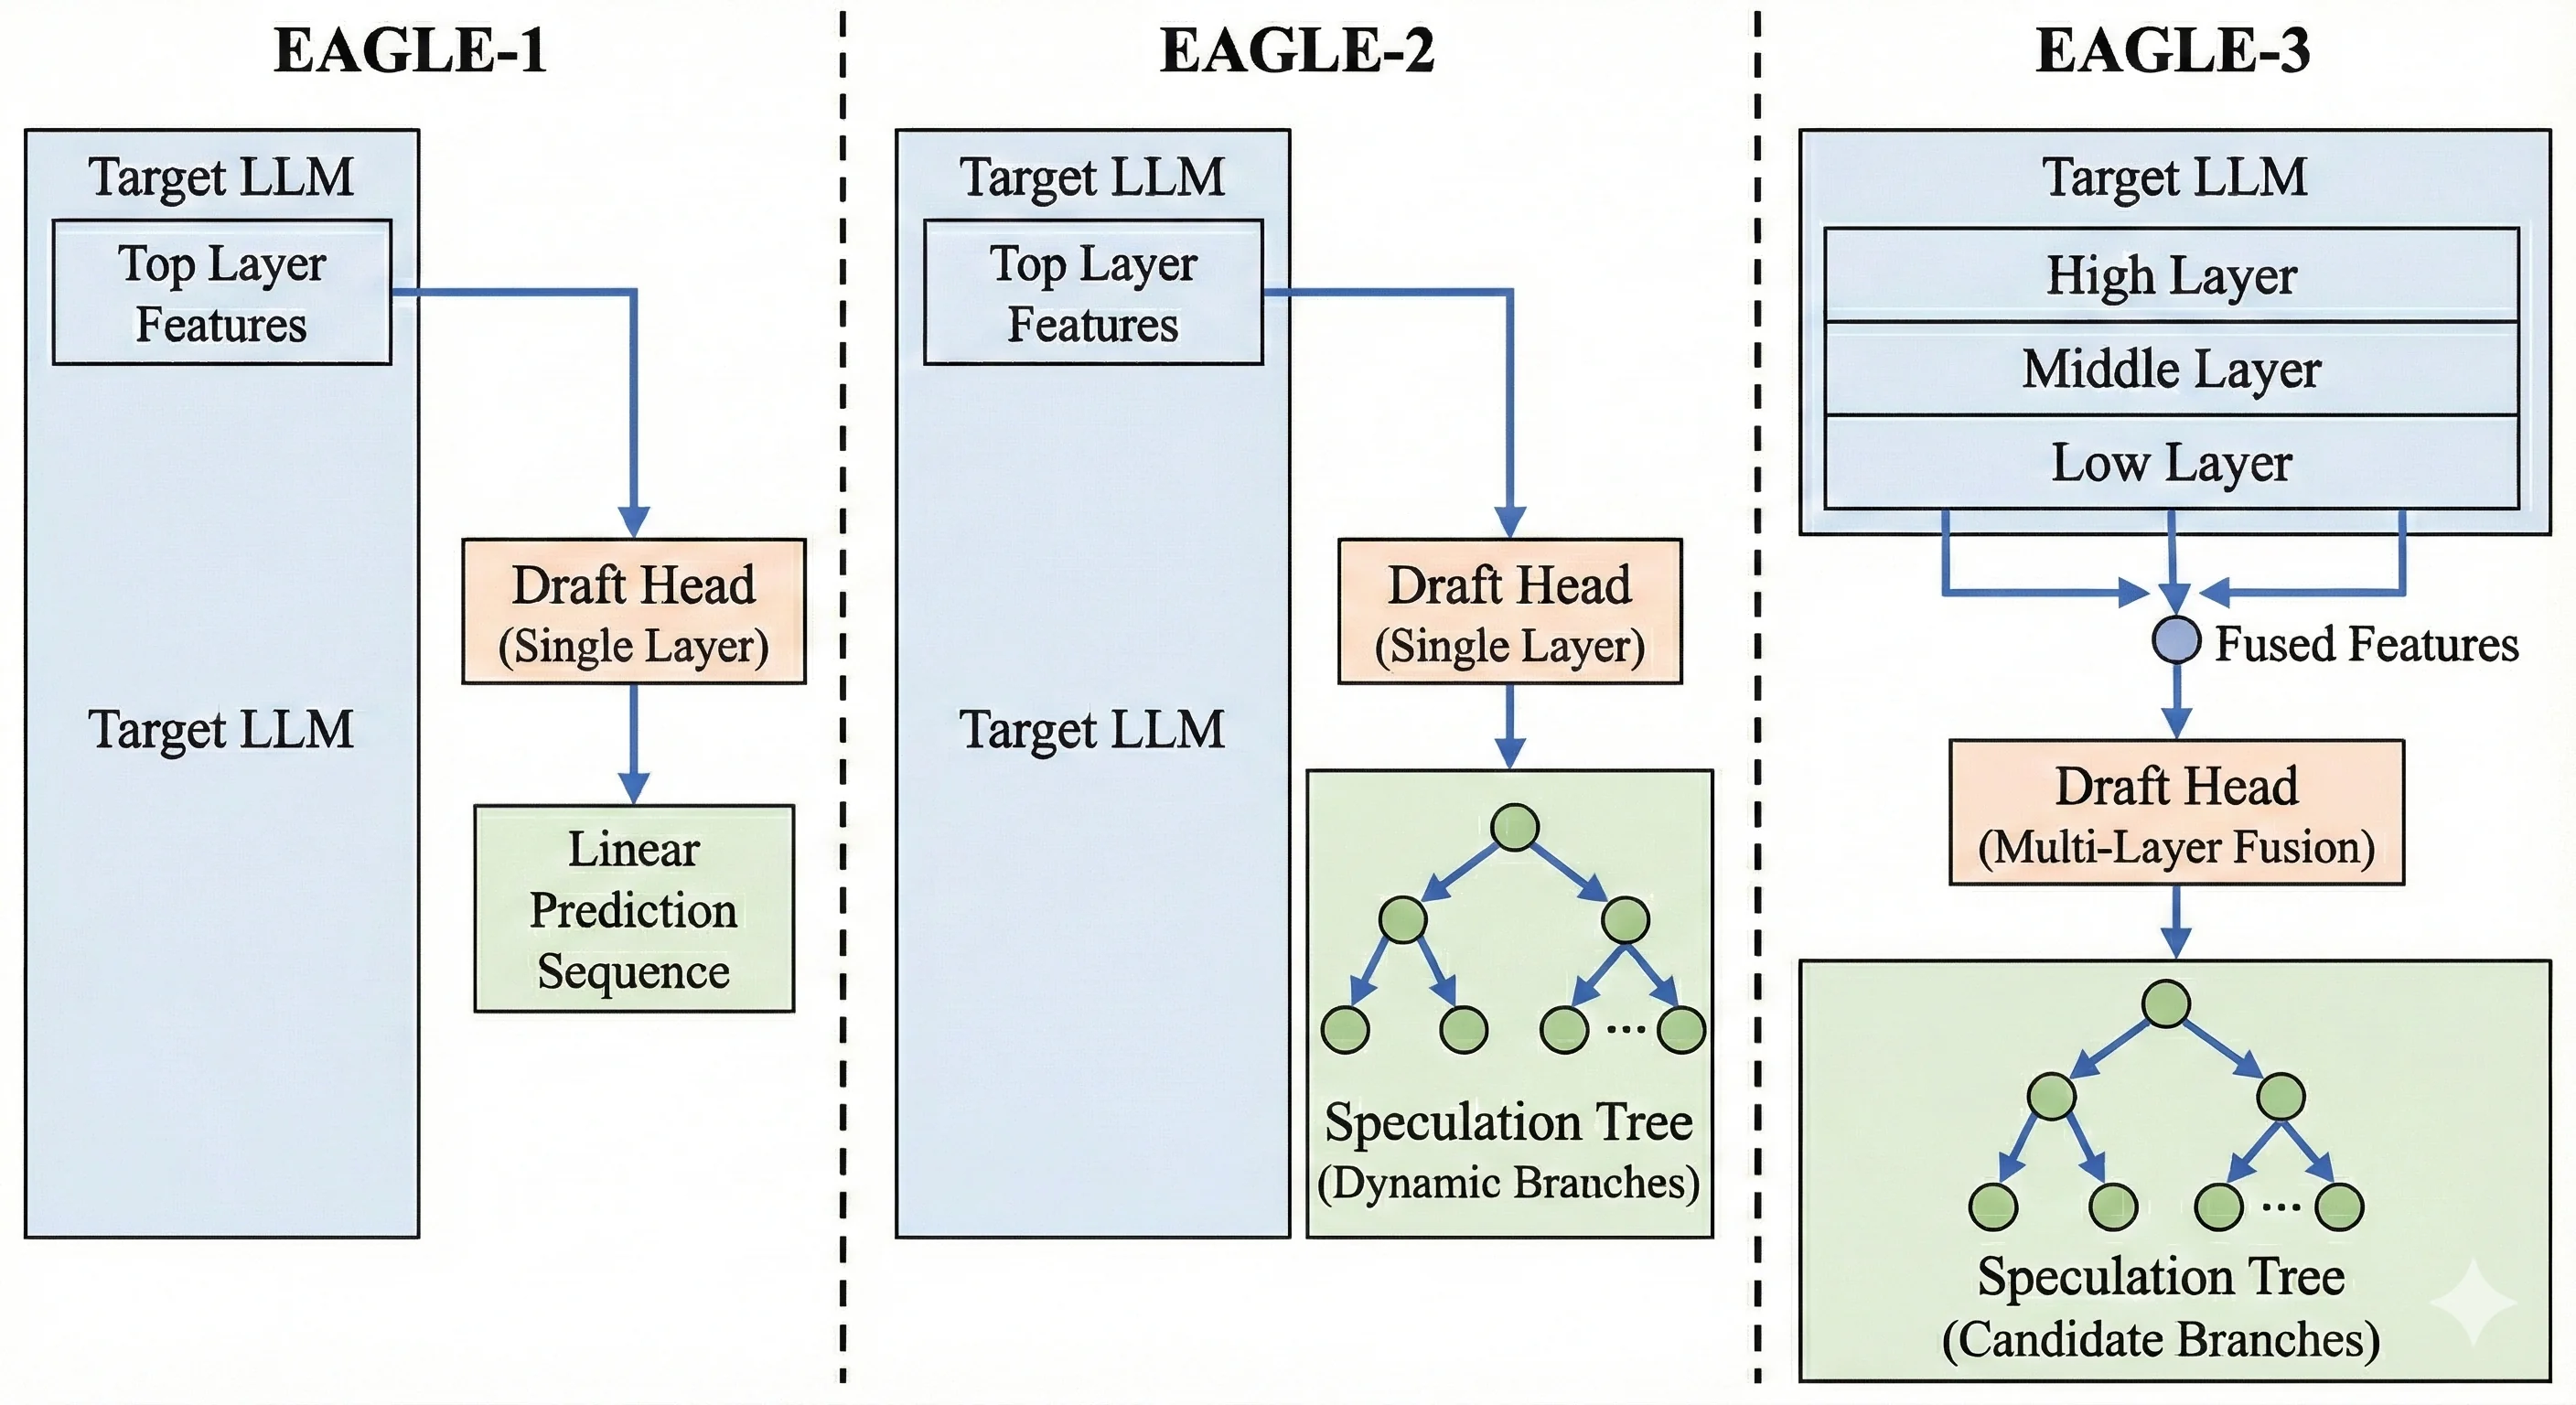
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...