
Figure 1 From Refatomnet Advancing Referring Atomic Video Action

Figure 1 from RefAtomNet++: Advancing Referring Atomic Video Action ...

Figure 1 from Referring Atomic Video Action Recognition | Semantic Scholar

Figure 1 from Referring Atomic Video Action Recognition | Semantic Scholar

Figure 1 from Referring Atomic Video Action Recognition | Semantic Scholar
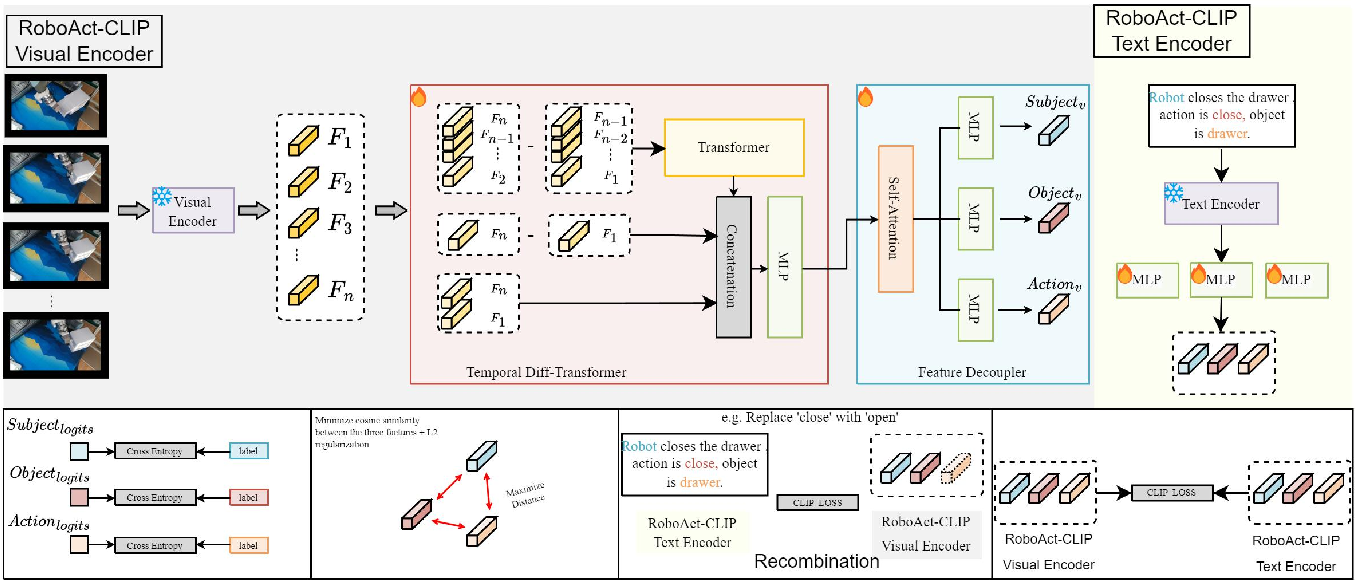
Figure 1 from RoboAct-CLIP: Video-Driven Pre-training of Atomic Action ...
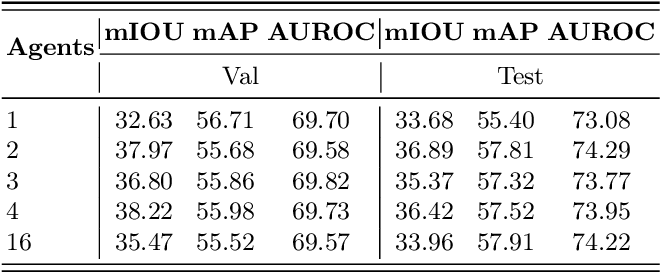
Table 8 from Referring Atomic Video Action Recognition | Semantic Scholar
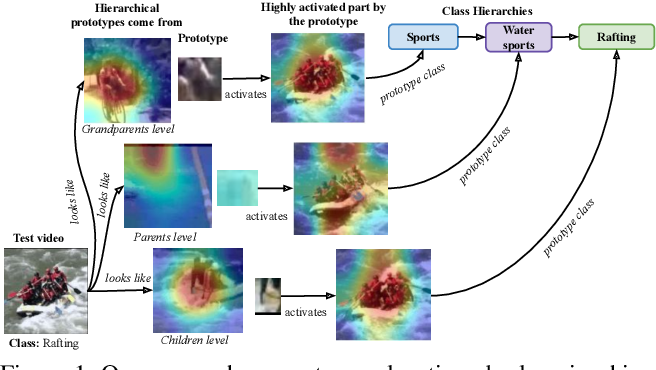
Figure 1 from Hierarchical Explanations for Video Action Recognition ...

Referring Atomic Video Action Recognition | AI Research Paper Details

ECCV2024 Referring Atomic Video Action Recognition - YouTube
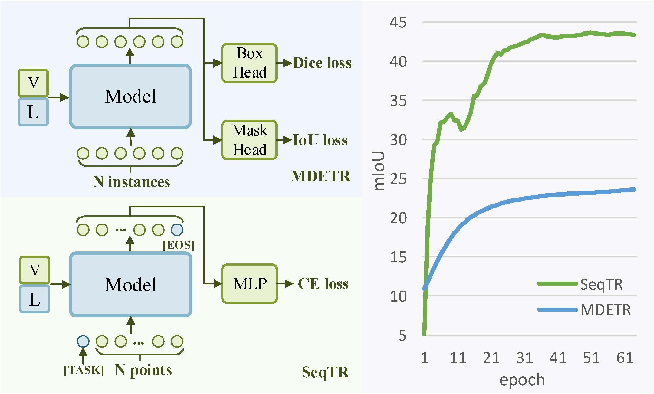
Figure 1 from Learning to Segment Every Referring Object Point by Point ...
Advertisement Space (300x250)
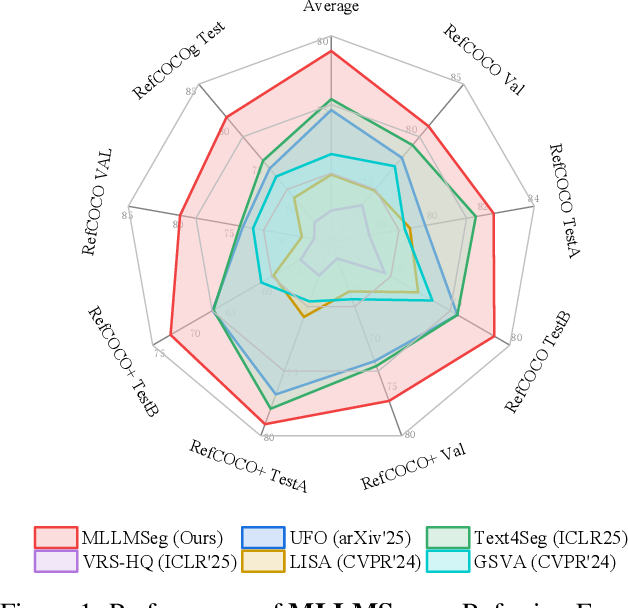
Figure 1 from Unlocking the Potential of MLLMs in Referring Expression ...

Figure 1 from A Large-Scale Human-Centric Benchmark for Referring ...
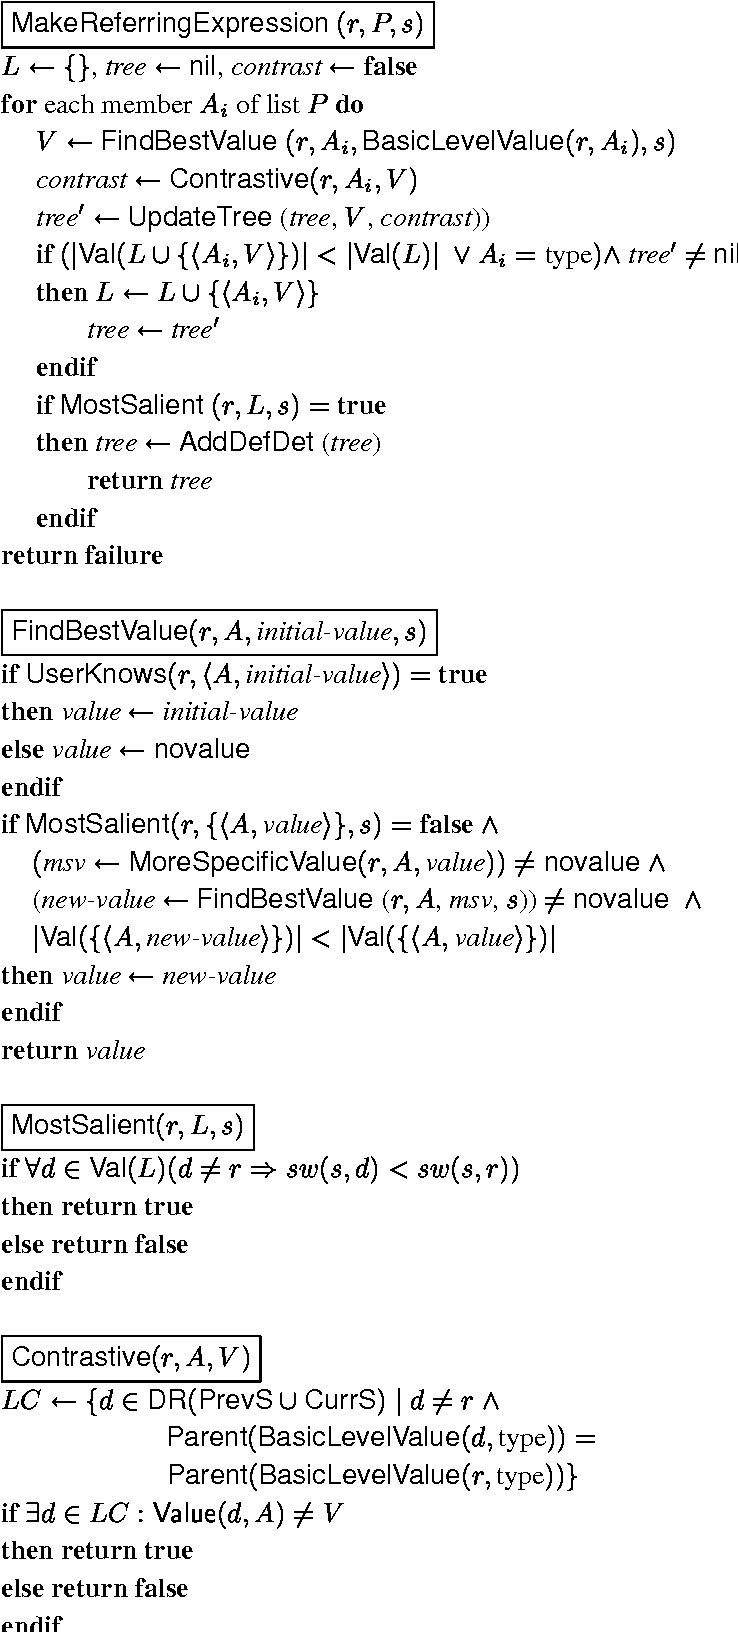
Figure 1 from Efficient context-sensitive generation of referring ...

Sample frames from video clips for all three Atomic Group Action ...
GitHub - KPeng9510/RAVAR: Github repo for referring atomic video action ...

Figure 1 from Mask Grounding for Referring Image Segmentation ...
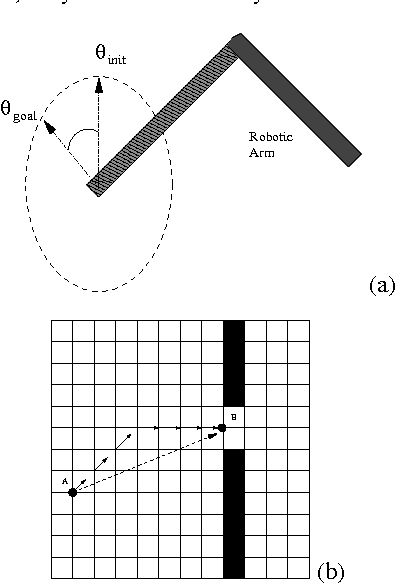
Figure 1 from Reinforcement Learning with Action Discovery | Semantic ...
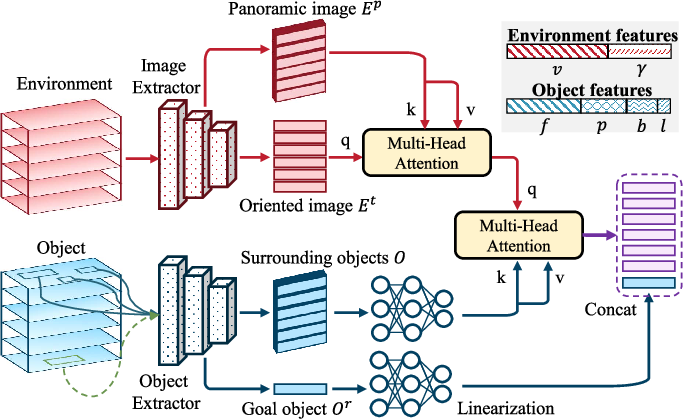
Figure 1 from RES-StS: Referring Expression Speaker via Self-Training ...
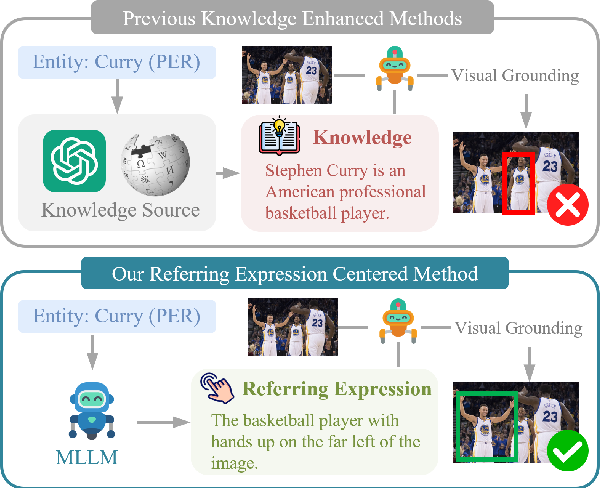
Figure 1 from ISR: Self-Refining Referring Expressions for Entity ...

Figure 1 from Referring Camouflaged Object Detection | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from Multi-Context Temporal Consistent Modeling for Referring ...
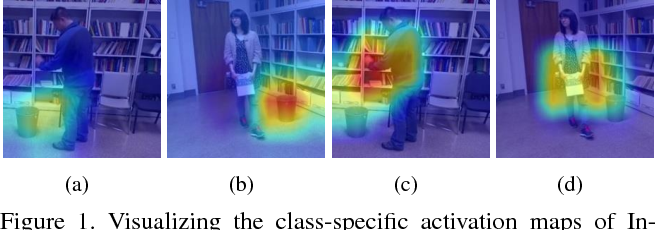
Figure 1 from Action Machine: Rethinking Action Recognition in Trimmed ...

Figure 1 from Recognizing action at a distance | Semantic Scholar
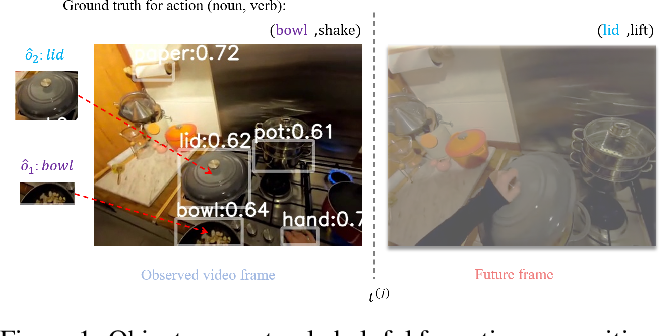
Figure 1 from Prompt-based Object-centric Video Representation for ...
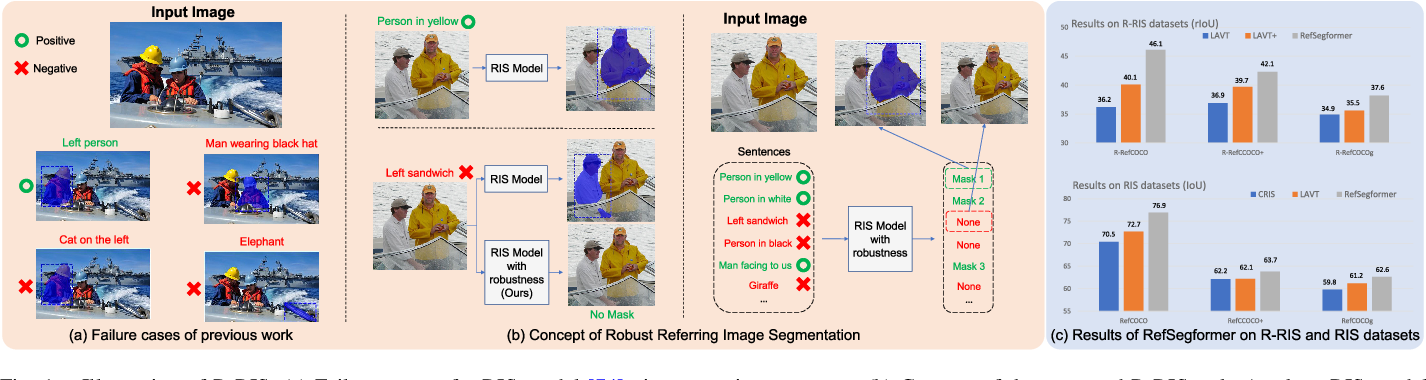
Figure 1 from Toward Robust Referring Image Segmentation | Semantic Scholar
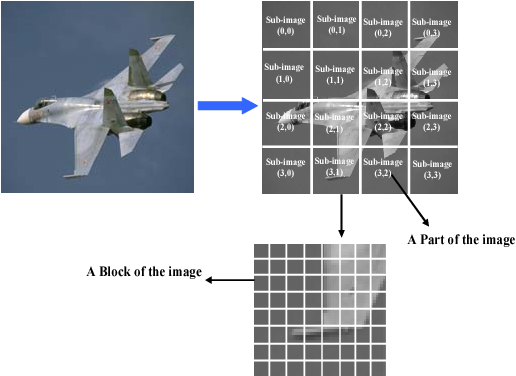
Figure 1 from A hardware acceleration of a real time video processing ...

Figure 1 from Boosting Weakly-Supervised Referring Image Segmentation ...
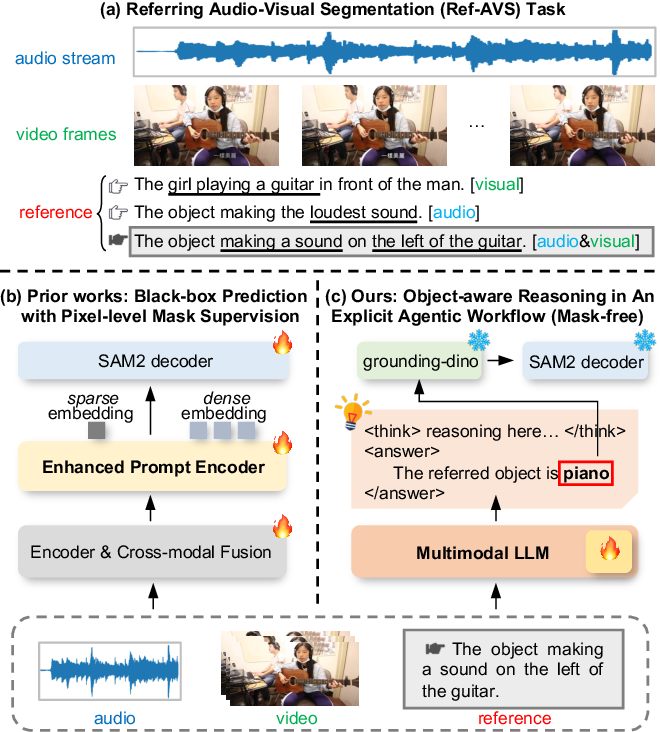
Figure 1 from Think Before You Segment: An Object-aware Reasoning Agent ...

Figure 1 from Actional Atomic-Concept Learning for Demystifying Vision ...
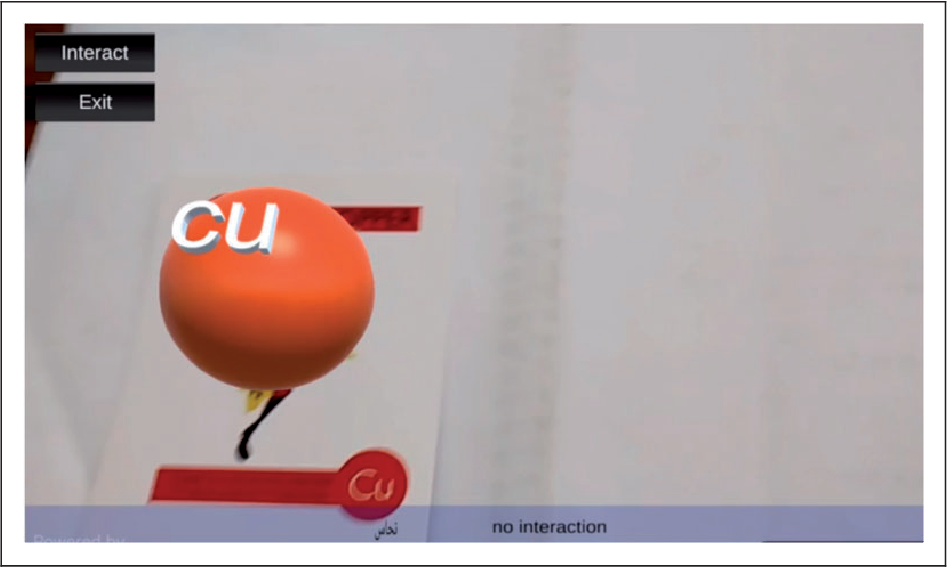
Figure 1 from A Usability and Acceptance Evaluation of the Use of ...
Advertisement Space (336x280)
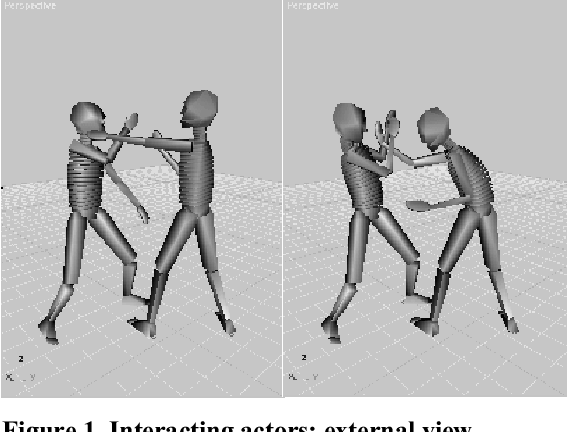
Figure 1 from A more realistic action-reaction model for virtual ...
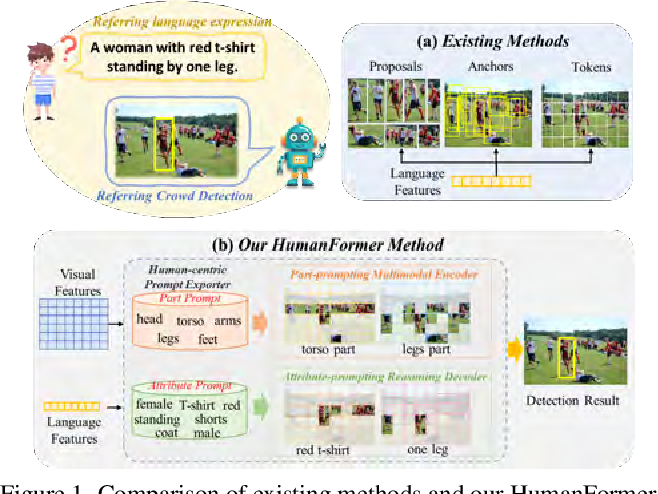
Figure 1 from HumanFormer: Human-centric Prompting Multi-modal ...
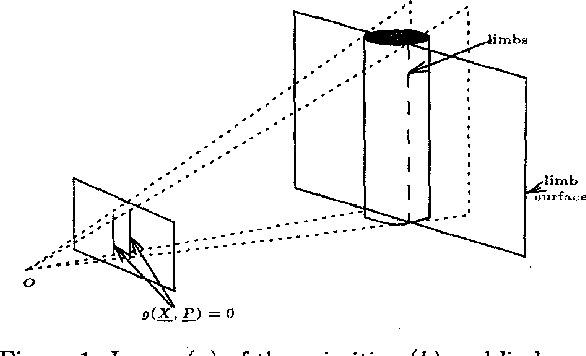
Figure 1 from Real time active visual reconstruction using the ...
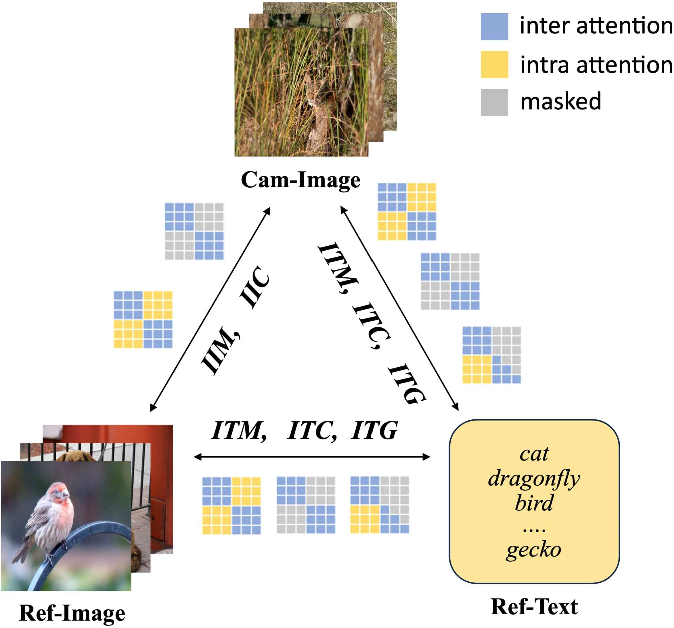
Figure 3 from Leveraging Multimodal Large Language Models for Referring ...

Figure 1 from Bidirectional Correlation-Driven Inter-Frame Interaction ...
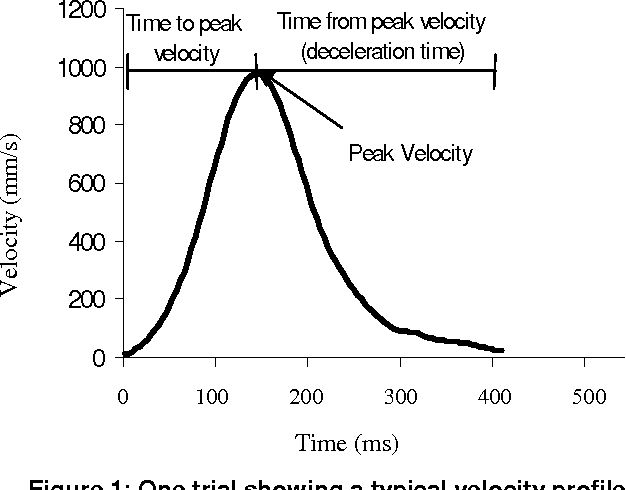
Figure 1 from Reaching movements to augmented and graphic objects in ...