
Figure 1 From Rethinking Amodal Video Segmentation From Learning
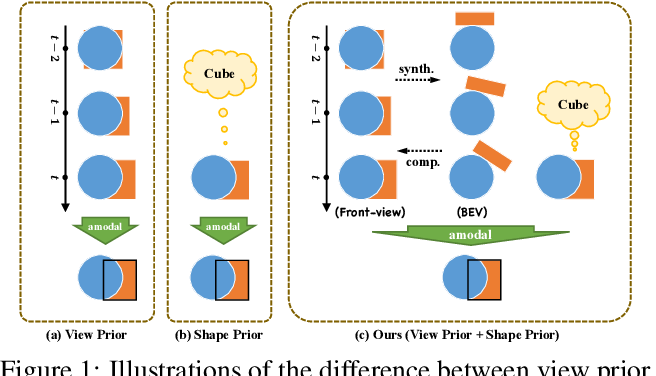
Figure 1 from Rethinking Amodal Video Segmentation from Learning ...

Figure 1 from Rethinking Amodal Video Segmentation from Learning ...

Figure 1 from End-to-end Amodal Video Instance Segmentation | Semantic ...

Paper page - Rethinking Amodal Video Segmentation from Learning ...

[2309.13248] Rethinking Amodal Video Segmentation from Learning ...

Figure 1 from Learning Video Object Segmentation From Unlabeled Videos ...

Figure 1 from Self-supervised Amodal Video Object Segmentation ...

Rethinking Amodal Video Segmentation from Learning Supervised Signals ...

Figure 1 from pix2gestalt: Amodal Segmentation by Synthesizing Wholes ...

Figure 1 from AISFormer: Amodal Instance Segmentation with Transformer ...
Advertisement Space (300x250)

Figure 1 from Semantic Amodal Segmentation | Semantic Scholar

Figure 1 from Elevating Amodal Segmentation Using ASH-Net Architecture ...

Figure 1 from Amodal Instance Segmentation With KINS Dataset | Semantic ...

Figure 1 from Elevating Amodal Segmentation Using ASH-Net Architecture ...
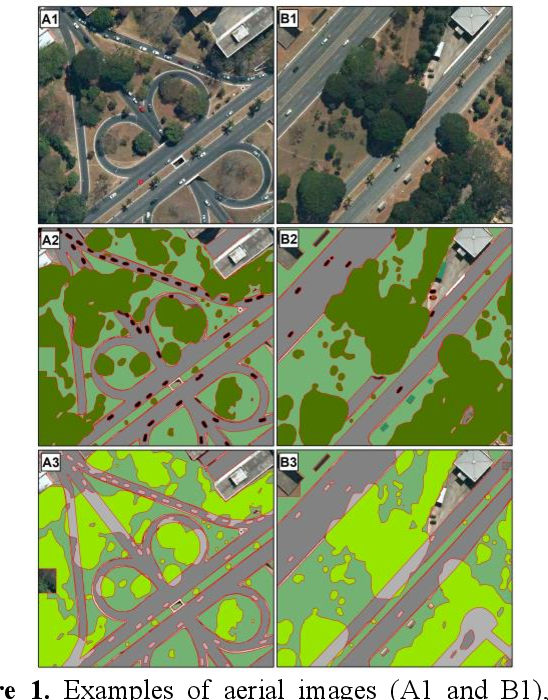
Figure 1 from Amodal Segmentation Considering Visible and Non-Visible ...
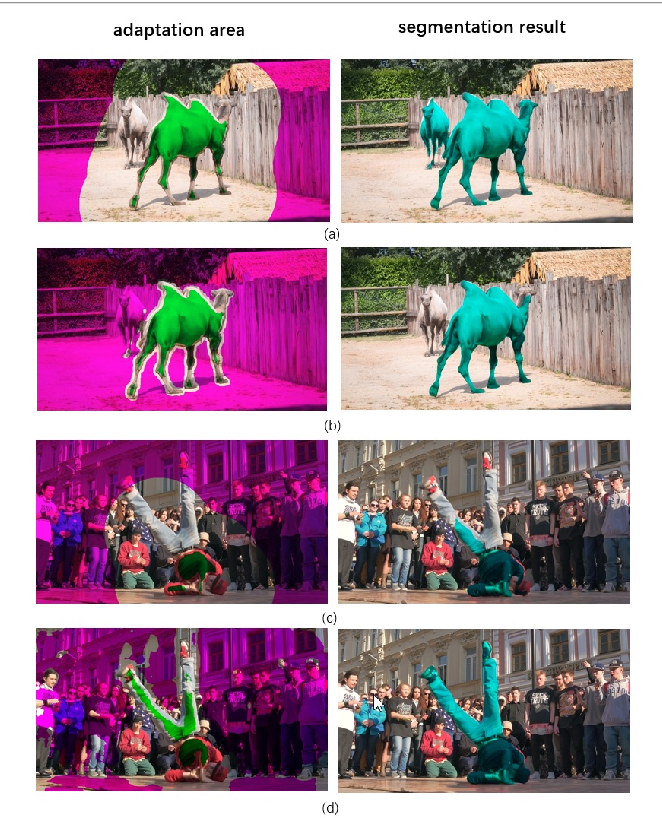
Figure 1 from Adaptive ROI Generation for Video Object Segmentation ...

Figure 1 from Rethinking Audiovisual Segmentation with Semantic ...

Figure 1 from Rethinking Boundary Detection in Deep Learning Models for ...
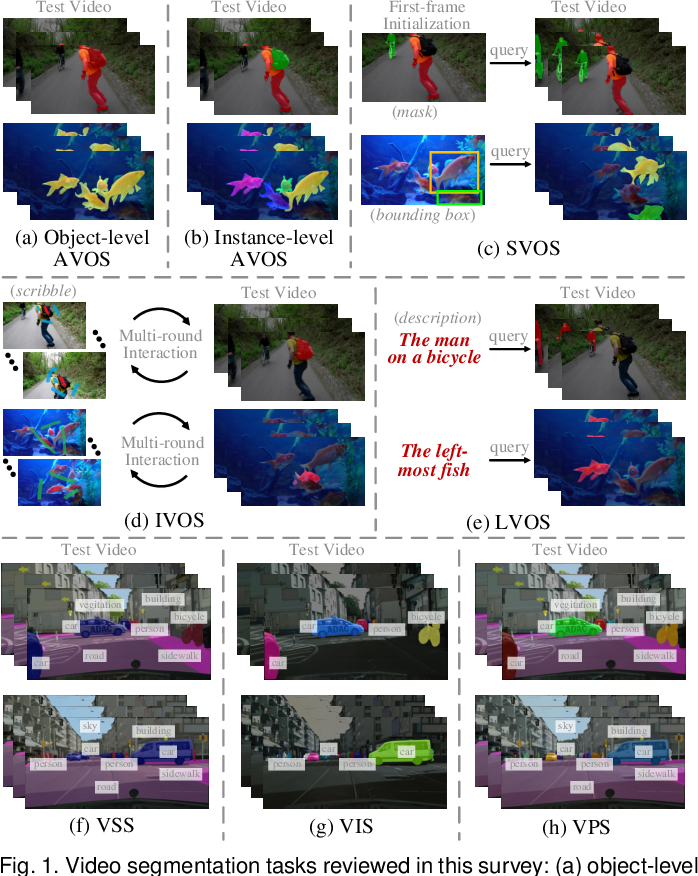
Figure 1 from A Survey on Deep Learning Technique for Video ...

Figure 1 from Self-Supervised Learning of Object Segmentation from ...
Advertisement Space (336x280)

Figure 1 from Coarse-to-Fine Amodal Segmentation with Shape Prior ...

Figure 1 from Learning Segmentation by Random Walks | Semantic Scholar

Figure 1 from Perceiving the Invisible: Proposal-Free Amodal Panoptic ...

Figure 1 from Learning Semantics-aware Distance Map with Semantics ...
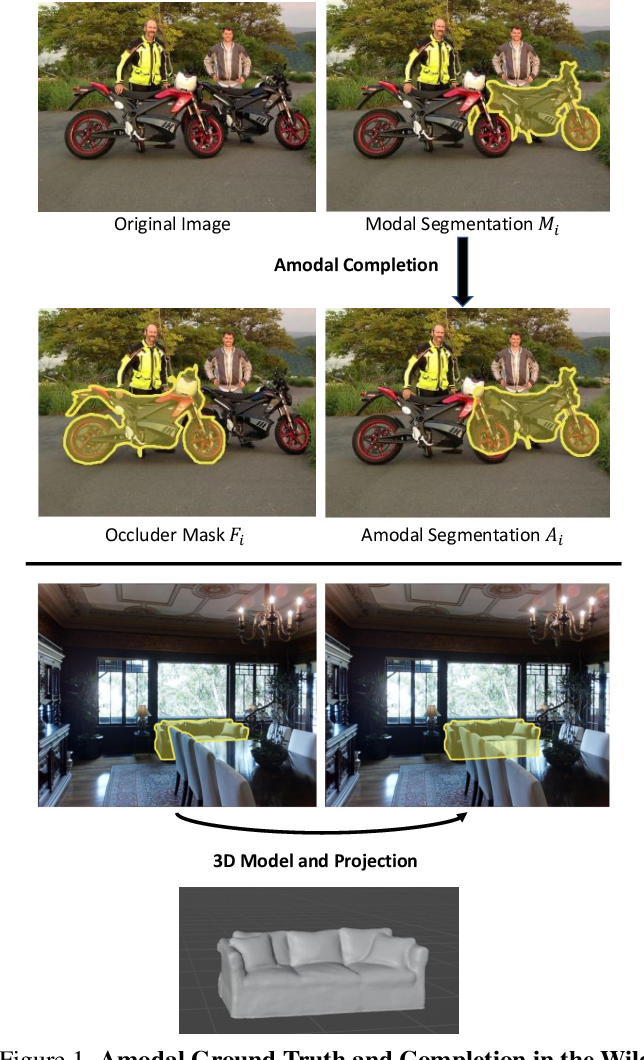
Figure 1 from Amodal Ground Truth and Completion in the Wild | Semantic ...

Figure 1 from Amodal Scene Analysis via Holistic Occlusion Relation ...

Figure 2 from AISFormer: Amodal Instance Segmentation with Transformer ...
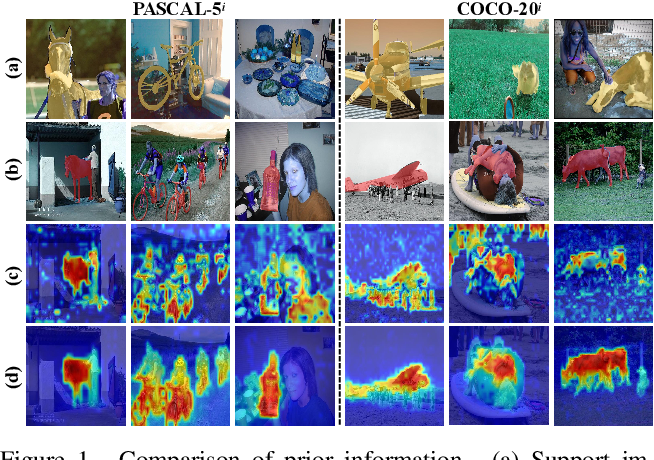
Figure 1 from Rethinking Prior Information Generation with CLIP for Few ...

Figure 1 from Rethinking Saliency-Guided Weakly-Supervised Semantic ...

Figure 1 from Rethinking local and global feature representation for ...
Advertisement Space (336x280)

Figure 1 from Amodal Scene Analysis via Holistic Occlusion Relation ...
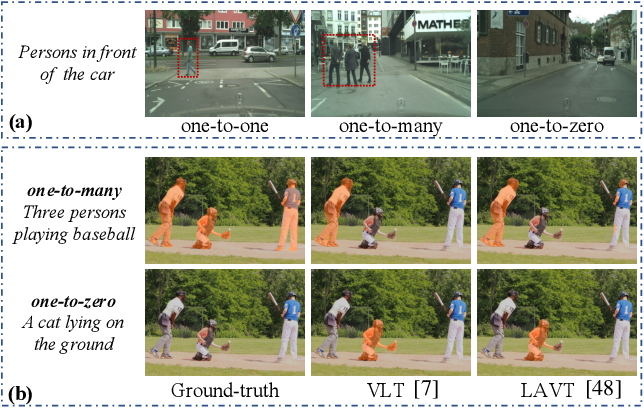
Figure 1 from Beyond One-to-One: Rethinking the Referring Image ...

Figure 3 from Elevating Amodal Segmentation Using ASH-Net Architecture ...

Figure 1 from Rethinking Two-Stage Referring Expression Comprehension ...
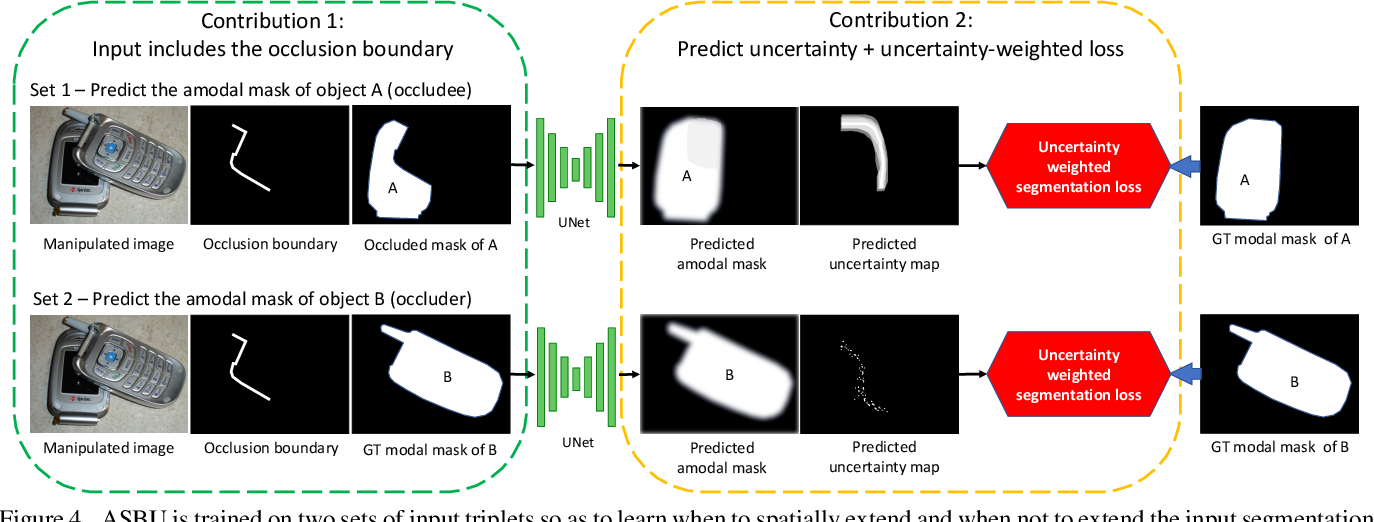
Figure 1 from A Weakly Supervised Amodal Segmenter with Boundary ...

Figure 5 from Learning Semantics-aware Distance Map with Semantics ...