
Figure 1 From Schnet Sam Marries Clip For Human Parsing Semantic Scholar
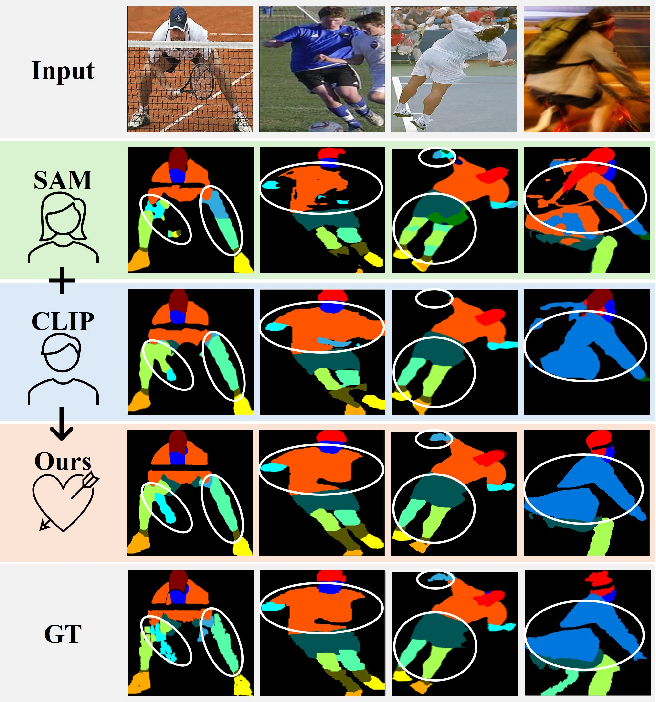
Figure 1 from SCHNet: SAM Marries CLIP for Human Parsing | Semantic Scholar

Figure 1 from Self-Correction for Human Parsing | Semantic Scholar

Figure 1 from Self-supervised human semantic parsing for video-based ...
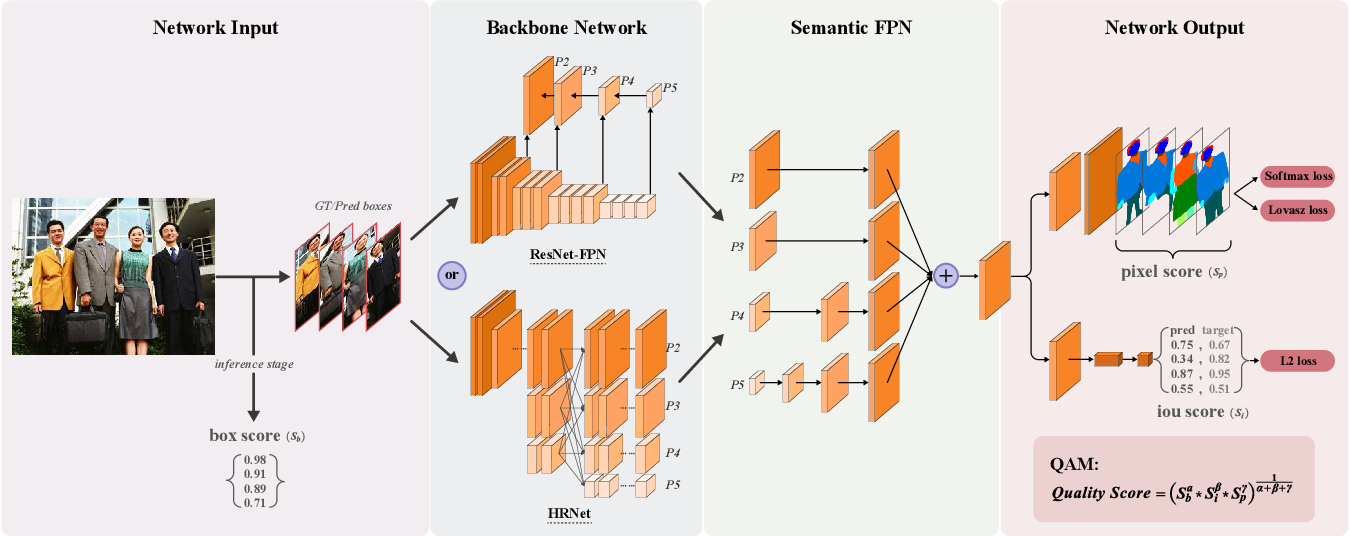
Figure 1 from Quality-Aware Network for Face Parsing | Semantic Scholar
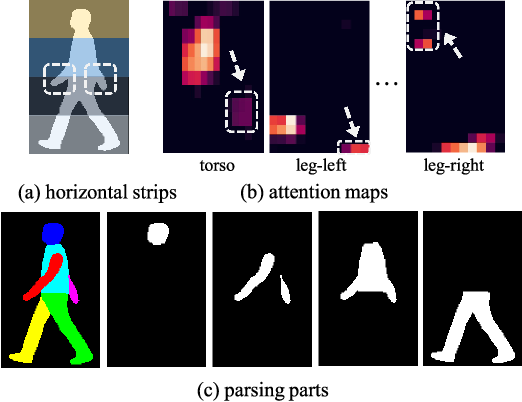
Figure 1 from GaitParsing: Human Semantic Parsing for Gait Recognition ...
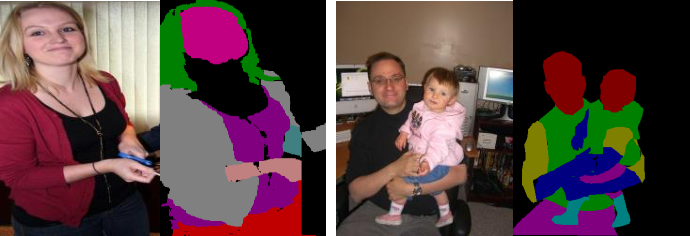
Figure 1 from Deep Learning for Human Parsing: A Survey | Semantic Scholar

Figure 1 from Integrating Human Parsing and Pose Network for Human ...

Figure 1 from Attention Guided Semantic Relationship Parsing for Visual ...
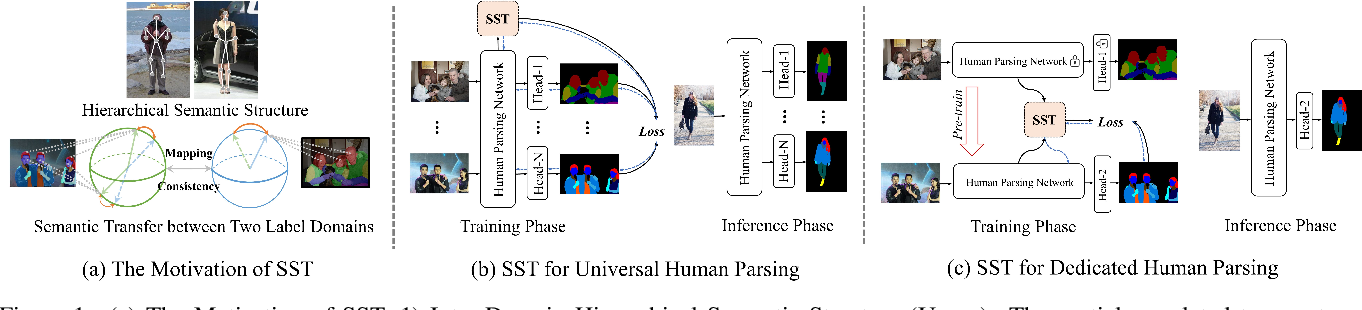
Figure 1 from Semantic Human Parsing via Scalable Semantic Transfer ...

Figure 1 from Knowledge Informed Semantic Parsing for Conversational ...
Advertisement Space (300x250)

Figure 1 from Integrating Human Parsing and Pose Network for Human ...

Figure 1 from Error Detection for Text-to-SQL Semantic Parsing ...

Figure 1 from Semantic Parsing for Question Answering over Knowledge ...
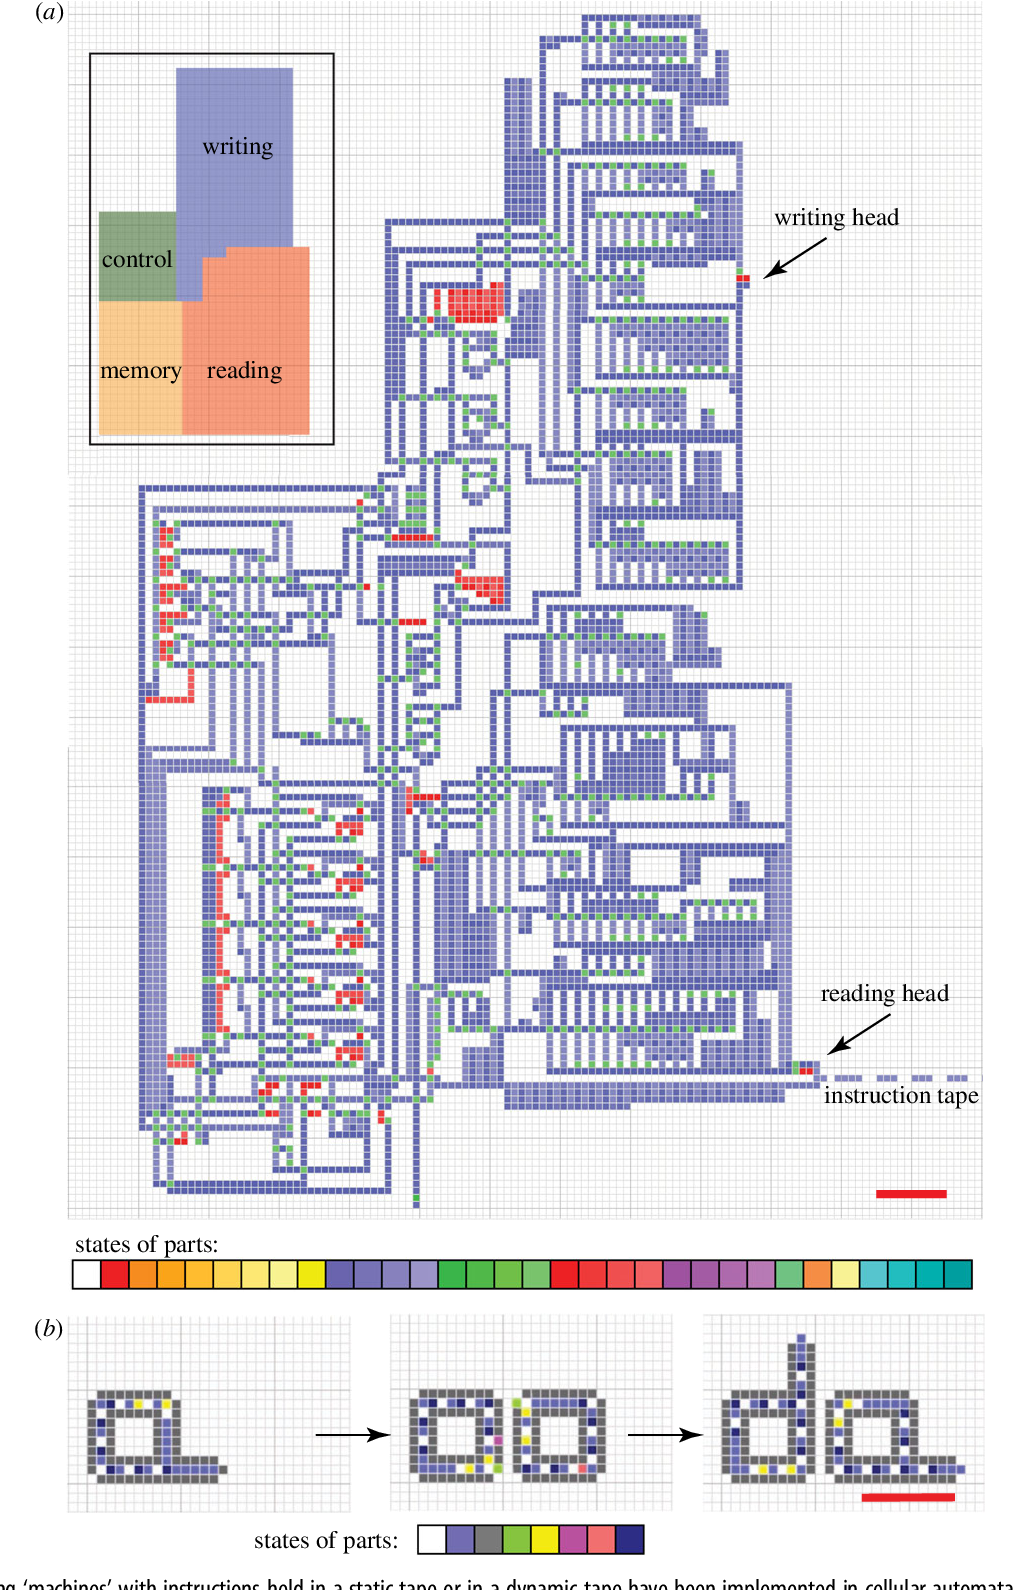
Figure 1 from A framework for parsing heritable information | Semantic ...
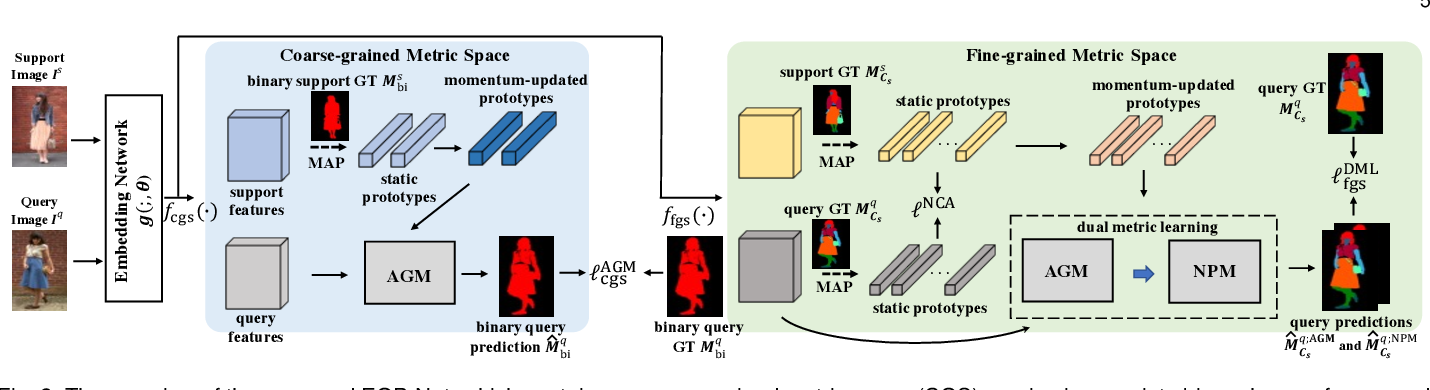
Figure 2 from End-to-End One-Shot Human Parsing | Semantic Scholar

Figure 1 from Integrating Human Parsing and Pose Network for Human ...

Figure 1 from Semantic Dependency Parsing with Edge GNNs | Semantic Scholar

Figure 1 from Span-Based LCFRS-2 Parsing | Semantic Scholar
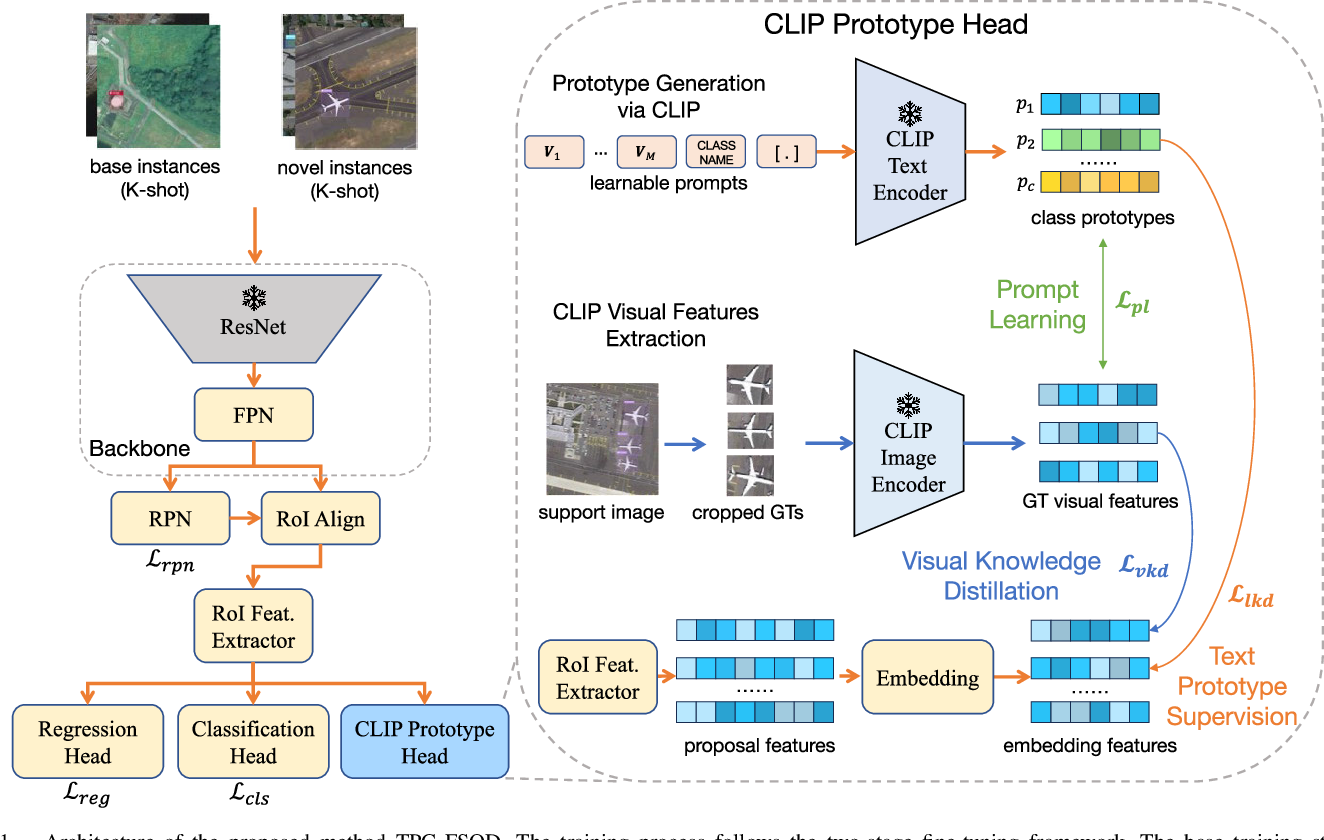
Figure 1 from Semantic Prototyping With CLIP for Few-Shot Object ...

Figure 1 from Parsing – A Brief Study | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from Rethinking Semantic Parsing for Large Language Models ...

Figure 1 from Cross-domain Generalization for AMR Parsing | Semantic ...
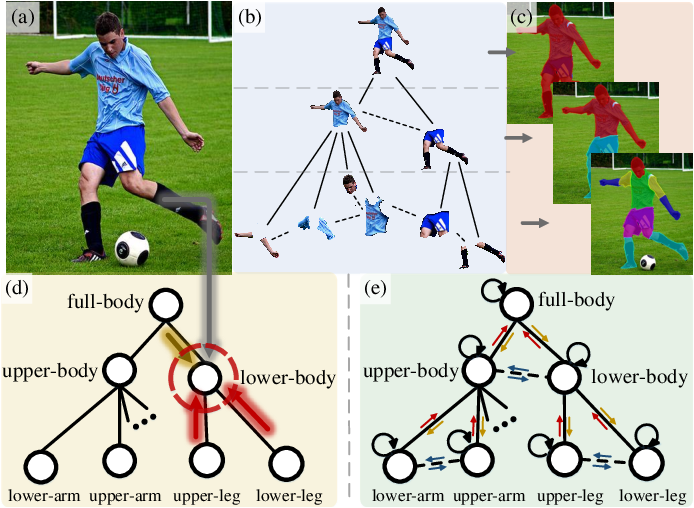
Figure 1 from Hierarchical Human Semantic Parsing With Comprehensive ...

Figure 3 from Self-supervised human semantic parsing for video-based ...

Figure 1 from Generative Alignment and Semantic Parsing for Learning ...
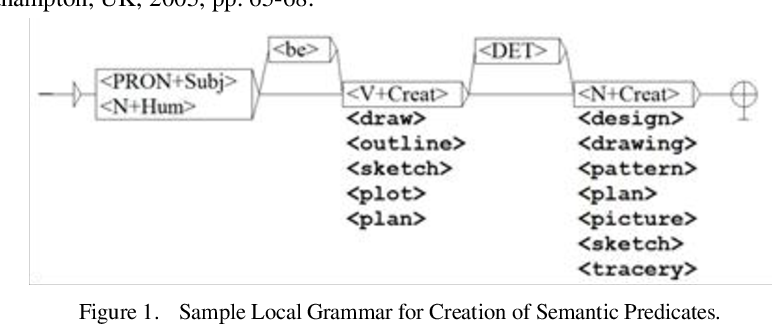
Figure 1 from A Semantic Annotation Model for Syntactic Parsing in ...
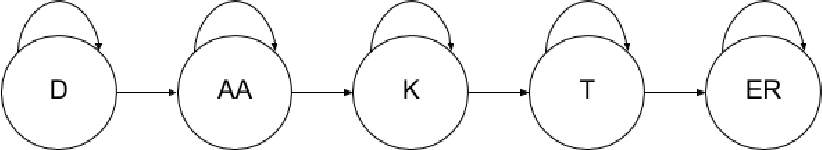
Figure 1 from An Analysis of Using Semantic Parsing for Speech ...

Figure 2 from Self-supervised human semantic parsing for video-based ...

Figure 1 from RepParser: End-to-End Multiple Human Parsing with ...

Figure 1 from Cross-domain Human Parsing via Adversarial Feature and ...
Advertisement Space (336x280)
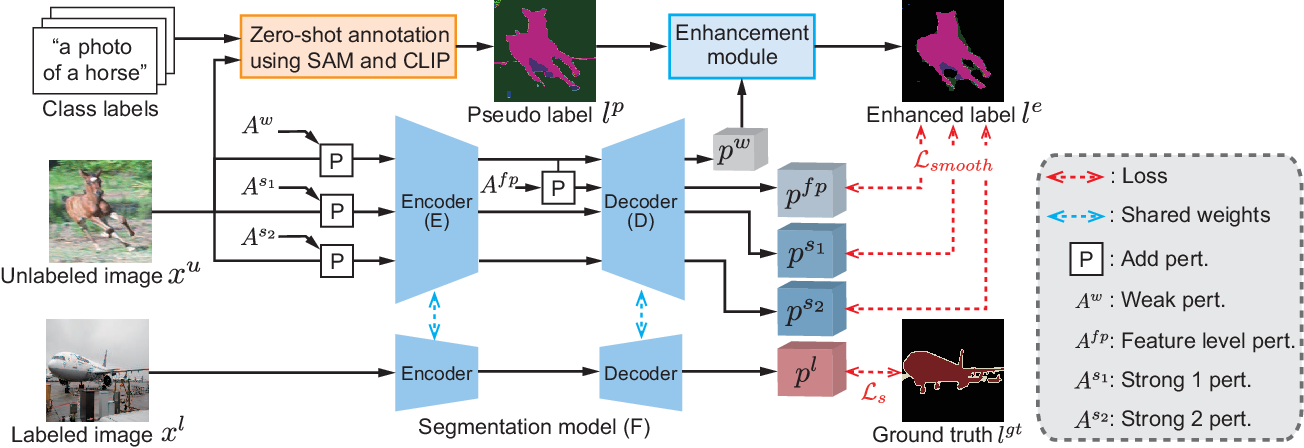
Figure 2 from Zero-Shot Pseudo Labels Generation Using SAM and CLIP for ...

Figure 1 from Segment and Caption Anything | Semantic Scholar
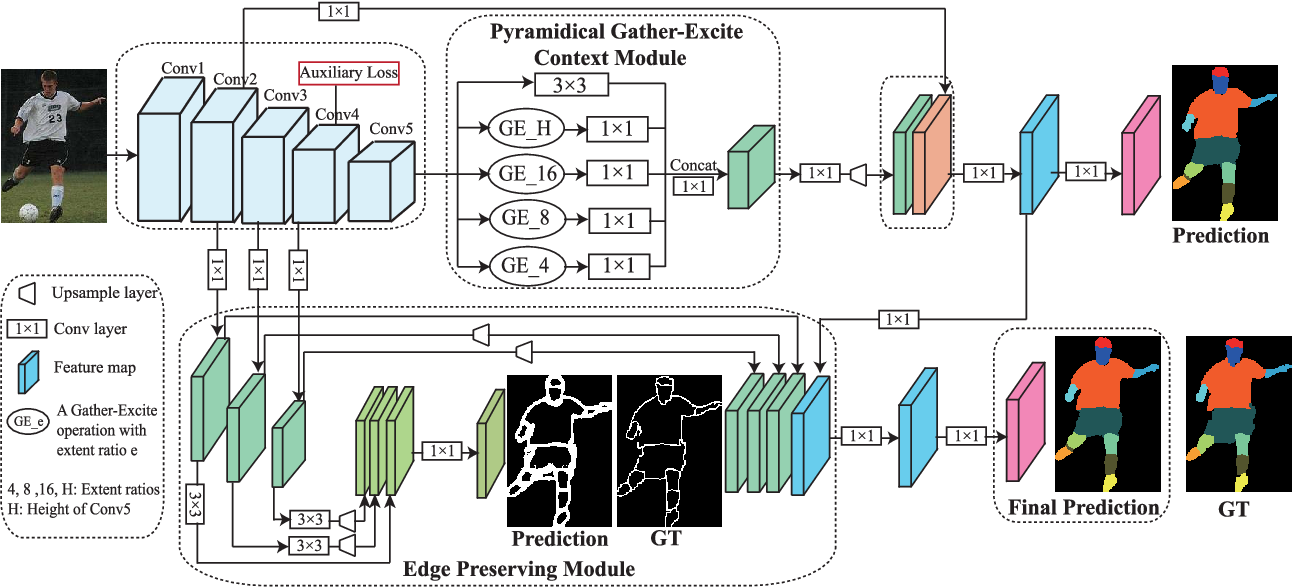
Figure 1 from Human Parsing With Pyramidical Gather-Excite Context ...

Figure 1 from Toward Accurate Human Parsing Through Edge Guided ...

Figure 1 from Weakly and Semi Supervised Human Body Part Parsing via ...
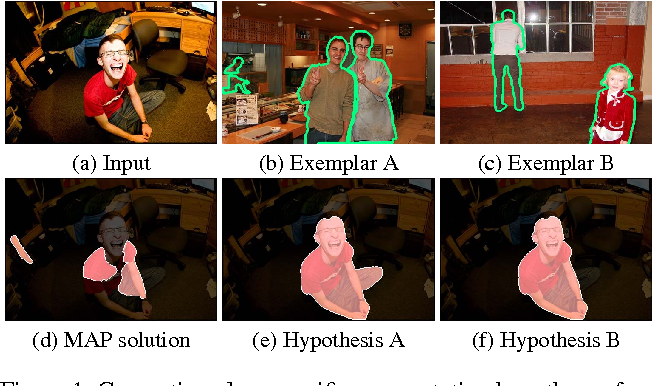
Figure 1 from Exemplar Cut | Semantic Scholar