
Figure 1 From Single Channel Target Speaker Extraction Based On Deep

Figure 1 from Single Channel Target Speaker Extraction Based on Deep ...

Figure 1 from Deep Ad-hoc Beamforming Based on Speaker Extraction for ...

Figure 1 from Coarse-to-Fine Target Speaker Extraction Based on ...
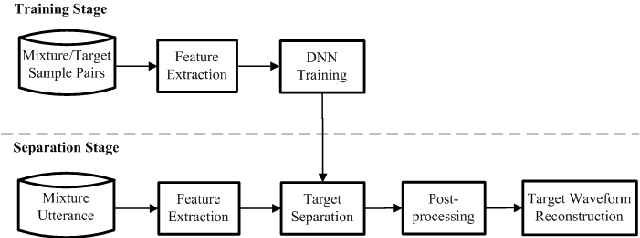
Figure 1 from Speech separation of a target speaker based on deep ...

Figure 3 from Single Channel Target Speaker Extraction and Recognition ...
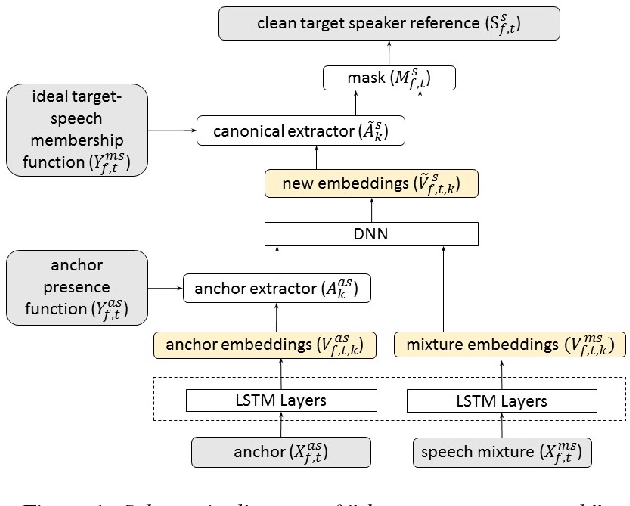
Figure 1 from Deep Extractor Network for Target Speaker Recovery From ...
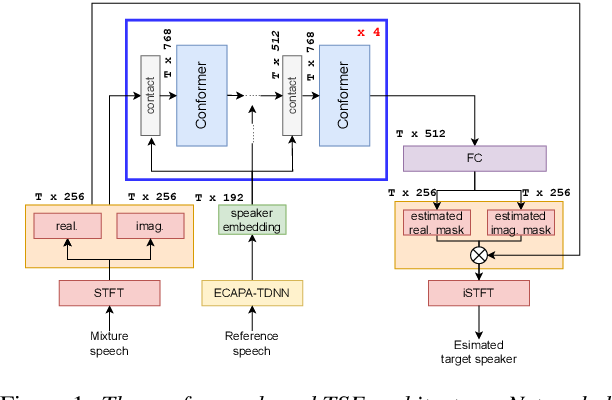
Figure 1 from Target Speaker Extraction with Curriculum Learning ...
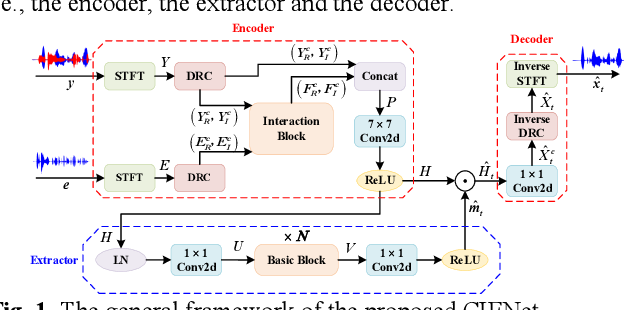
Figure 1 from Target Speaker Extraction by Directly Exploiting ...

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...
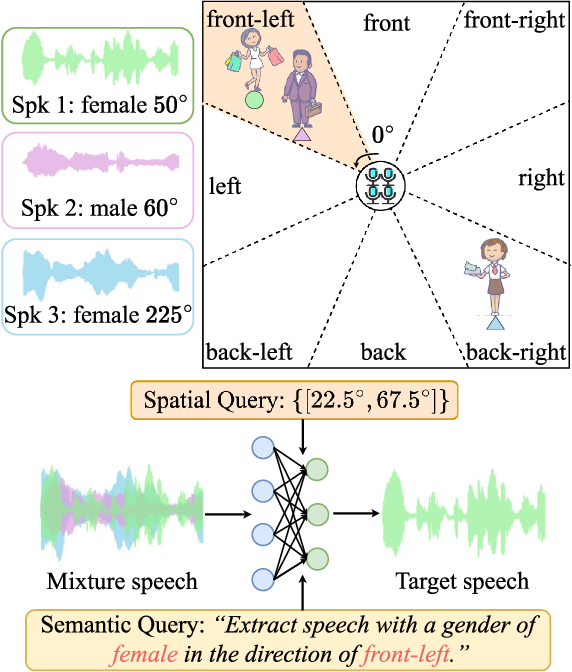
Figure 1 from SSDQ: Target Speaker Extraction via Semantic and Spatial ...
Advertisement Space (300x250)
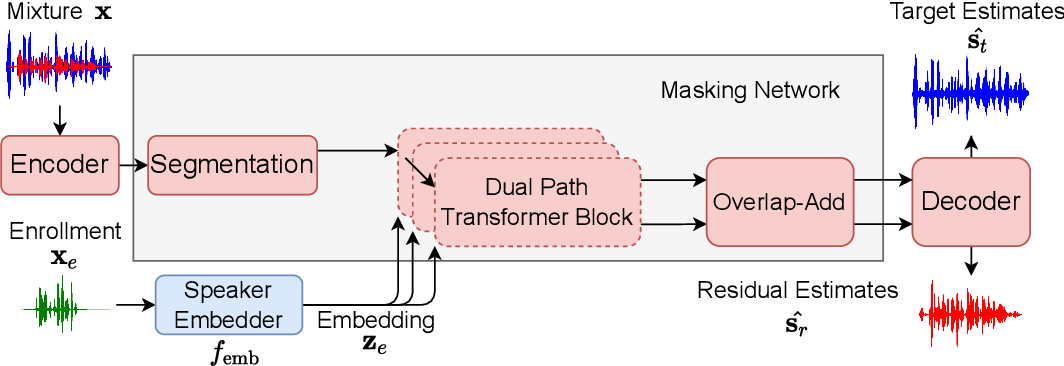
Figure 1 from Semi-supervised Time Domain Target Speaker Extraction ...

Figure 1 from Binaural Target Speaker Extraction using Individualized ...

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...

Figure 1 from Deep Learning Based Target Cancellation for Speech ...

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...

Figure 1 from SMMA-Net: An Audio Clue-Based Target Speaker Extraction ...

Figure 1 from Target Speaker Extraction by Directly Exploiting ...

Figure 1 from Target Speaker Extraction for Multi-Talker Speaker ...
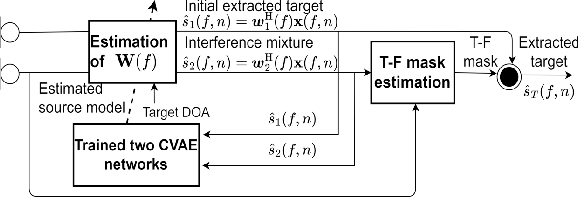
Figure 1 from Directional Target Speaker Extraction under Noisy ...
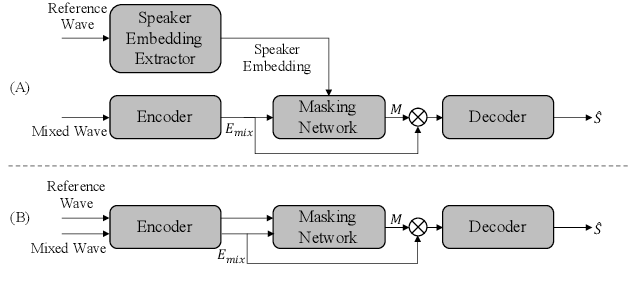
Figure 1 from SEF-Net: Speaker Embedding Free Target Speaker Extraction ...
Advertisement Space (336x280)

Figure 1 from Target Speaker Extraction with Attention Enhancement and ...
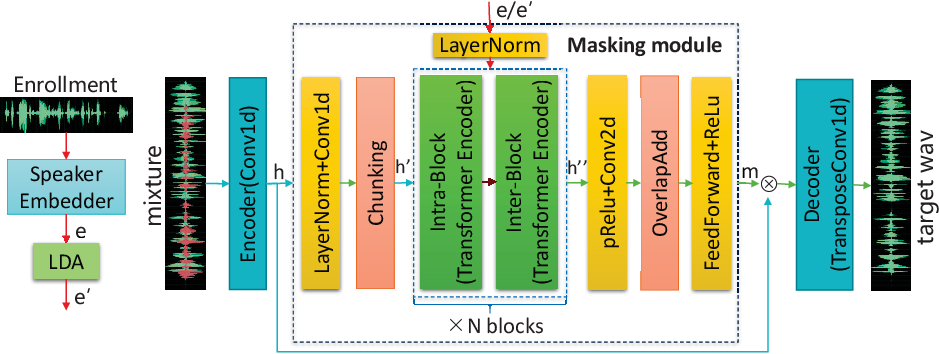
Figure 1 from Improving Target Speaker Extraction with Sparse LDA ...

Figure 1 from Speaker-conditioning Single-channel Target Speaker ...
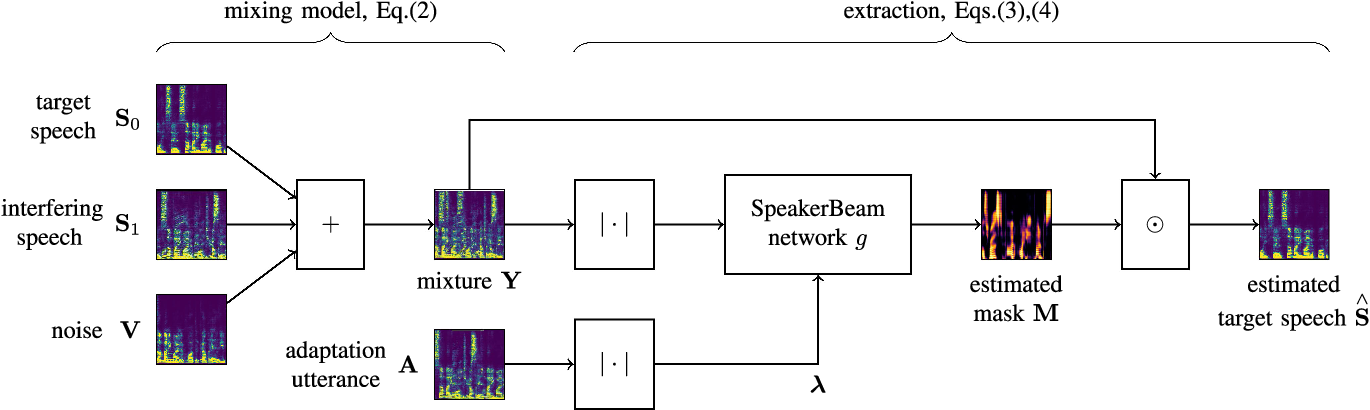
Figure 1 from SpeakerBeam: Speaker Aware Neural Network for Target ...

Figure 1 from Speaker-Aware Target Speaker Enhancement by Jointly ...

Figure 1 from Binaural Selective Attention Model for Target Speaker ...

Figure 1 from Single-Channel Target Speaker Separation Using Joint ...

Speaker-conditioned Target Speaker Extraction based on Customized LSTM ...
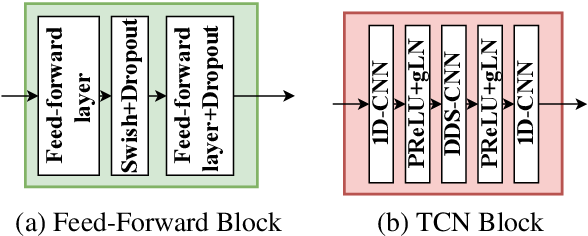
Figure 1 from Speaker-Conditioning Single-Channel Target Speaker ...
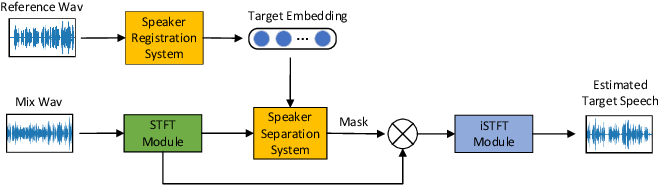
Figure 1 from A Target Speaker Separation Neural Network with Joint ...
Advertisement Space (336x280)

Figure 1 from Simultaneous Speech Extraction for Multiple Target ...

Figure 1 from Universal Speaker Extraction in the Presence and Absence ...

Figure 1 from Hierarchical Speaker Representation for Target Speaker ...
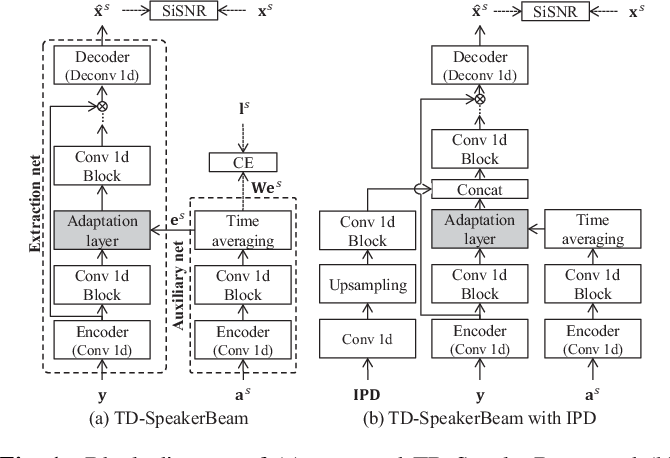
Figure 1 from Improving Speaker Discrimination of Target Speech ...

Figure 1 from Speaker Extraction with Detection of Presence and Absence ...

Figure 1 from Target Speaker Voice Activity Detection with Transformers ...