
Figure 1 From Speech Acoustic Modeling From Raw Multichannel Waveforms

Figure 1 from Speech acoustic modeling from raw multichannel waveforms ...
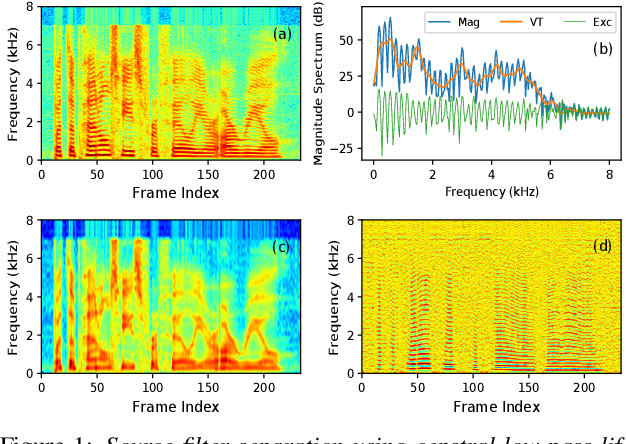
Figure 1 from Speech Acoustic Modelling Using Raw Source and Filter ...

Figure 1 from Acoustic Model Adaptation from Raw Waveforms with Sincnet ...
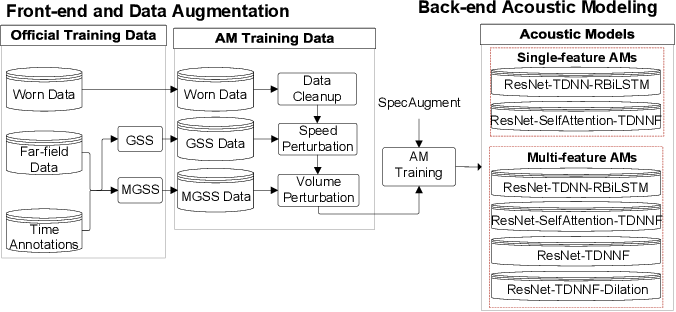
Figure 1 from Acoustic Modeling for Multi-Array Conversational Speech ...
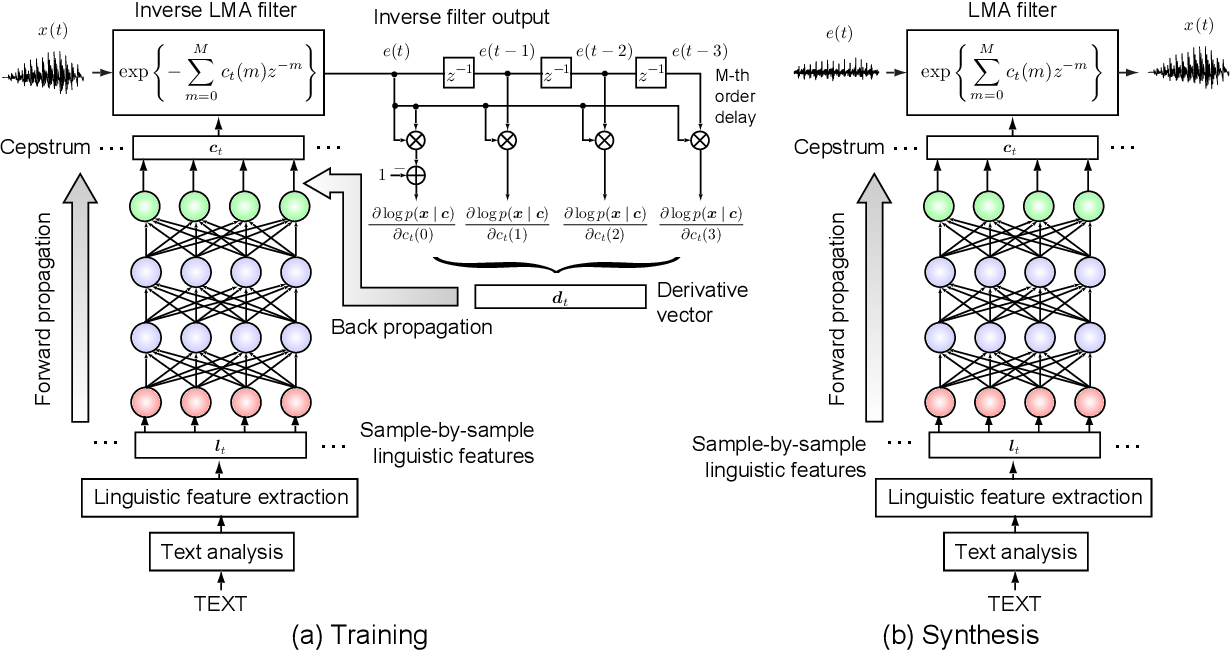
Figure 1 from Directly modeling speech waveforms by neural networks for ...
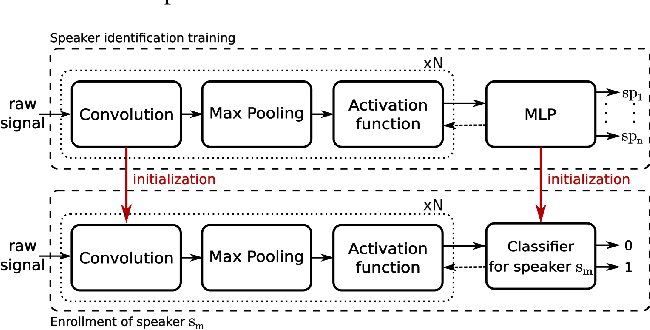
Figure 1 from Towards Directly Modeling Raw Speech Signal for Speaker ...
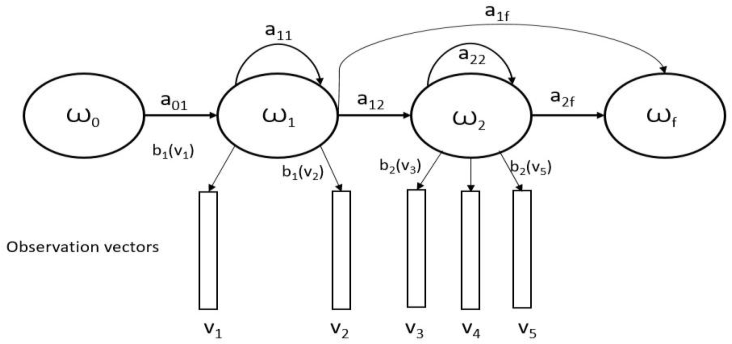
Figure 1 from Acoustic modeling in Automatic Speech Recognition - A ...

Figure 1 from Acoustic Modelling From Raw Source and Filter Components ...
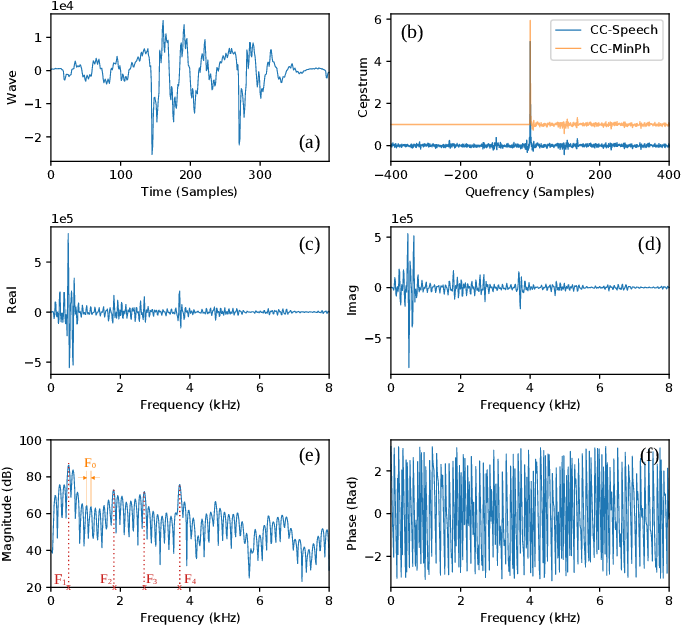
Figure 1 from Multi-Stream Acoustic Modelling Using Raw Real and ...

Figure 1 from Sequence-to-Sequence Acoustic Modeling with Semi-Stepwise ...
Advertisement Space (300x250)

Figure 1 from Hybrid acoustic models for distant and multichannel large ...

Figure 1 from Multichannel Speech Enhancement Without Beamforming ...
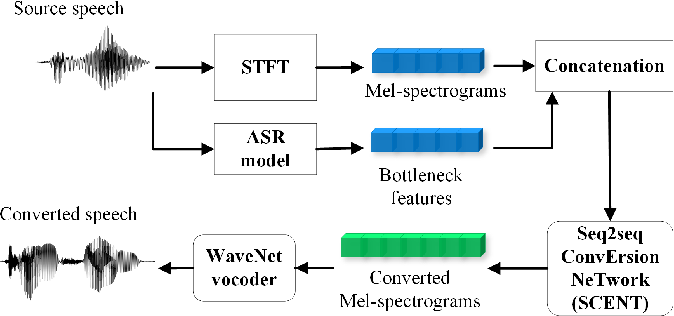
Figure 1 from Sequence-to-Sequence Acoustic Modeling for Voice ...

Figure 1 from Learning Acoustic Features from the Raw Waveform for ...
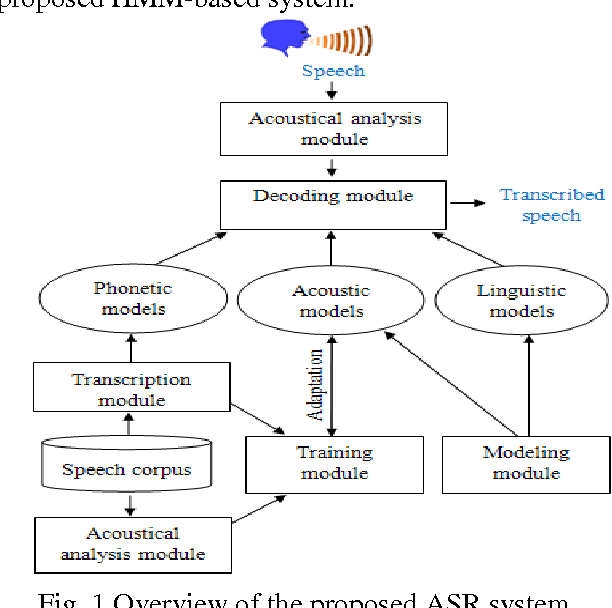
Figure 1 from Study of acoustic analysis and modeling for Automatic ...
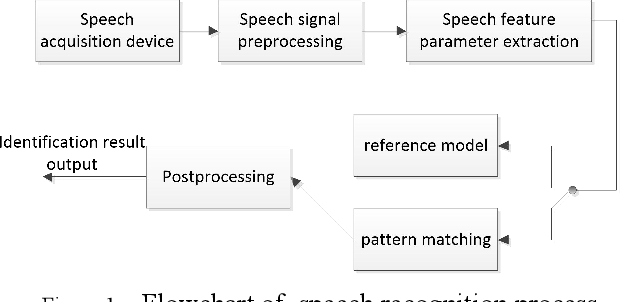
Figure 1 from An Acoustic Model for English Speech Recognition Based on ...
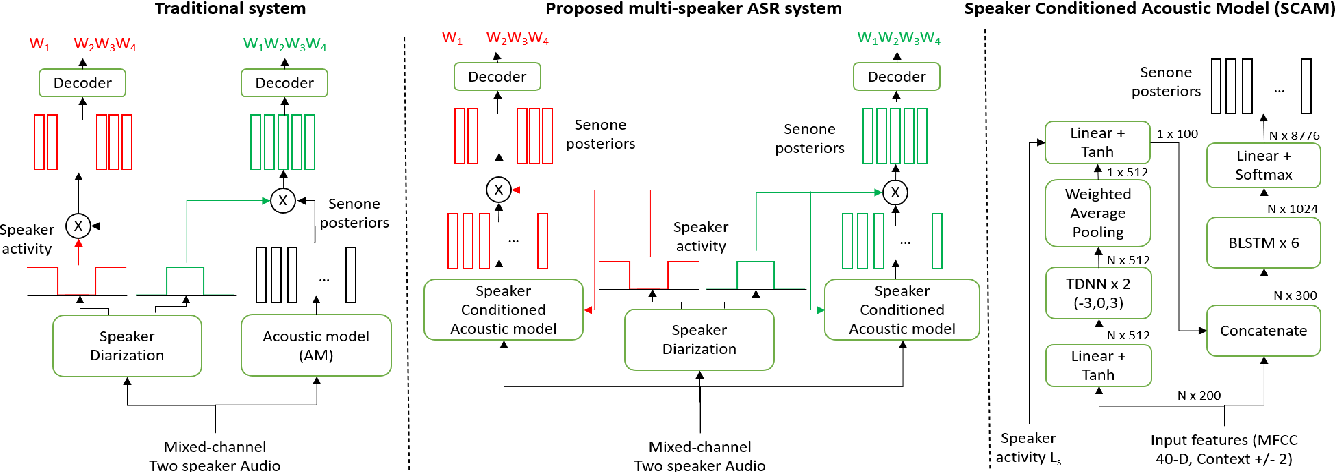
Figure 1 from Speaker conditioned acoustic modeling for multi-speaker ...

Figure 1 from Raw waveform-based speech enhancement by fully ...
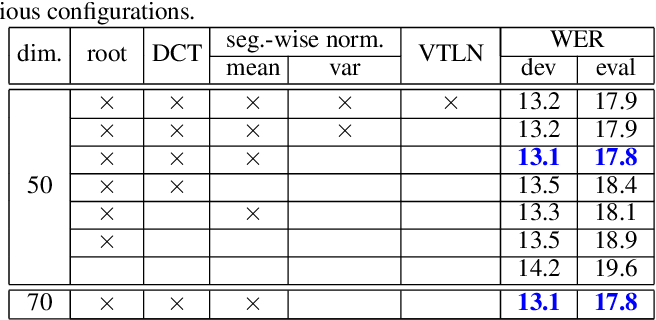
Table 1 from Acoustic Modeling of Speech Waveform Based on Multi ...

Figure 1 from Acoustic modeling with a shared phoneme set for ...
Advertisement Space (336x280)

Figure 1 from MAM: Masked Acoustic Modeling for End-to-End Speech-to ...
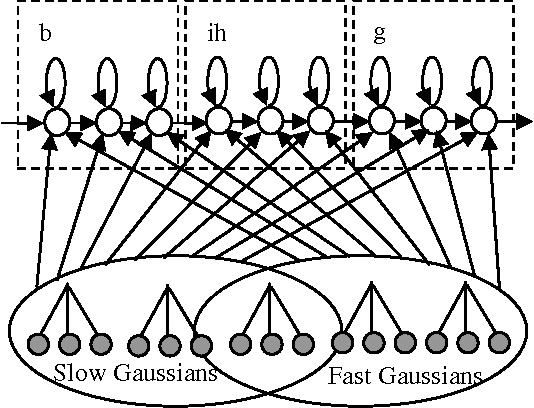
Figure 1 from Effective acoustic modeling for rate-of-speech variation ...
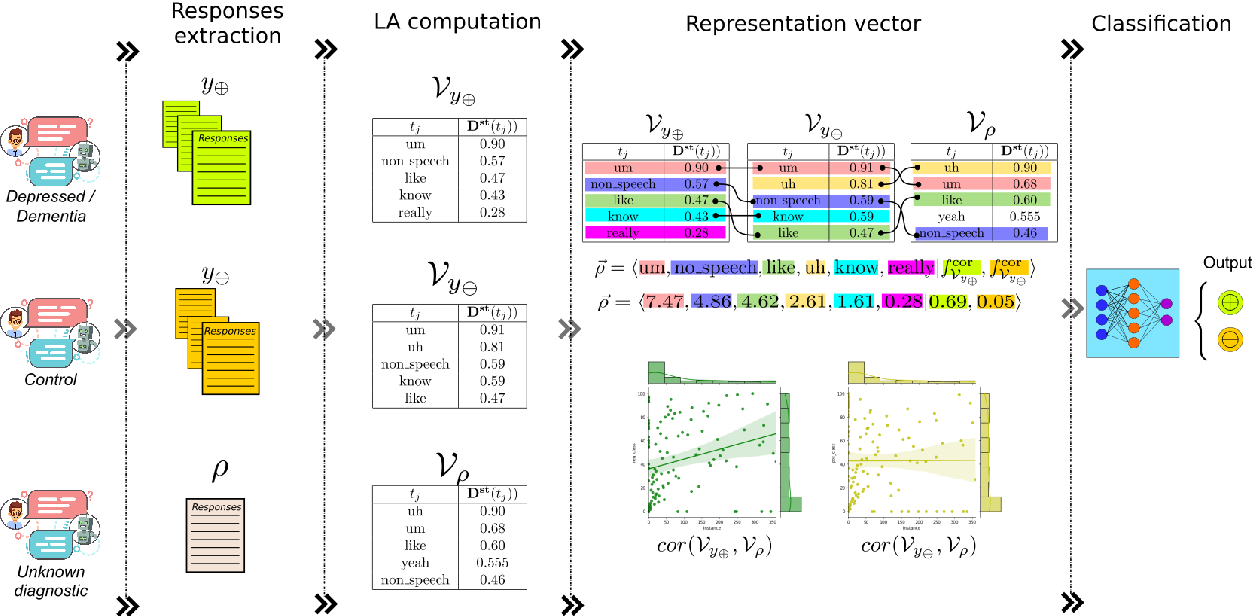
Figure 1 from Late Fusion of the Available Lexicon and Raw Waveform ...
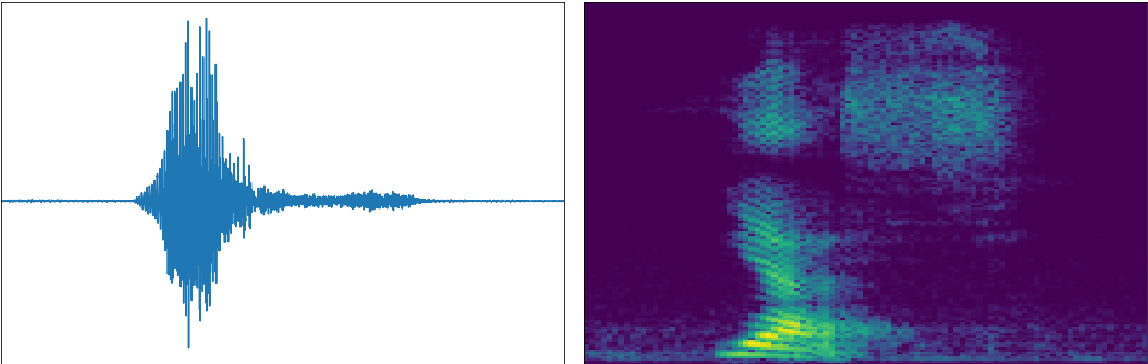
Figure 1 from Single-word speech recognition with Convolutional Neural ...
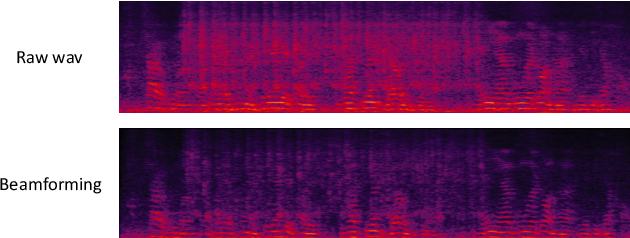
Figure 1 from Real-Time Multi-Channel Speech Enhancement Based on ...
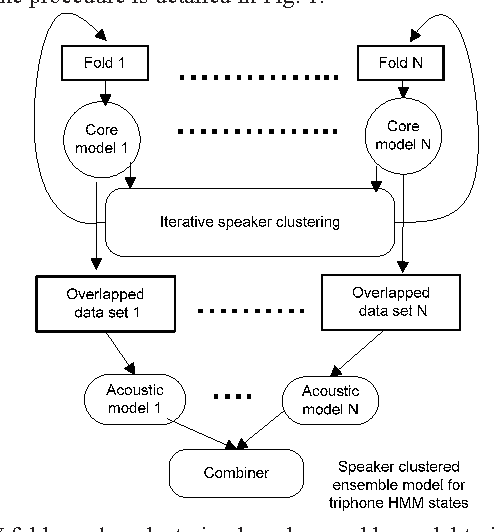
Figure 1 from Data sampling ensemble acoustic modelling in speaker ...

Figure 1 from Multimodal Speaker Adaptation of Acoustic Model and ...

Figure 1 from Raw Waveform Based Speaker Identification Using Deep ...

Figure 1 from Robust speech recognition using beamforming with adaptive ...

Figure 1 from Jointly Learning Visual and Auditory Speech ...
Advertisement Space (336x280)
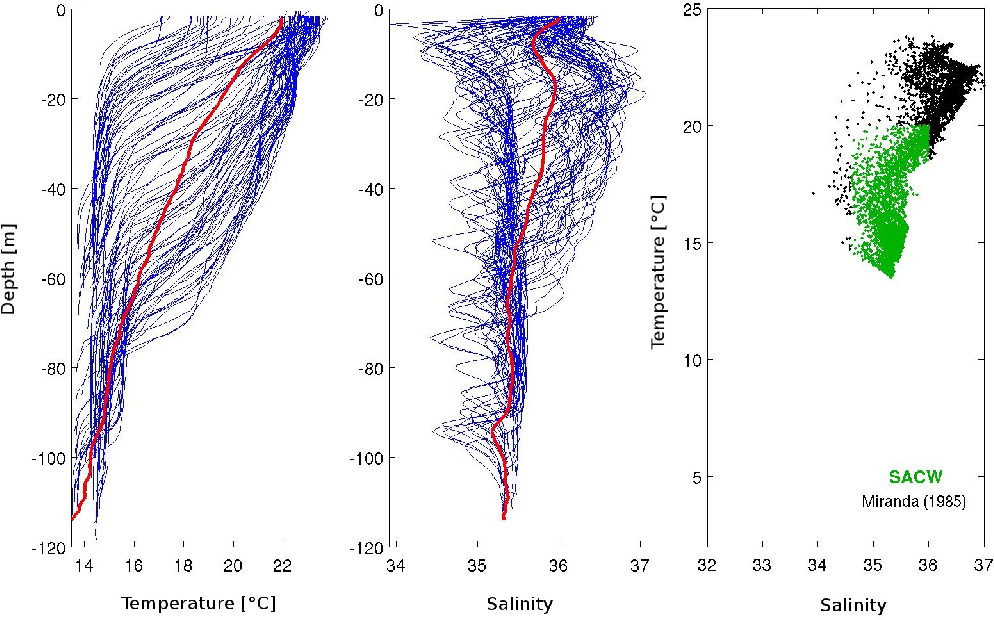
Figure 1 from Acoustic prediction using a feature-oriented regional ...

Figure 1 from Self-Supervised Learning with Multi-Target Contrastive ...
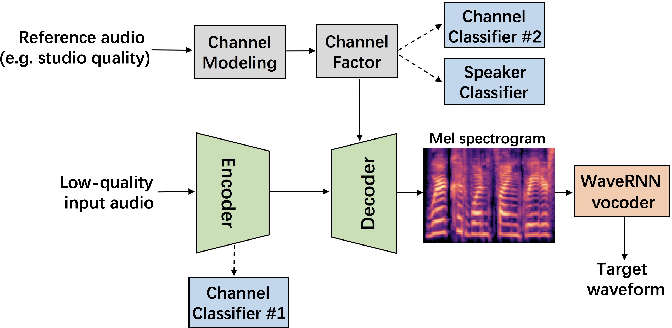
Figure 1 from Enhancing Low-Quality Voice Recordings Using Disentangled ...

Structure of the model with acoustic features from speech data ...
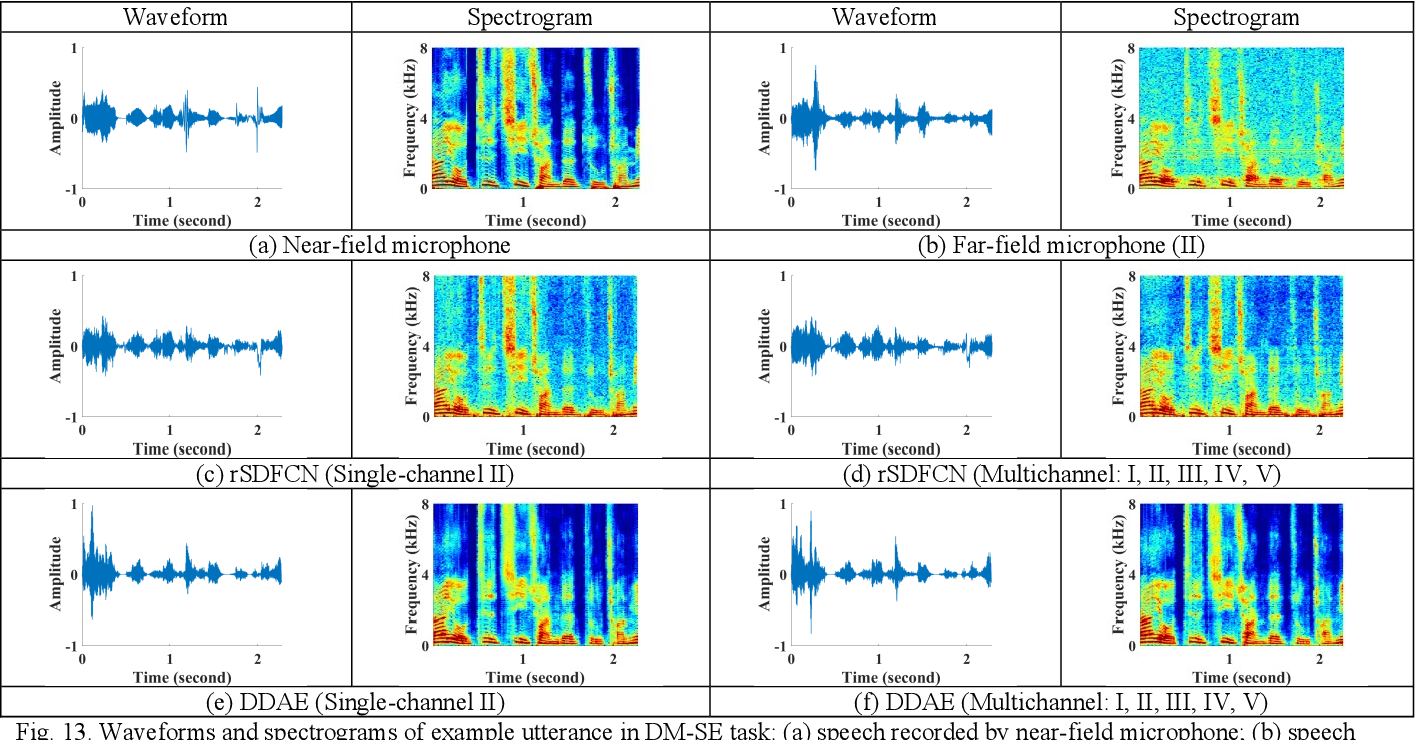
Multichannel Speech Enhancement by Raw Waveform-mapping using Fully ...

(PDF) Multichannel Speech Enhancement by Raw Waveform-mapping using ...