
Figure 1 From Speech Segmentation Without Speech Recognition Semantic
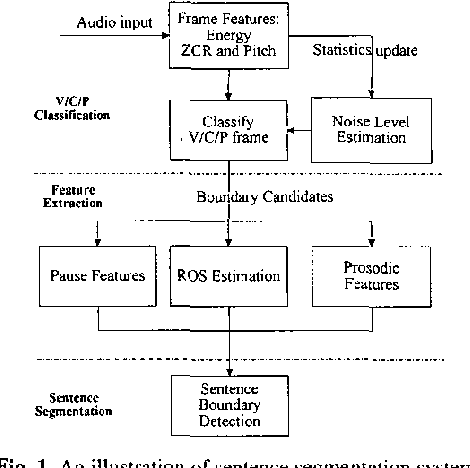
Figure 1 from Speech segmentation without speech recognition | Semantic ...

Figure 1 from Persian speech sentence segmentation without speech ...

Figure 1 from Speech Synthesis - Automatic Segmentation | Semantic Scholar
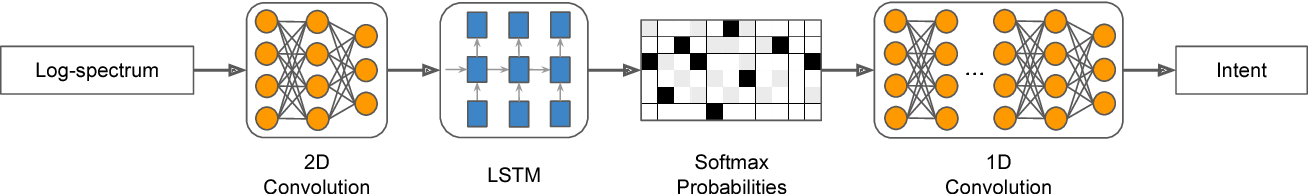
Figure 1 from Spoken Language Understanding without Speech Recognition ...

Figure 1 from Overview and Analysis of Speech Recognition | Semantic ...
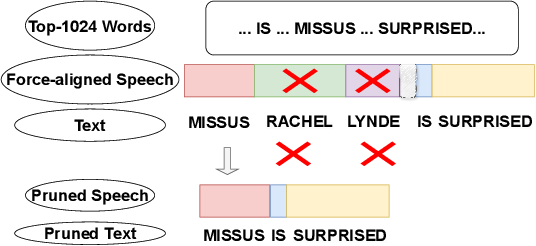
Figure 1 from Towards Unsupervised Speech Recognition Without ...
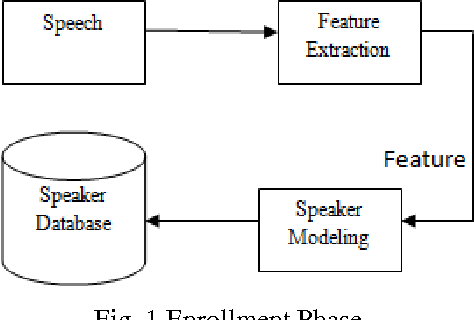
Figure 1 from A Survey on Speech Recognition Algorithms | Semantic Scholar

Figure 1 from Visual speech segmentation and speaker recognition for ...
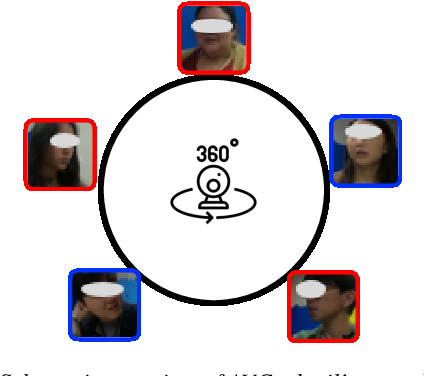
Figure 1 from Cocktail-Party Audio-Visual Speech Recognition | Semantic ...
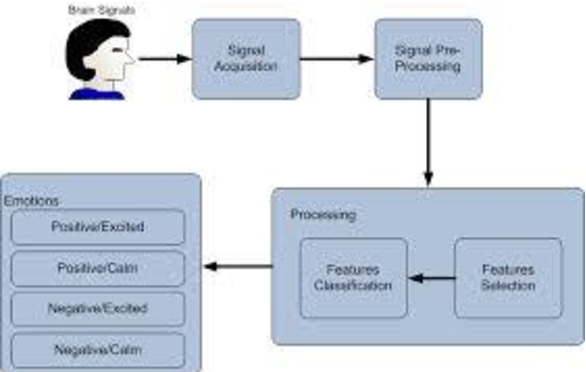
Figure 1 from Speech Emotion Recognition | Semantic Scholar
Advertisement Space (300x250)

Figure 1 from A method of multi-layered speech segmentation tailored ...

Figure 1 from Unsupervised Quasi-Silence based Speech Segmentation for ...

Figure 1 from Unsupervised Audio Speech Segmentation Using the Voting ...

Figure 1 from StableToken: A Noise-Robust Semantic Speech Tokenizer for ...

Figure 1 from End-to-end model for named entity recognition from speech ...
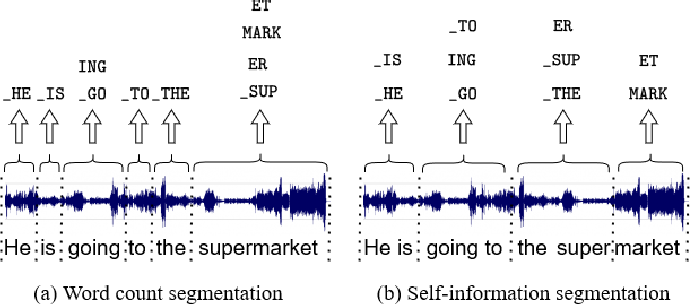
Figure 1 from Self-Information Guided Speech Segmentation for Efficient ...
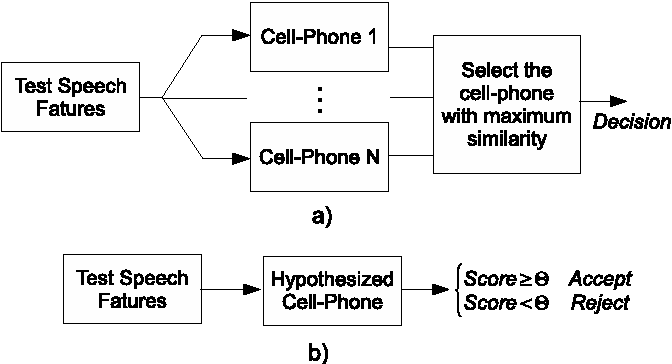
Figure 1 from Source cell-phone recognition from recorded speech using ...
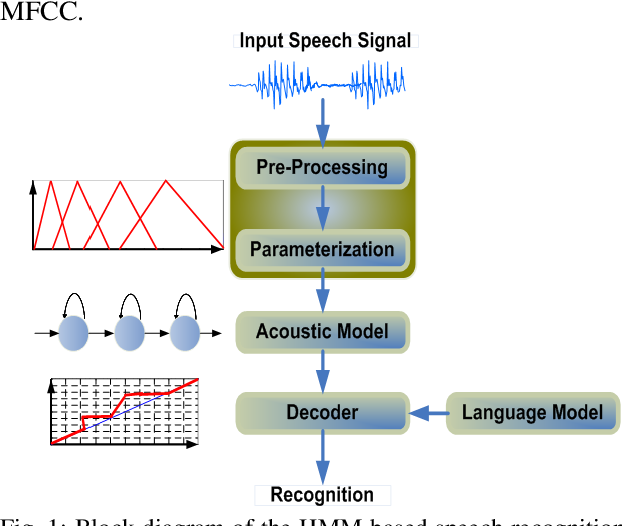
Figure 1 from Comparison of Speech Features on the Speech Recognition ...

Figure 1 from Integrating Emotion Recognition with Speech Recognition ...
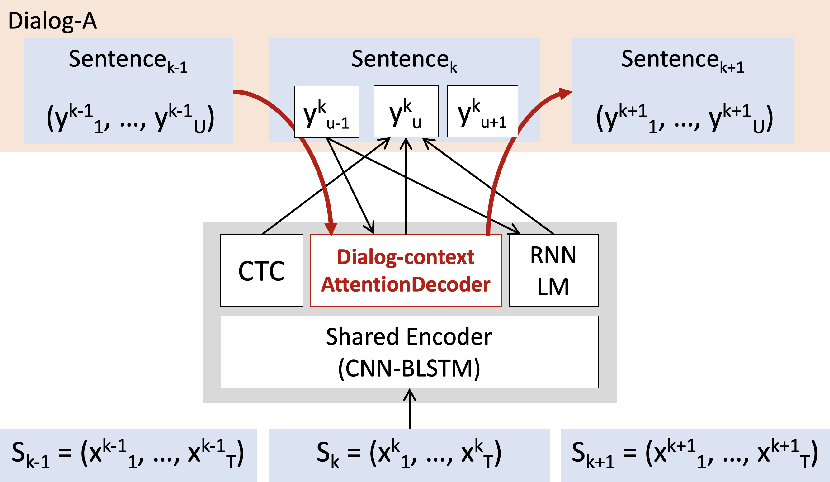
Figure 1 from Dialog-Context Aware end-to-end Speech Recognition ...
Advertisement Space (336x280)
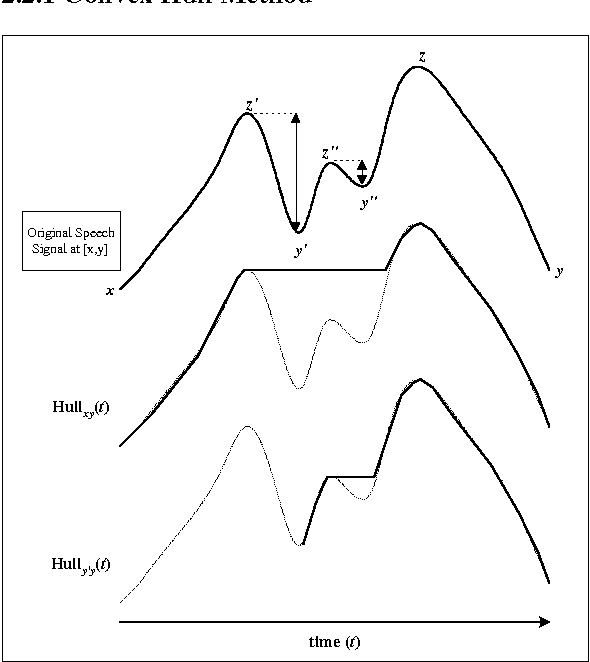
Figure 1 from A Comparative Study of Speech Segmentation and ...
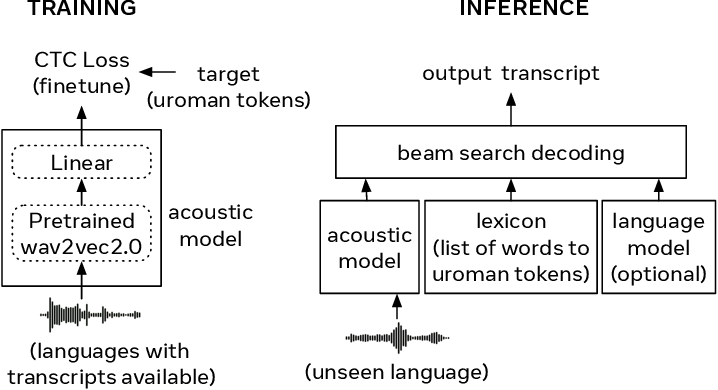
Figure 1 from Scaling A Simple Approach to Zero-Shot Speech Recognition ...

Figure 1 from Segment-based speech emotion recognition using recurrent ...

Figure 1 from Modeling speech recognition and synthesis simultaneously ...
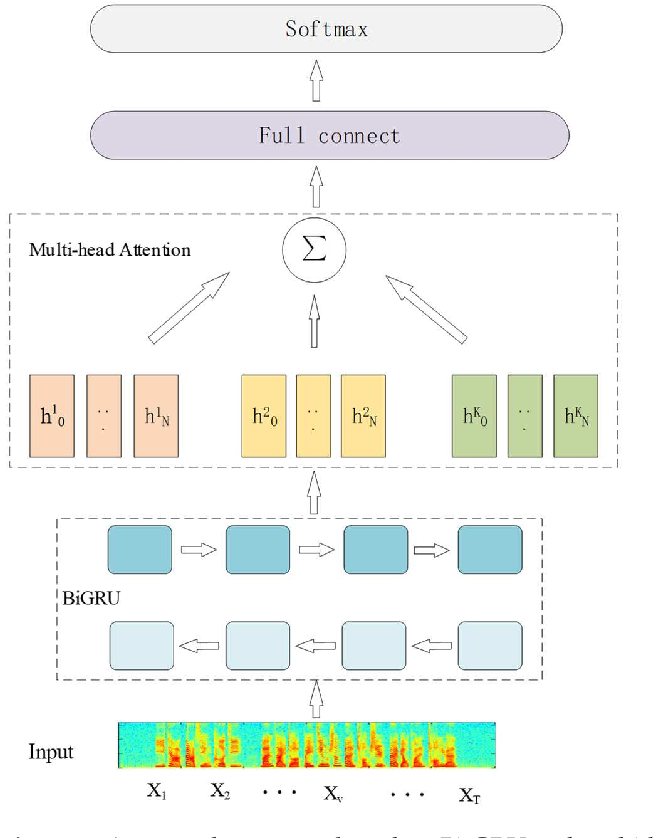
Figure 1 from A New Network Structure for Speech Emotion Recognition ...

Figure 1 from Conversational Speech Recognition by Learning Audio ...
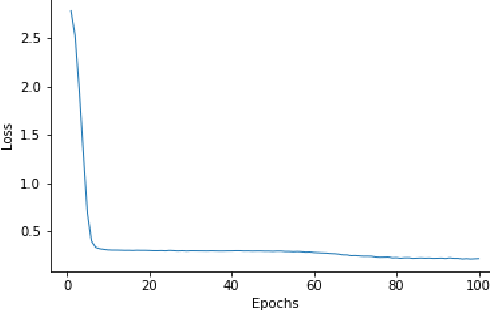
Figure 1 from Advancing Speech Recognition With No Speech Or With Noisy ...

Figure 1 from Speech Emotion Recognition Based on Speech Segment Using ...

Figure 1 from Deep Learning Enabled Semantic Communications With Speech ...

Figure 1 from Semi-supervised cross-lingual speech emotion recognition ...
Advertisement Space (336x280)

Figure 1 from A lOObit/s speech coding using a speech recognition ...

Figure 1 from Factual Consistency Oriented Speech Recognition ...
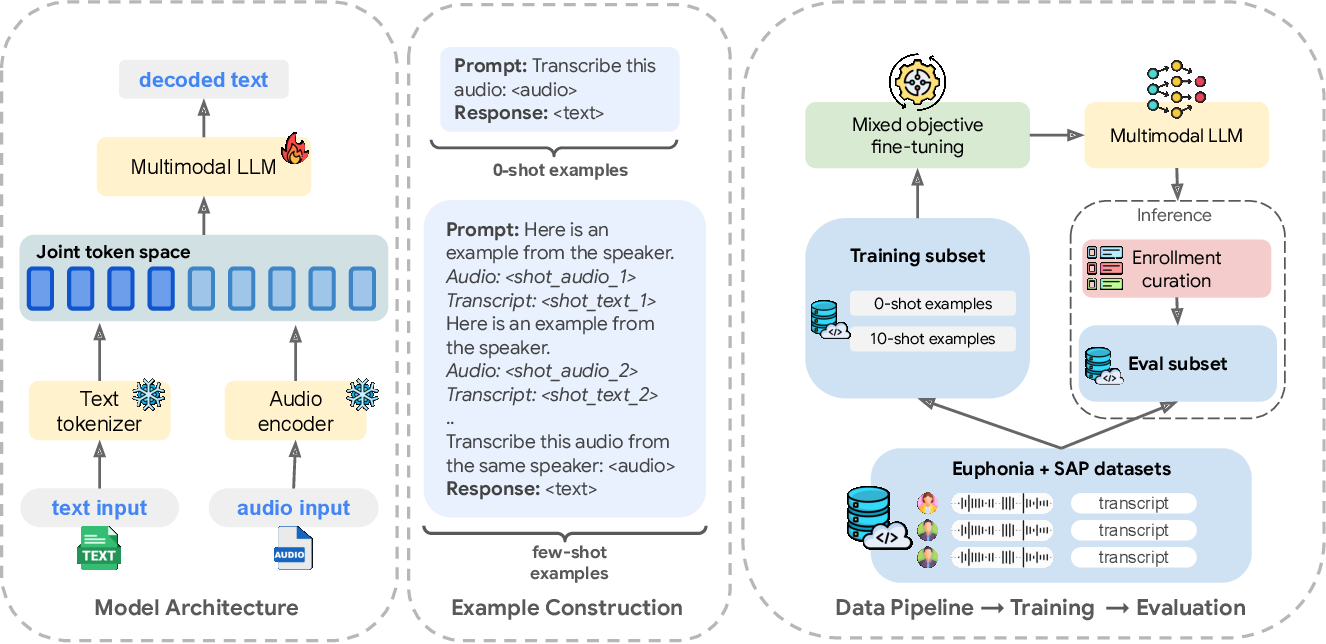
Figure 1 from State-of-the-Art Dysarthric Speech Recognition with ...

Figure 1 from A c/v segmentation method for Mandarin speech based on ...
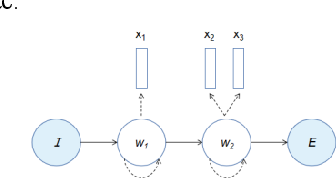
Figure 1 from A Review of Speech Recognition in Low-resource Languages ...

Figure 1 from Advancing Speech Recognition With No Speech Or With Noisy ...