
Figure 1 From Streaming Bilingual End To End Asr Model Using Attention

Figure 1 from Streaming Bilingual End-to-End ASR Model Using Attention ...
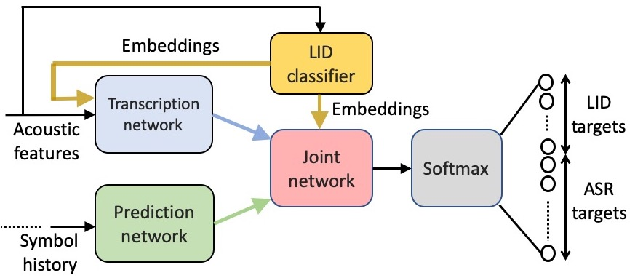
Figure 1 from Streaming End-to-End Bilingual ASR Systems with Joint ...
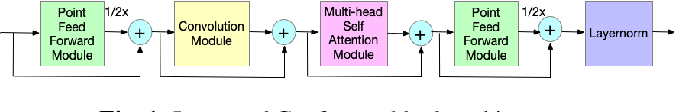
Figure 1 from A Better and Faster end-to-end Model for Streaming ASR ...

Figure 1 from ShrinkML: End-to-End ASR Model Compression Using ...

Figure 1 from Bilingual Streaming ASR with Grapheme units and Auxiliary ...

[2401.11645] Streaming Bilingual End-to-End ASR model using Attention ...

[2401.11645] Streaming Bilingual End-to-End ASR model using Attention ...

[2401.11645] Streaming Bilingual End-to-End ASR model using Attention ...

Figure 2 from On Comparison of Encoders for Attention based End to End ...

[2401.11645] Streaming Bilingual End-to-End ASR model using Attention ...
Advertisement Space (300x250)

[2401.11645] Streaming Bilingual End-to-End ASR model using Attention ...
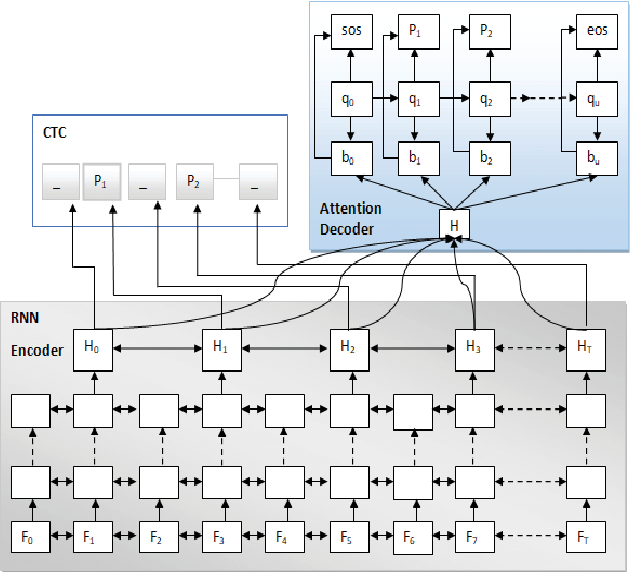
Figure 1 from ASR for Speech based Search in Hindi using Attention ...

Figure 1 from Streaming End-to-End ASR based on Blockwise Non ...

Figure 1 from Can We Train a Language Model Inside an End-to-End ASR ...

Figure 1 from A Language Agnostic Multilingual Streaming On-Device ASR ...

Figure 1 from Text-only domain adaptation for end-to-end ASR using ...

Figure 1 from Two-Pass End-to-End ASR Model Compression | Semantic Scholar

Figure 1 from AACFlow: an end-to-end model based on attention augmented ...

Figure 1 from Adaptable End-to-End ASR Models Using Replaceable ...

Figure 1 from Pre-Training Transformer Decoder for End-to-End ASR Model ...
Advertisement Space (336x280)

Figure 1 from Effects of End-to-end ASR and Score Fusion Model Learning ...
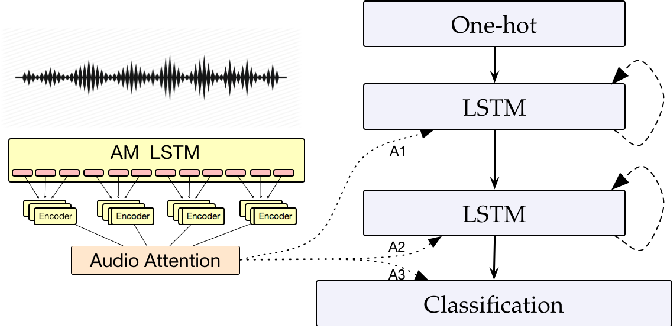
Figure 1 from Audio-Attention Discriminative Language Model for ASR ...

Figure 1 from Jointly Adversarial Enhancement Training for Robust End ...

Figure 1 from Streaming Multi-Speaker ASR with RNN-T | Semantic Scholar

Figure 2 from A Better and Faster end-to-end Model for Streaming ASR ...
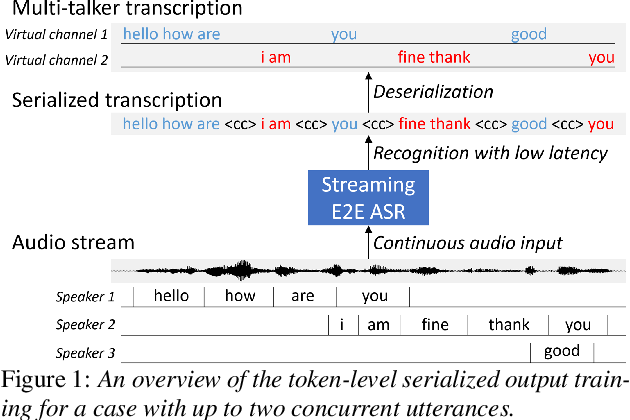
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...

Figure 1 from An Attention-Based Joint Acoustic and Text on-Device End ...

Figure 1 from Robust Front-End for Multi-Channel ASR using Flow-Based ...
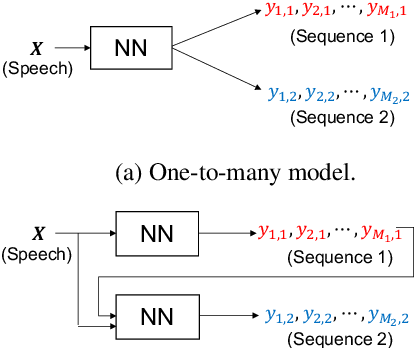
Figure 1 from End-to-end ASR to jointly predict transcriptions and ...
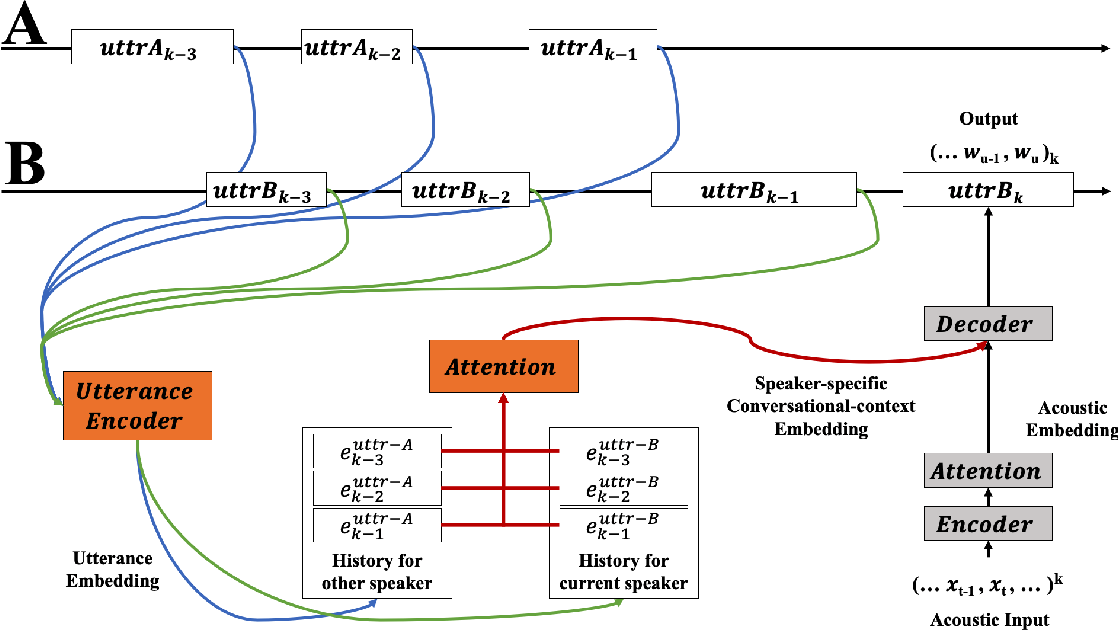
Figure 1 from Cross-Attention End-to-End ASR for Two-Party ...
Advertisement Space (336x280)

Figure 1 from End-to-End Spoken Language Understanding using RNN ...

Figure 1 from ASR Posterior-Based Loss for Multi-Task End-to-End Speech ...
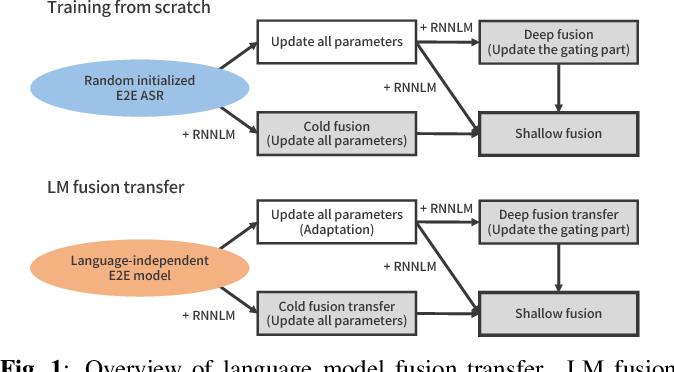
Figure 1 from Transfer Learning of Language-independent End-to-end ASR ...
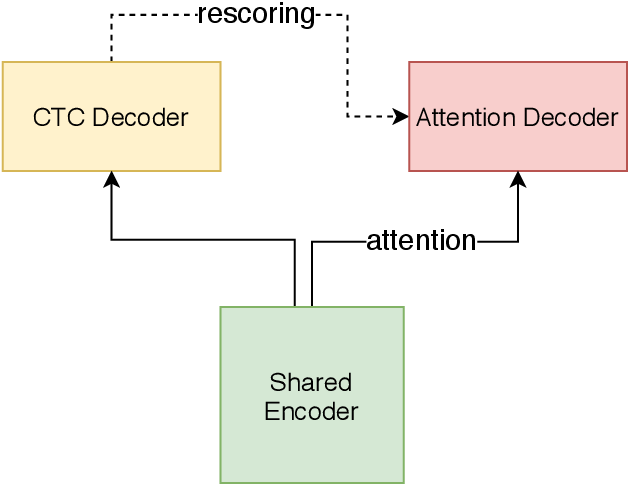
Figure 1 from Unified Streaming and Non-streaming Two-pass End-to-end ...
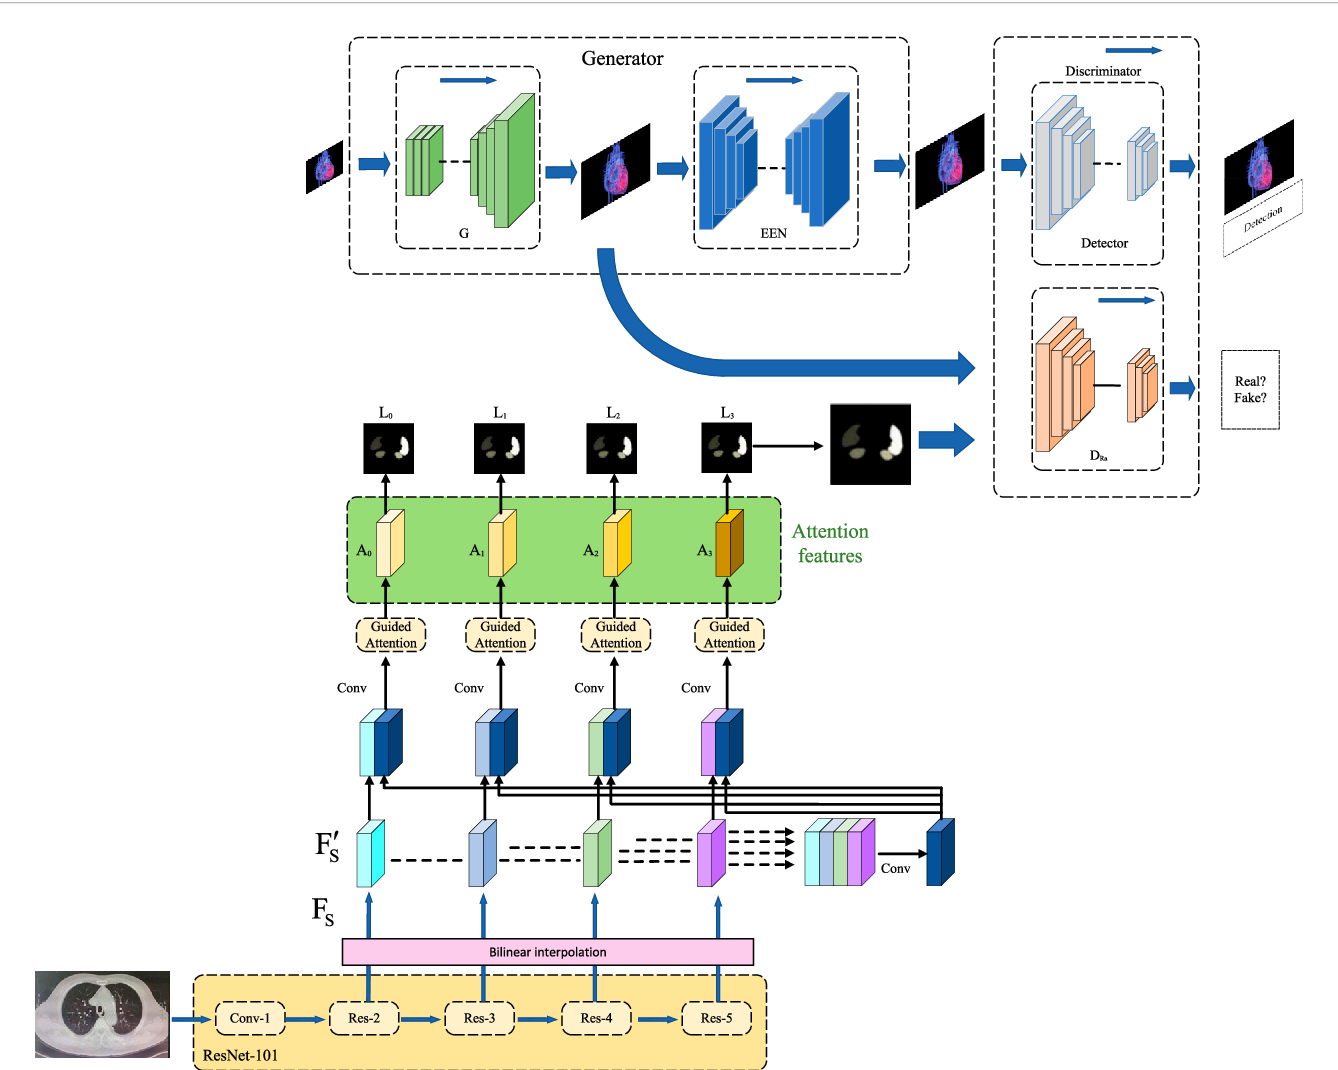
Figure 1 from Application of an end-to-end model with self-attention ...

Figure 1 from End-to-end contextual asr based on posterior distribution ...