
Figure 1 From Streaming Joint Speech Recognition And Disfluency

Figure 1 from Streaming Joint Speech Recognition and Disfluency ...

Figure 1 from Streaming Models for Joint Speech Recognition and ...
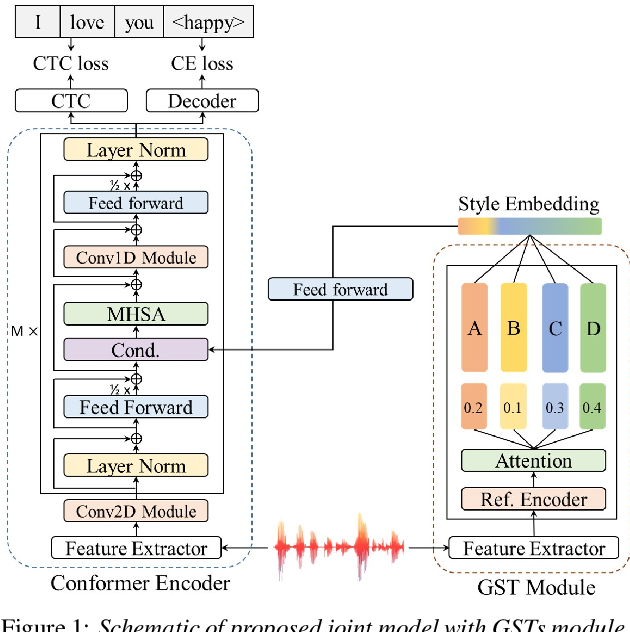
Figure 1 from Improving Joint Speech and Emotion Recognition Using ...

Figure 1 from Joint Speech Recognition and Speaker Diarization via ...
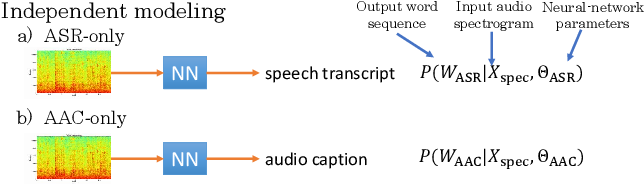
Figure 1 from Joint Speech Recognition and Audio Captioning | Semantic ...
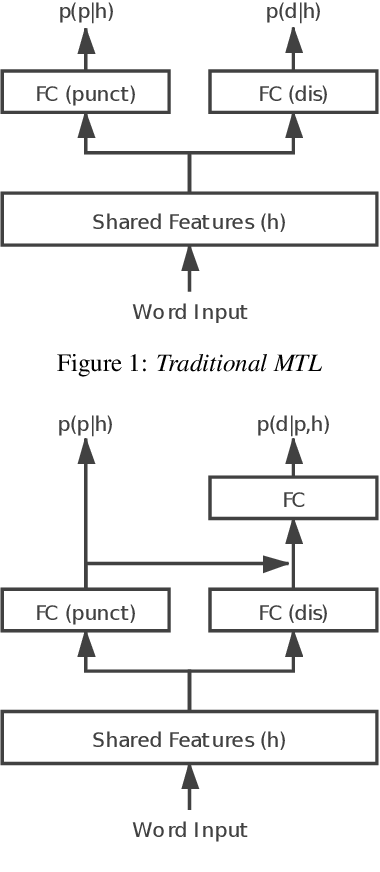
Figure 1 from Joint Prediction of Punctuation and Disfluency in Speech ...
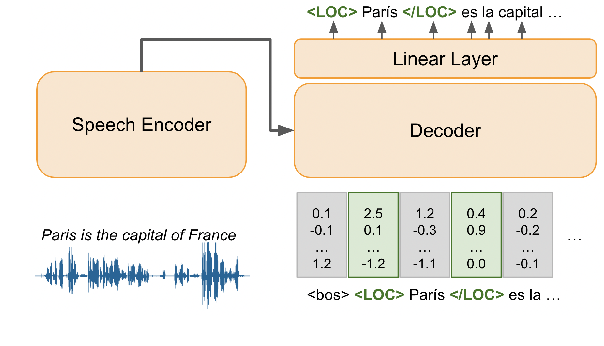
Figure 1 from Joint Speech Translation and Named Entity Recognition ...
Figure 1 from Joint audio-visual speech processing for recognition and ...

Figure 1 from Improving Joint Speech and Emotion Recognition Using ...

Figure 1 from Streaming End-to-End Multilingual Speech Recognition with ...
Advertisement Space (300x250)

Figure 1 from Joint Optimization of Streaming and Non-Streaming ...

Figure 1 from Streaming Audio-Visual Speech Recognition with Alignment ...
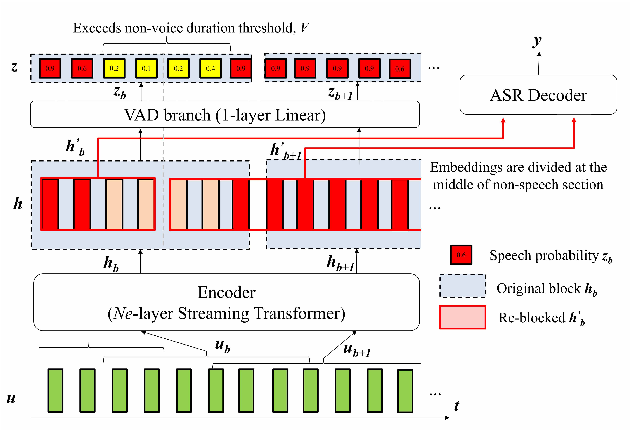
Figure 1 from Streaming Automatic Speech Recognition with Re-blocking ...

Figure 1 from Joint Transition-based Dependency Parsing and Disfluency ...
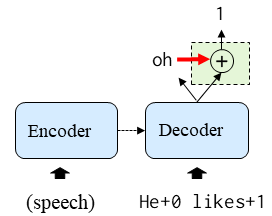
[2211.08726] STREAMING JOINT SPEECH RECOGNITION AND DISFLUENCY DETECTION

Figure 1 from Joint variable frame rate and length analysis for speech ...

STREAMING JOINT SPEECH RECOGNITION AND DISFLUENCY DETECTION | SPS ...
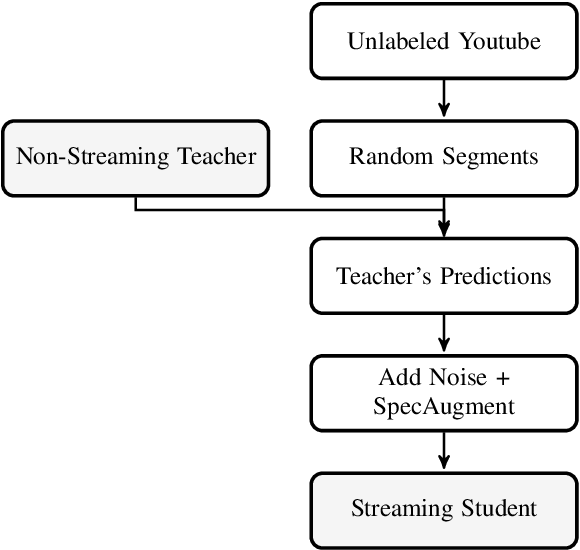
Figure 1 from Improving Streaming Automatic Speech Recognition with Non ...
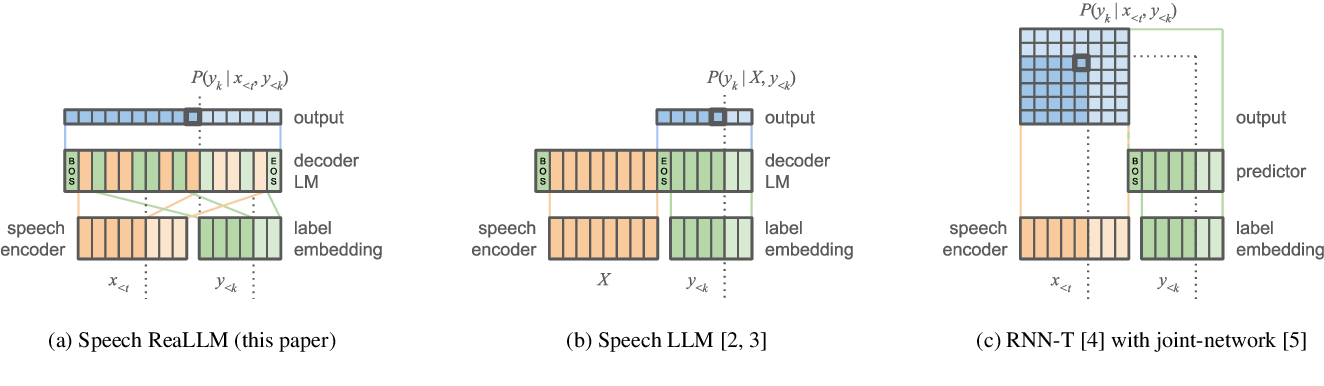
Figure 1 from Speech ReaLLM - Real-time Streaming Speech Recognition ...

Figure 1 from Streaming End-to-End Speech Recognition with Jointly ...
Advertisement Space (336x280)

Figure 1 from Attention Based On-Device Streaming Speech Recognition ...

Figure 1 from A Streaming End-to-End Speech Recognition Approach Based ...

Figure 1 from End-To-End Speech Recognition with Joint Dereverberation ...

Figure 1 from Contextualized Streaming End-to-End Speech Recognition ...
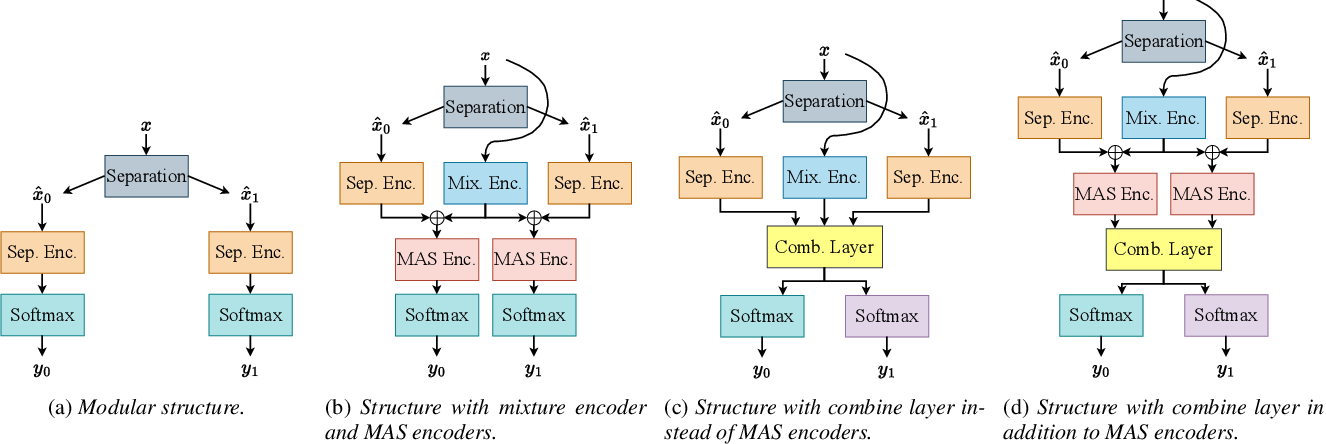
Figure 1 from Mixture Encoder for Joint Speech Separation and ...

Figure 1 from Joint single-channel speech separation and speaker ...

Figure 1 from SINGLE CHANNEL JOINT SPEECH DEREVERBERATION AND DENOISING ...

Figure 1 from Streaming End-to-End Multi-Talker Speech Recognition ...

Figure 1 from Language modeling for spontaneous speech recognition ...

Figure 1 from Decoder-only Architecture for Streaming End-to-end Speech ...
Advertisement Space (336x280)

Figure 1 from Joint Speech-Text Embeddings for Multitask Speech ...

Figure 1 from Automatic Disfluency Detection From Untranscribed Speech ...

Figure 1 from Direction-Aware Joint Adaptation of Neural Speech ...
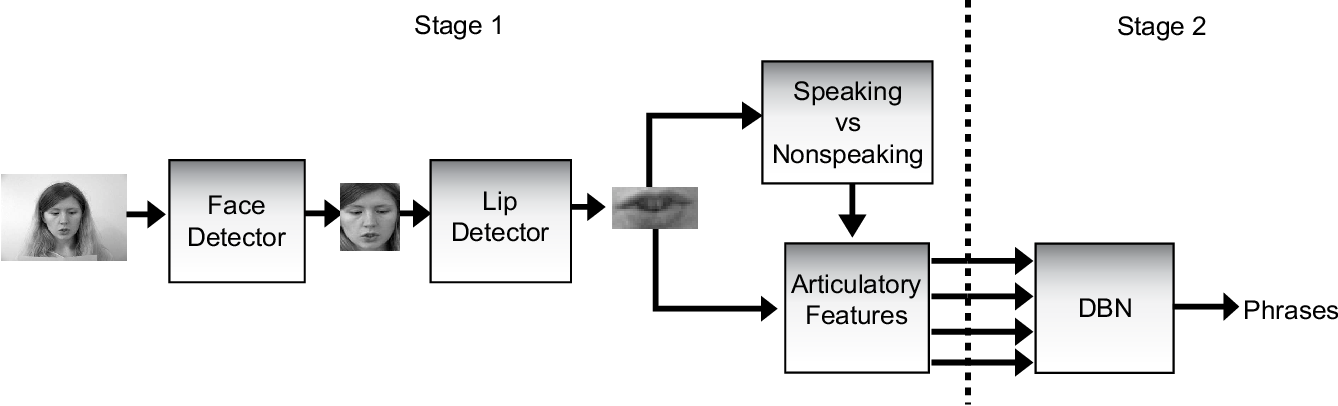
Figure 1 from Visual speech recognition with loosely synchronized ...

Figure 1 from Improving Speaker-Independent Speech Emotion Recognition ...
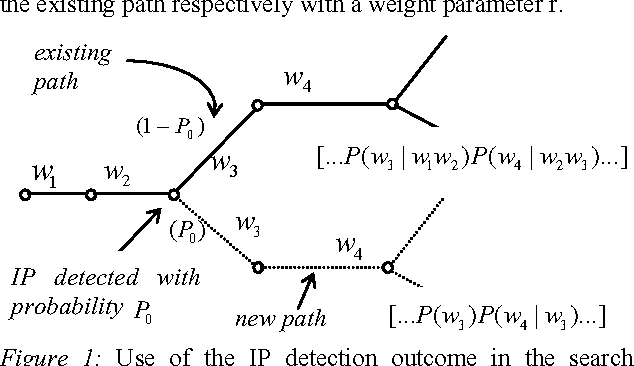
Figure 1 from Improved spontaneous Mandarin speech recognition by ...