
Figure 1 From Unsupervised Acoustic Unit Discovery For Speech Synthesis

Figure 1 from Unsupervised acoustic unit discovery for speech synthesis ...

Figure 1 from Transformer VQ-VAE for Unsupervised Unit Discovery and ...
[PPT] - Unsupervised acoustic unit discovery for speech synthesis using ...
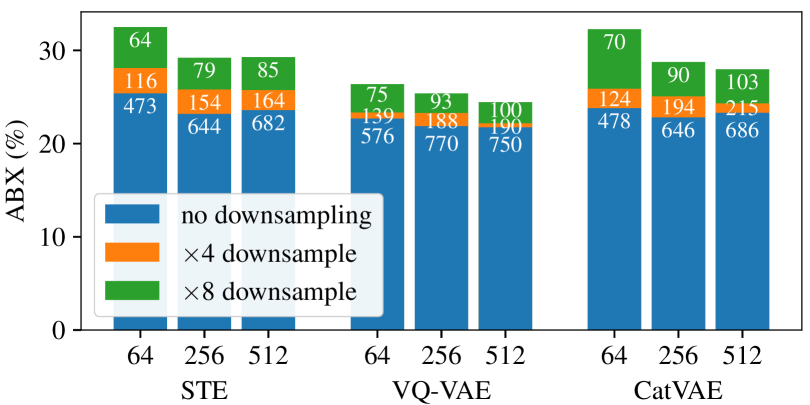
[1904.07556] Unsupervised acoustic unit discovery for speech synthesis ...
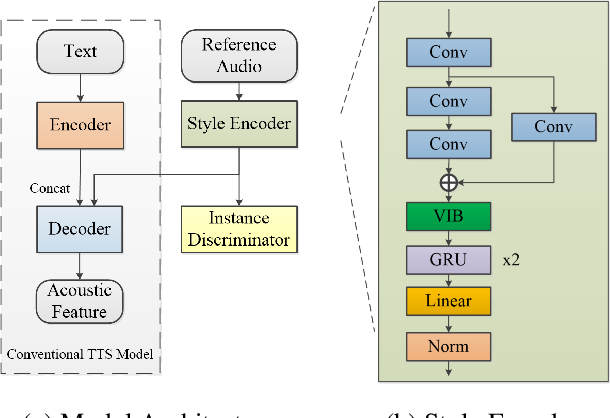
Figure 1 from Unsupervised Learning for Multi-Style Speech Synthesis ...

Figure 1 from Multimodal speech synthesis architecture for unsupervised ...

Figure 1 from Multimodal speech synthesis architecture for unsupervised ...

Figure 1 from Unsupervised Acoustic Unit Representation Learning for ...

Figure 1 from Unsupervised pre-training for sequence to sequence speech ...

Figure 1 from Towards Unsupervised Speech Recognition and Synthesis ...
Advertisement Space (300x250)

Figure 1 from Speech-XLNet: Unsupervised Acoustic Model Pretraining For ...
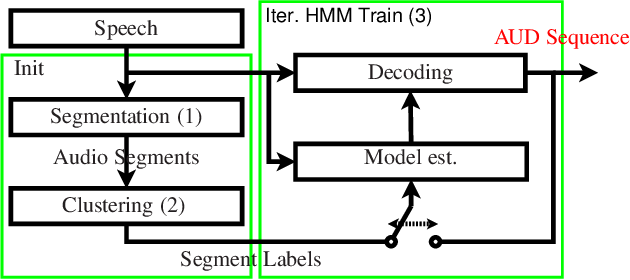
Figure 1 from An evaluation of unsupervised acoustic model training for ...

Figure 1 from Unit Selection Speech Synthesis Using Phonetic-Prosodic ...

Figure 1 from Unsupervised domain adaptation for speech recognition ...

Figure 1 from Unsupervised TTS Acoustic Modeling for TTS With ...
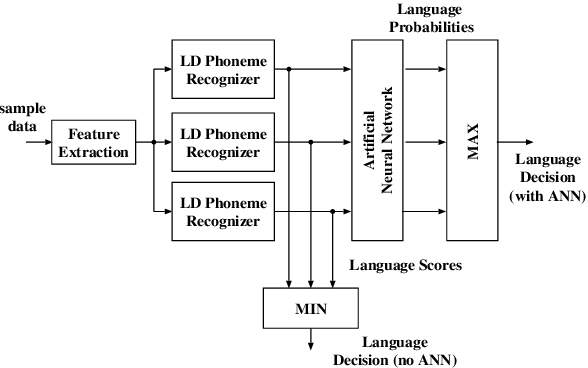
Figure 1 from Unsupervised adaptation for acoustic language ...

Figure 1 from Unsupervised Learning of Acoustic Units Using ...

Figure 1 from VoxGenesis: Unsupervised Discovery of Latent Speaker ...

Figure 1 from A Theory of Unsupervised Speech Recognition | Semantic ...

Pushing the Limits of Unsupervised Unit Discovery for SSL Speech ...
Advertisement Space (336x280)

Figure 1 from A Multimodal Prototypical Approach for Unsupervised Sound ...
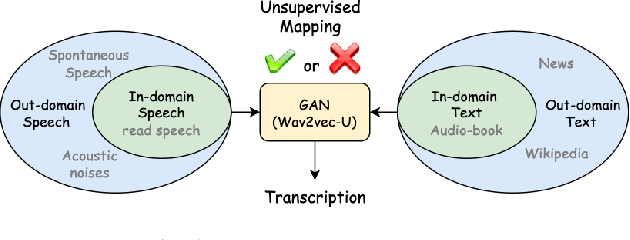
Figure 1 from Analyzing The Robustness of Unsupervised Speech ...

Figure 1 from Unsupervised Acoustic Scene Mapping Based on Acoustic ...

Figure 1 from Simple and Effective Unsupervised Speech Translation ...

Figure 1 from Enhancing Unsupervised Speech Recognition with Diffusion ...

Figure 1 from Unsupervised Word-Level Prosody Tagging for Controllable ...
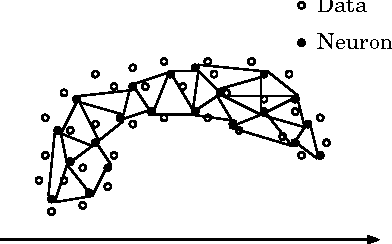
Figure 1 from Learning Speech as Acoustic Sequences with the ...
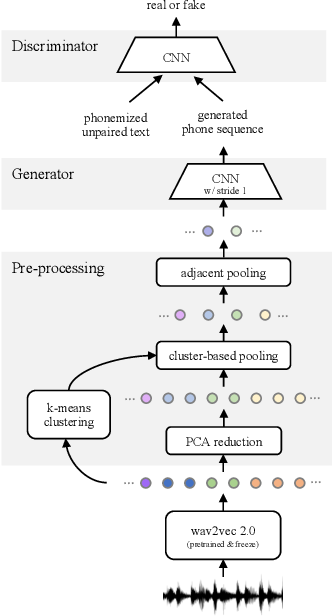
Figure 1 from Towards End-to-End Unsupervised Speech Recognition ...
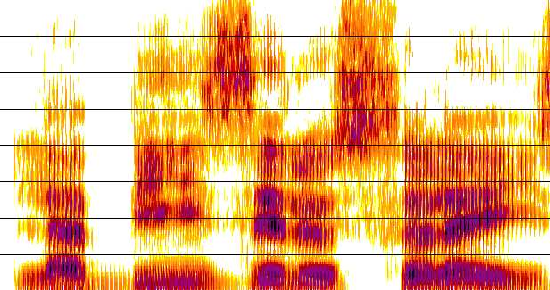
Figure 1 from Learning Speech as Acoustic Sequences with the ...
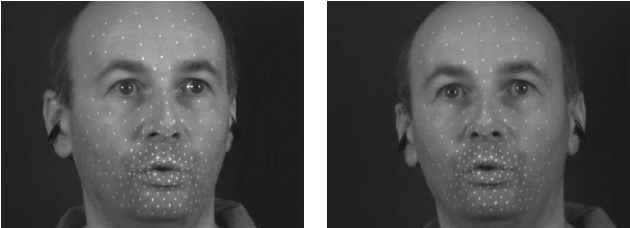
Figure 1 from Towards a true acoustic-visual speech synthesis ...
Advertisement Space (336x280)
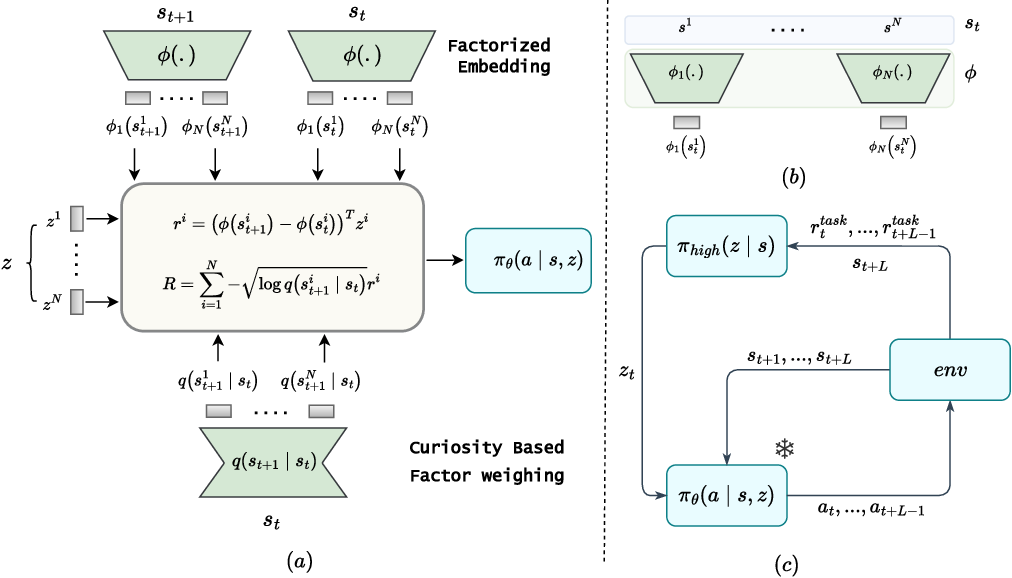
Figure 1 from SUSD: Structured Unsupervised Skill Discovery through ...

Figure 1 from Unsupervised Speech/Non-Speech Detection for Automatic ...
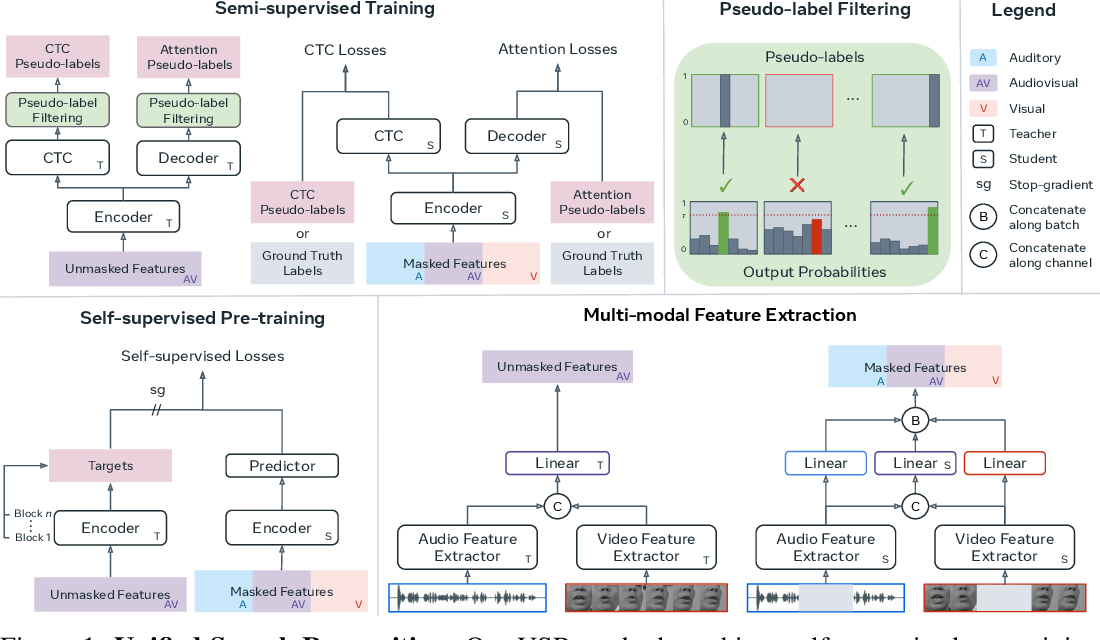
Figure 1 from Unified Speech Recognition: A Single Model for Auditory ...
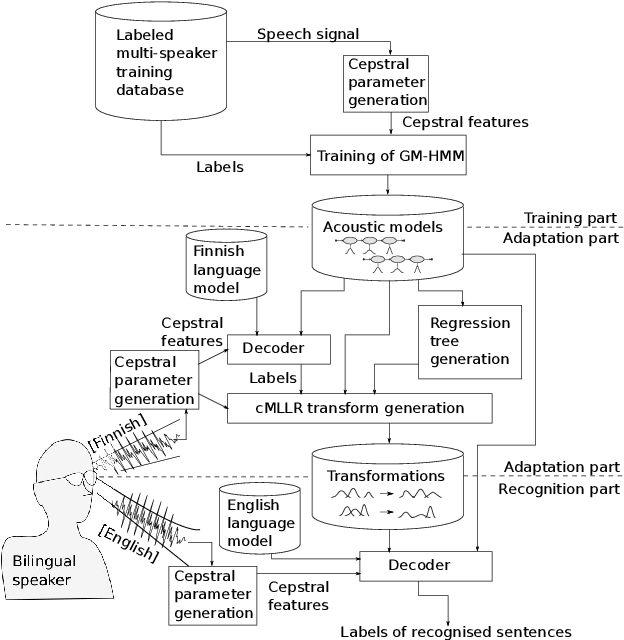
Figure 1 from Unsupervised cross-lingual speaker adaptation for ...

Figure 3 from Unsupervised Pattern Discovery from Thematic Speech ...

Figure 1 from Hybrid Unsupervised and Supervised Multitask Learning For ...