
Figure 1 From Unsupervised Speaker Adaptation Based On Sufficient Hmm
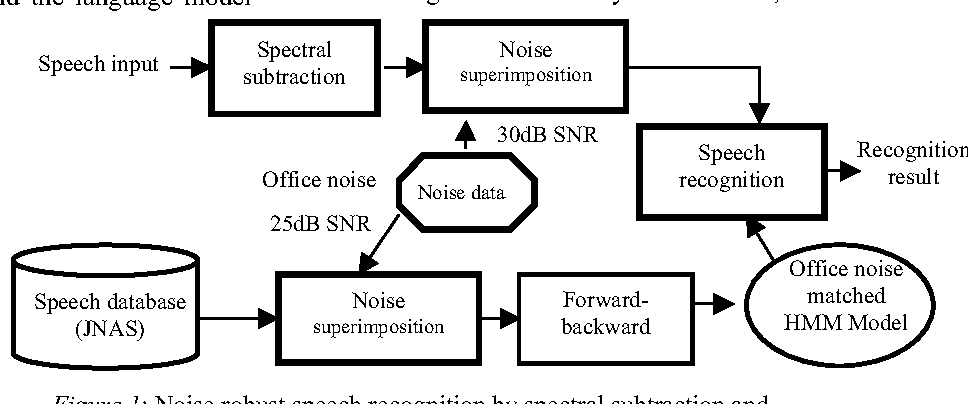
Figure 1 from Unsupervised speaker adaptation based on HMM sufficient ...

Figure 1 from Unsupervised speaker adaptation based on sufficient HMM ...
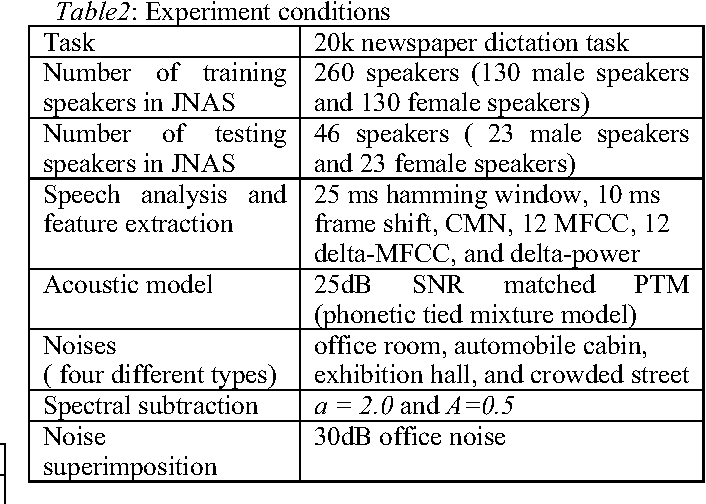
Table 1 from Unsupervised speaker adaptation based on HMM sufficient ...

Table 1 from Unsupervised speaker adaptation based on sufficient HMM ...
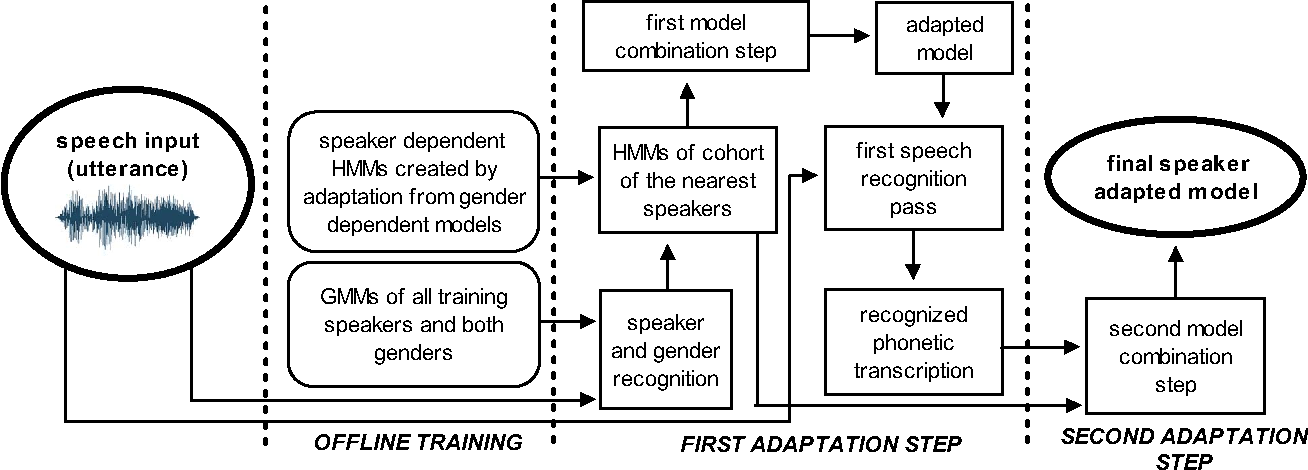
Figure 1 from Two-step unsupervised speaker adaptation based on speaker ...
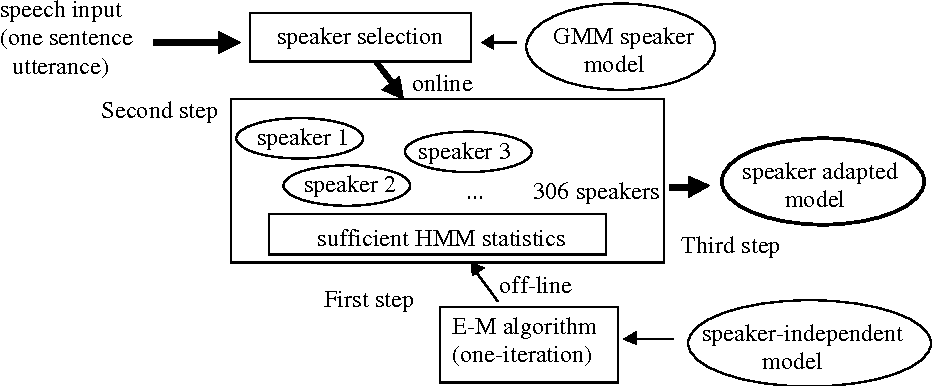
Figure 1 from Evaluation on unsupervised speaker adaptation based on ...
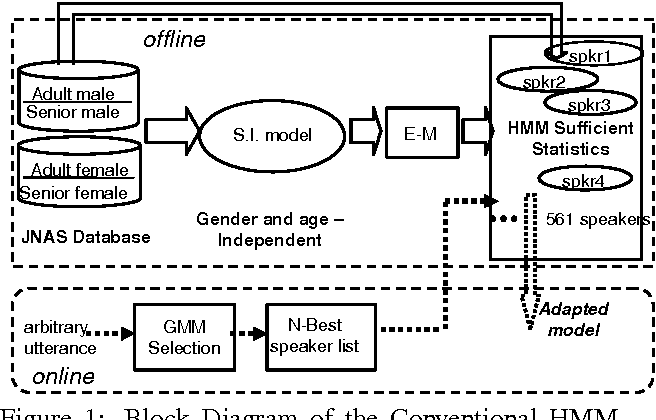
Figure 1 from Rapid unsupervised speaker adaptation based on multi ...
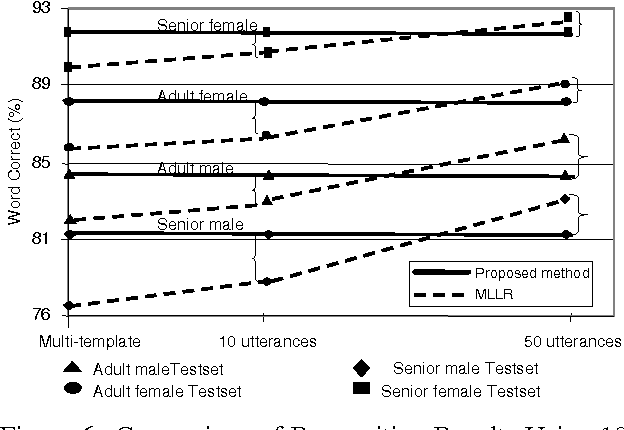
Figure 1 from Rapid unsupervised speaker adaptation based on multi ...

Figure 1 from Unsupervised cross-lingual speaker adaptation for HMM ...

Table 1 from Evaluation on unsupervised speaker adaptation based on ...
Advertisement Space (300x250)

Figure 5 from Evaluation on unsupervised speaker adaptation based on ...

Figure 3 from Evaluation on unsupervised speaker adaptation based on ...

Figure 7 from Evaluation on unsupervised speaker adaptation based on ...

Figure 8 from Evaluation on unsupervised speaker adaptation based on ...

Figure 1 from Unsupervised Domain Adaptation Method Based on Domain ...
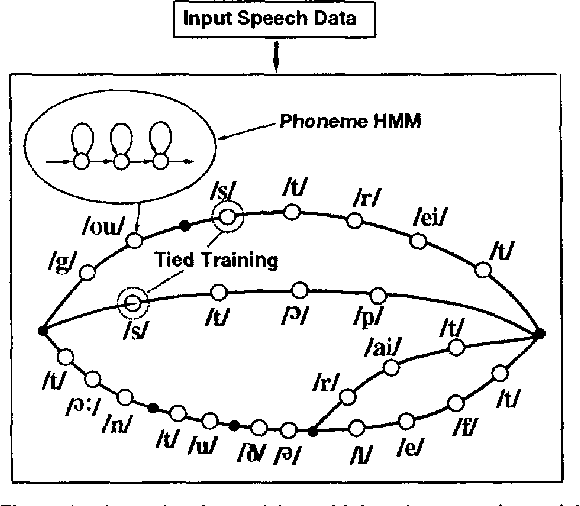
Figure 1 from An all-phoneme ergodic HMM for unsupervised speaker ...

Figure 1 from Analysis of unsupervised cross-lingual speaker adaptation ...

(PDF) Evaluation on unsupervised speaker adaptation based on sufficient ...

Figure 1 from Unsupervised speaker adaptation for DNN-based TTS ...

Figure 1 from Unsupervised Model-Based Speaker Adaptation of End-To-End ...
Advertisement Space (336x280)
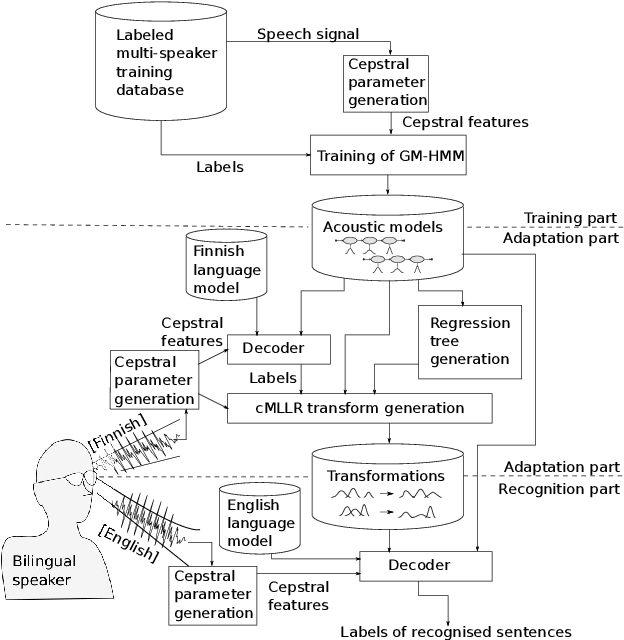
Figure 1 from Unsupervised cross-lingual speaker adaptation for ...
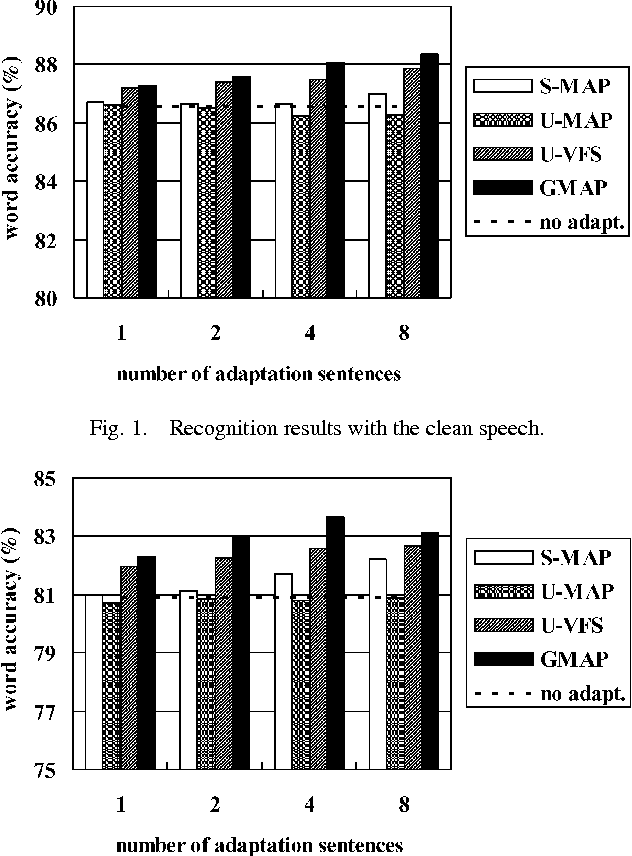
Figure 1 from An approach to robust unsupervised speaker adaptation ...
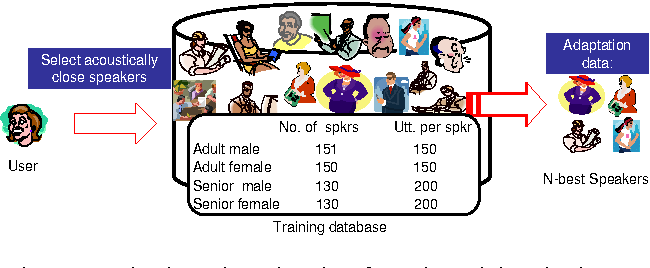
Figure 1 from Rapid unsupervised speaker adaptation using single ...

Figure 1 from On combining DNN and GMM with unsupervised speaker ...
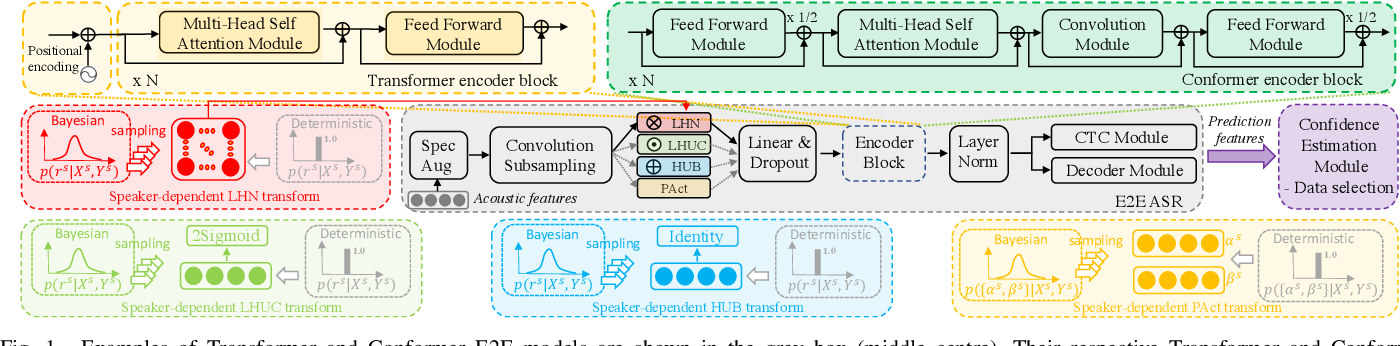
Figure 1 from Confidence Score Based Speaker Adaptation of Conformer ...
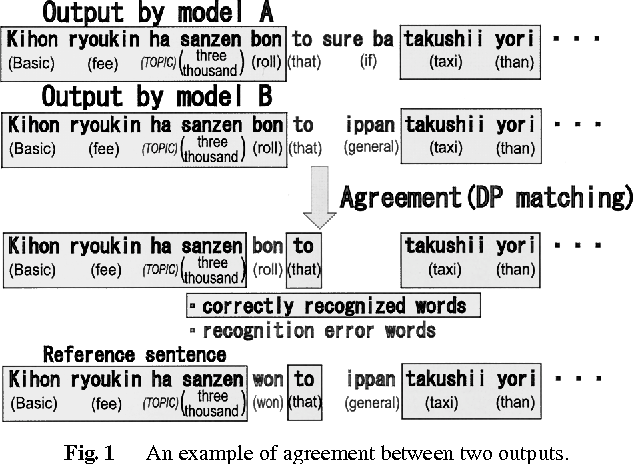
Figure 1 from An Unsupervised Speaker Adaptation Method for Lecture ...
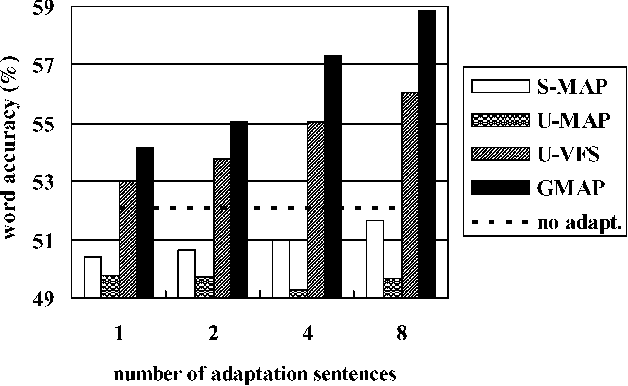
Figure 1 from An approach to robust unsupervised speaker adaptation ...

Figure 1 from Cross-lingual Speaker Adaptation for HMM-based Speech ...
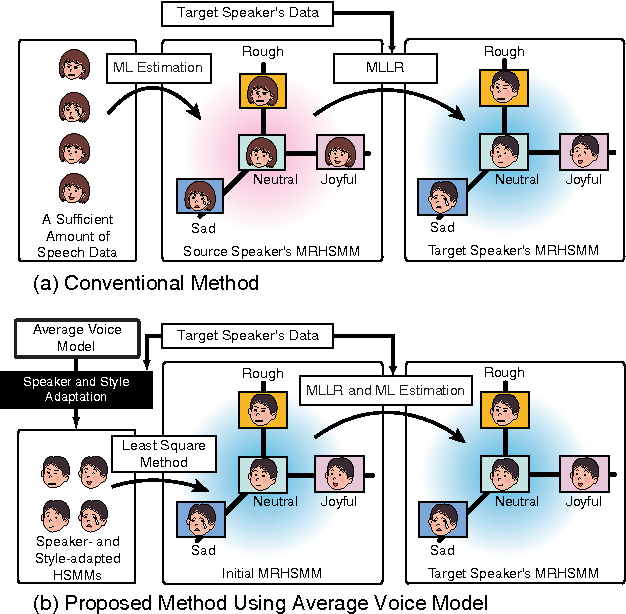
Figure 1 from Speaker and style adaptation using average voice model ...
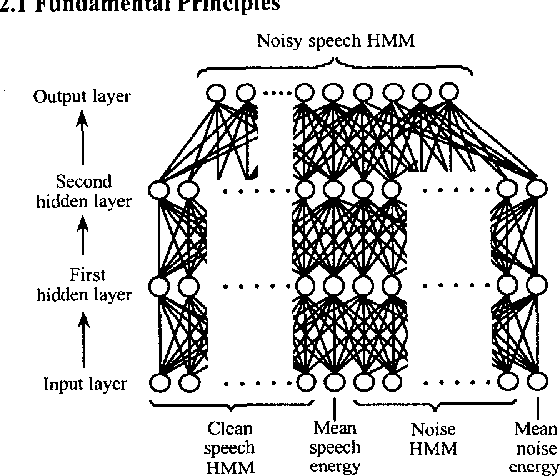
Figure 1 from Neural-network-based HMM adaptation for noisy speech ...
Advertisement Space (336x280)
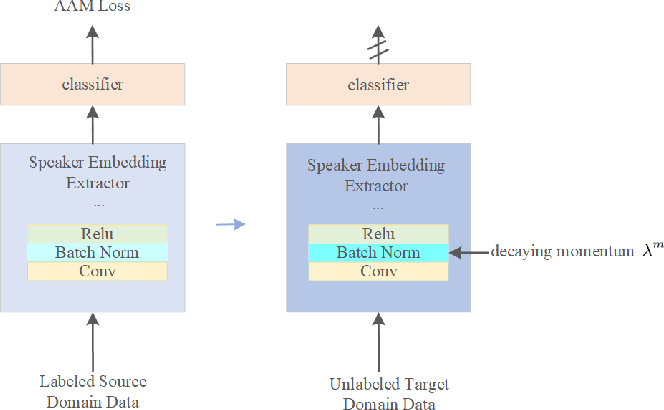
Figure 1 from Unsupervised Source Free Domain Adaptation by Batch ...

Figure 1 from Cluster-Guided Unsupervised Domain Adaptation for Deep ...

Figure 1 from Unsupervised Adaptive Speaker Recognition by Coupling ...
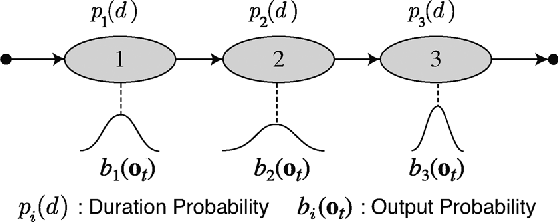
Figure 1 from Analysis of Speaker Adaptation Algorithms for HMM-Based ...

Figure 1 from Class-Aware Distribution Alignment based Unsupervised ...

Figure 1 from Unsupervised Adaptation with Quality-Aware Masking to ...