
Figure 1 From Using Seq2seq Voice Conversion With Pre Trained

Figure 1 from Using Seq2seq voice conversion with pre-trained ...

Figure 2 from Using Seq2seq voice conversion with pre-trained ...
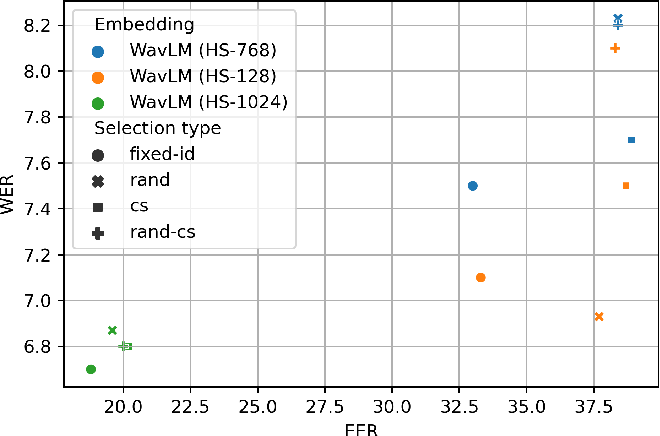
Figure 3 from Using Seq2seq voice conversion with pre-trained ...

Figure 1 from Any-to-One Sequence-to-Sequence Voice Conversion Using ...

Figure 1 from Non-Parallel Sequence-to-Sequence Voice Conversion With ...
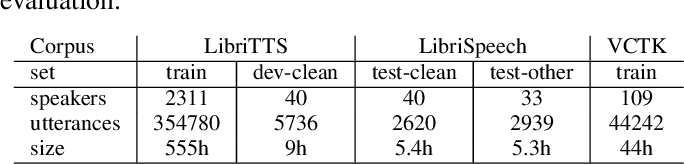
Table I from Using Seq2seq voice conversion with pre-trained ...

Table IV from Using Seq2seq voice conversion with pre-trained ...
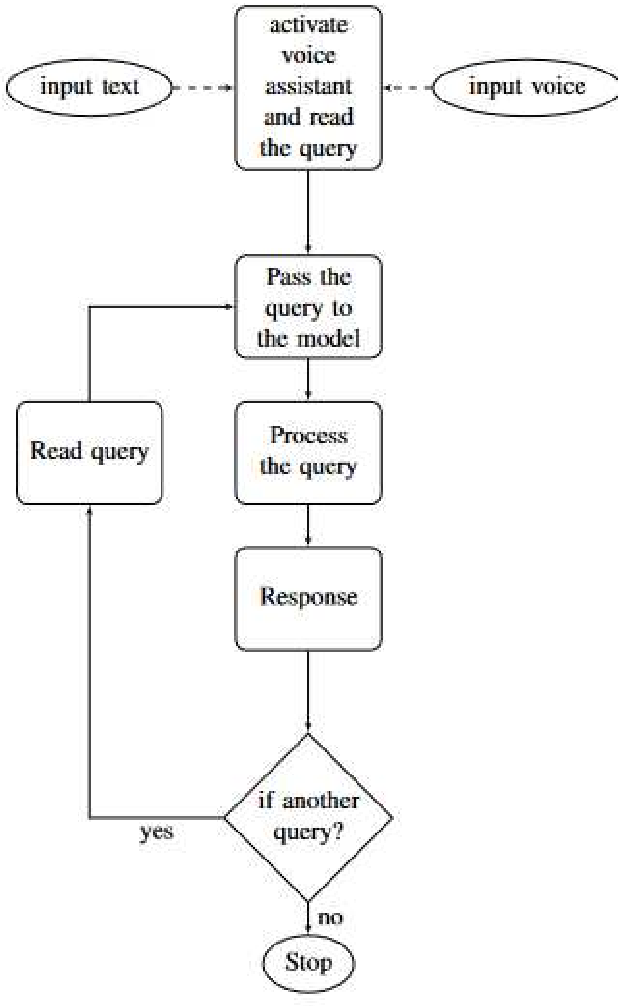
Figure 1 from Seq2seq and Legacy techniques enabled Chatbot with Voice ...
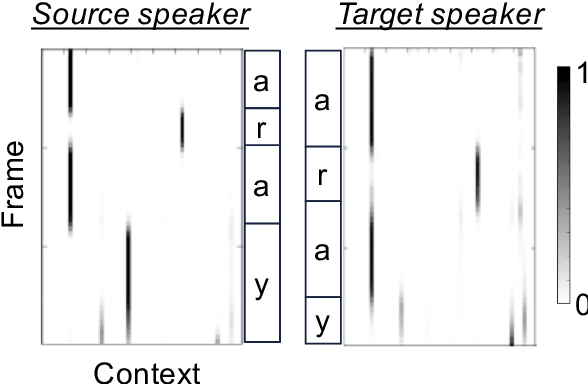
Figure 1 from Voice Conversion Using Sequence-to-Sequence Learning of ...
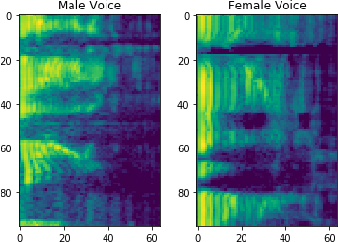
Figure 1 from Voice Conversion using Generative Techniques | Semantic ...
Advertisement Space (300x250)

Figure 1 from Jointly Trained Conversion Model With LPCNet for Any-to ...

Figure 1 from Improving Sequence-to-sequence Voice Conversion by Adding ...
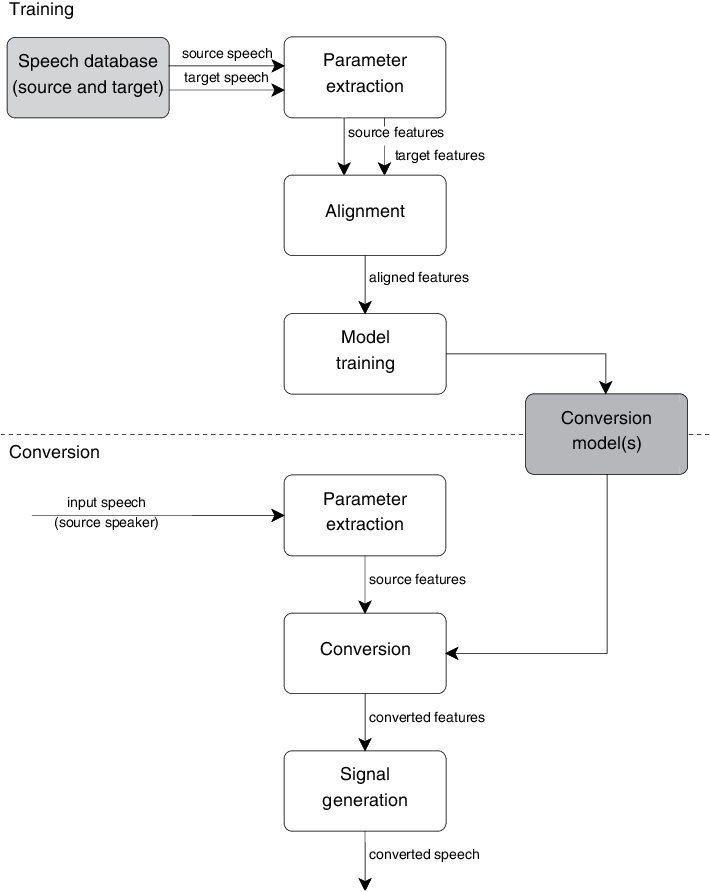
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from Jointly Trained Conversion Model and WaveNet Vocoder for ...

Figure 1 from Using Seq2Seq Model to Detect Infection Focusing on ...
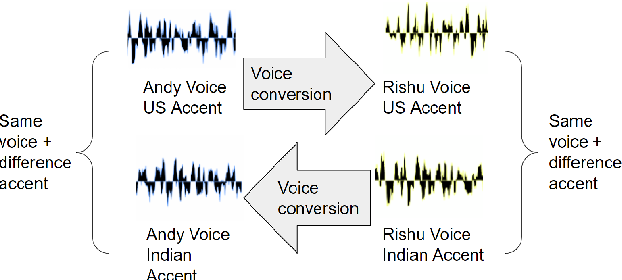
Figure 1 from Accent Conversion using Pre-trained Model and Synthesized ...

Figure 1 from Non-Autoregressive Sequence-To-Sequence Voice Conversion ...

Figure 1 from Walking Speed Learning and Generalization Using Seq2Seq ...

Figure 1 from Abstractive Text Summarization using Seq2seq Model ...

Figure 1 from Predicting Airport Visibility using Seq2Seq Models ...
Advertisement Space (336x280)

Figure 2 from Voice Conversion Using Sequence-to-Sequence Learning of ...

Figure 1 from Conditional set generation using Seq2seq models ...
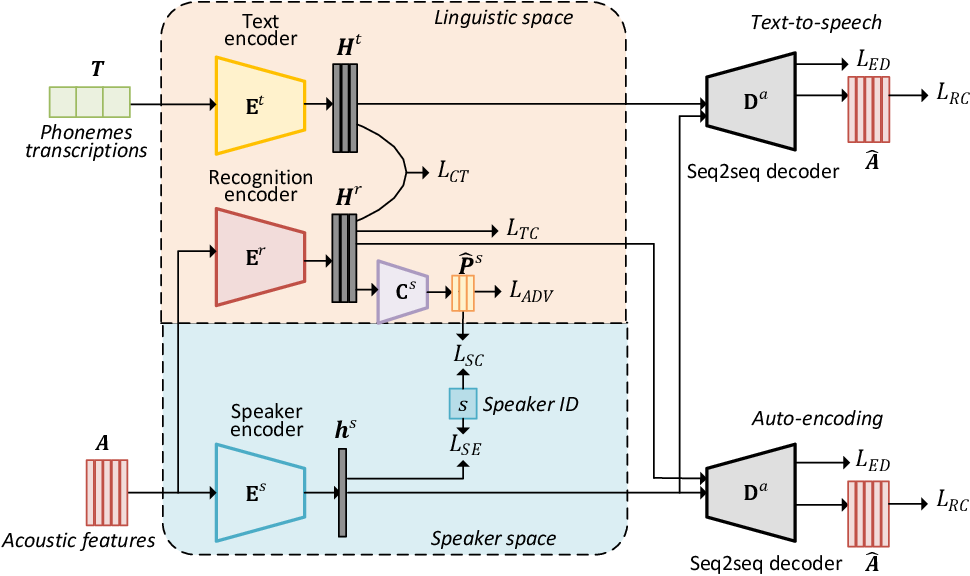
Figure 2 from Non-Parallel Sequence-to-Sequence Voice Conversion With ...

Figure 1 from An evaluation of many-to-one voice conversion algorithms ...

Figure 1 from Voice Conversion Augmentation for Speaker Recognition on ...
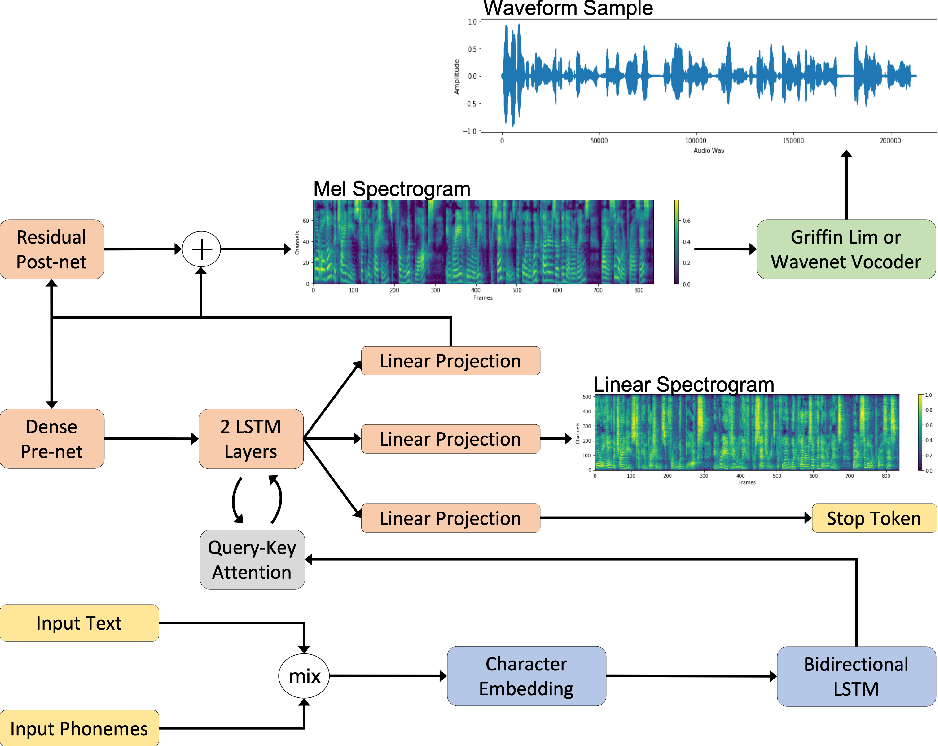
Table 1 from Deep Text-to-Speech System with Seq2Seq Model | Semantic ...
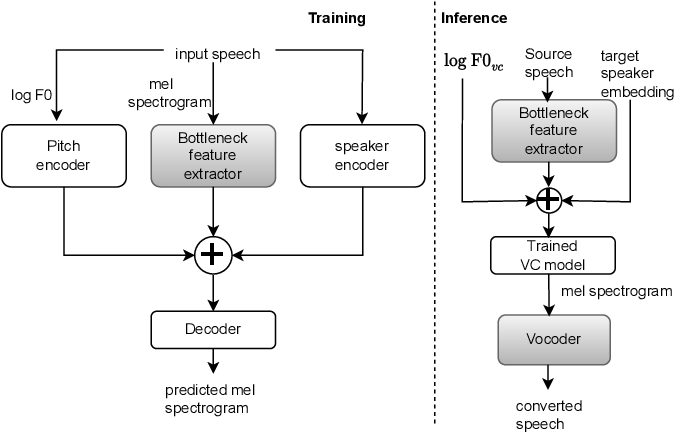
Figure 1 from Adapting Pretrained Models for Adult to Child Voice ...

Figure 1 from Injecting a Structural Inductive Bias into a Seq2Seq ...
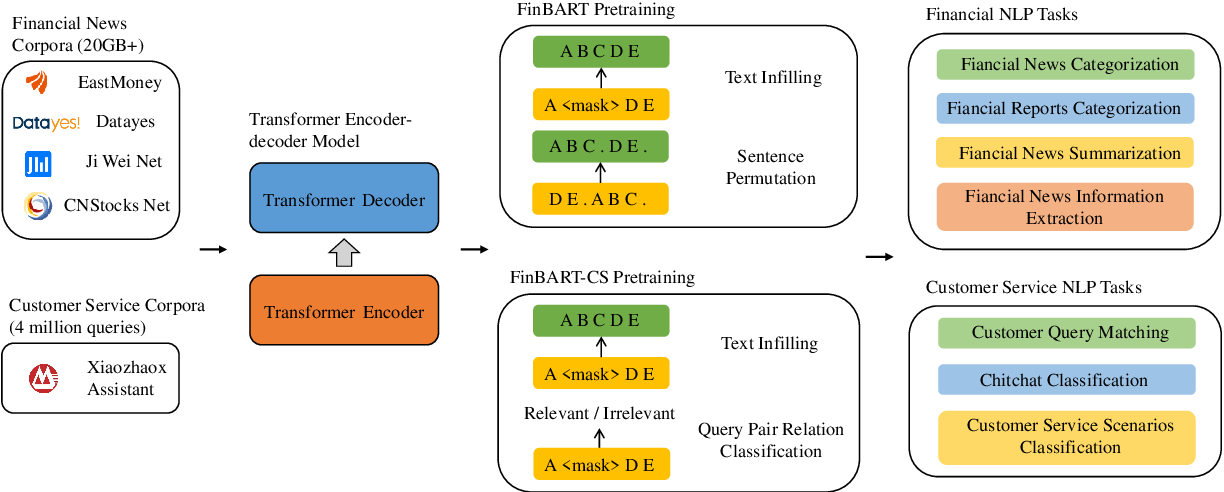
Figure 1 from FinBART: A Pre-trained Seq2seq Language Model for Chinese ...

Figure 1 from Enhanced Direct Speech-to-Speech Translation Using Self ...
Advertisement Space (336x280)

Figure 1 from Normalization of Transliterated Mongolian Words Using ...
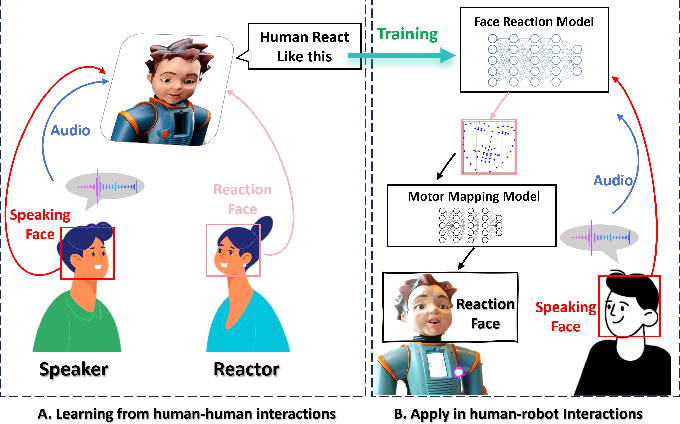
Figure 1 from Learning from Human Conversations: A Seq2Seq based Multi ...
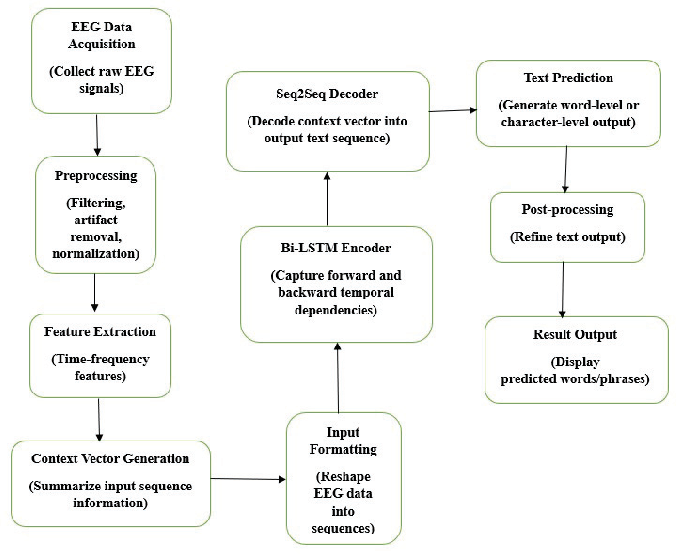
Figure 1 from An Electroencephalography-Driven Language Interface Using ...
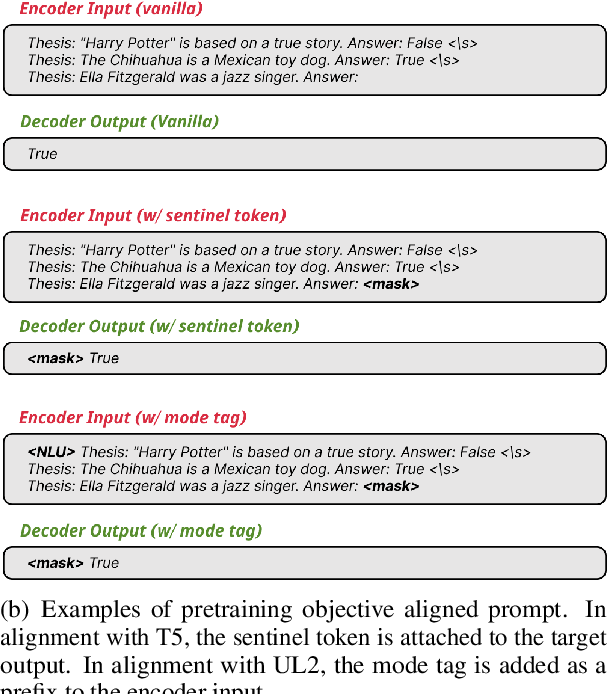
Figure 1 from Exploiting the Potential of Seq2Seq Models as Robust Few ...
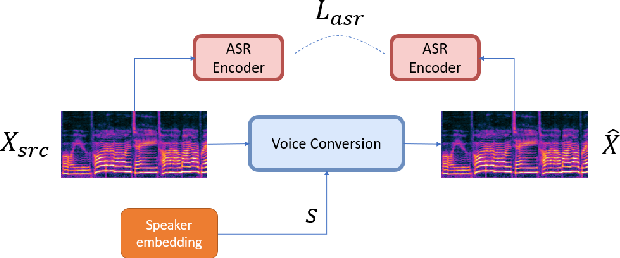
Figure 1 from Iteratively Improving Speech Recognition and Voice ...

Figure 1 from Unsupervised pre-training for sequence to sequence speech ...