
Figure 1 From Vision And Dialog Navigation Semantic Scholar

Figure 1 from Vision-and-Dialog Navigation | Semantic Scholar
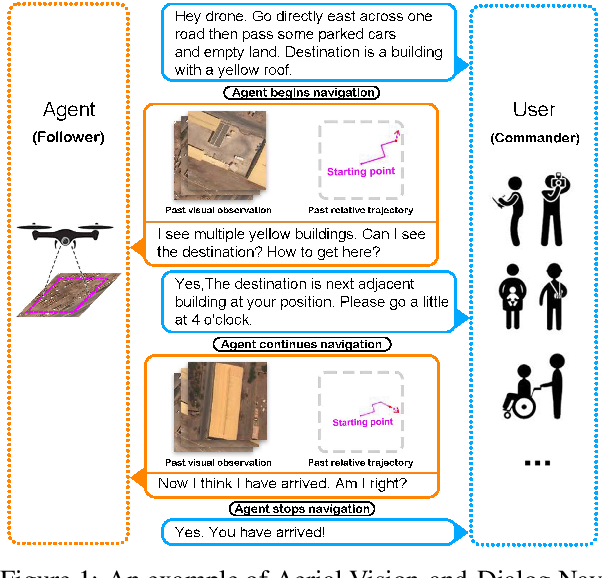
Figure 1 from Aerial Vision-and-Dialog Navigation | Semantic Scholar
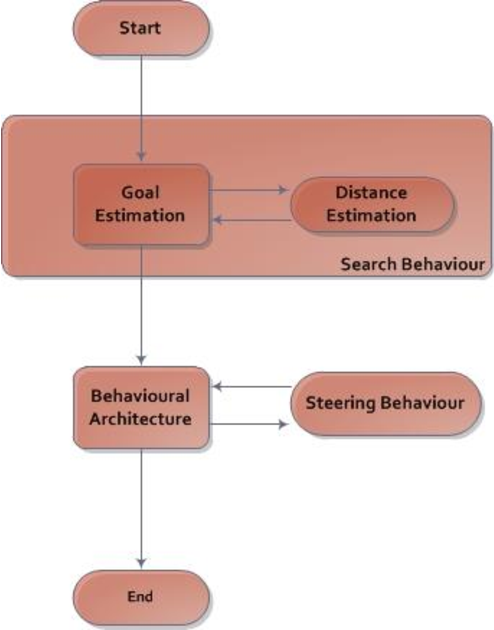
Figure 1 from A Goal Oriented Navigation System Using Vision | Semantic ...

Figure 1 from Iterative Vision-and-Language Navigation | Semantic Scholar

Figure 1 from Aerial Vision-and-Dialog Navigation | Semantic Scholar
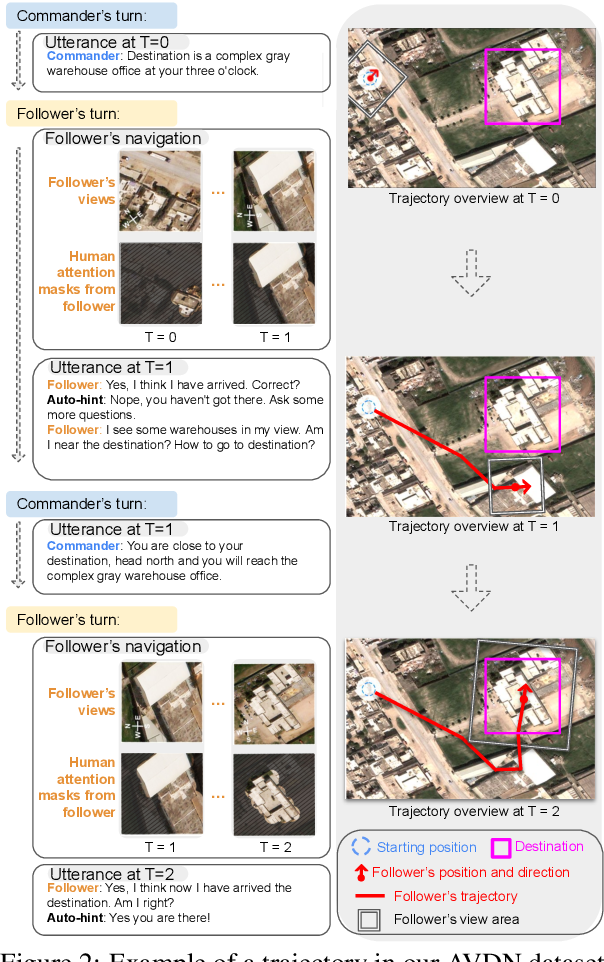
Figure 1 from Aerial Vision-and-Dialog Navigation | Semantic Scholar

Figure 1 from Dialog generation for voice browsing | Semantic Scholar
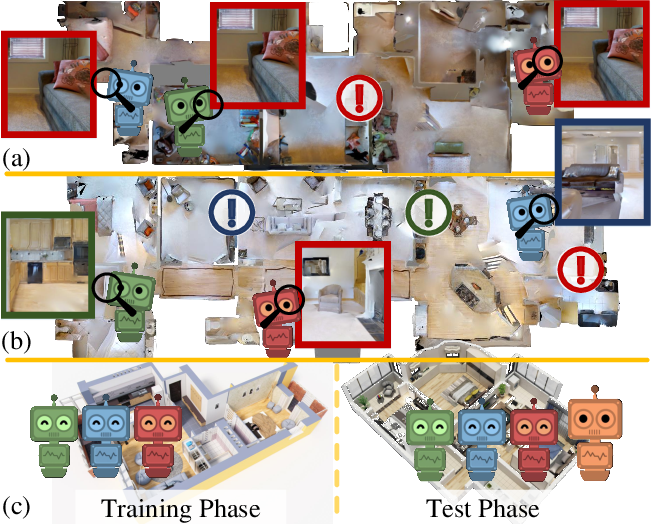
Figure 1 from Collaborative Visual Navigation | Semantic Scholar
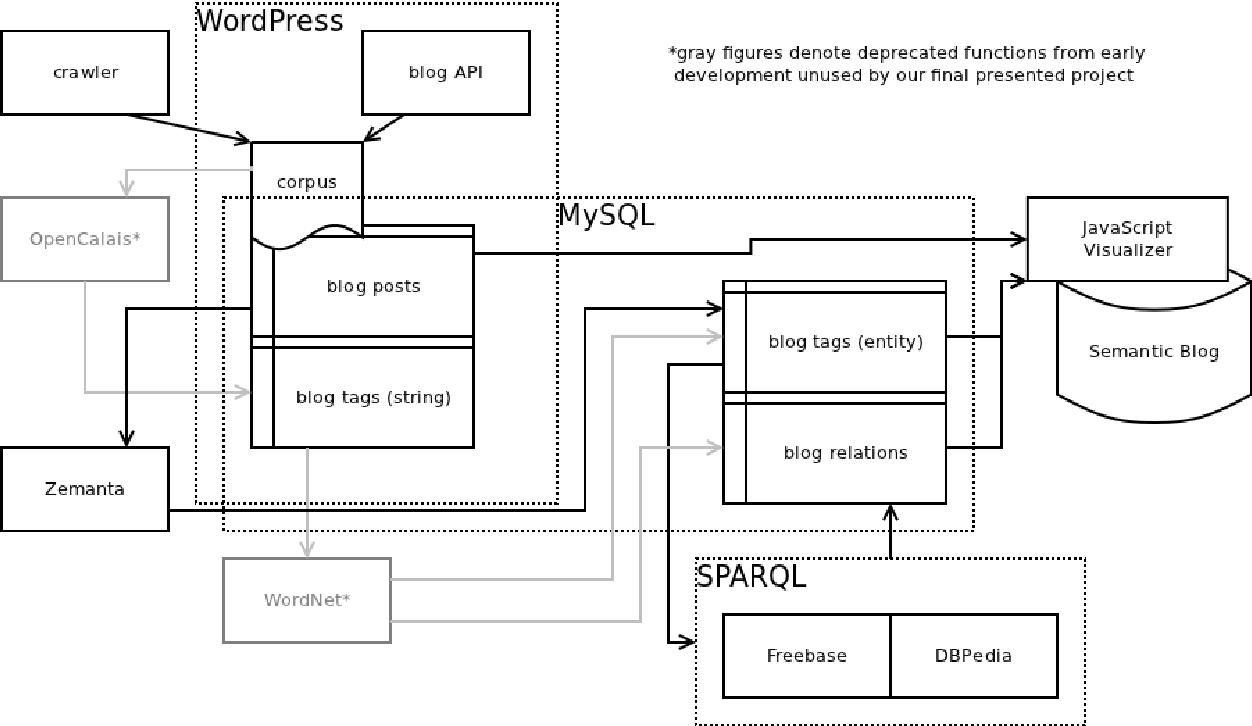
Figure 1 from Navigation via Semantic Analysis | Semantic Scholar
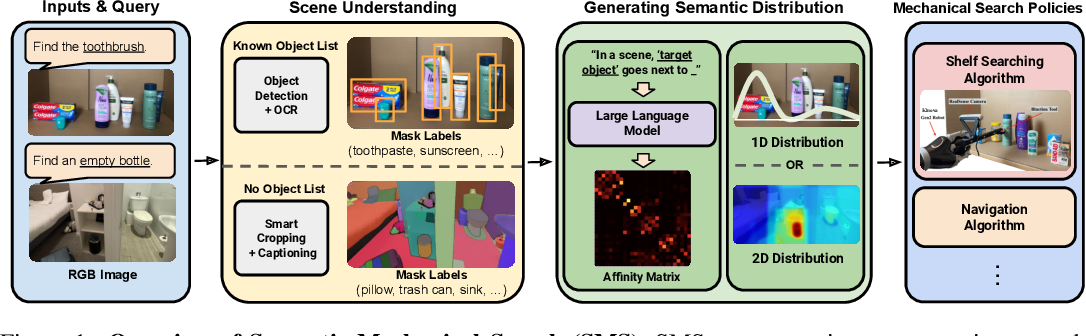
Figure 1 from Semantic Mechanical Search with Large Vision and Language ...
Advertisement Space (300x250)

Figure 1 from Unified Vision and Language Prompt Learning | Semantic ...

Figure 1 from Optical Flow For Vision-Aided Navigation | Semantic Scholar

Figure 1 from Aerial Vision-and-Dialog Navigation | Semantic Scholar
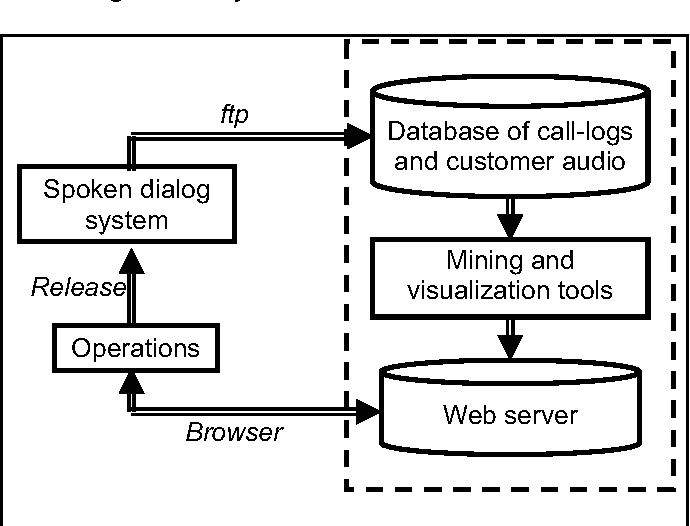
Figure 1 from Dialog trajectory analysis | Semantic Scholar
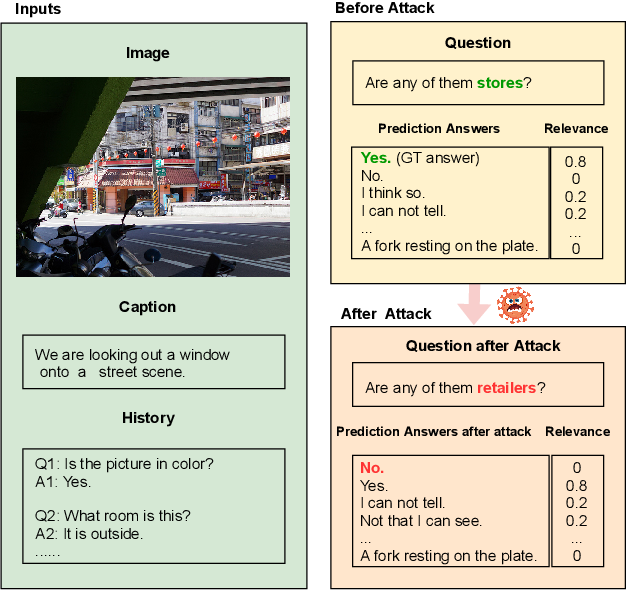
Figure 1 from Adversarial Robustness of Visual Dialog | Semantic Scholar
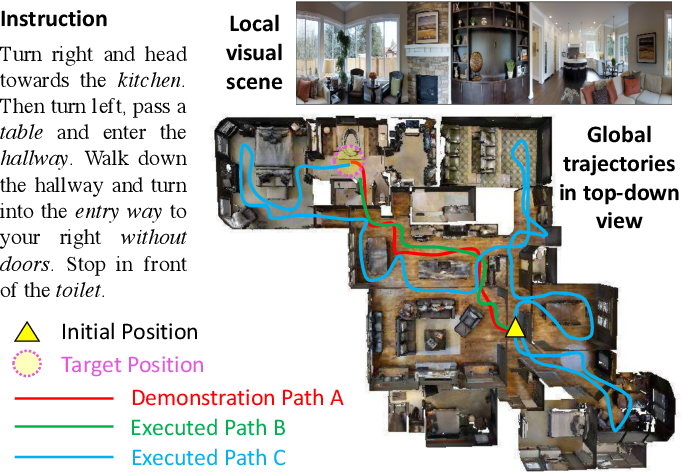
Figure 1 from Vision-Language Navigation Policy Learning and Adaptation ...
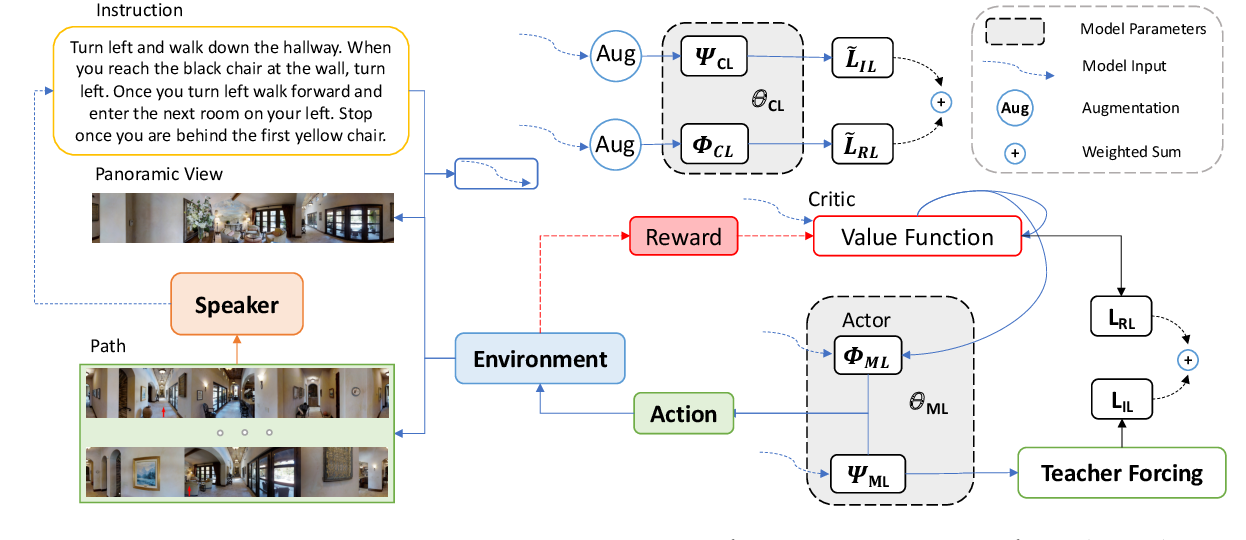
Figure 1 from Anticipating the Unseen Discrepancy for Vision and ...
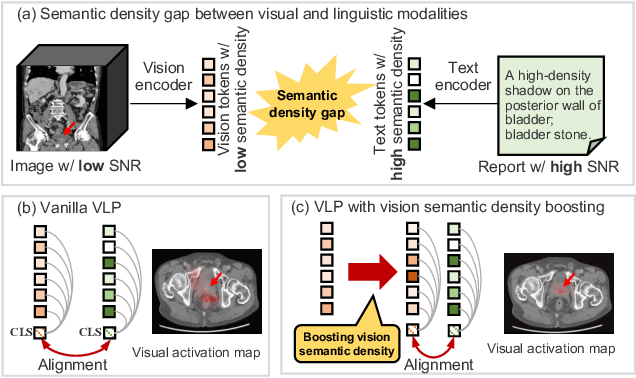
Figure 1 from Boosting Vision Semantic Density with Anatomy Normality ...
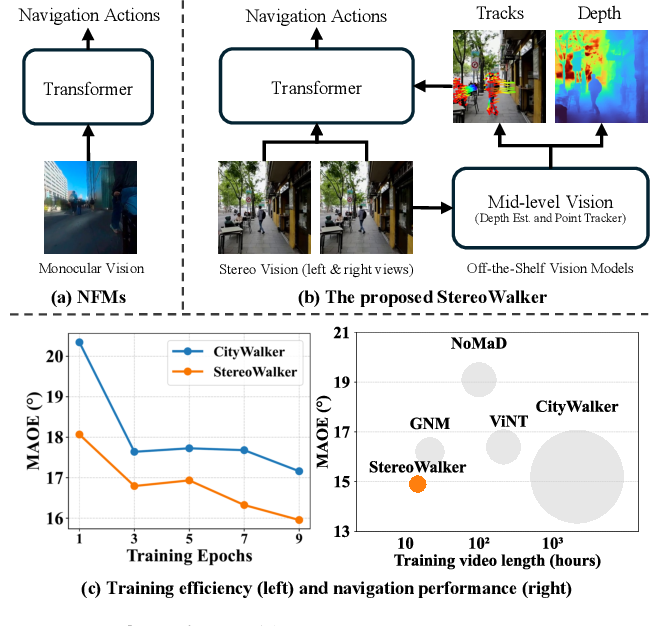
Figure 1 from Empowering Dynamic Urban Navigation with Stereo and Mid ...
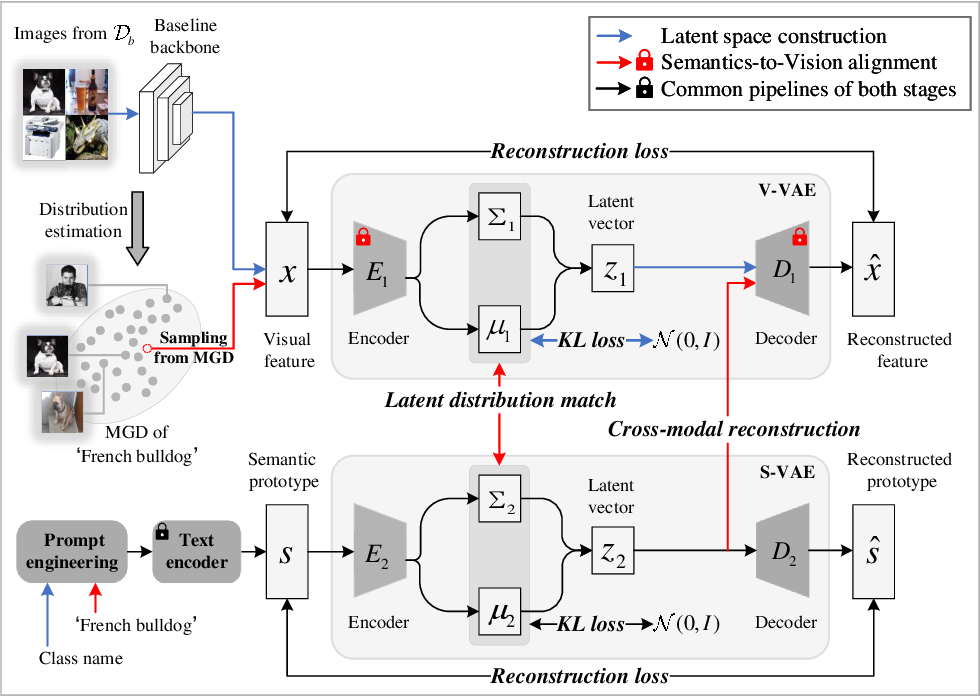
Figure 1 from Better Integrating Vision and Semantics for Improving Few ...
Advertisement Space (336x280)
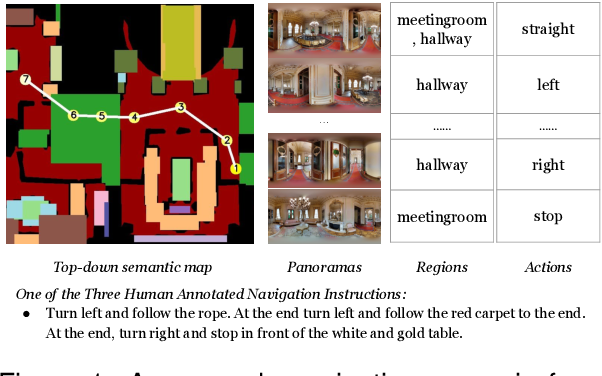
Figure 1 from Semantic Map-based Generation of Navigation Instructions ...

Figure 1 from Using Utterance and Semantic Level Confidence for ...

Figure 1 from UNIT: Unifying Image and Text Recognition in One Vision ...

Figure 1 from A Survey on Robot Semantic Navigation Systems for Indoor ...
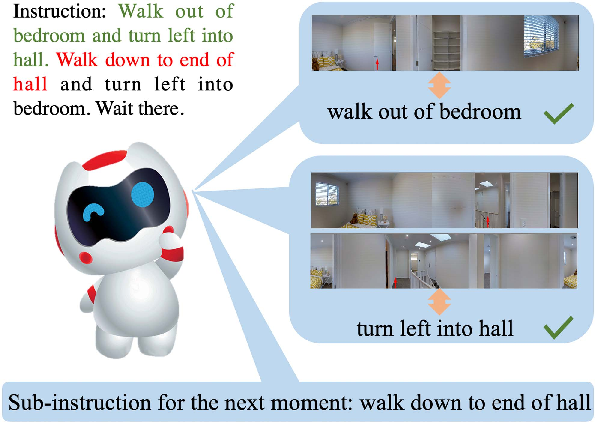
Figure 1 from Vision-and-Language Navigation via Latent Semantic ...

Figure 1 from Navigating to Objects Specified by Images | Semantic Scholar

Figure 1 from Diagnosing and Rectifying Vision Models using Language ...
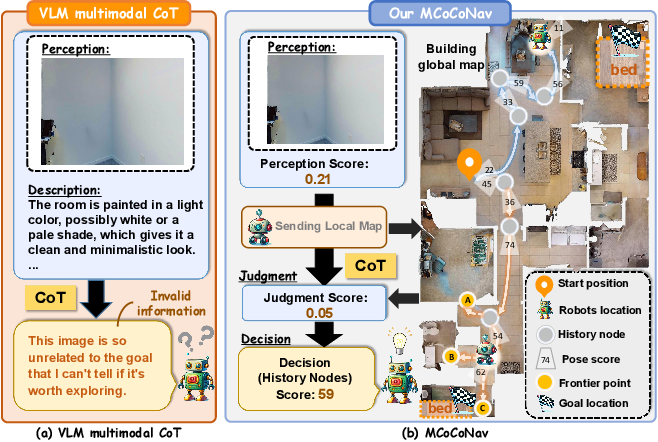
Figure 1 from Enhancing Multi-Robot Semantic Navigation Through ...
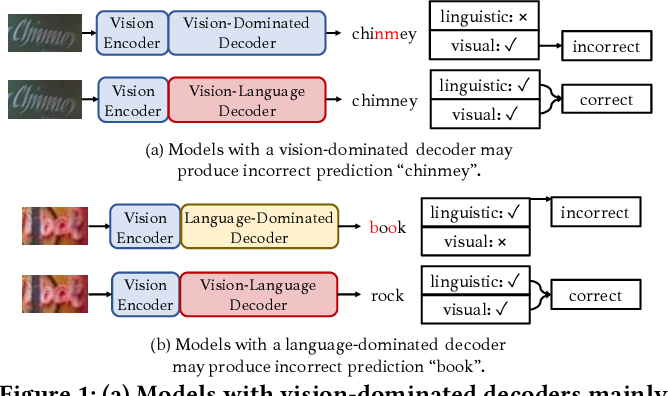
Figure 1 from VL-Reader: Vision and Language Reconstructor is an ...
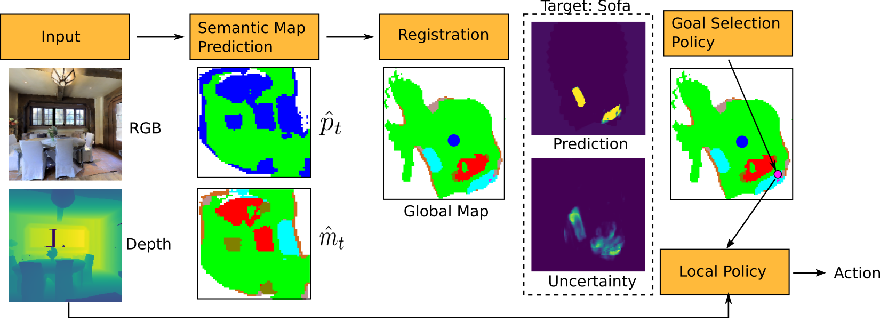
Figure 1 from Learning to Map for Active Semantic Goal Navigation ...
Advertisement Space (336x280)
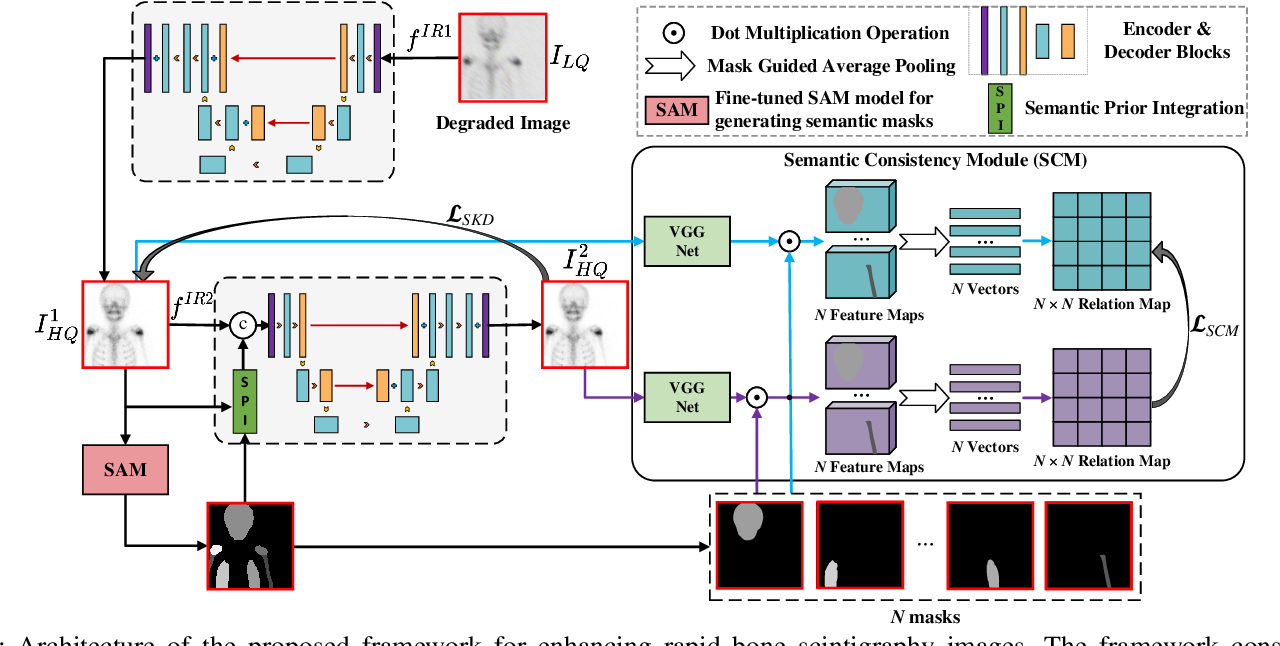
Figure 1 from Semantic Prior Distillation with Vision Foundation Model ...

Figure 1 from Adversarial Vision Transformer for Medical Image Semantic ...
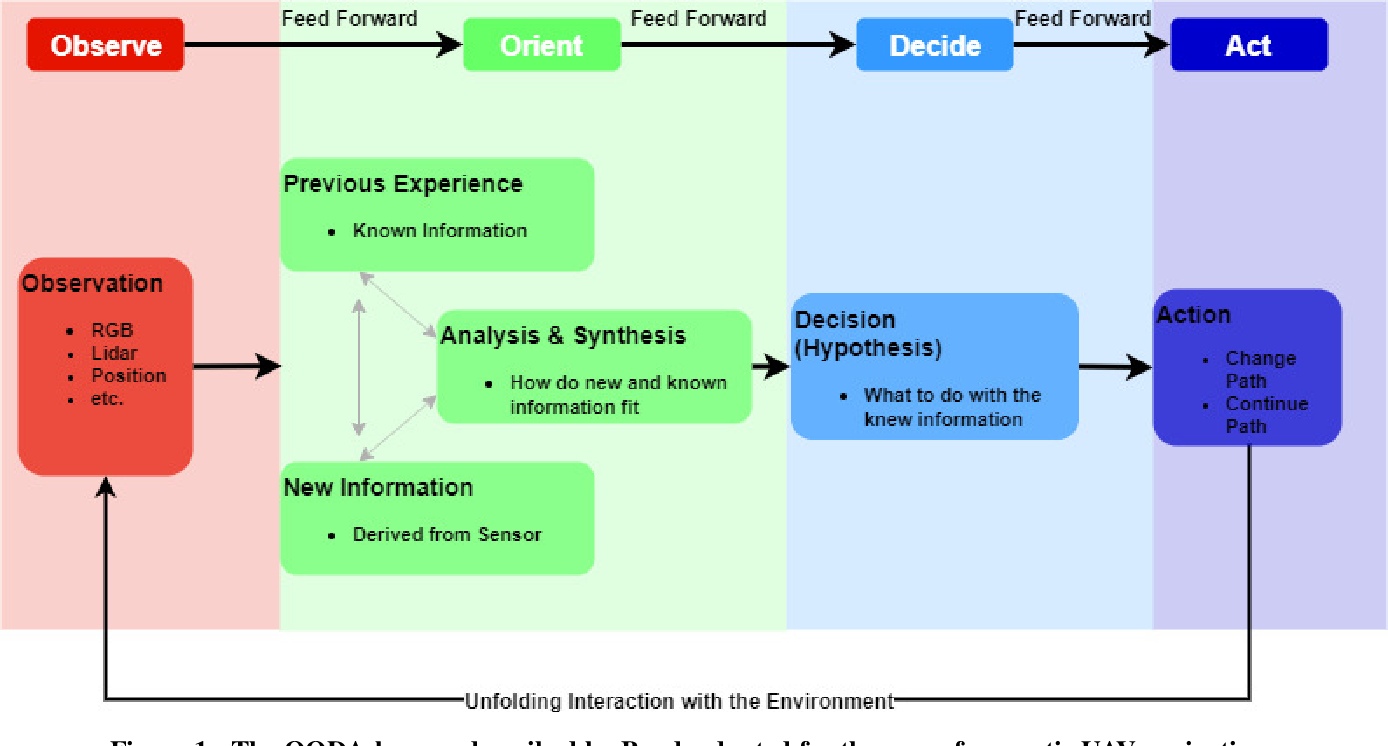
Figure 1 from Towards Simulating Semantic Onboard UAV Navigation ...
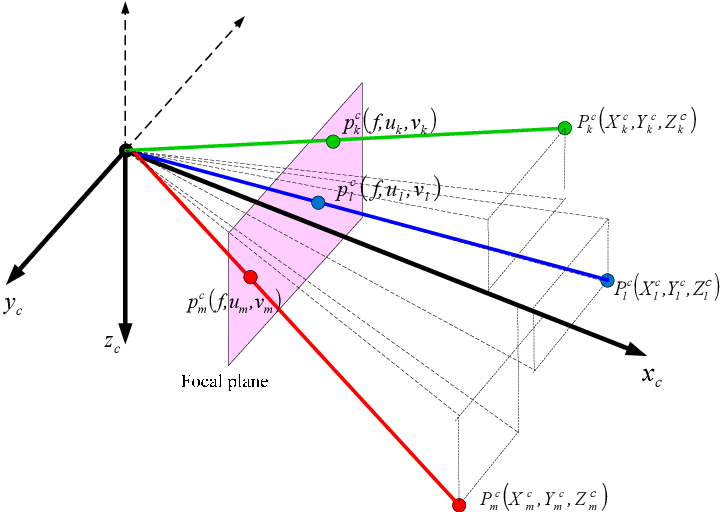
Figure 1 from Vision/INS Integrated Navigation System for Poor Vision ...
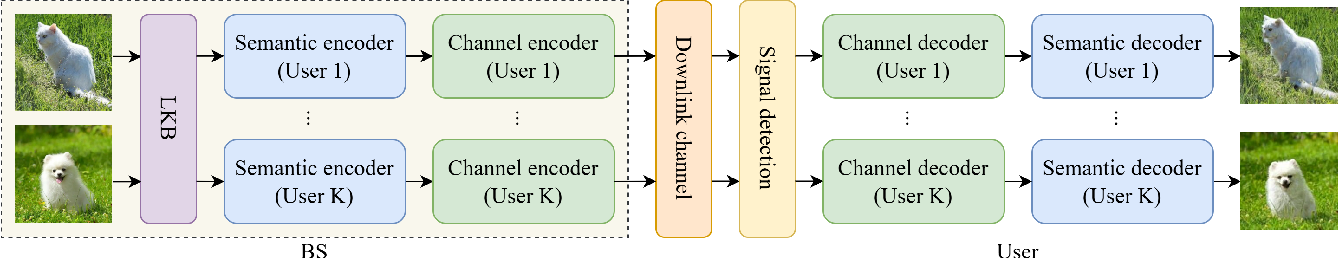
Figure 1 from Lightweight Vision Model-based Multi-user Semantic ...
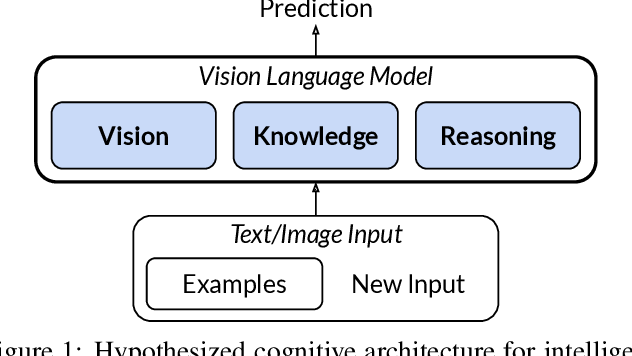
Figure 1 from Analyzing the Roles of Language and Vision in Learning ...