
Figure 1 From Vision Encoder Decoder Models For Ai Coaching Semantic
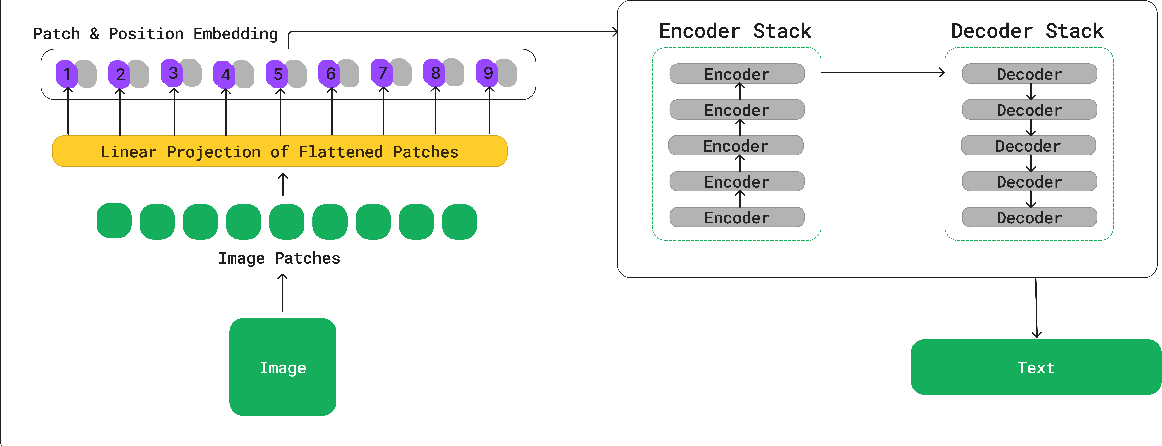
Figure 1 from Vision Encoder-Decoder Models for AI Coaching | Semantic ...

Figure 1 from Graph Based Semantic Encoder Decoder Framework for Task ...

Figure 1 from Unveiling Encoder-Free Vision-Language Models | Semantic ...
[2311.16161] Vision Encoder-Decoder Models for AI Coaching
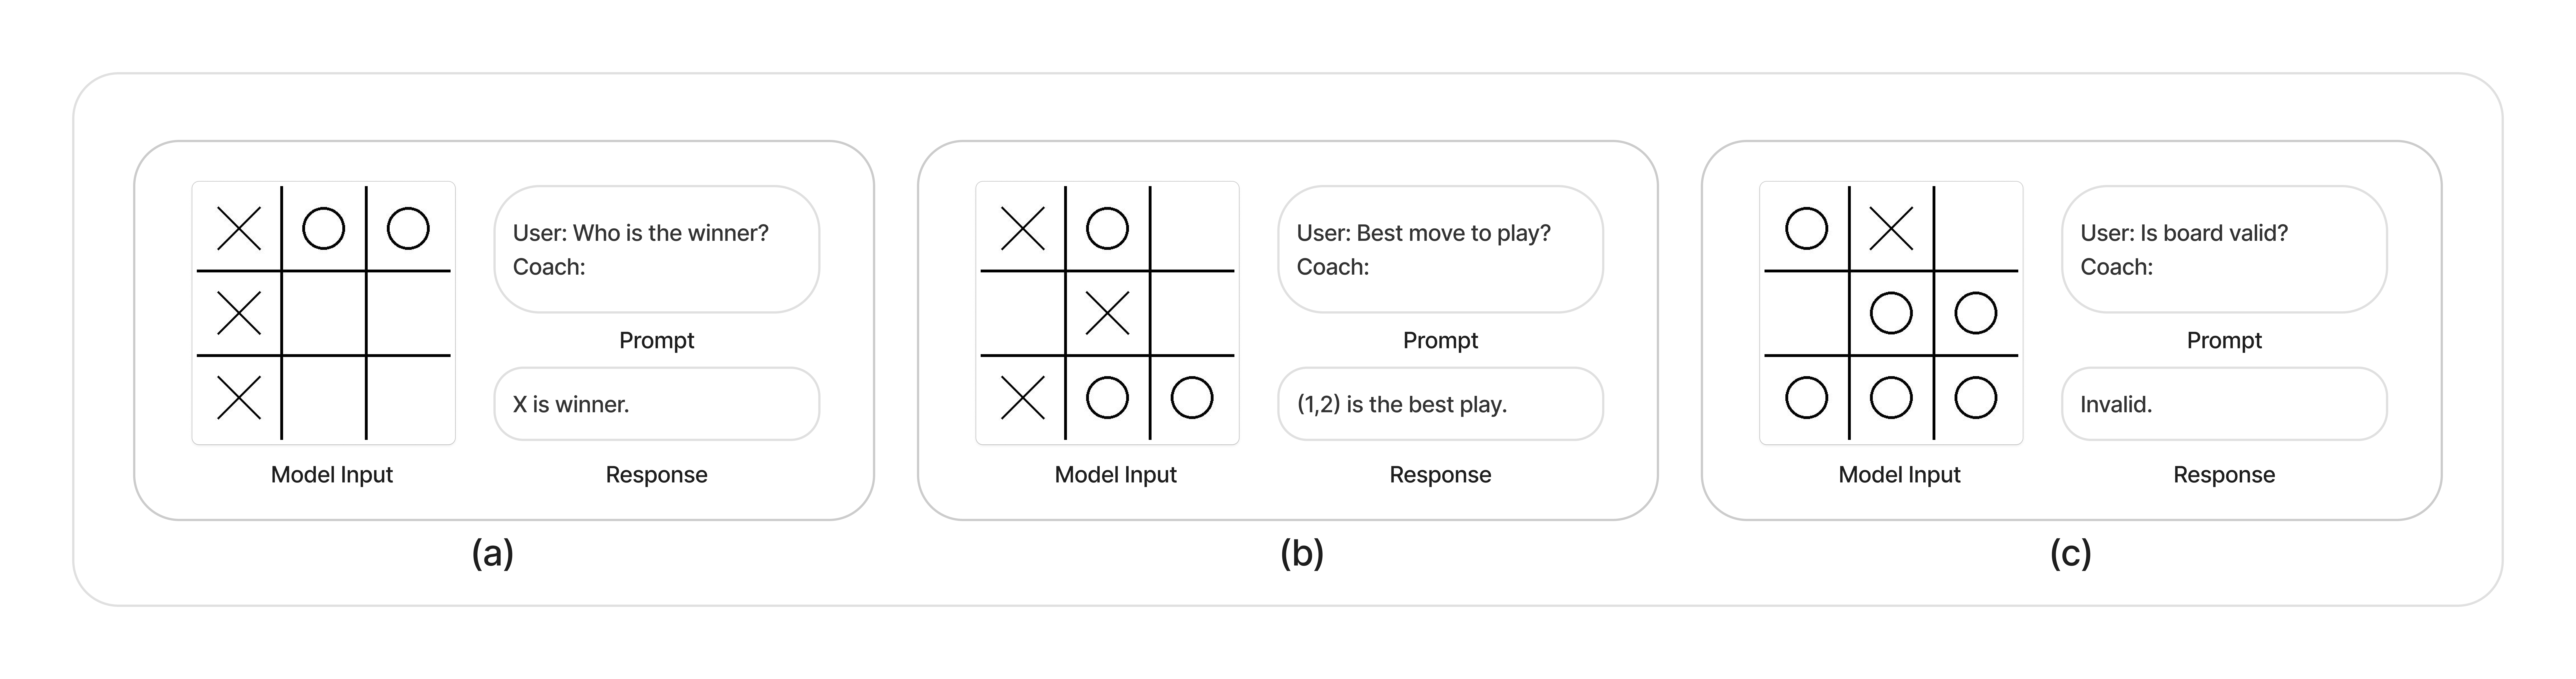
[2311.16161] Vision Encoder-Decoder Models for AI Coaching

Figure 1 from VCoder: Versatile Vision Encoders for Multimodal Large ...

Figure 1 from A Comparative Evaluation of Transformer-Based Vision ...

Figure 1 from Bengali Image Captioning Using Vision Encoder-Decoder ...

Figure 1.1 from Vision Encoders in Visual Question Answering | Semantic ...

Figure 1.1 from Vision Encoders in Visual Question Answering | Semantic ...
Advertisement Space (300x250)

Figure 1 from A Single Transformer for Scalable Vision-Language ...

Figure 1 from Diagnosing the Compositional Knowledge of Vision Language ...
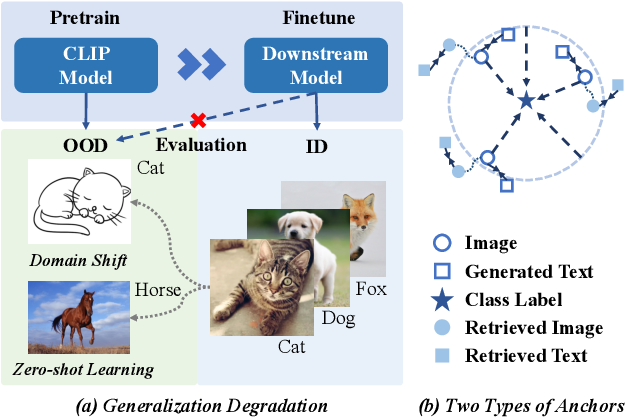
Figure 1 from Anchor-based Robust Finetuning of Vision-Language Models ...

Figure 3 from Interpreting vision and language generative models with ...

Figure 1 from Semantic-visual Guided Transformer for Few-shot Class ...
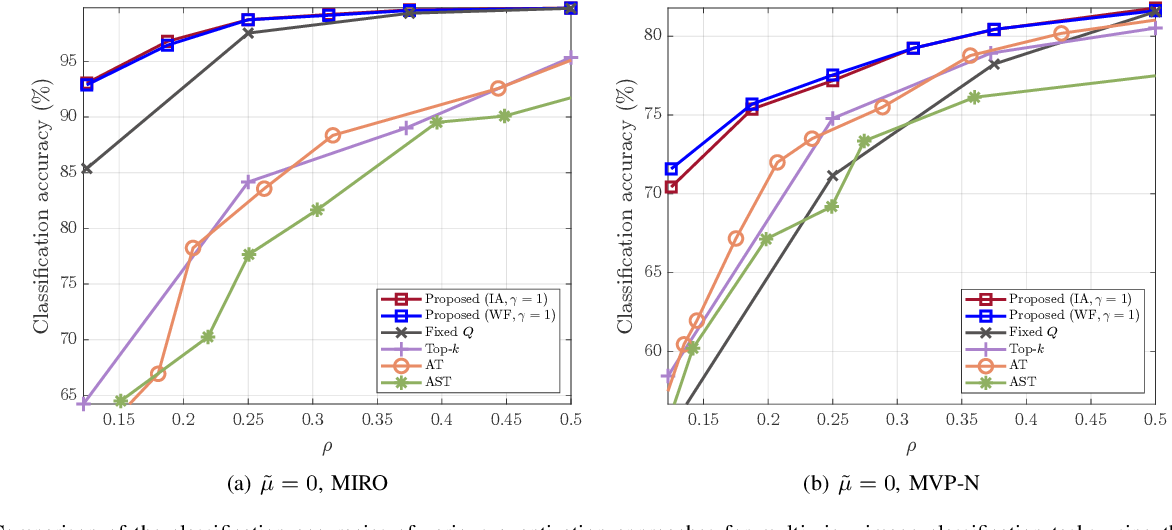
Figure 4 from Vision Transformer-Based Semantic Communications With ...

Figure 1 from Semantic-visual Guided Transformer for Few-shot Class ...

Figure 1 from Scheduled Sampling in Vision-Language Pretraining with ...

Figure 1 from A Vision-Language Pre-training model based on Cross ...

Figure 2 from Bengali Image Captioning Using Vision Encoder-Decoder ...
Advertisement Space (336x280)

Figure 1 from Instruction-Following Agents with Jointly Pre-Trained ...
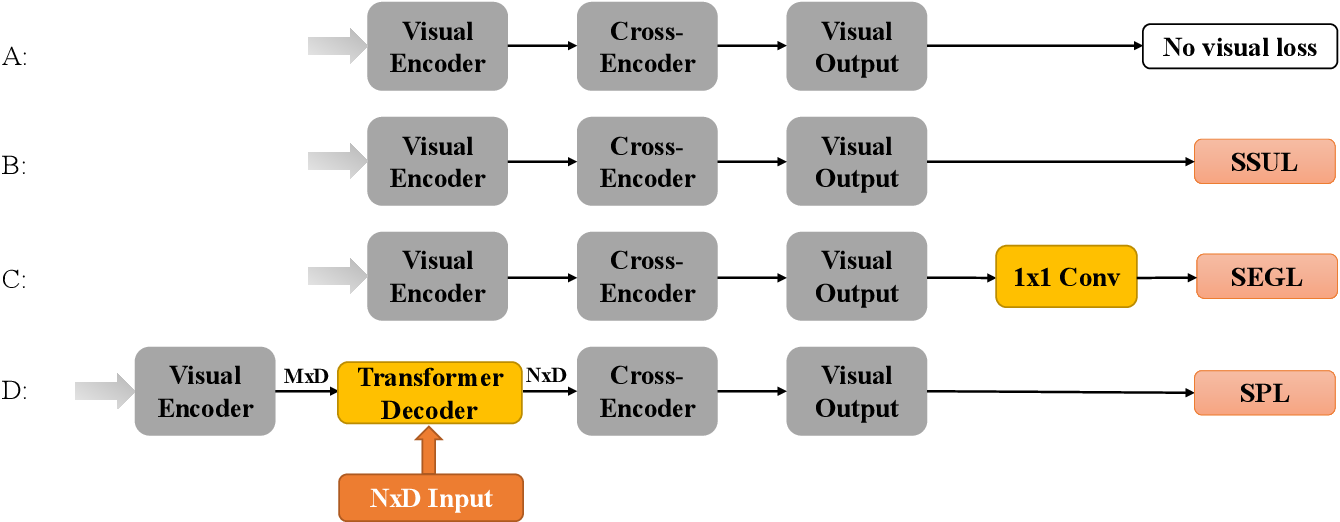
Figure 4 from Effective End-to-End Vision Language Pretraining With ...

Figure 1 from Enhancing Vision-Language Model with Unmasked Token ...
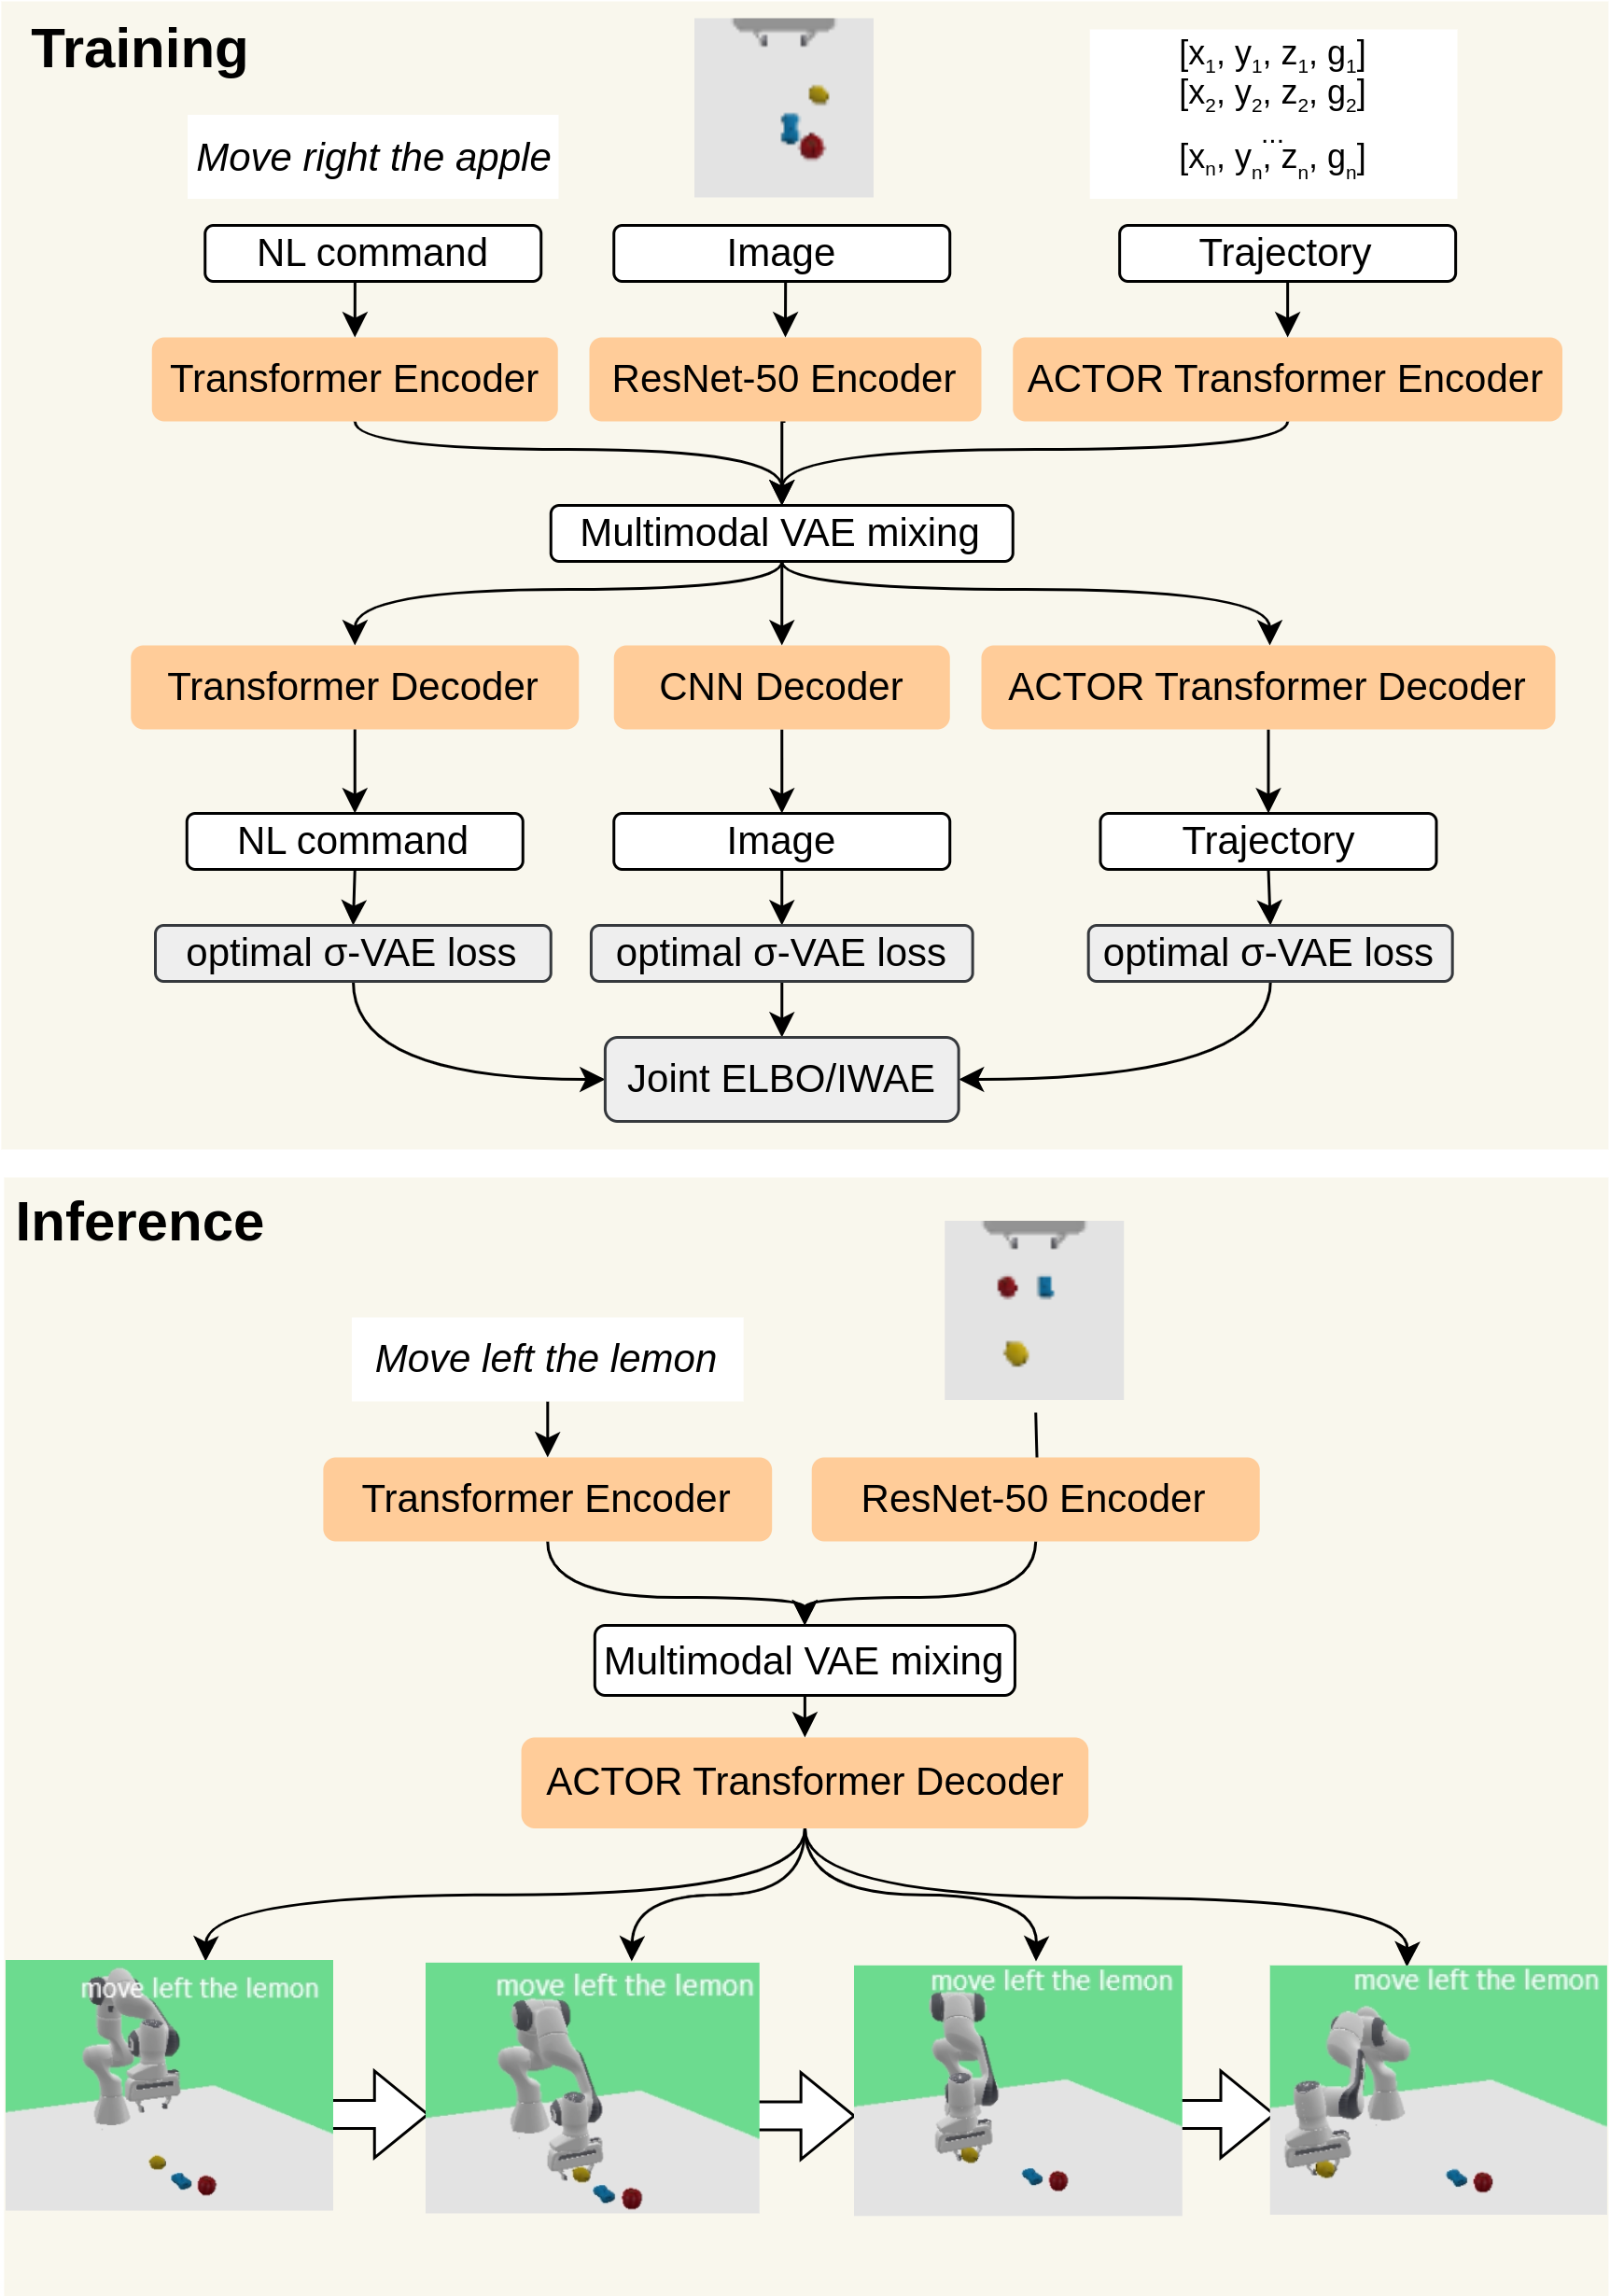
A Survey on Vision-Language-Action Models for Embodied AI | AI Research ...

Figure 1 from Revisiting Classifier: Transferring Vision-Language ...

[논문 리뷰] An Efficient and Effective Encoder Model for Vision and ...

Figure 1 from Investigating Compositional Challenges in Vision-Language ...
Image to Text Analysis using Vision Encoder Decoder Model | by ...

Figure 1 from Attention Visualizer Package: Revealing Word Importance ...

Harnessing the Power of Pre-Trained Models for Efficient Semantic ...
Advertisement Space (336x280)
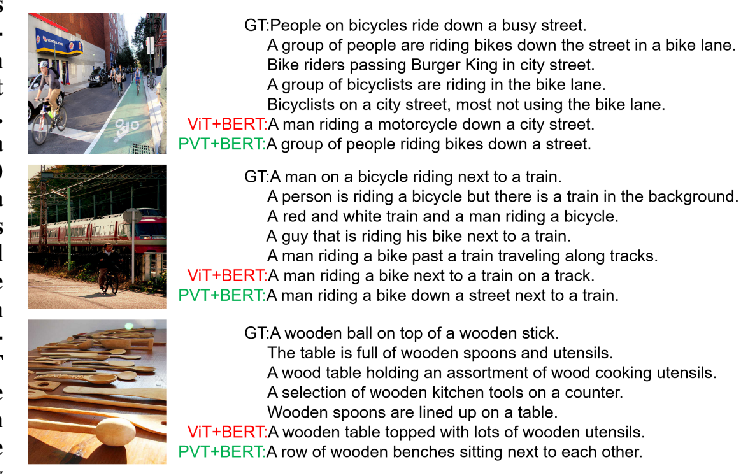
Figure 1 from Research on Image Captioning Based on Vision-language Pre ...

Vision Language Models as Values Detectors | AI Research Paper Details
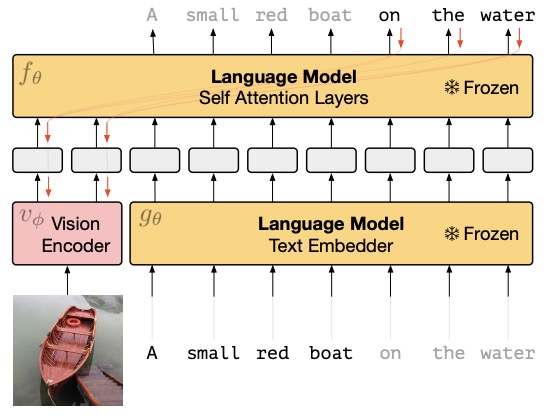
Aman's AI Journal • Primers • Overview of Vision-Language Models
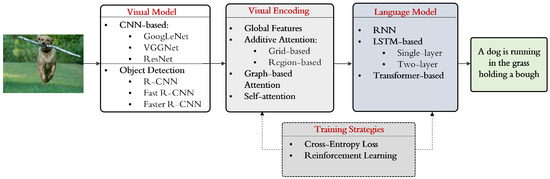
A Systematic Literature Review on Using the Encoder-Decoder Models for ...

Demystifying Ai Models Encoders Decoders And Embeddings Omegatypes Of ...

A Systematic Literature Review on Using the Encoder-Decoder Models for ...