
Figure 1 From Visual Context Embeddings For Zero Shot Recognition

Figure 1 from Visual context embeddings for zero-shot recognition ...
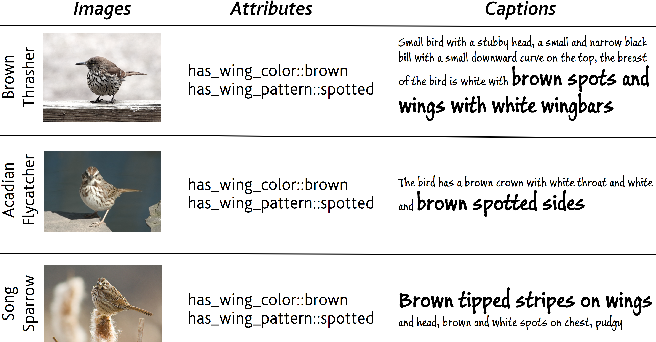
Figure 1 from Semantically Grounded Visual Embeddings for Zero-Shot ...

Figure 1 from Harmonizing Visual and Textual Embeddings for Zero-Shot ...
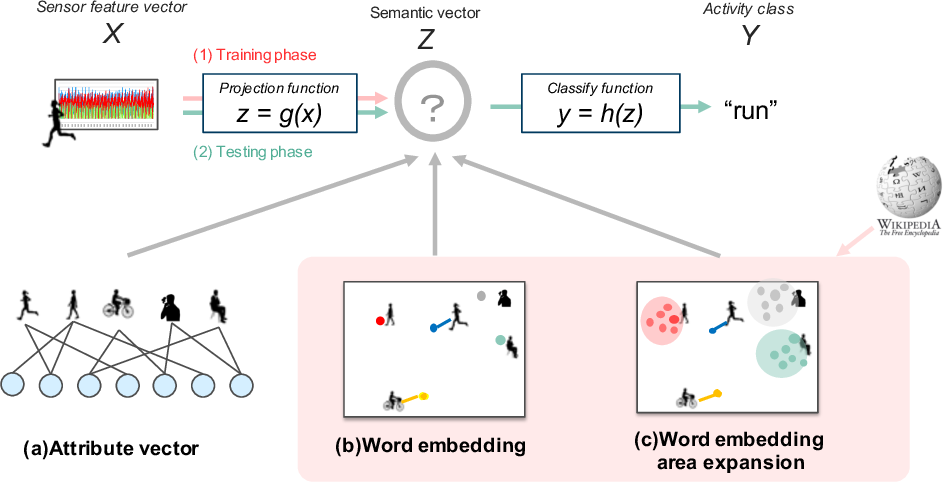
Figure 1 from Characterizing Word Embeddings for Zero-Shot Sensor-Based ...
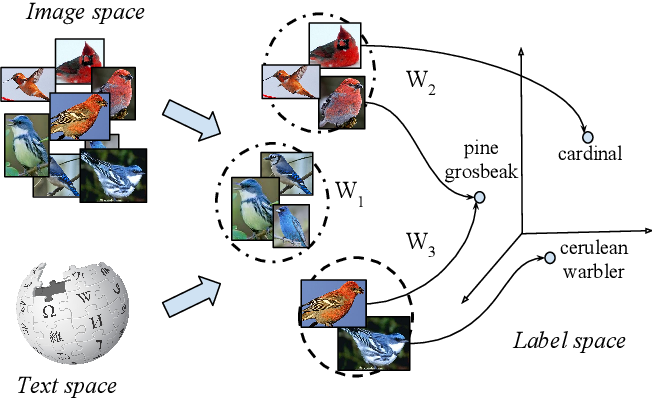
Figure 1 from Latent Embeddings for Zero-Shot Classification | Semantic ...

Figure 1 from Enhancing Visual Embeddings through Weakly Supervised ...

Figure 1 from Data Augmentation of Semantic Embeddings for Skeleton ...

Figure 1 from Efficient Zero-shot Visual Search via Target and Context ...

Figure 1 from Learning Graph Embeddings for Open World Compositional ...

Figure 1 from Learning Graph Embeddings for Compositional Zero-shot ...
Advertisement Space (300x250)

Figure 1 from Learning Adversarial Semantic Embeddings for Zero-Shot ...
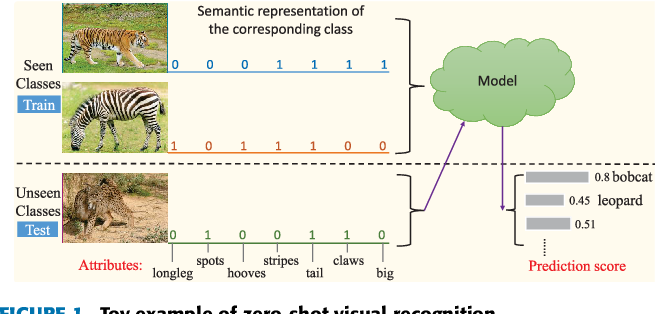
Figure 1 from Zero-Shot Visual Recognition via Semantic Attention-Based ...

Figure 1 from Visual Space Optimization for Zero-shot Learning ...

Figure 1 from Spatial-Aware Object Embeddings for Zero-Shot ...

Figure 1 from Exploring synonyms as context in zero-shot action ...

Figure 1 from Zero-Shot Learning with Knowledge Enhanced Visual ...

Figure 1 from Aligned Dynamic-Preserving Embedding for Zero-Shot Action ...

Figure 1 from Visual Language Based Succinct Zero-Shot Object Detection ...

Figure 1 from Semantic Compression Embedding for Generative Zero-Shot ...

Figure 1 from Zero-Shot Action Recognition by Word-Vector Embedding ...
Advertisement Space (336x280)
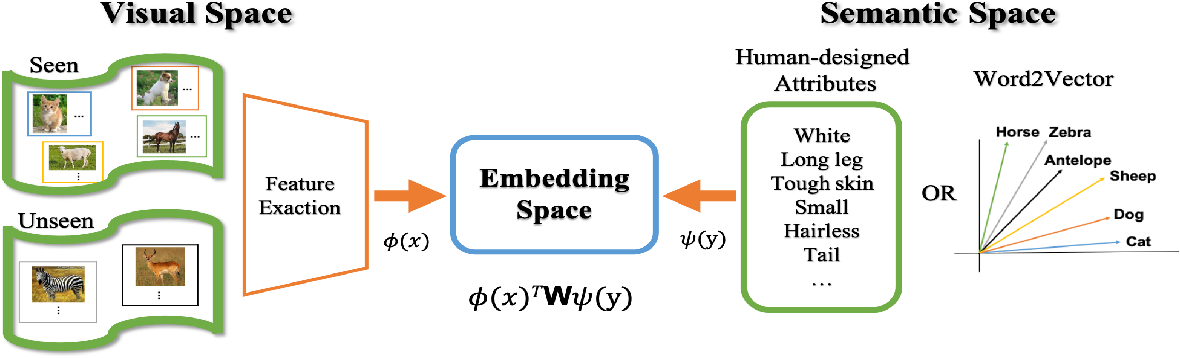
Figure 1 from Zero-shot Recognition with Image Attributes Generation ...
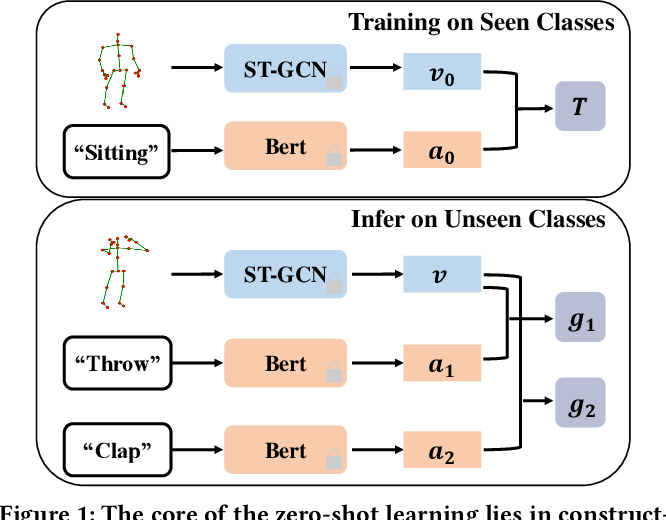
Figure 1 from Zero-shot Skeleton-based Action Recognition via Mutual ...

Figure 1 from Zero-Shot Recognition Using Dual Visual-Semantic Mapping ...

Figure 1 from From Saturation to Zero-Shot Visual Relationship ...
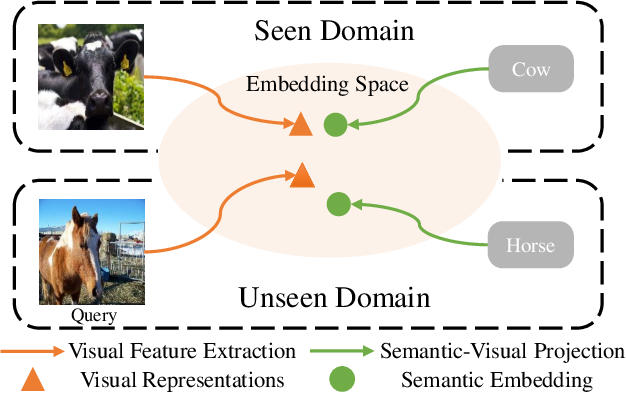
Figure 1 from Domain-Specific Embedding Network for Zero-Shot ...

Figure 1 from Generalized Zero-Shot Recognition Through Image-Guided ...

Figure 1 from Generalized Zero-Shot Activity Recognition with Embedding ...

Figure 1 from Context-Aware Zero-Shot Recognition | Semantic Scholar
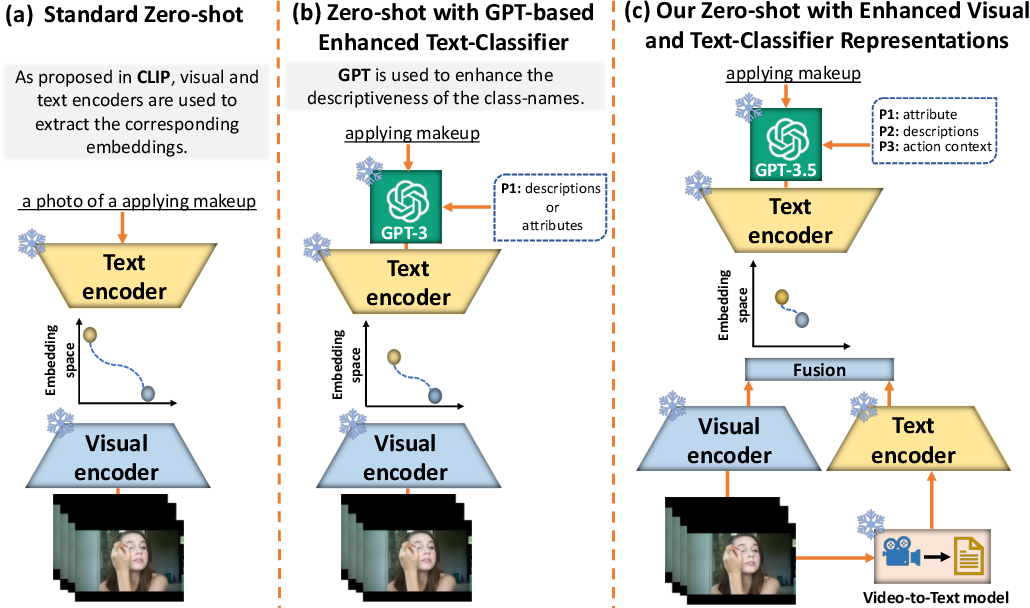
Figure 1 from Videoprompter: an ensemble of foundational models for ...
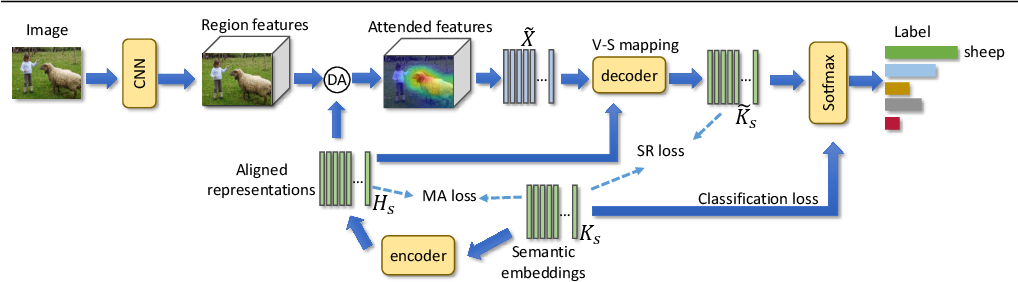
Figure 1 from Joint Learning of Attended Zero-Shot Features and Visual ...
Advertisement Space (336x280)

Figure 1 from Semantic-guided Reinforced Region Embedding for ...
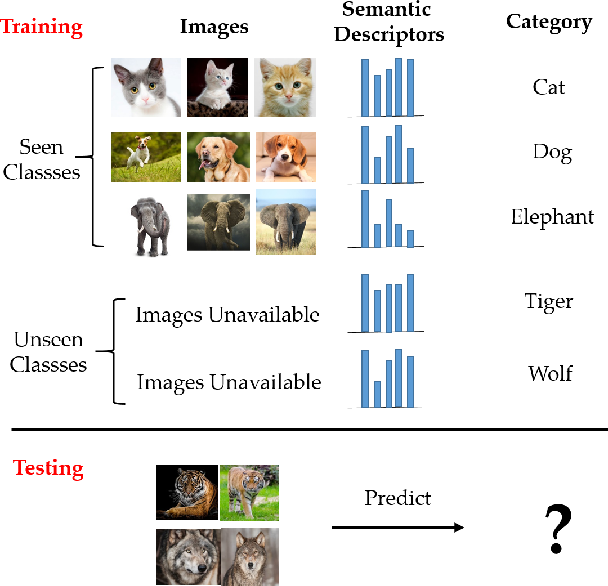
Figure 1 from Zero-shot Image Recognition Using Relational Matching ...
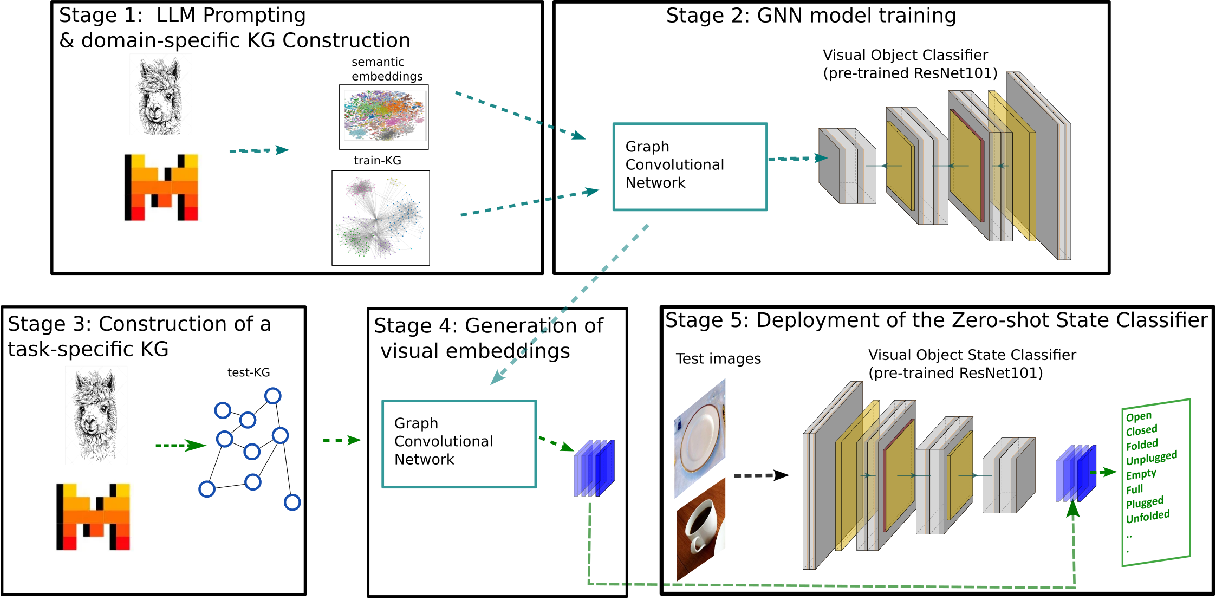
Figure 1 from LLM-aided Knowledge Graph construction for Zero-Shot ...

Figure 1 from Hierarchical Prompt Learning for Compositional Zero-Shot ...

Figure 1 from Zero-shot Object Detection Through Vision-Language ...

Figure 1 from Zero-Shot Semantic Segmentation via Spatial and Multi ...