
Figure 1 From Visual Grounding With Transformers Semantic Scholar

Figure 1 from Visual Grounding with Transformers | Semantic Scholar

Figure 1 from Visual Grounding with Transformers | Semantic Scholar

Figure 1 from Visual Grounding with Transformers | Semantic Scholar

Figure 1 from TransVG: End-to-End Visual Grounding with Transformers ...
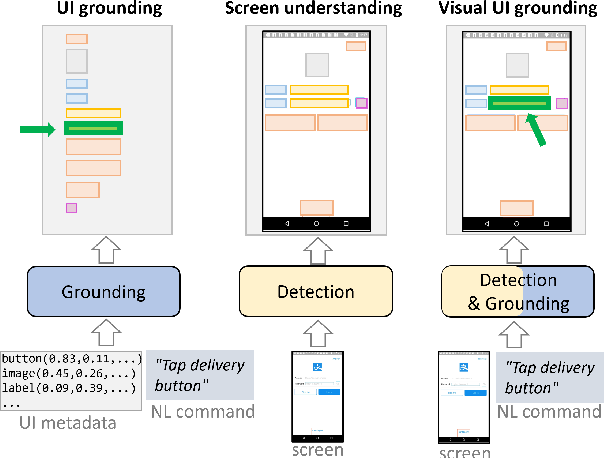
Figure 1 from Visual Grounding for User Interfaces | Semantic Scholar

Figure 1 from Revisiting Visual Grounding | Semantic Scholar

Figure 1 from Visual Grounding Via Accumulated Attention | Semantic Scholar
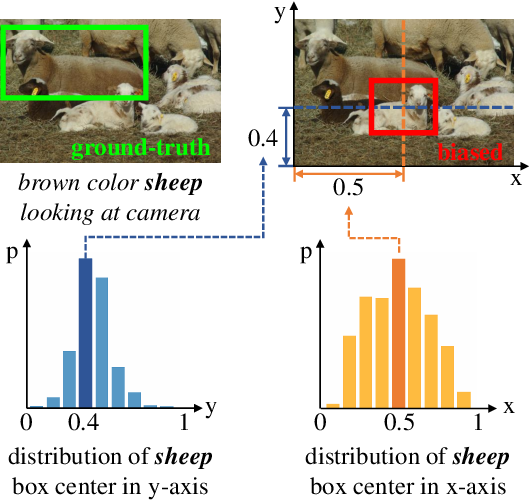
Figure 1 from Deconfounded Visual Grounding | Semantic Scholar

Figure 1 from Visual Grounding with Feature Enhancement and Language ...
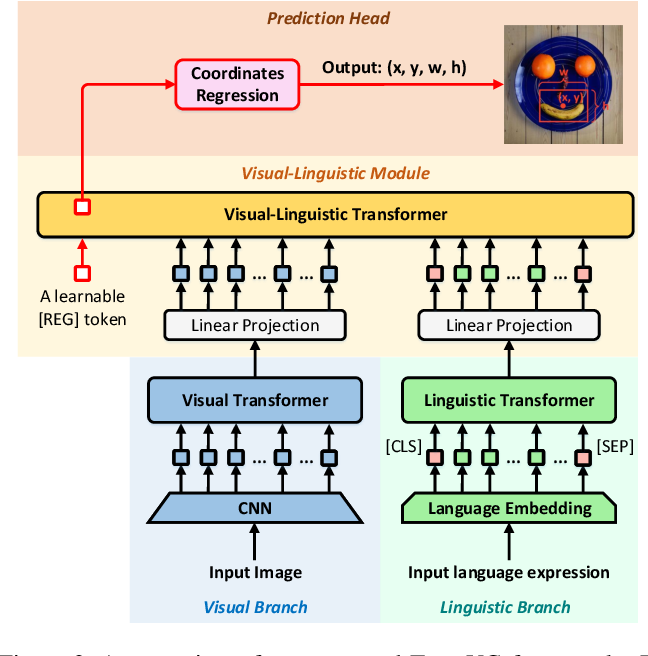
Figure 2 from TransVG: End-to-End Visual Grounding with Transformers ...
Advertisement Space (300x250)
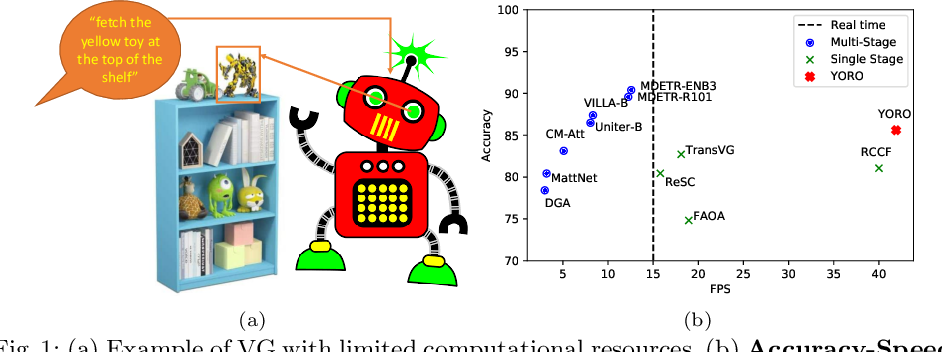
Figure 1 from YORO - Lightweight End to End Visual Grounding | Semantic ...

Figure 1 from Multi-Grained Alignment for Visual Grounding | Semantic ...

Figure 1 from Improving Visual Grounding with Visual-Linguistic ...
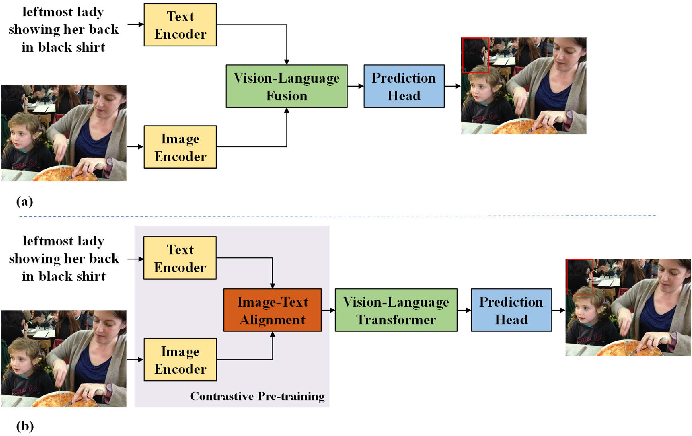
Figure 1 from Visual Grounding With Joint Multimodal Representation and ...
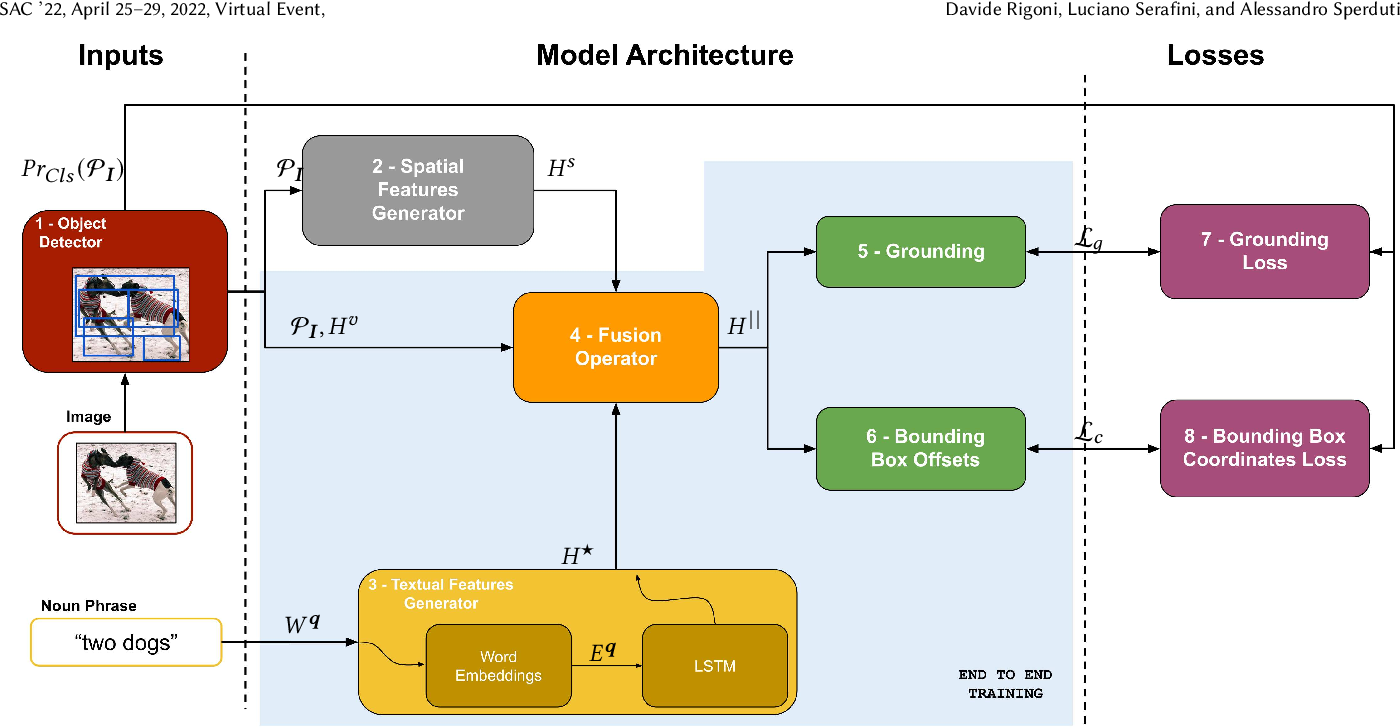
Figure 1 from A better loss for visual-textual grounding | Semantic Scholar

Figure 1 from Cycle-Consistent Weakly Supervised Visual Grounding With ...

Figure 1 from Grounding Visual Representations with Texts for Domain ...

Figure 1 from Visual Grounding of Learned Physical Models | Semantic ...

Figure 1 from Multi-View Transformer for 3D Visual Grounding | Semantic ...

Figure 1 from Iterative Robust Visual Grounding with Masked Reference ...
Advertisement Space (336x280)

Figure 1 from End-to-end visual grounding via region proposal networks ...

Figure 1 from LLaVA-Grounding: Grounded Visual Chat with Large ...
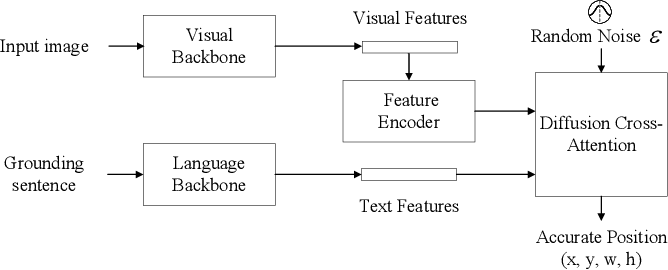
Figure 1 from Remote Sensing Visual Grounding through Diffusion Model ...
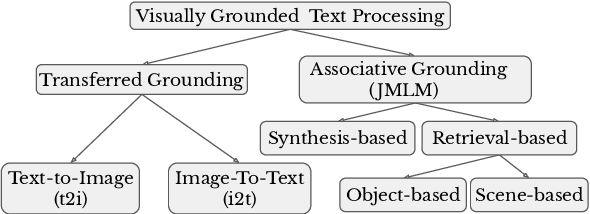
Figure 1 from Visual Grounding Strategies for Text-Only Natural ...

Figure 3 from Multi-View Transformer for 3D Visual Grounding | Semantic ...
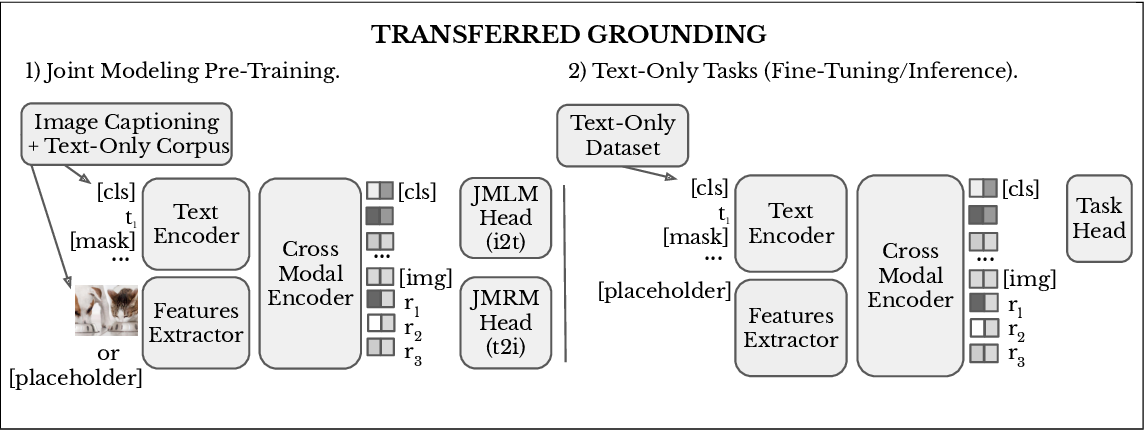
Figure 1 from Visual Grounding Strategies for Text-Only Natural ...

Figure 3 from Transformer-Based Visual Grounding with Cross-Modality ...
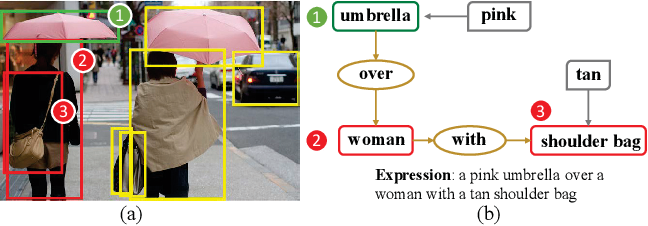
Figure 1 from Visual-Semantic Graph Matching for Visual Grounding ...

Figure 1 from SeCG: Semantic-Enhanced 3D Visual Grounding via Cross ...

Figure 1 from Measuring Faithful and Plausible Visual Grounding in VQA ...
Advertisement Space (336x280)

Figure 1 from End-to-End Visual Grounding Framework for Multimodal NER ...
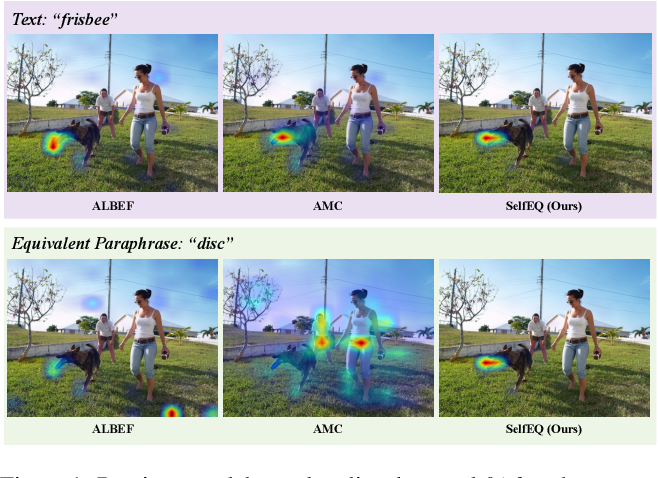
Figure 1 from Improved Visual Grounding through Self-Consistent ...

Figure 1 from Learning Visual Grounding from Generative Vision and ...

Figure 1 from Comprehensive Visual Grounding for Video Description ...
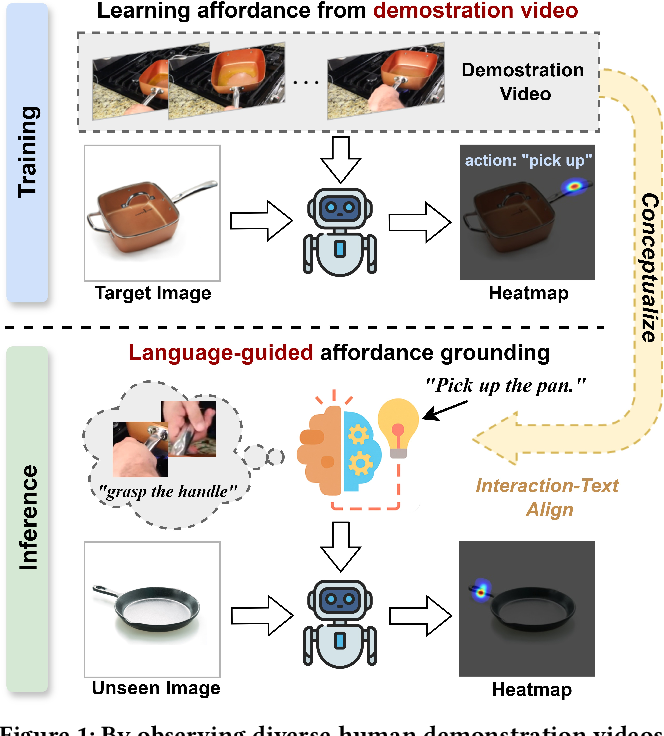
Figure 1 from Video-to-Image Affordance Grounding via Visual Conceptual ...
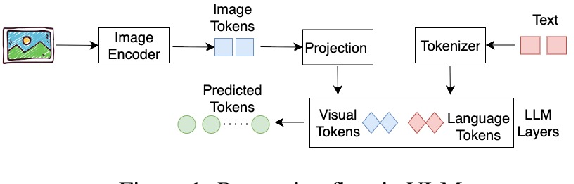
Figure 1 from Direct Visual Grounding by Directing Attention of Visual ...