
Figure 1 From Zero Shot Audio To Audio Emotion Transfer With Speaker
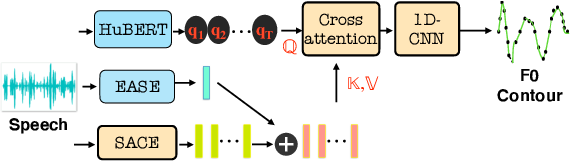
Figure 1 from Zero Shot Audio To Audio Emotion Transfer With Speaker ...
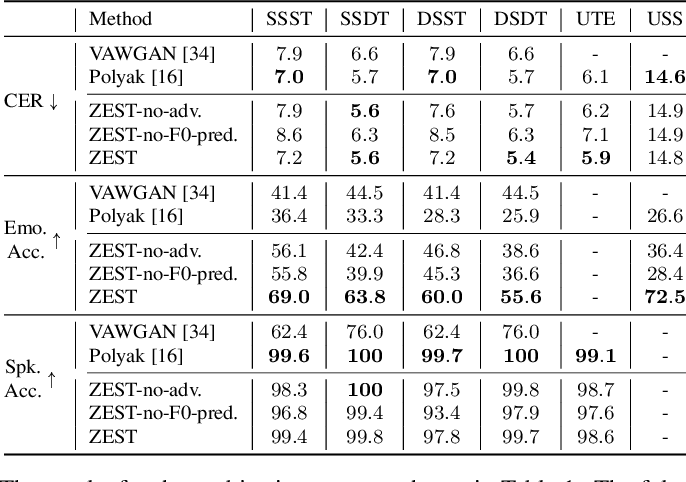
Table 1 from Zero Shot Audio To Audio Emotion Transfer With Speaker ...
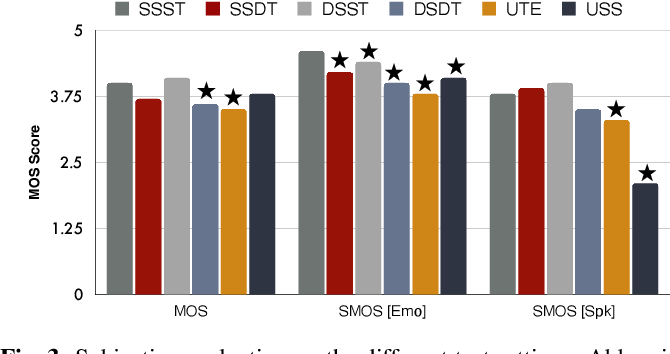
Figure 3 from Zero Shot Audio To Audio Emotion Transfer With Speaker ...

Figure 1 from Few-Shot Audio Classification with Attentional Graph ...

Figure 1 from Zero-Shot Audio Classification Via Semantic Embeddings ...
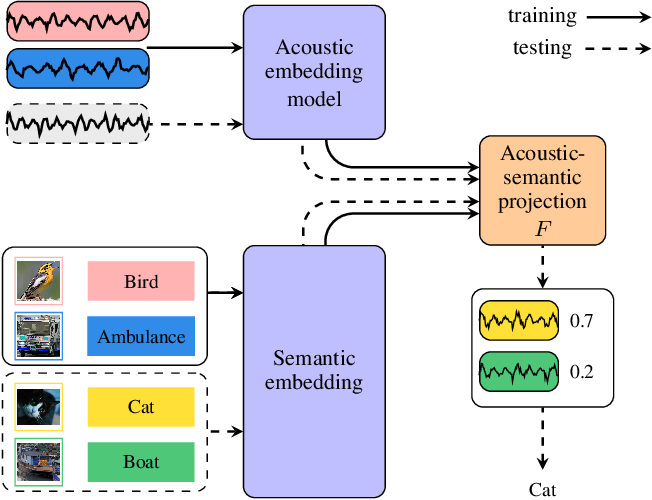
Figure 1 from Zero-Shot Audio Classification using Image Embeddings ...

Figure 1 from Zero-Shot Emotion Transfer for Cross-Lingual Speech ...
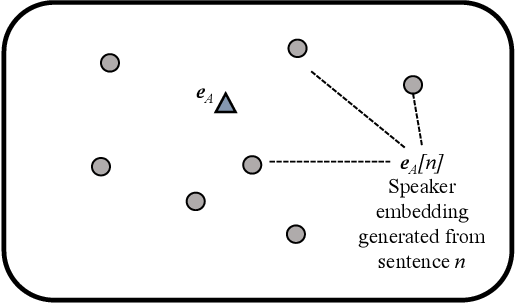
Figure 1 from Zero-Shot Voice Conversion with Adjusted Speaker ...
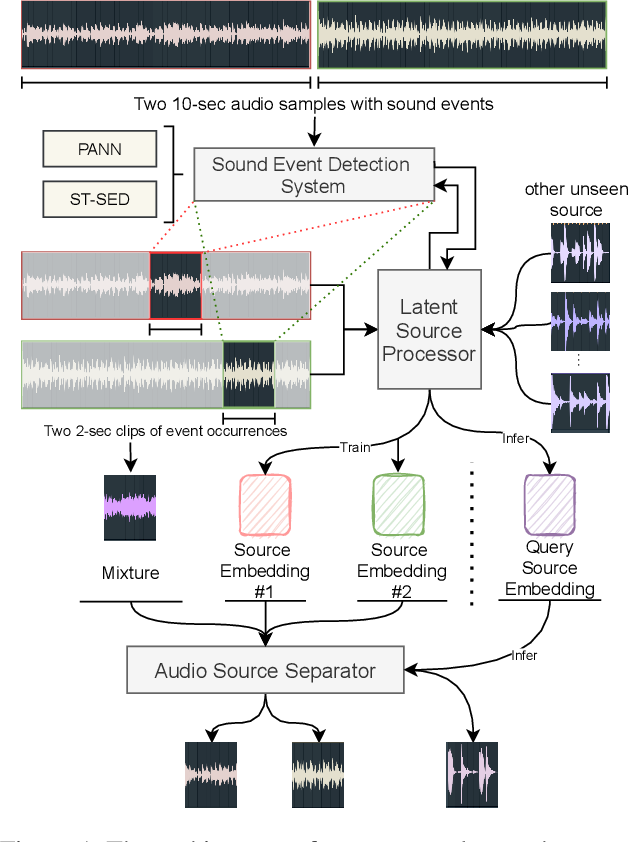
Figure 1 from Zero-shot Audio Source Separation through Query-based ...
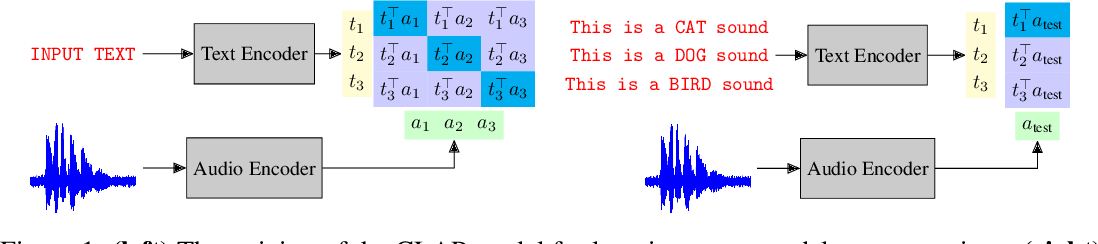
Figure 1 from Listenable Maps for Zero-Shot Audio Classifiers ...
Advertisement Space (300x250)

Figure 1 from Enhancing Zero-shot Audio Classification using Sound ...

Figure 1 from Zero-Shot Unsupervised and Text-Based Audio Editing Using ...

Figure 1 from End-to-End Zero-Shot Voice Style Transfer with Location ...
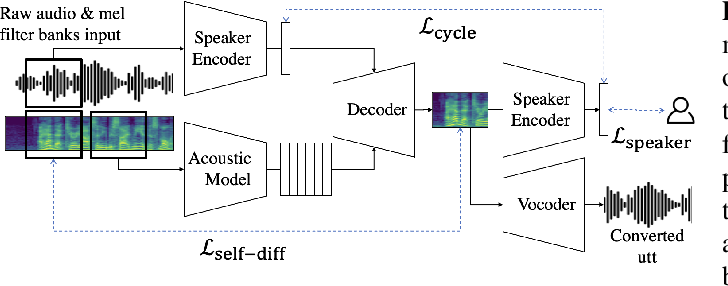
Figure 1 from Training Robust Zero-Shot Voice Conversion Models with ...

Figure 1 from Zero-shot Video Emotion Recognition via Multimodal ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...
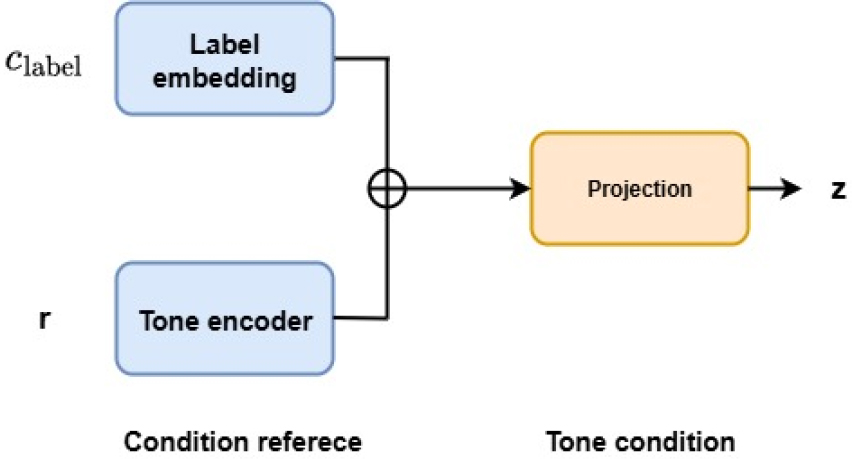
Integrated modeling of zero shot audio effects based on dual conditioning
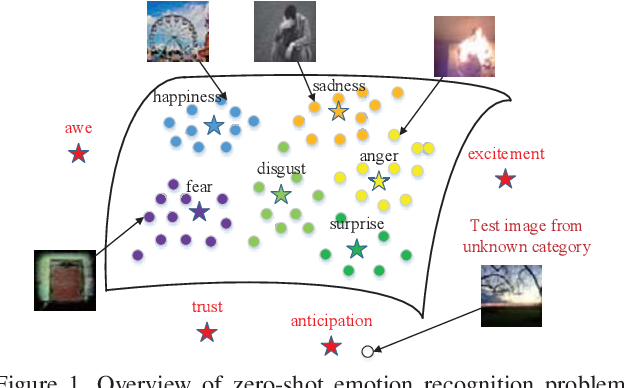
Figure 1 from Zero-Shot Emotion Recognition via Affective Structural ...
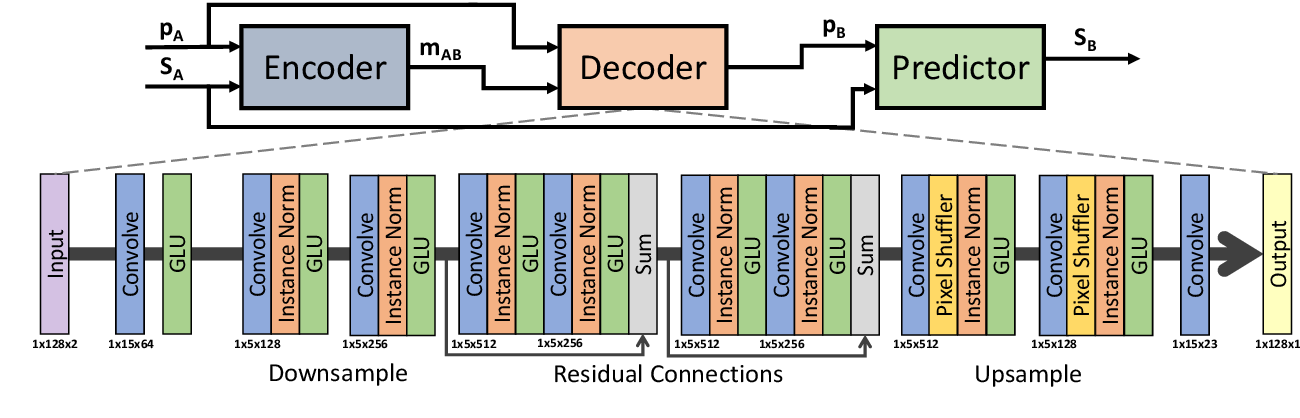
Figure 1 from Multi-speaker Emotion Conversion via Latent Variable ...
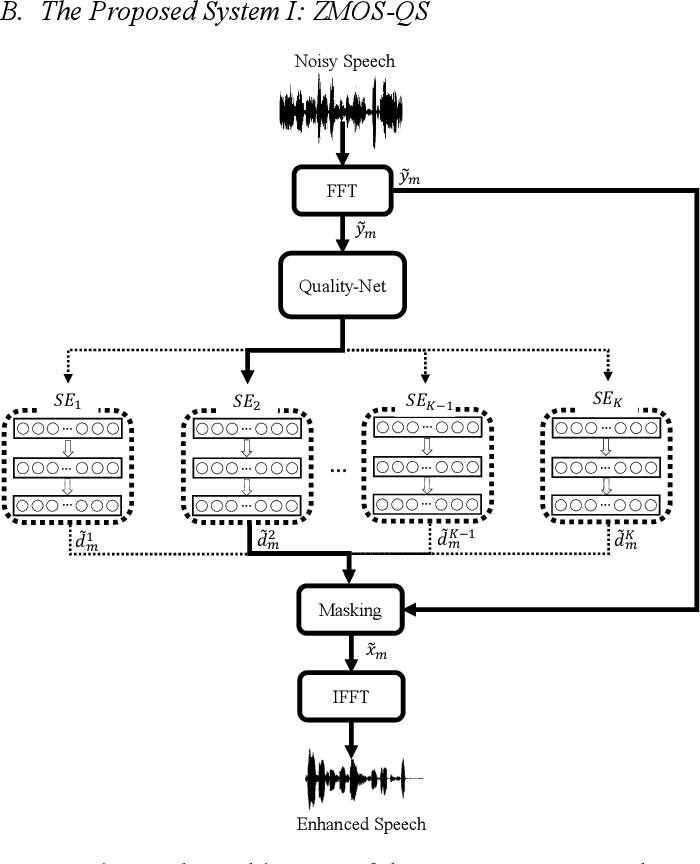
Figure 1 from Speech Enhancement with Zero-Shot Model Selection ...
Advertisement Space (336x280)
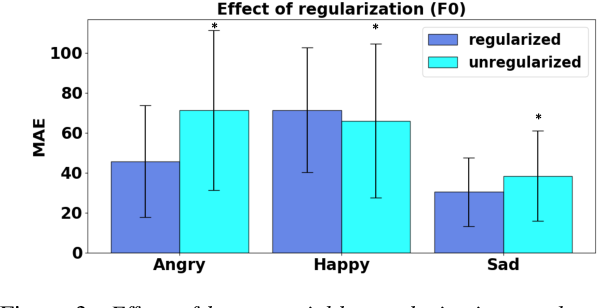
Figure 1 from Multi-speaker Emotion Conversion via Latent Variable ...
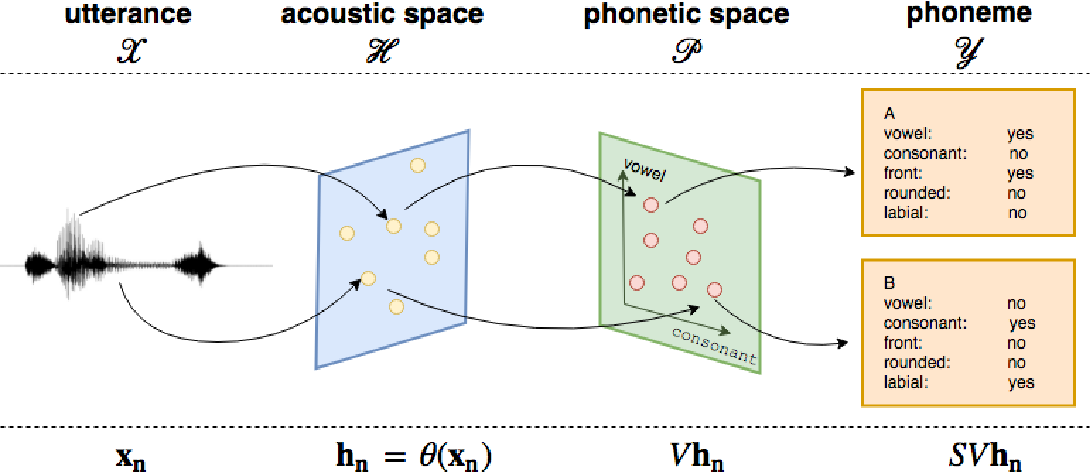
Figure 1 from Zero-shot Learning for Speech Recognition with Universal ...

Figure 3 from Zero-shot Audio Source Separation through Query-based ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from Zero-Shot Voice Conversion Based on Speaker Embedding ...

Figure 2 from Zero-Shot Emotion Transfer for Cross-Lingual Speech ...
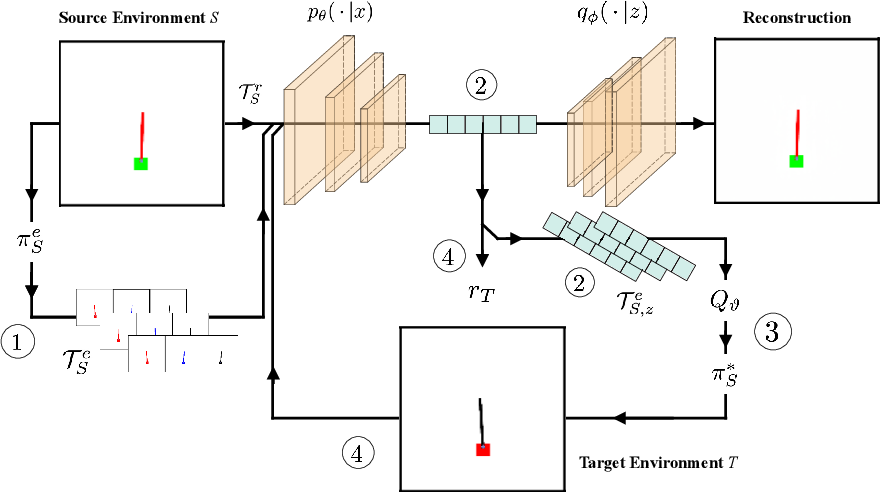
Figure 1 from Zero-Shot Transfer in Imitation Learning | Semantic Scholar
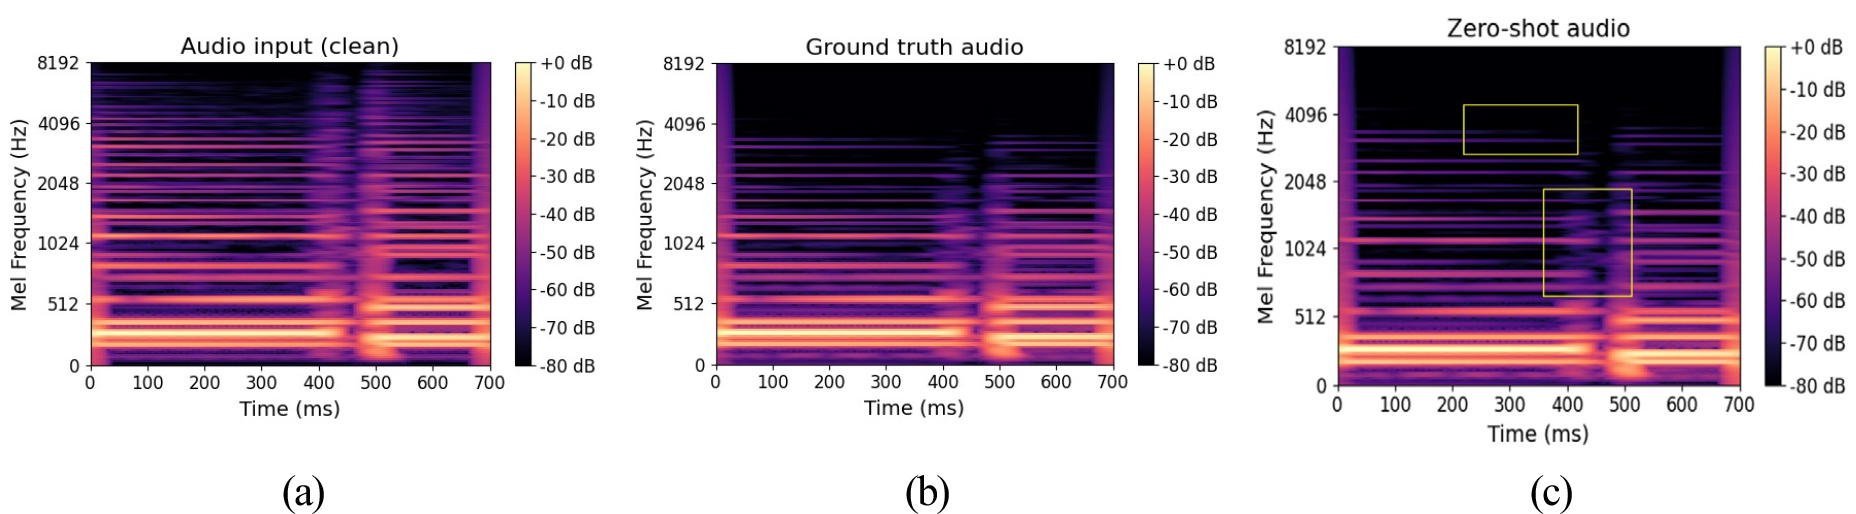
Integrated modeling of zero shot audio effects based on dual conditioning

Figure 1 from Zero-Shot Transfer of Neural ODEs | Semantic Scholar

Figure 1 from Zero-Shot Audio-Visual Compound Expression Recognition ...
Advertisement Space (336x280)
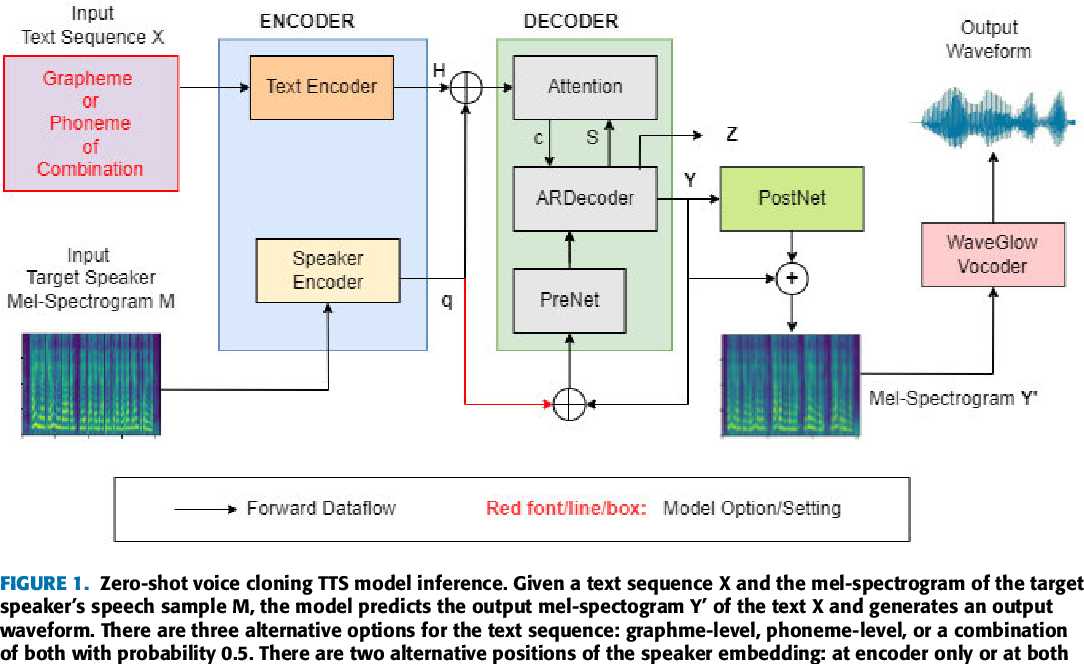
Figure 1 from Zero-Shot Voice Cloning Text-to-Speech for Dysphonia ...

Multi-label Zero-Shot Audio Classification with Temporal Attention

Figure 1 from Zero-shot Speech Translation | Semantic Scholar
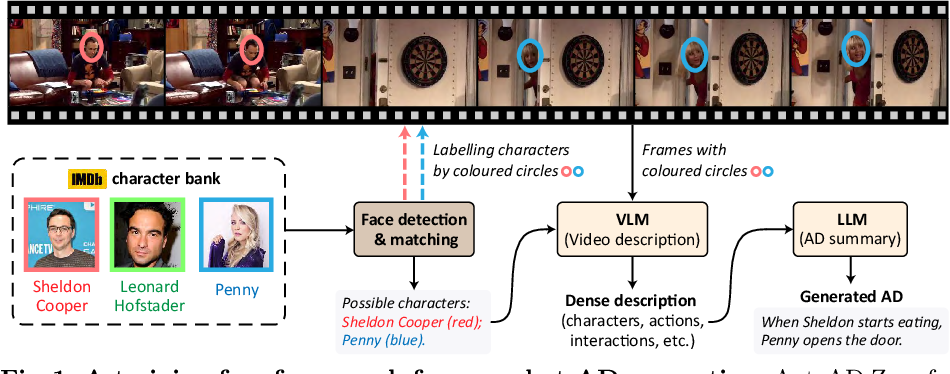
Figure 1 from AutoAD-Zero: A Training-Free Framework for Zero-Shot ...
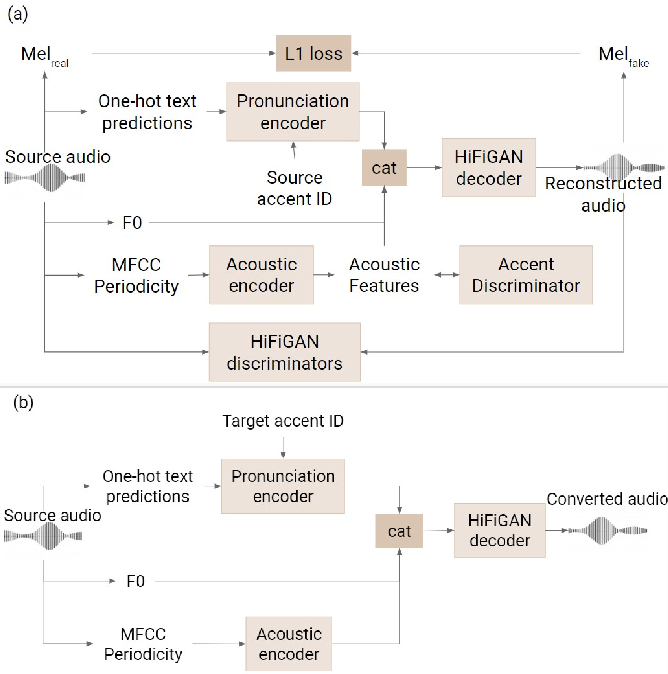
Figure 1 from Voice-Preserving Zero-Shot Multiple Accent Conversion ...
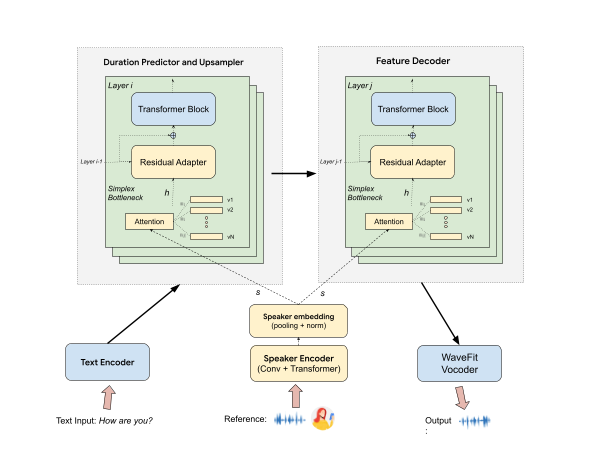
Restoring speaker voices with zero-shot cross-lingual voice transfer ...