
Figure 2 From Bridging Different Language Models And Generative Vision

Figure 2 from Bridging Different Language Models and Generative Vision ...

Figure 11 from Bridging Different Language Models and Generative Vision ...

Figure 9 from Bridging Different Language Models and Generative Vision ...

Figure 8 from Bridging Different Language Models and Generative Vision ...

Table 2 from Bridging Different Language Models and Generative Vision ...

Table 3 from Bridging Different Language Models and Generative Vision ...
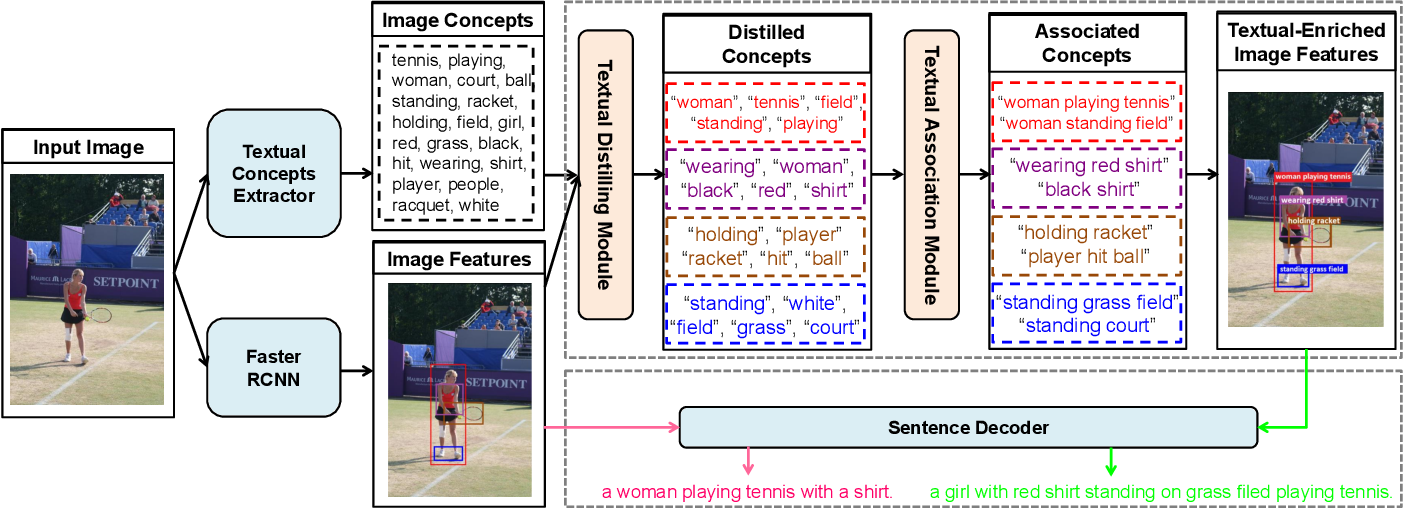
Figure 2 from Bridging the Gap between Vision and Language Domains for ...

Bridging Different Language Models and Generative Vision Models for ...

Figure 3 from Interpreting vision and language generative models with ...

Bridging Different Language Models and Generative Vision Models for ...
Advertisement Space (300x250)

Figure 1 from Bridging Vision and Language Encoders: Parameter ...

Figure 1 from Bridging Vision and Language Spaces with Assignment ...

Figure 2 from RegionGPT: Towards Region Understanding Vision Language ...

[论文评述] Bridging Vision Language Models and Symbolic Grounding for Video ...

(PDF) Learning Visual Grounding from Generative Vision and Language Model
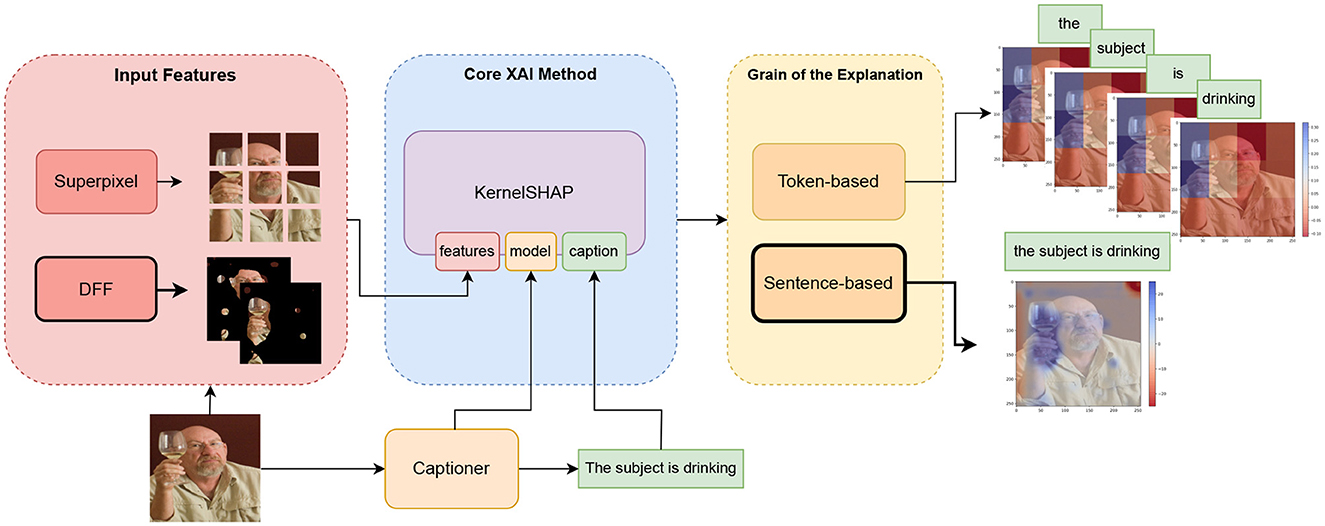
Frontiers | Interpreting vision and language generative models with ...
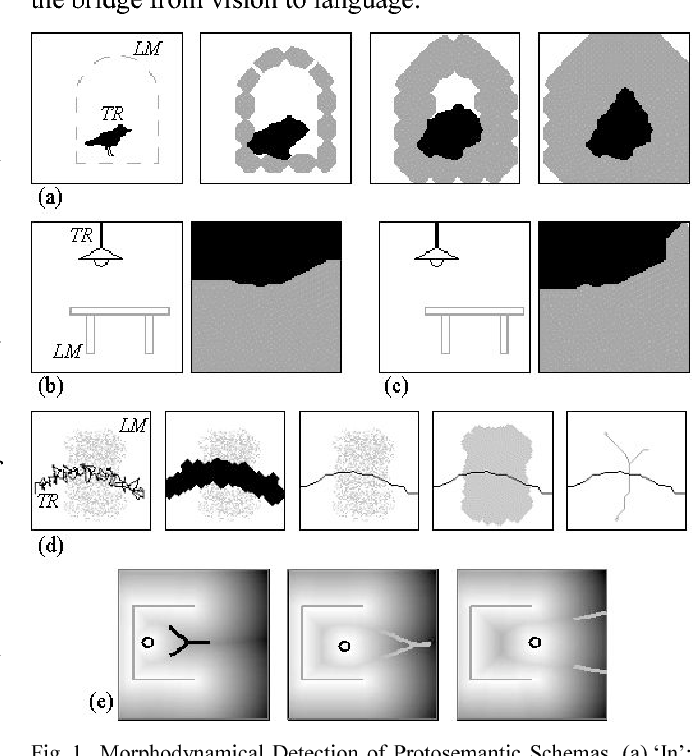
Figure 1 from Bridging the gap between vision and language: a ...

[论文评述] Learning Visual Grounding from Generative Vision and Language Model

Figure 2 from From Gaze to Insight: Bridging Human Visual Attention and ...
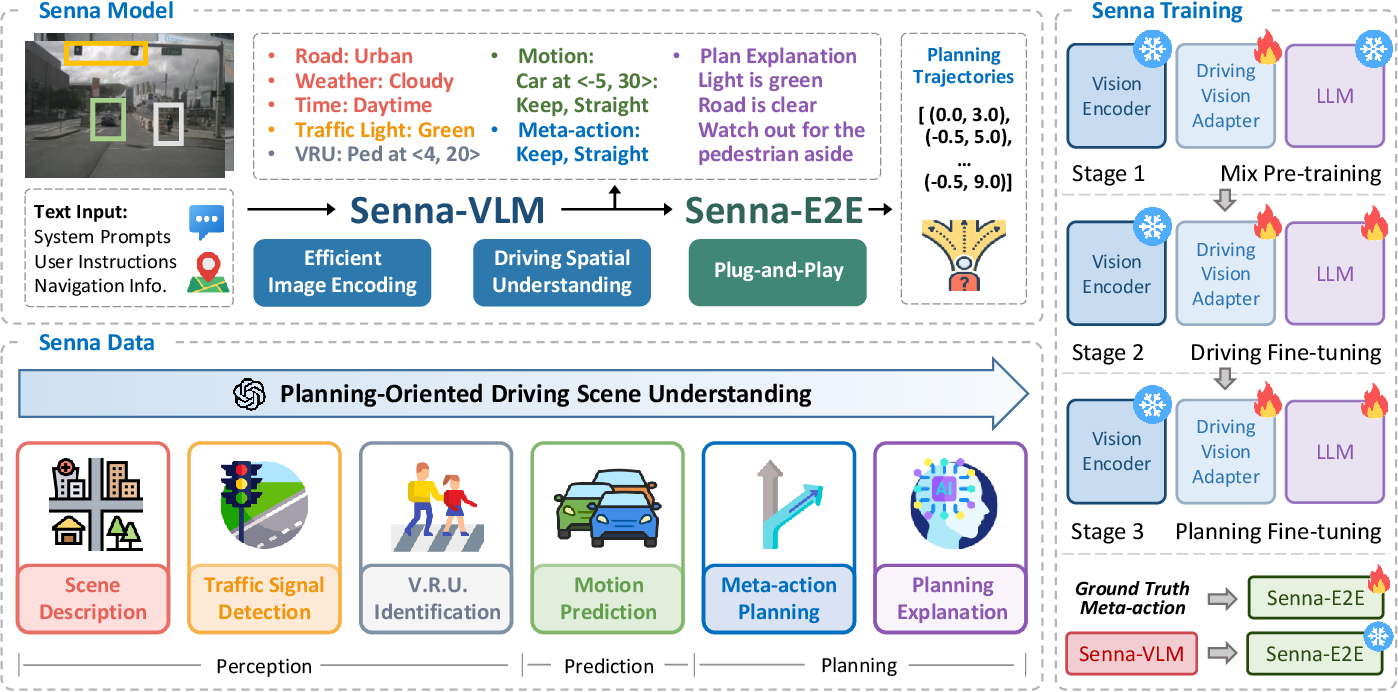
Figure 1 from Senna: Bridging Large Vision-Language Models and End-to ...
Advertisement Space (336x280)

Figure 1 from Going Beyond Nouns With Vision & Language Models Using ...
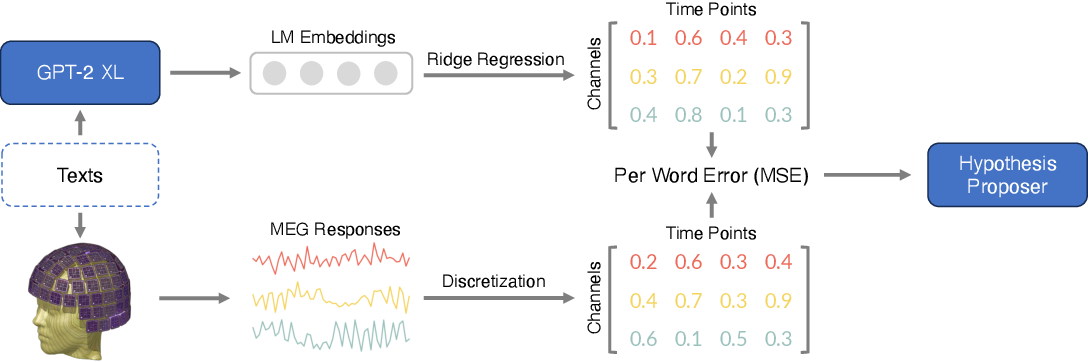
Figure 1 from Divergences between Language Models and Human Brains ...

Paper page - Rec-R1: Bridging Generative Large Language Models and User ...

Bridging Vision and Language | PDF

Figure 2 from Distilling Vision-Language Models on Millions of Videos ...

Bridging Vision and Language Spaces with Assignment Prediction | AI ...
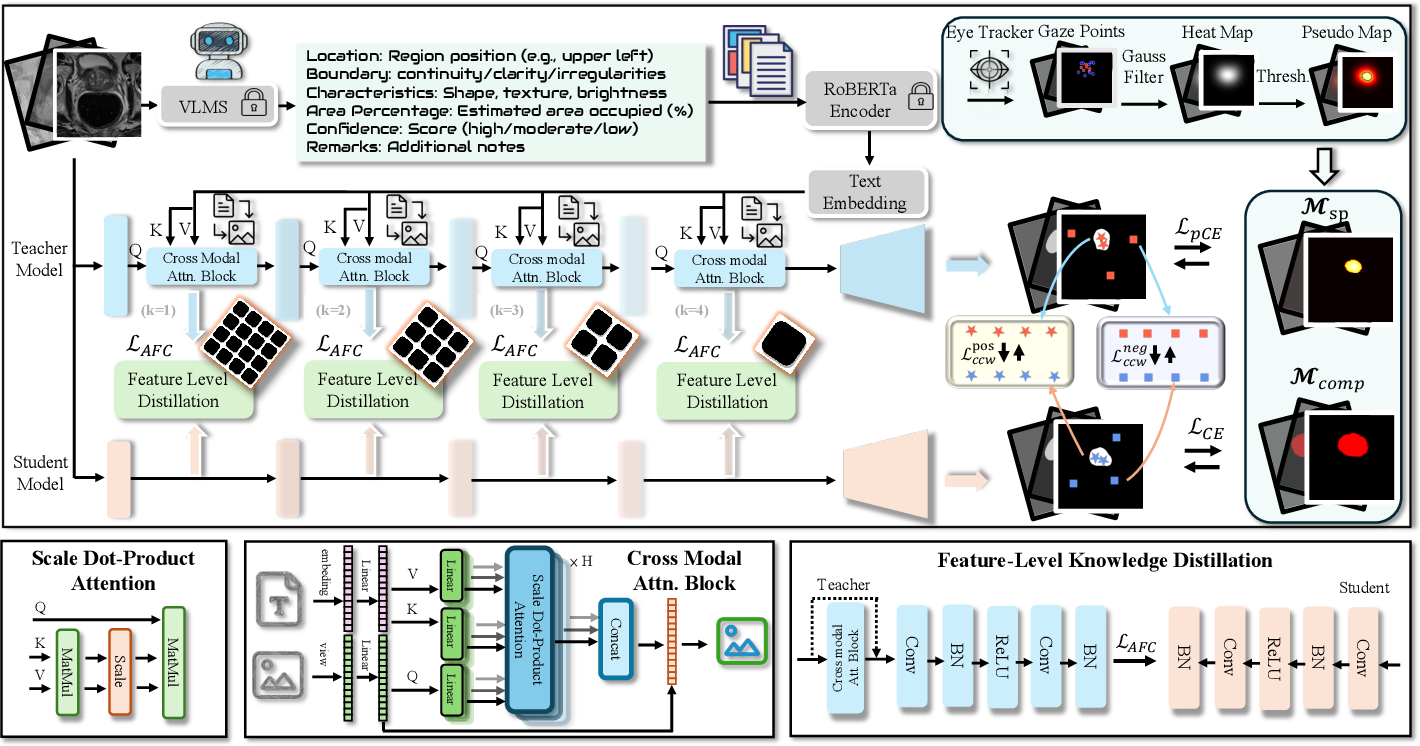
Figure 1 from From Gaze to Insight: Bridging Human Visual Attention and ...

Figure 1 from SpanVLA: Efficient Action Bridging and Learning from ...

Bridging environments and language with rendering functions and vision ...

Bridging Vision Foundation and Vision–Language Models for Open ...
Advertisement Space (336x280)

AlignVLM: Bridging Vision and Language Latent Spaces for Multimodal ...

[논문 리뷰] Bridging Molecular Graphs and Large Language Models

(PDF) Locate Then Generate: Bridging Vision and Language with Bounding ...

Figure 2 from Unsupervised Vision-Language Parsing: Seamlessly Bridging ...

(PDF) From Gaze to Insight: Bridging Human Visual Attention and Vision ...

(PDF) Vision Guided Generative Pre-trained Language Models for ...