
Figure 2 From Depth And Semantics Aware Multi Modal Domain Translation

Figure 2 from Depth- and Semantics-aware Multi-modal Domain Translation ...

Figure 3 from Depth- and Semantics-aware Multi-modal Domain Translation ...

Figure 2 from Intra-Model Smoothing Using Depth Aware Multi-Sample Anti ...

Figure 4 from Depth- and Semantics-aware Multi-modal Domain Translation ...
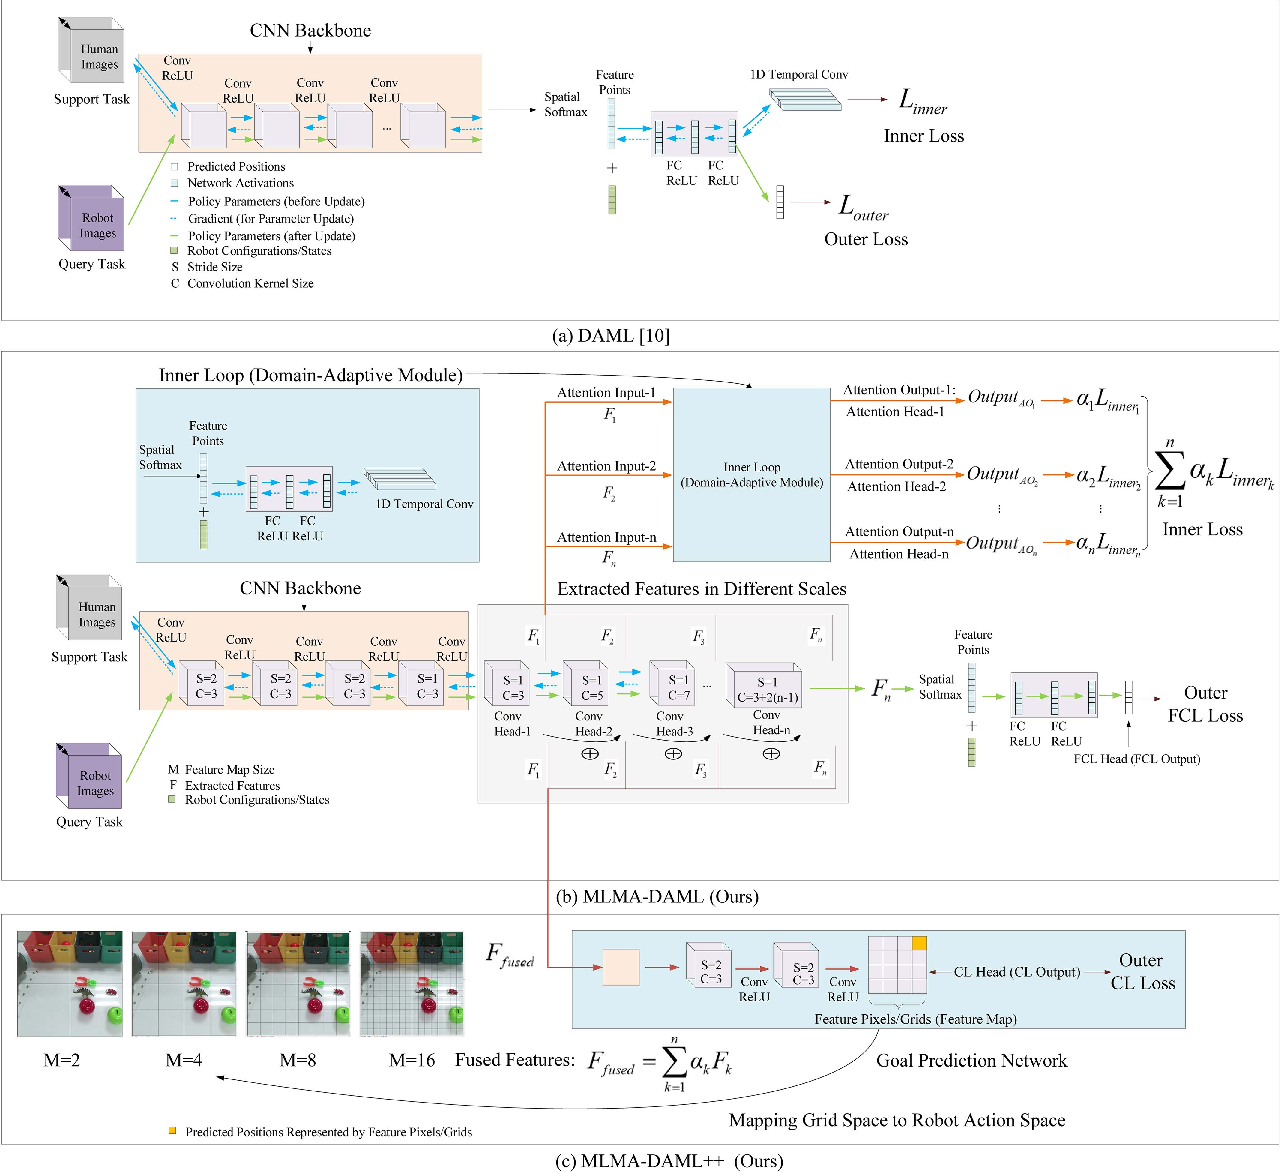
Figure 2 from Learning From Demonstrations Via Multi-Level and Multi ...

Figure 2 from DADA: Depth-Aware Domain Adaptation in Semantic ...

Figure 2 from Multi-Scale Depth-Aware Unsupervised Domain Adaption in ...

Figure 2 from MFF-Net: Towards Efficient Monocular Depth Completion ...

Figure 2 from Structure Aware Multi-Graph Network for Multi-Modal ...
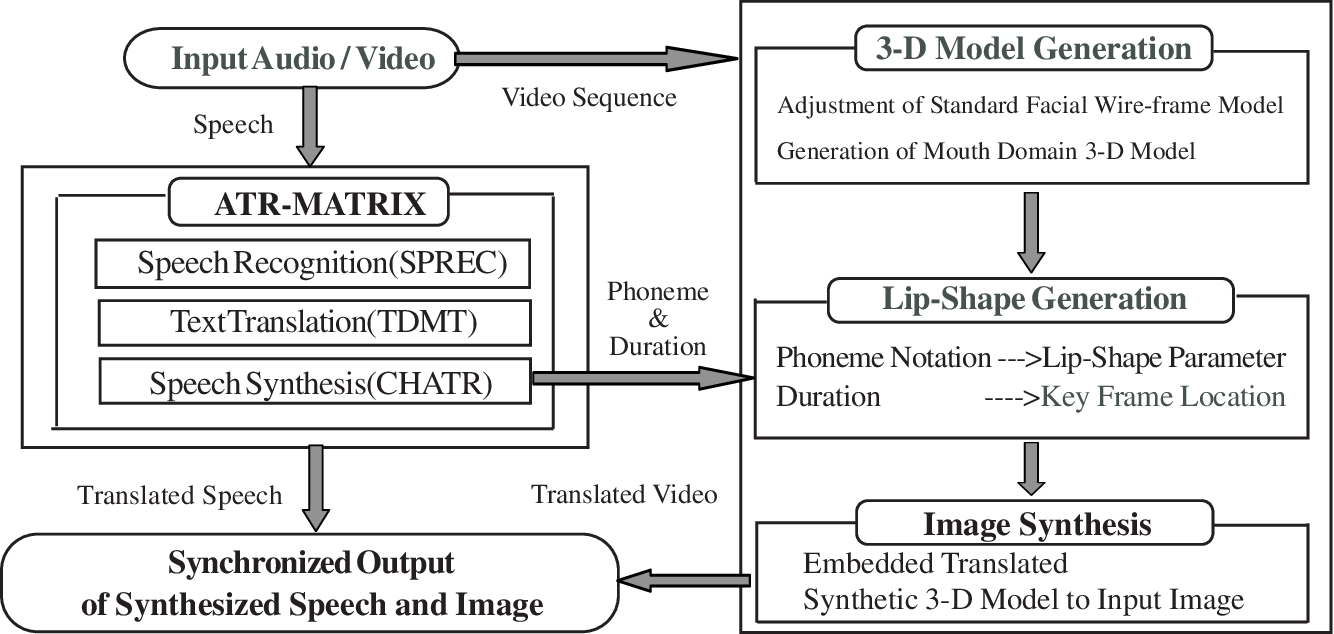
Figure 1 from Multi-modal translation system and its evaluation ...
Advertisement Space (300x250)

Figure 2 from Depth-Aware Multi-Person 3D Pose Estimation With Multi ...
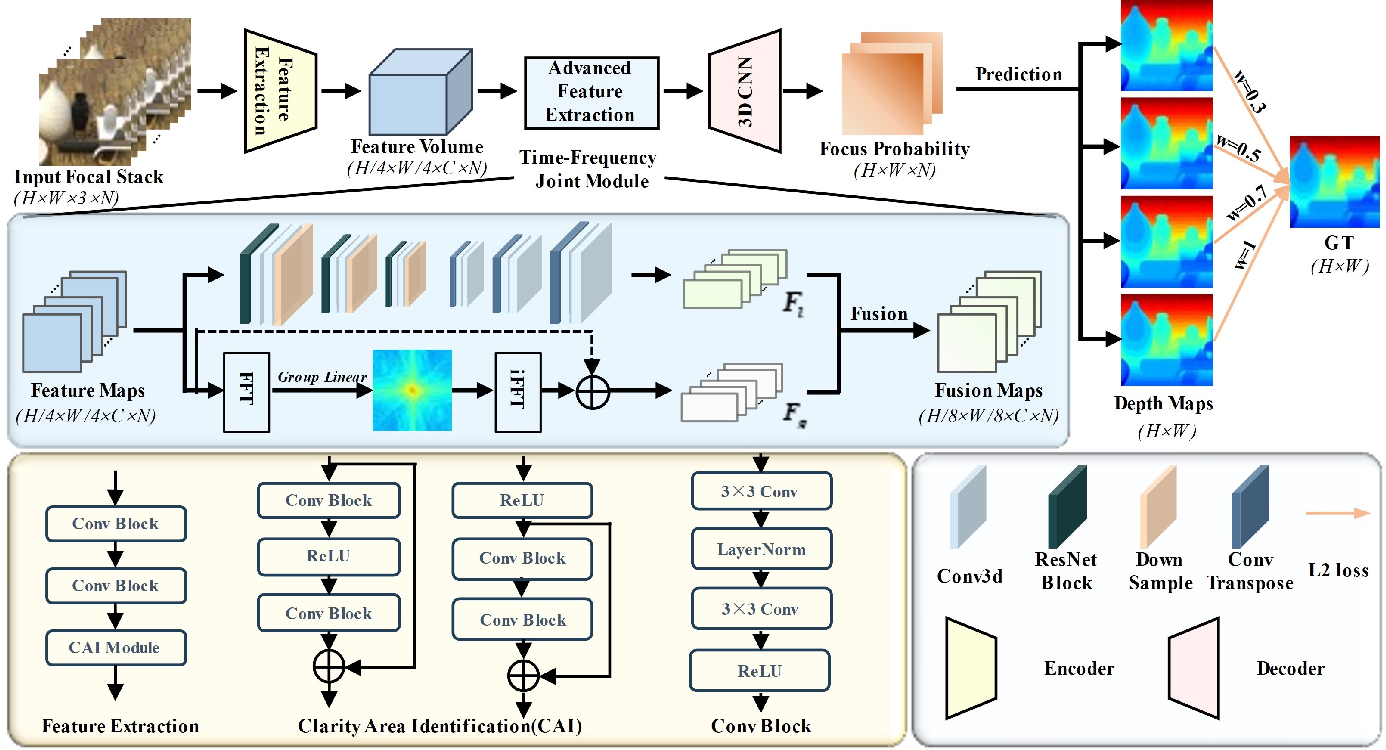
Figure 2 from Frequency-Aware Deep Depth from Focus | Semantic Scholar

Figure 2 from Multi-Modal Depth Estimation Using Convolutional Neural ...
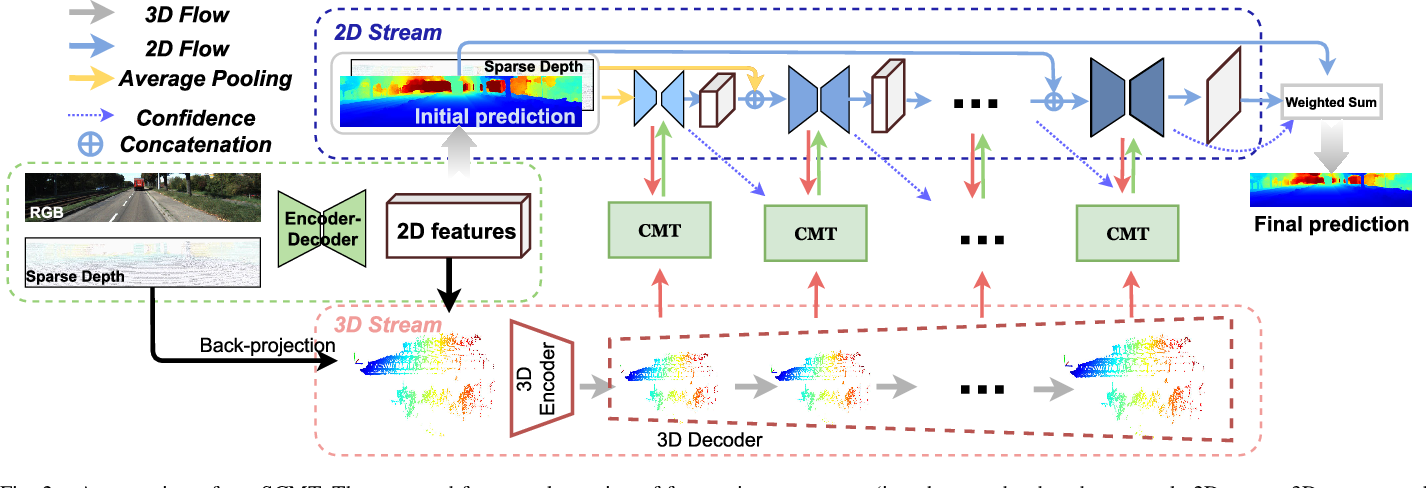
Figure 2 from Structure-Aware Cross-Modal Transformer for Depth ...

Figure 1 from Semi-supervised Multi-task Learning for Semantics and ...

Figure 2 from Multi-Modal Fusion Based on Depth Adaptive Mechanism for ...

Figure 2 from Self-Supervised Event-Based Monocular Depth Estimation ...
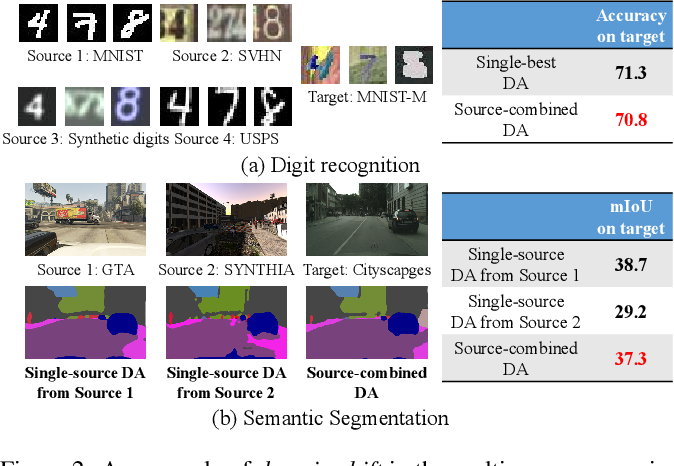
Figure 2 from Multi-source Domain Adaptation in the Deep Learning Era ...

Figure 2 from Multimodal Deep Learning using Images and Text for ...

(PDF) Depth- and Semantics-aware Multi-modal Domain Translation ...
Advertisement Space (336x280)

Figure 2 from Layer-Level Progressive Transformer With Modality ...

Figure 2 from Meta-Learning based Deferred Optimisation for Sentiment ...

Figure 2 from A Multimodal Semantic Fusion Network with Cross-Modal ...
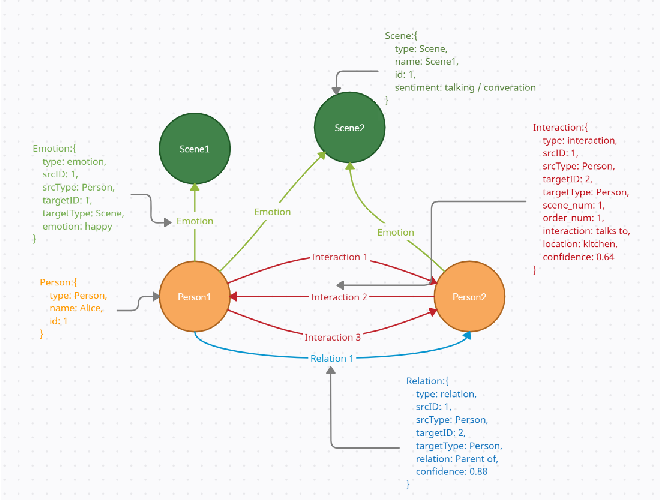
Figure 2 from MultiModal Language Modelling on Knowledge Graphs for ...

Figure 1 from Multi-Scale Depth-Aware Unsupervised Domain Adaption in ...

Figure 1 from Exploring Discriminative Word-Level Domain Contexts for ...

Figure 1 from Multilingual and Multi-Domain Adaptation for Neural ...

Figure 10 from Structure-Aware Cross-Modal Transformer for Depth ...

Figure 4 from Structure-Aware Cross-Modal Transformer for Depth ...

Figure 1 from Adding multimodal capabilities to a text-only translation ...
Advertisement Space (336x280)

Figure 2 from A Multi-Modal System with Wireless Flexible Sensor ...

Figure 2 from Structure-Aware Multimodal Sequential Learning for Visual ...

Figure 2 from Multi-Domain Deep Learning from a Multi-View Perspective ...

Figure 2 from Multi-Modal Attention-based Fusion Model for Semantic ...
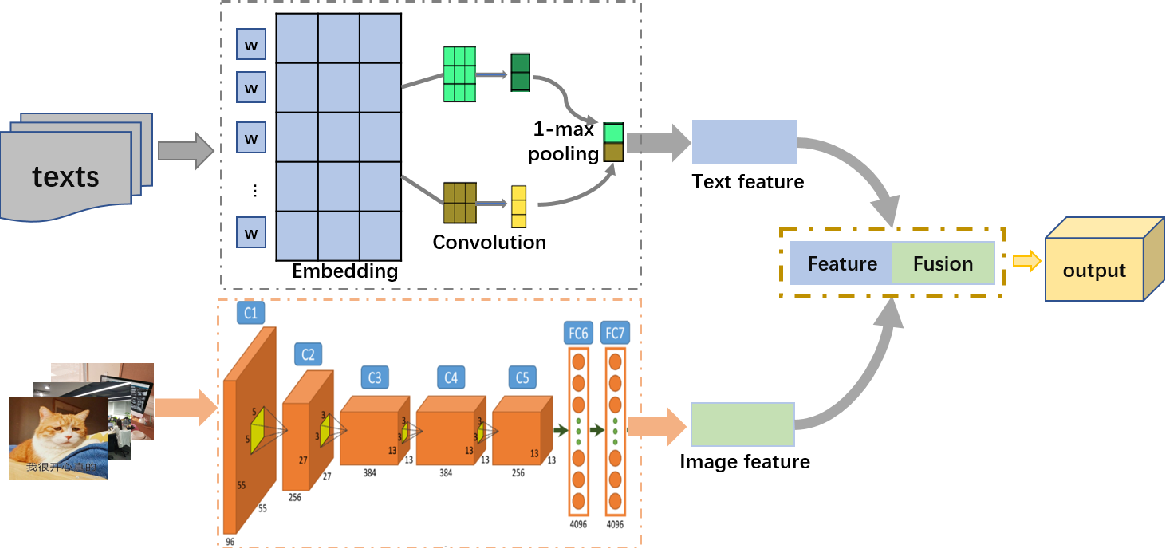
Figure 2 from A Deep Multi-Modal Fusion Approach for Semantic Place ...

Figure 2 from Improved Depth-Aware Circuit Partitioning for Mixed Logic ...