
Figure 2 From Ds Moe Dynamic Expert Scheduling For Efficient Moe Based
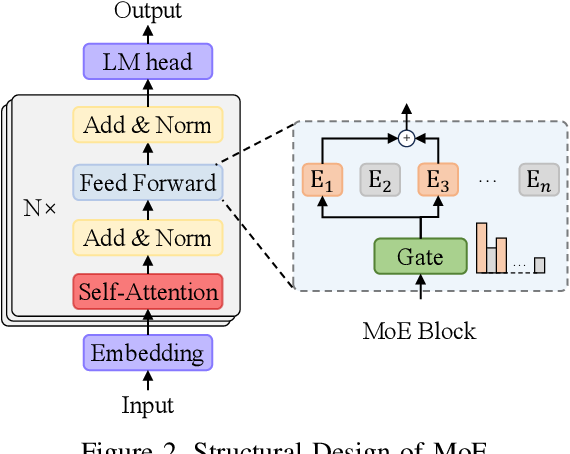
Figure 2 from DS-MoE: Dynamic Expert Scheduling for Efficient MoE-based ...
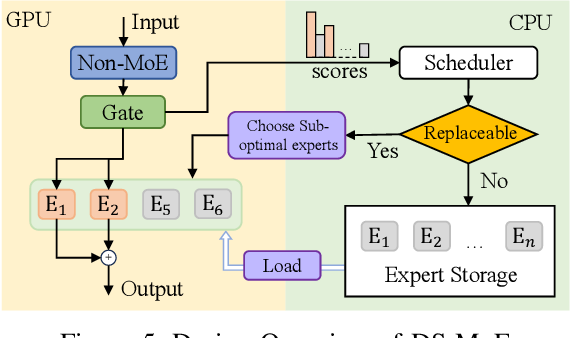
Figure 5 from DS-MoE: Dynamic Expert Scheduling for Efficient MoE-based ...
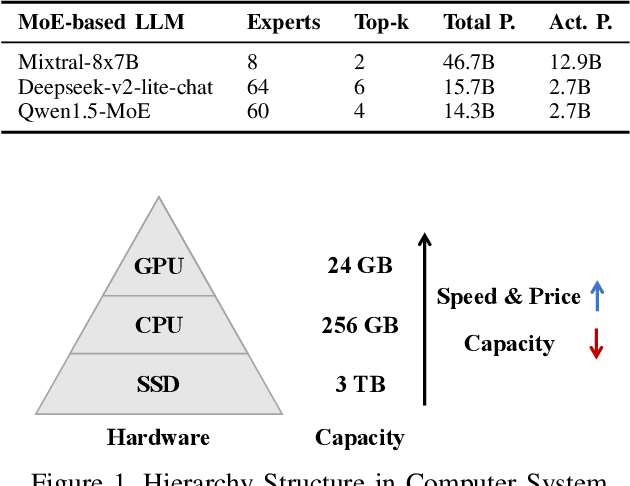
Figure 1 from DS-MoE: Dynamic Expert Scheduling for Efficient MoE-based ...

Figure 1 from A Scheduling Framework for Efficient MoE Inference on ...
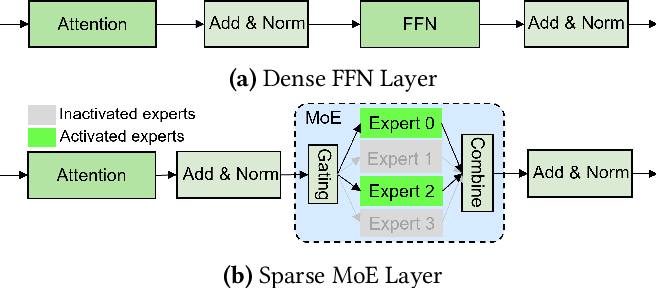
Figure 2 from MoE-APEX: An Efficient MoE Inference System with Adaptive ...

A Scheduling Framework for Efficient MoE Inference on Edge GPU-NDP ...

MoE-Infinity: Activation-Aware Expert Offloading for Efficient MoE Serving

[论文评述] A Scheduling Framework for Efficient MoE Inference on Edge GPU ...

[2504.15299] D2MoE: Dual Routing and Dynamic Scheduling for Efficient ...

(PDF) D$^{2}$MoE: Dual Routing and Dynamic Scheduling for Efficient On ...
Advertisement Space (300x250)

[2504.15299] D2MoE: Dual Routing and Dynamic Scheduling for Efficient ...

[2504.15299] D2MoE: Dual Routing and Dynamic Scheduling for Efficient ...

[2504.15299] D2MoE: Dual Routing and Dynamic Scheduling for Efficient ...

[2504.15299] D2MoE: Dual Routing and Dynamic Scheduling for Efficient ...
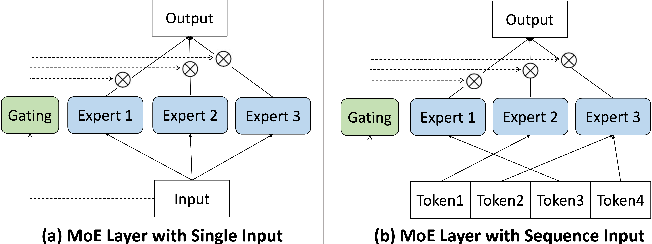
Figure 1 from Serving MoE Models on Resource-Constrained Edge Devices ...
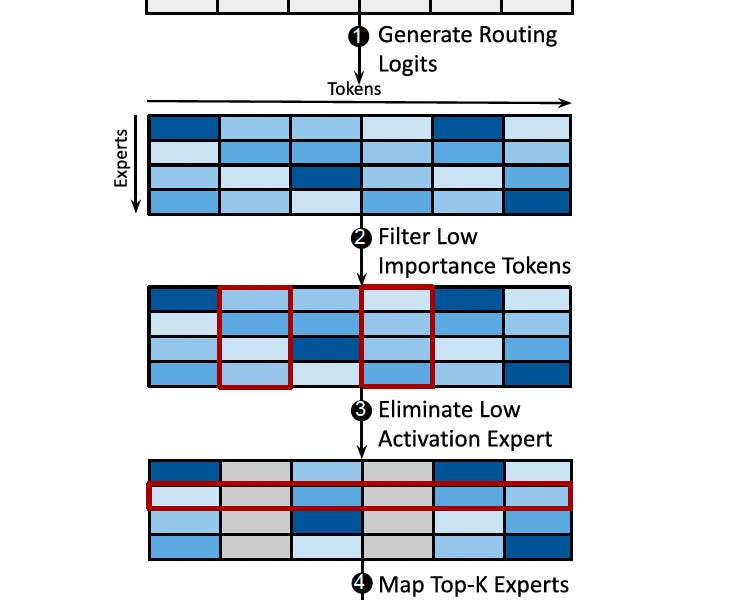
LYNX: ENABLING EFFICIENT MOE INFERENCE THROUGH DYNAMIC BATCH-AWARE ...
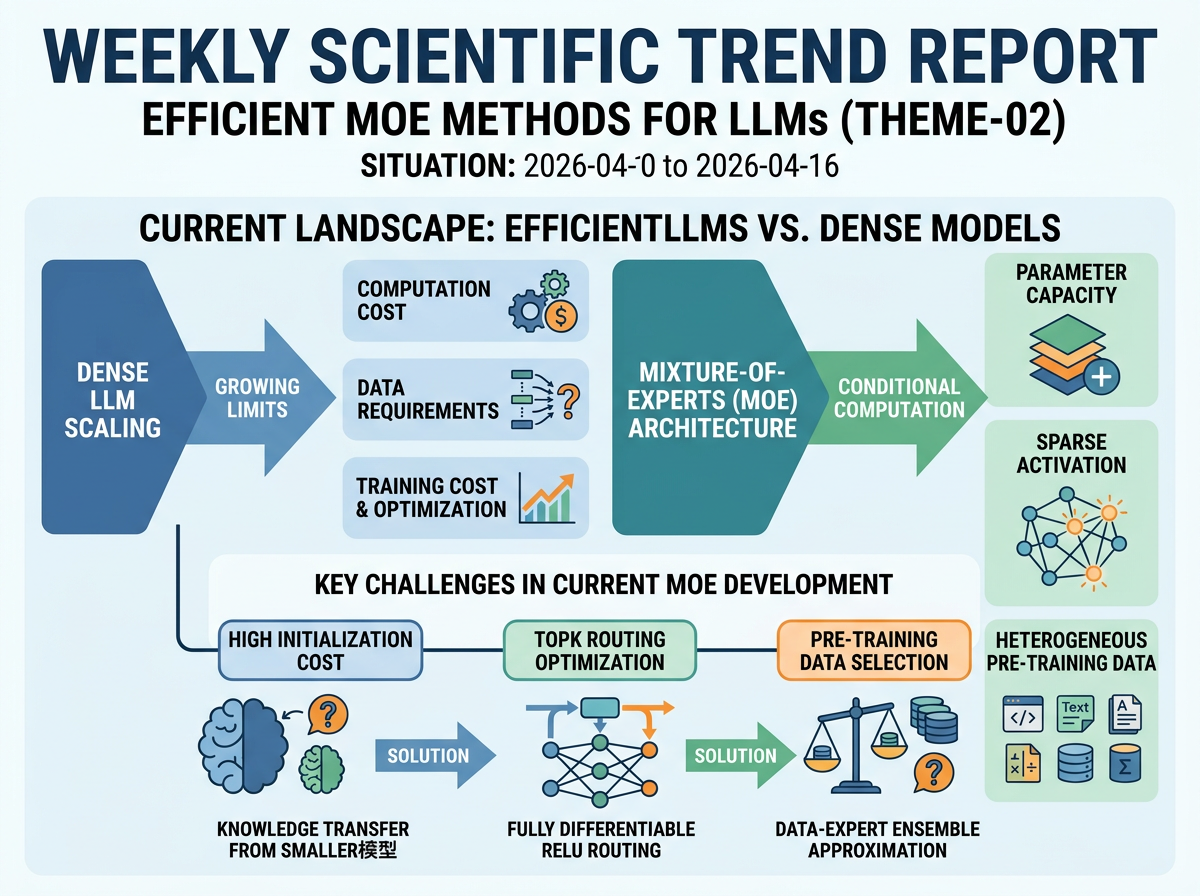
Weekly Theme 2: Efficient MoE Methods for LLMs (2026-04-10 to 2026-04 ...

Figure 1 from Serving MoE Models on Resource-Constrained Edge Devices ...
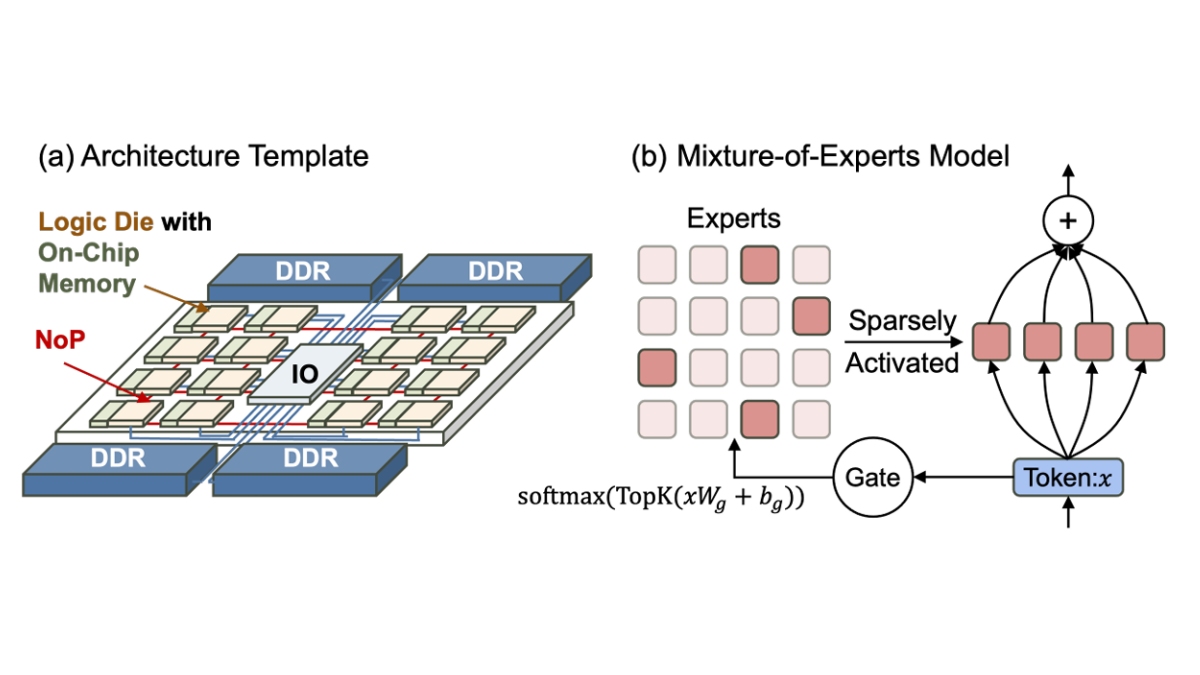
Expert Streaming: Accelerating Low-Batch MoE Inference via Multi ...

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive
Advertisement Space (336x280)

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Expertflow Achieves Efficient MoE Inference With Adaptive

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive

Expert Streaming: Accelerating Low-Batch MoE Inference via Multi ...
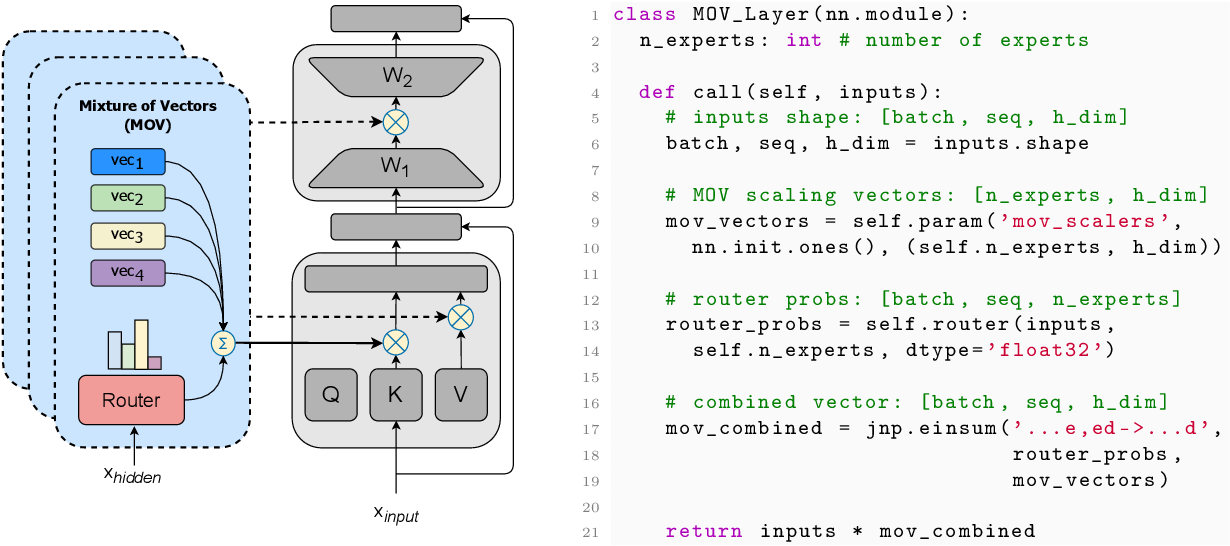
Figure 2 from Pushing Mixture of Experts to the Limit: Extremely ...

Table 2 from Sub-MoE: Efficient Mixture-of-Expert LLMs Compression via ...

Unveiling DeepSeek-V3 — A New Era of Efficient and Powerful MoE ...

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive

HybriMoE: Hybrid CPU-GPU Scheduling and Cache Management for Efficient ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...
Advertisement Space (336x280)

DA-MoE: Towards Dynamic Expert Allocation for Mixture-of-Experts Models ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

[论文评述] MoE-Spec: Expert Budgeting for Efficient Speculative Decoding

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Expert Streaming: Accelerating Low-Batch MoE Inference via Multi ...