
Figure 2 From E2lvlmevidence Enhanced Large Vision Language Model For

Figure 2 from E2LVLM:Evidence-Enhanced Large Vision-Language Model for ...

Figure 2 from Effectively Enhancing Vision Language Large Models by ...
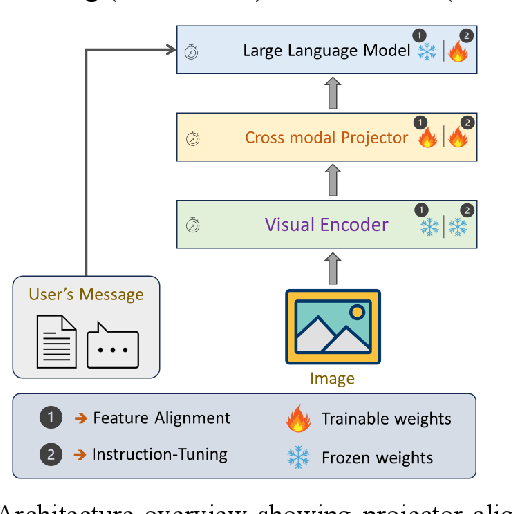
Figure 2 from Scaling Large Vision-Language Models for Enhanced ...
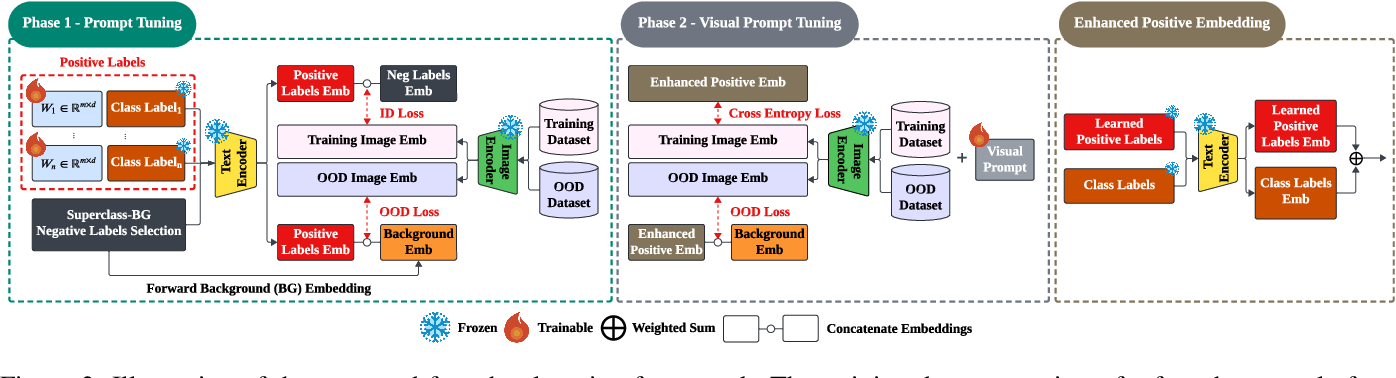
Figure 2 from Harnessing Large Language and Vision-Language Models for ...
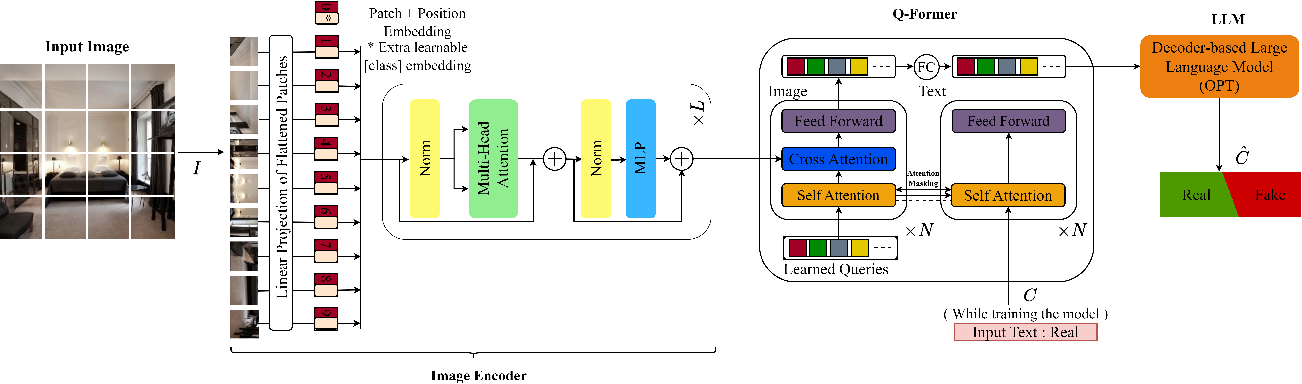
Figure 1 from Harnessing the Power of Large Vision Language Models for ...

Figure 2 from LVLM-EHub: A Comprehensive Evaluation Benchmark for Large ...

Figure 2 from Learning the Visualness of Text Using Large Vision ...

Figure 2 from ViGoR: Improving Visual Grounding of Large Vision ...

Figure 2 from Distilling Large Vision-Language Model with Out-of ...

Figure 2 from Large Language Models Know What is Key Visual Entity: An ...
Advertisement Space (300x250)

Figure 2 from Detecting and Mitigating Hallucination in Large Vision ...
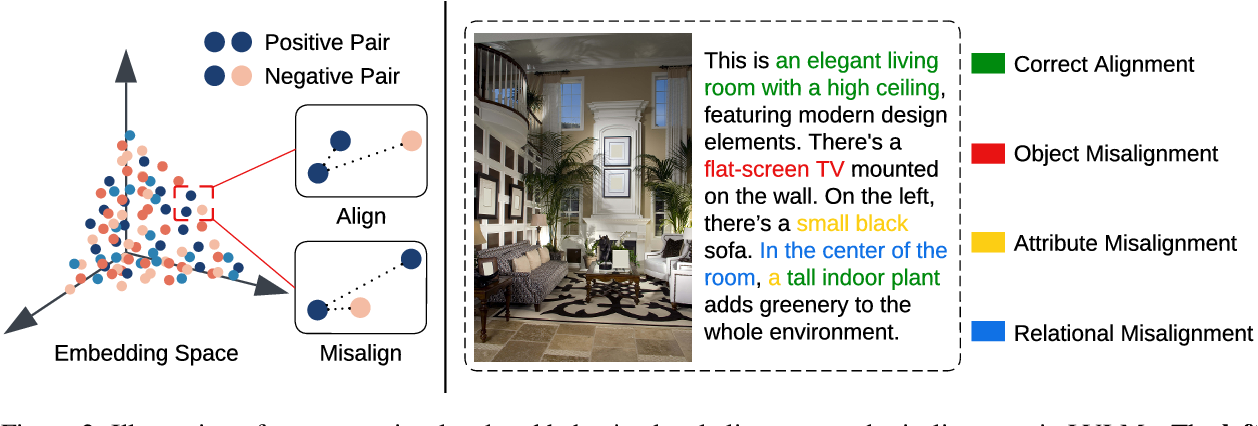
Figure 2 from Large Vision-Language Model Alignment and Misalignment: A ...

Figure 2 from Large Vision-Language Model Alignment and Misalignment: A ...
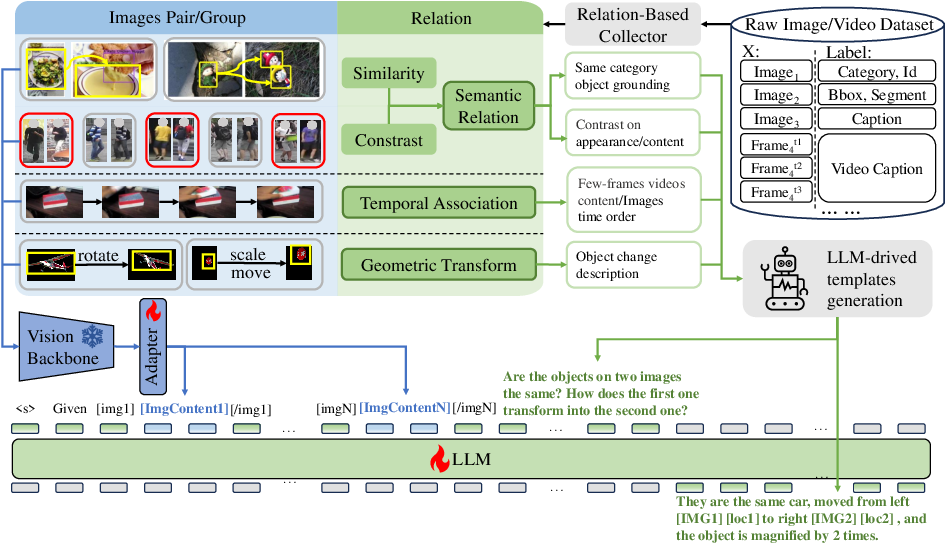
Figure 2 from RelationVLM: Making Large Vision-Language Models ...

Figure 2 from Inducing High Energy-Latency of Large Vision-Language ...
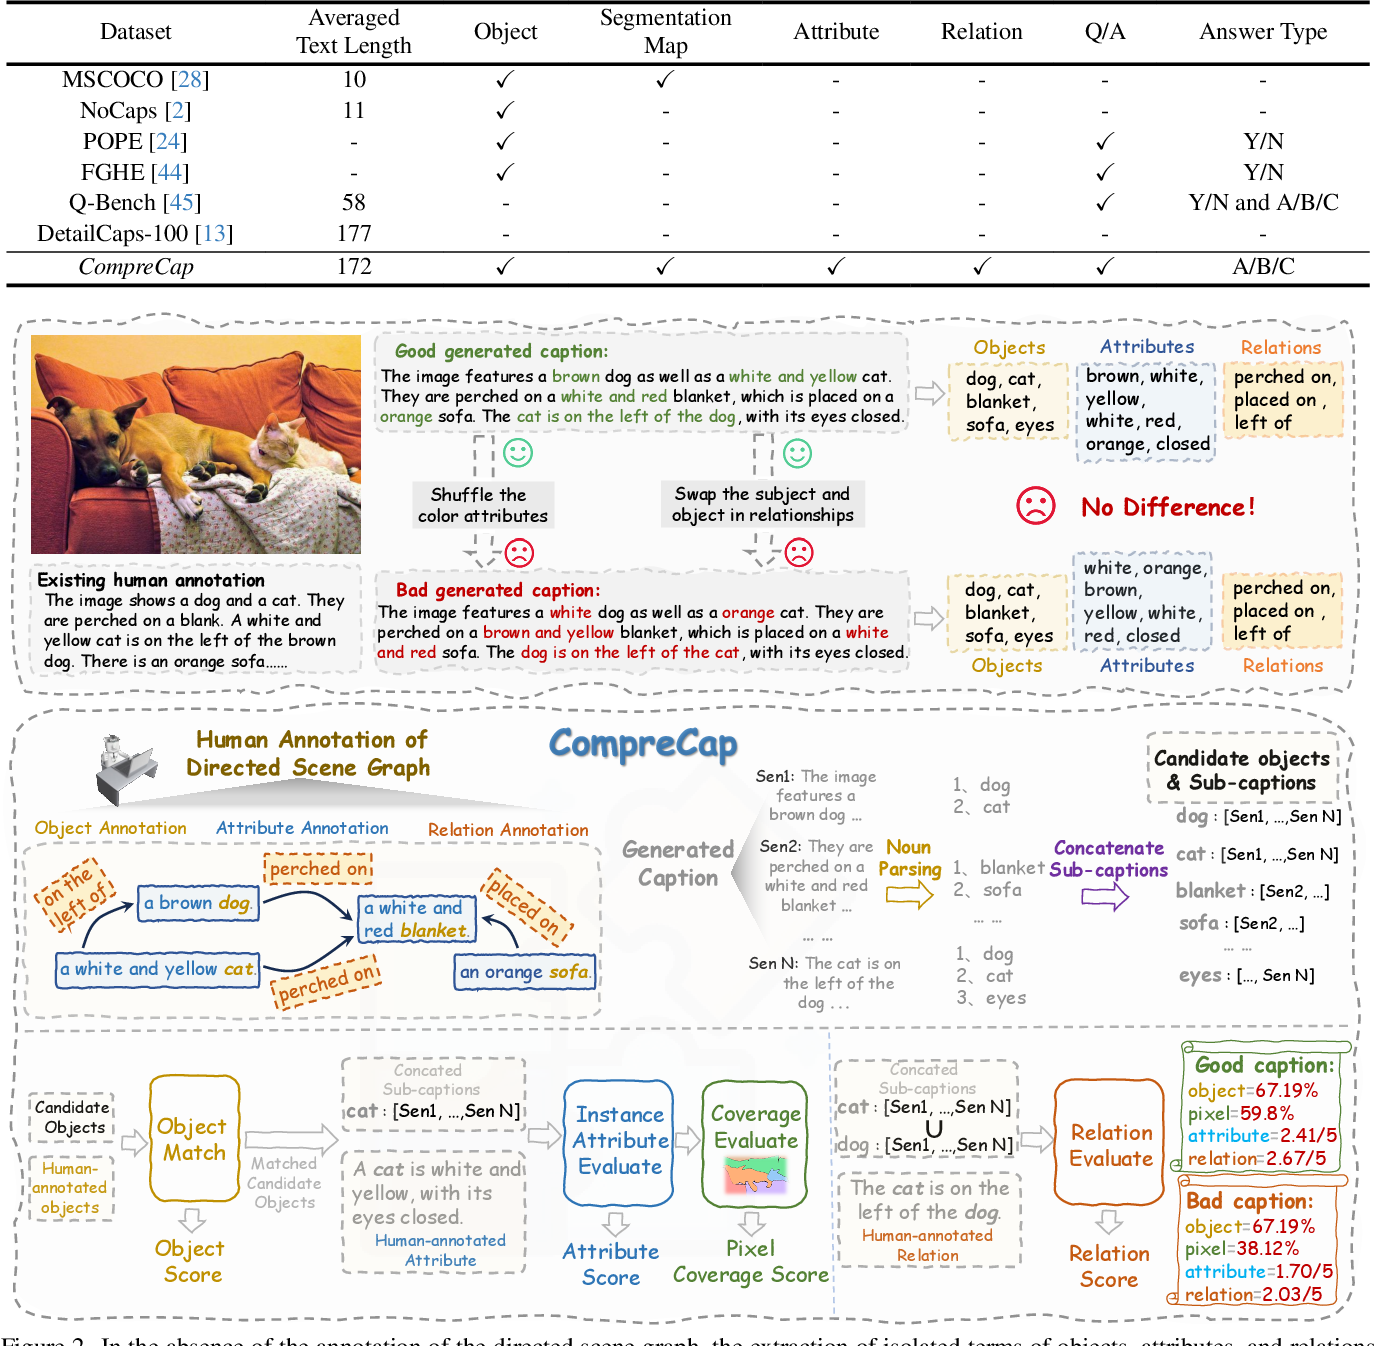
Figure 2 from Benchmarking Large Vision-Language Models via Directed ...

(PDF) Language Enhanced Model for Eye (LEME): An Open-Source ...

AdCare-VLM: Leveraging Large Vision Language Model (LVLM) to Monitor ...
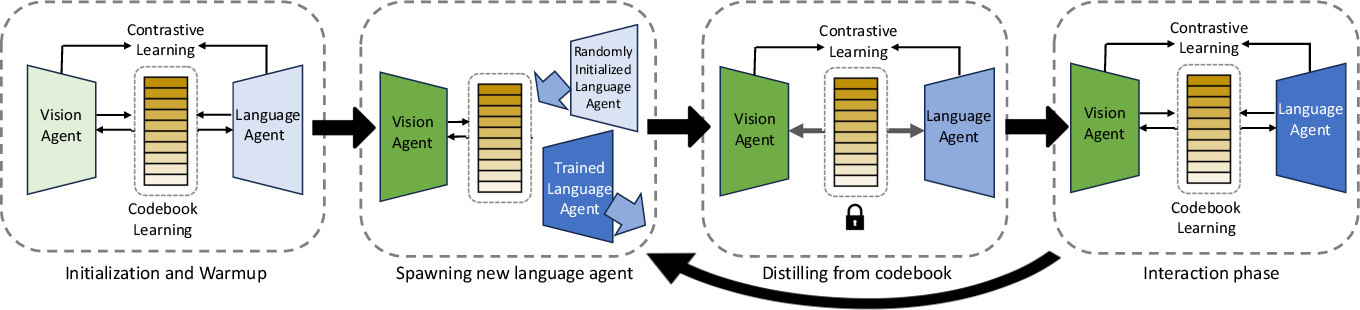
Figure 2 from Iterated Learning Improves Compositionality in Large ...
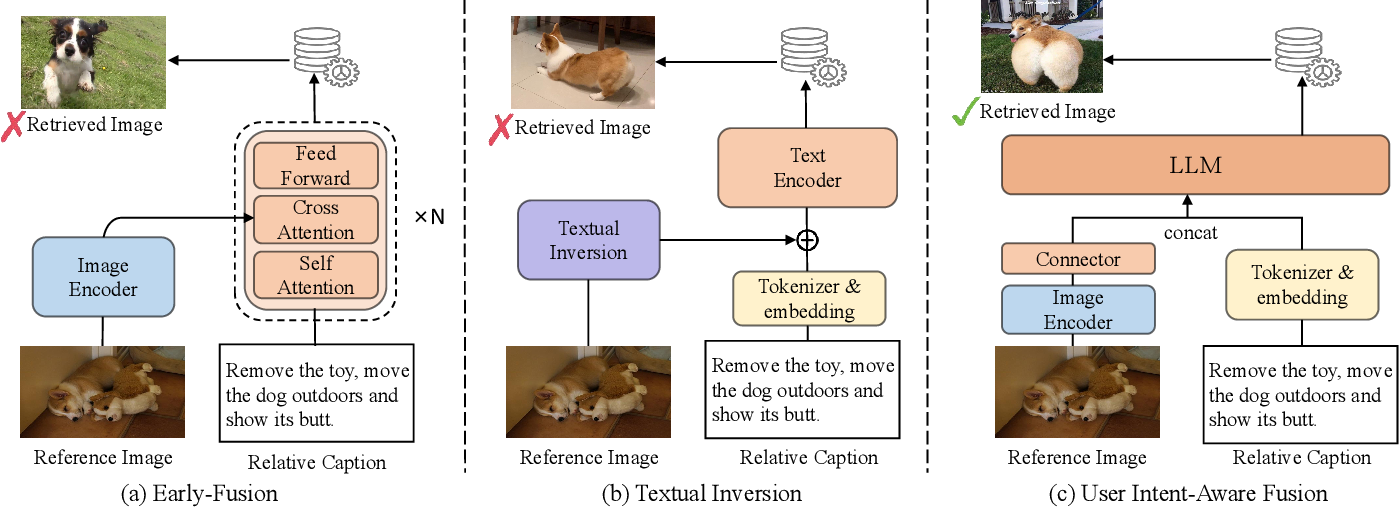
Figure 1 from Leveraging Large Vision-Language Model as User Intent ...
Advertisement Space (336x280)
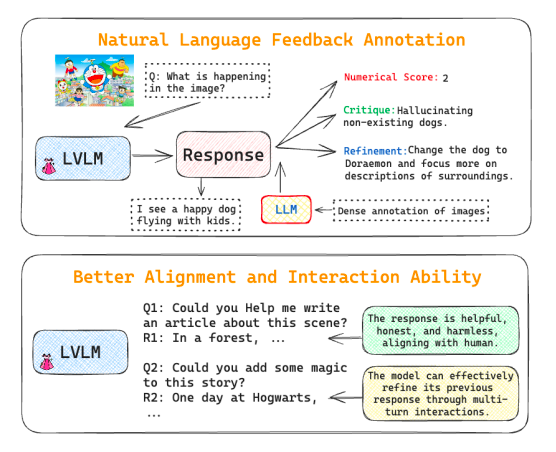
Meet 'DRESS': A Large Vision Language Model (LVLM) that Align and ...

EYE-Llama, an in-domain large language model for ophthalmology - PMC

Figure 2 from Analyzing and Mitigating Object Hallucination in Large ...

Figure 2 from Improving Compositional Text-to-image Generation with ...

[论文评述] E2LVLM:Evidence-Enhanced Large Vision-Language Model for ...
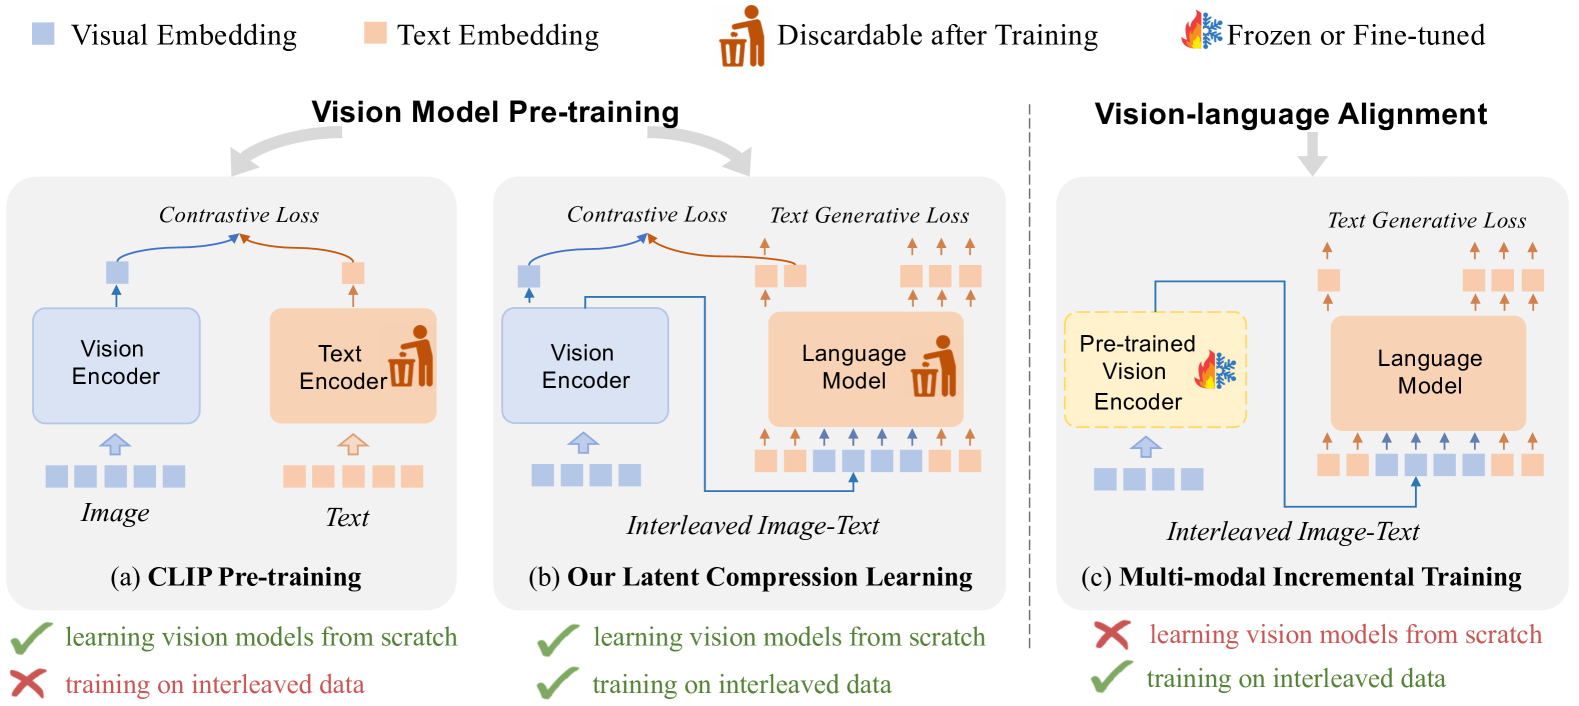
Enhancing Large Vision Language Models with Self-Training on Image ...

Multimodal Large Language Models: Transforming Computer Vision - Edge ...

[论文评述] Vision-Enhanced Large Language Models for High-Resolution Image ...
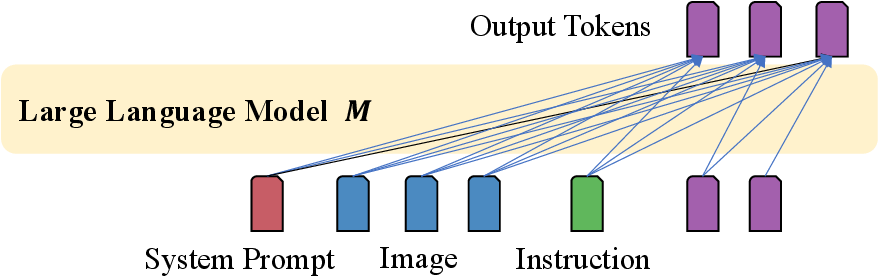
Figure 2 from An Image is Worth 1/2 Tokens After Layer 2: Plug-and-Play ...

Figure 1 from Large Vision-Language Models as Emotion Recognizers in ...
Advertisement Space (336x280)
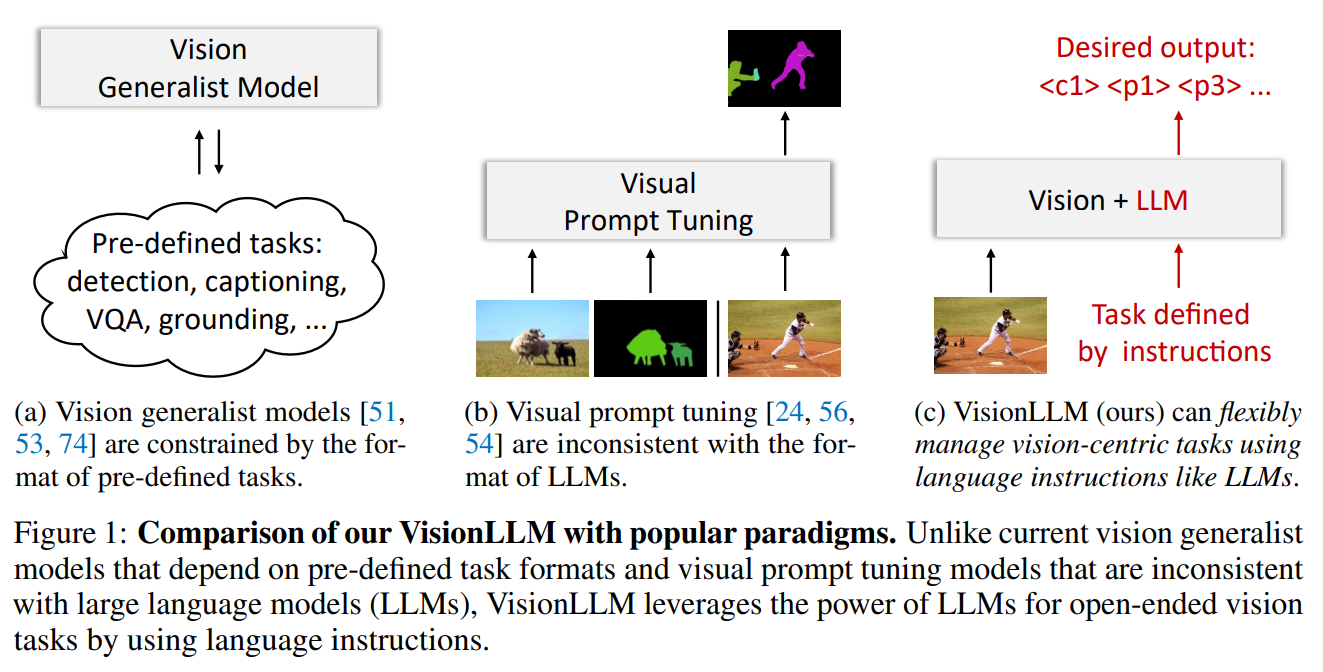
用大模型解决视觉任务:《VisionLLM: Large Language Model is also an Open-Ended ...
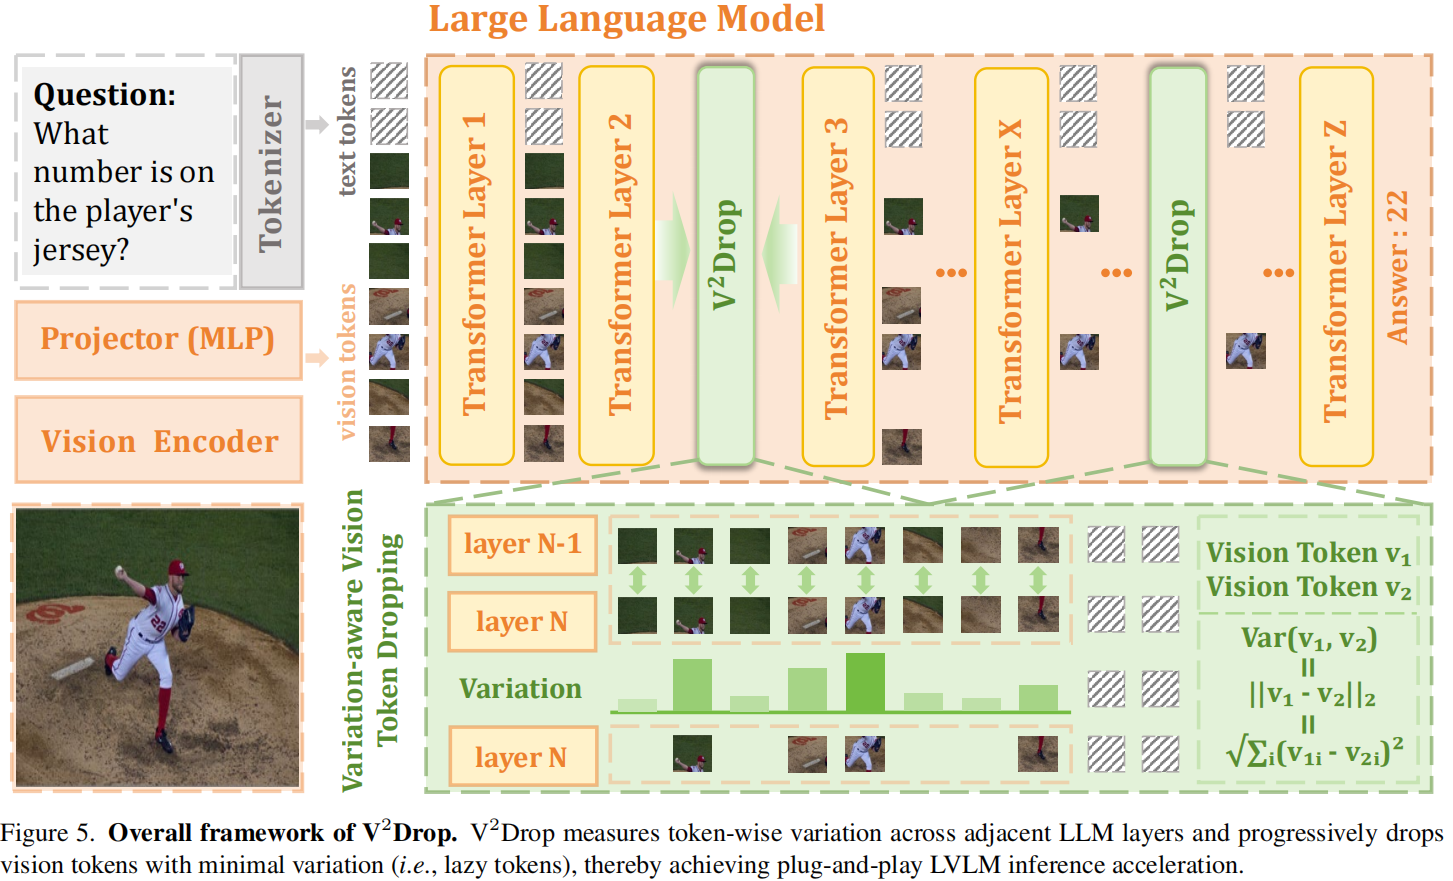
📝 Variation-aware Vision Token Dropping for Faster Large Vision ...

Large Language Models Facilitate Vision Reflection in Image ...

(PDF) LVLM_CSP: Accelerating Large Vision Language Models via ...

Paper page - LVLM-Intrepret: An Interpretability Tool for Large Vision ...

NavGPT-2: Unleashing Navigational Reasoning Capability for Large Vision ...