
Figure 2 From Integer Only Quantized Transformers For Embedded Fpga
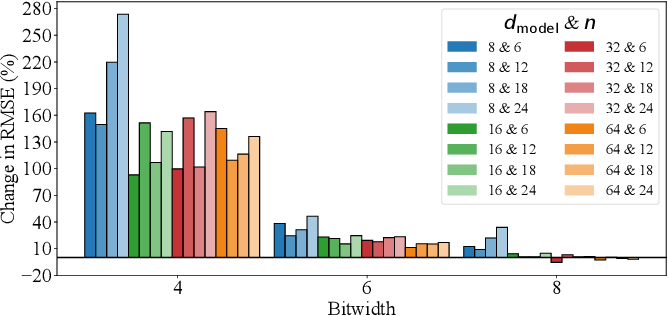
Figure 2 from Integer-only Quantized Transformers for Embedded FPGA ...
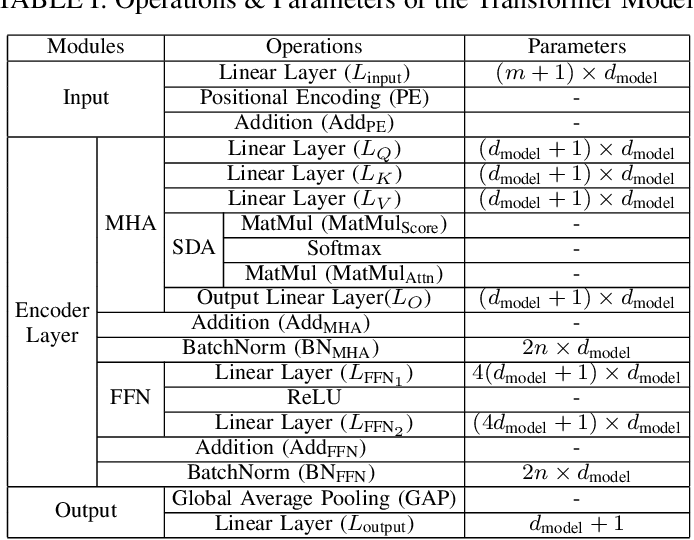
Table I from Integer-only Quantized Transformers for Embedded FPGA ...

Figure 2 from Design and Implementation of Integer Transform and ...

[论文评述] Integer-only Quantized Transformers for Embedded FPGA-based Time ...

Figure 2 from Custom Network Quantization Method for Lightweight CNN ...
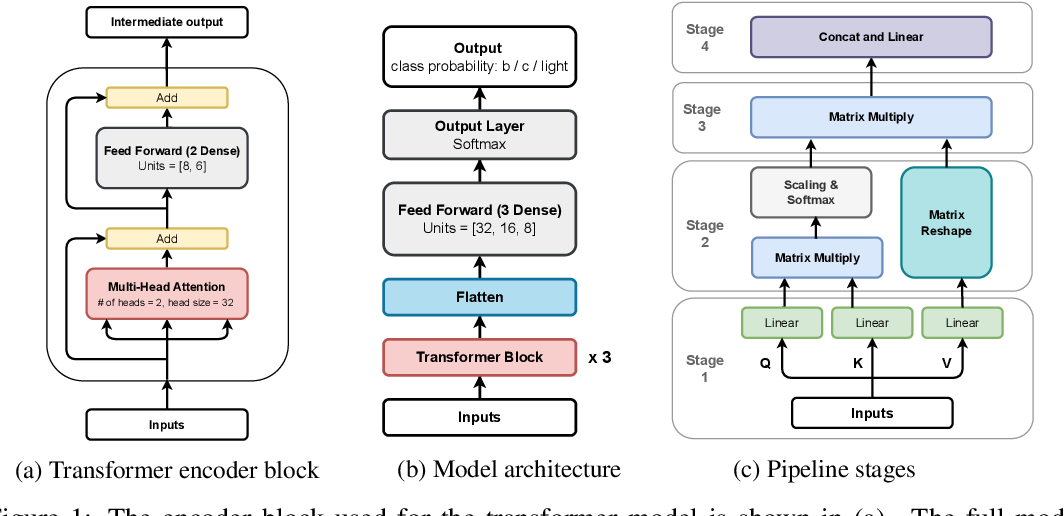
Figure 1 from Ultra Fast Transformers on FPGAs for Particle Physics ...
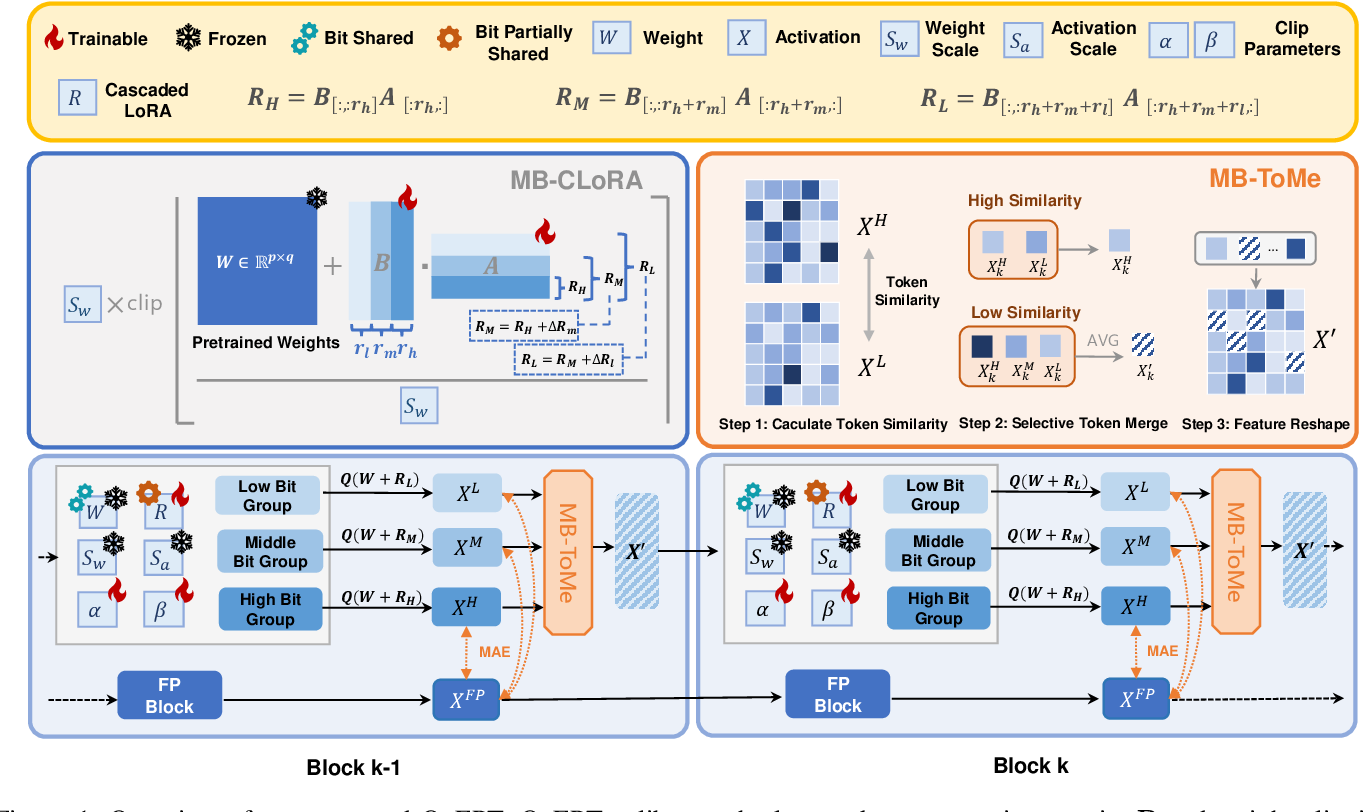
Figure 1 from QuEPT: Quantized Elastic Precision Transformers with One ...

Figure 2 from An FPGA-Based Reconfigurable Accelerator for Convolution ...

Figure 3 from LLM-FP4: 4-Bit Floating-Point Quantized Transformers ...

Figure 5 from Design and FPGA Implementation of Integer Transform and ...
Advertisement Space (300x250)

Figure 1 from Hierarchical Vector Quantized Transformer for Multi-class ...

Figure 2 from Vector Quantized Underwater Image Enhancement With ...
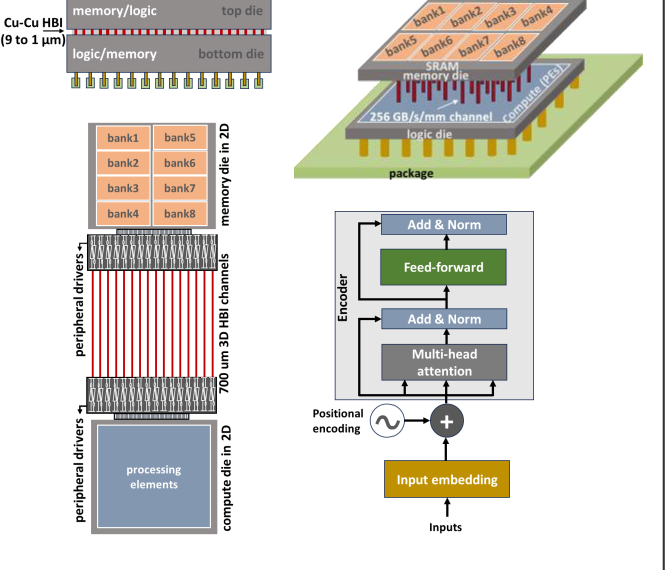
Figure 2 from 1.536TB/s/mm2 Bandwidth Scalable Attention Accelerator ...

Figure 1 from Custom Network Quantization Method for Lightweight CNN ...

Figure 3 from Custom Network Quantization Method for Lightweight CNN ...
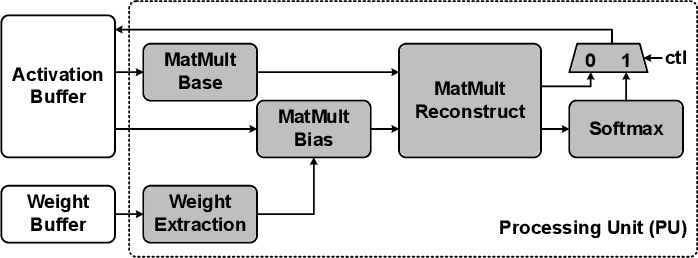
Figure 2 from Energy Efficient FPGA-Based Binary Transformer ...
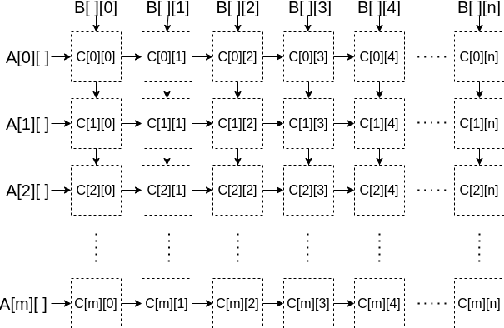
Figure 2 from Hardware Acceleration of Transformer Networks using FPGAs ...

Figure 1 from A Cost-Efficient FPGA Implementation of Tiny Transformer ...

Figure 1 from Post-Training Quantization for Vision Transformer in ...

[论文评述] Learning Graph Quantized Tokenizers for Transformers
Advertisement Space (336x280)

Figure 1 from FPGA-Based Implementation of the Quantized Neural Network ...

Figure 1 from Towards Accurate Post-Training Quantization for Vision ...

Figure 5 from A Cost-Efficient FPGA Implementation of Tiny Transformer ...

Figure 1 from FPGA-Based Implementation of the Quantized Neural Network ...
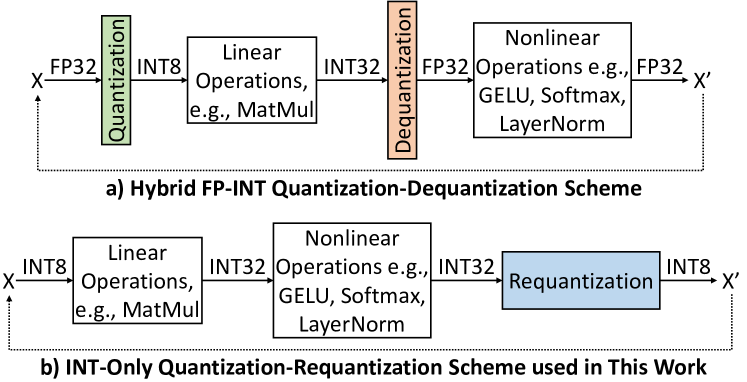
[2304.03986] SwiftTron: An Efficient Hardware Accelerator for Quantized ...

Efficient Integer Quantization for Compressed DETR Models
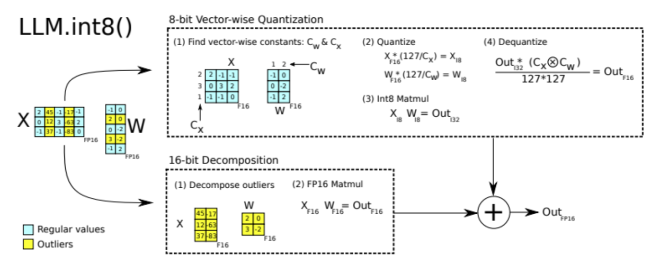
Fast and Accurate GPU Quantization for Transformers

FPGA implementation of the JPEG XR for onboard earth-observation ...
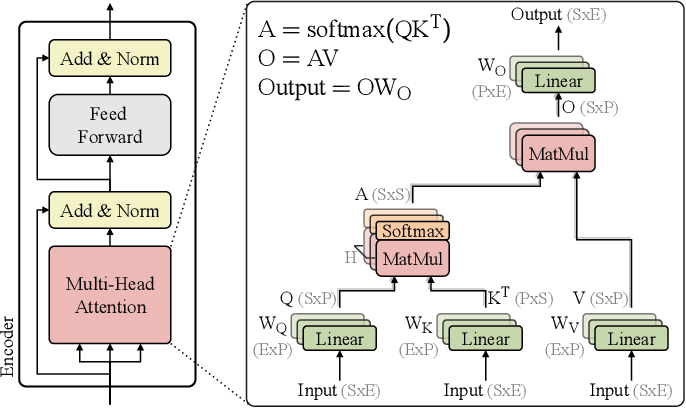
Figure 1 from ITA: An Energy-Efficient Attention and Softmax ...

Figure 1 from Efficient 8-Bit Quantization of Transformer Neural ...
Advertisement Space (336x280)
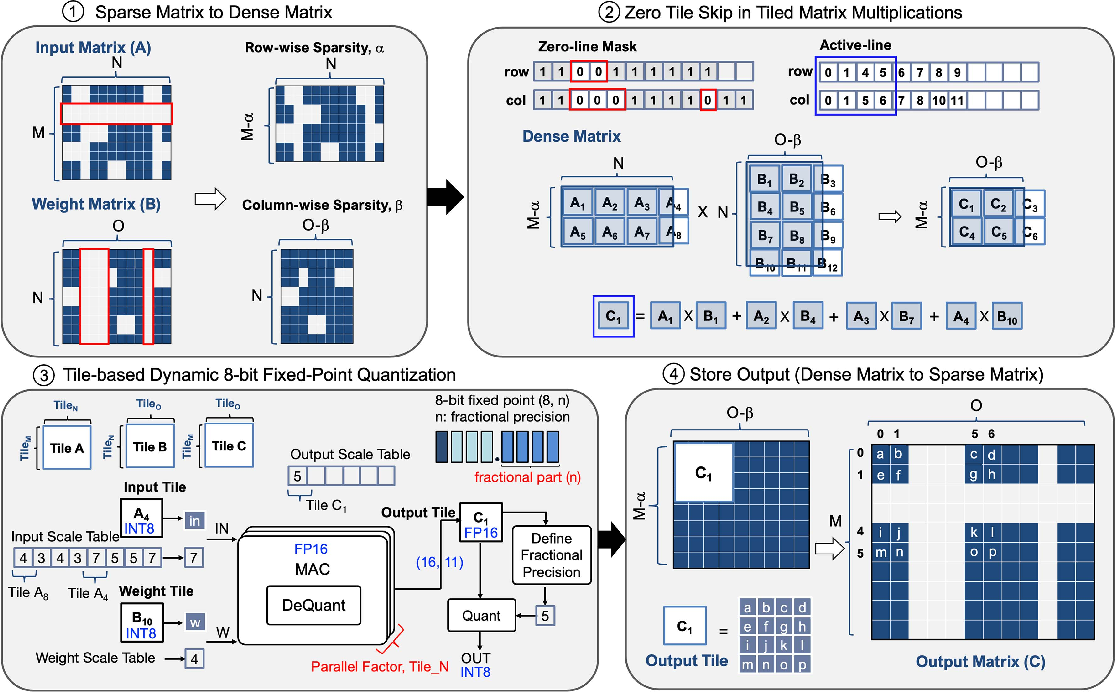
Figure 1 from Mobile Transformer Accelerator Exploiting Various Line ...
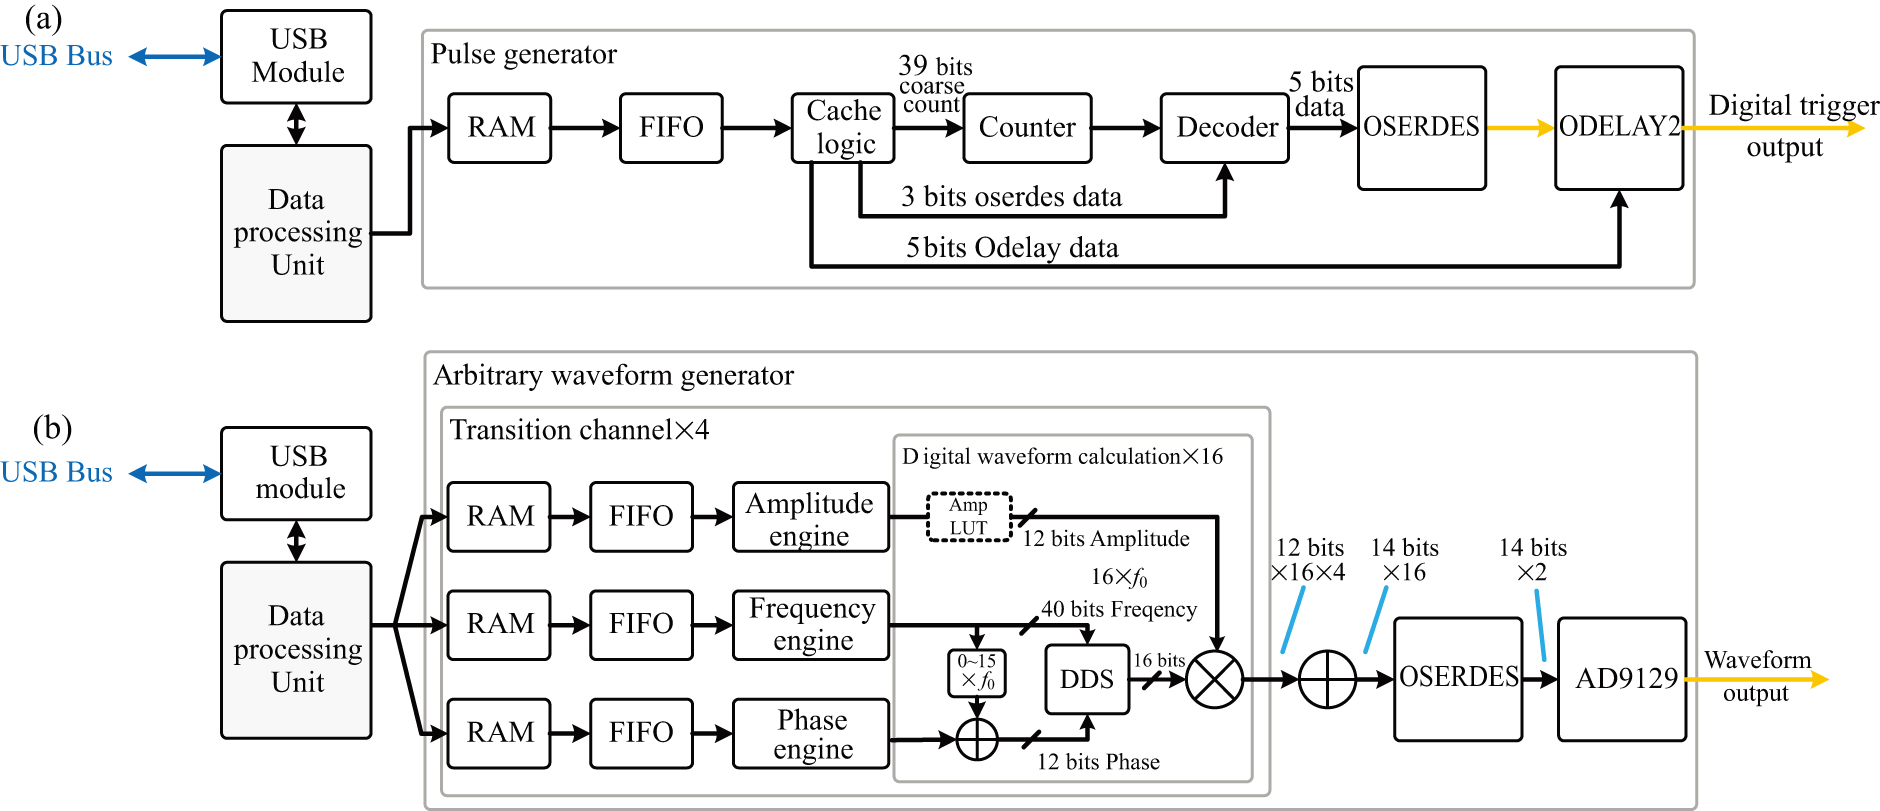
FPGA based hardware platform for trapped-ion-based multi-level quantum ...
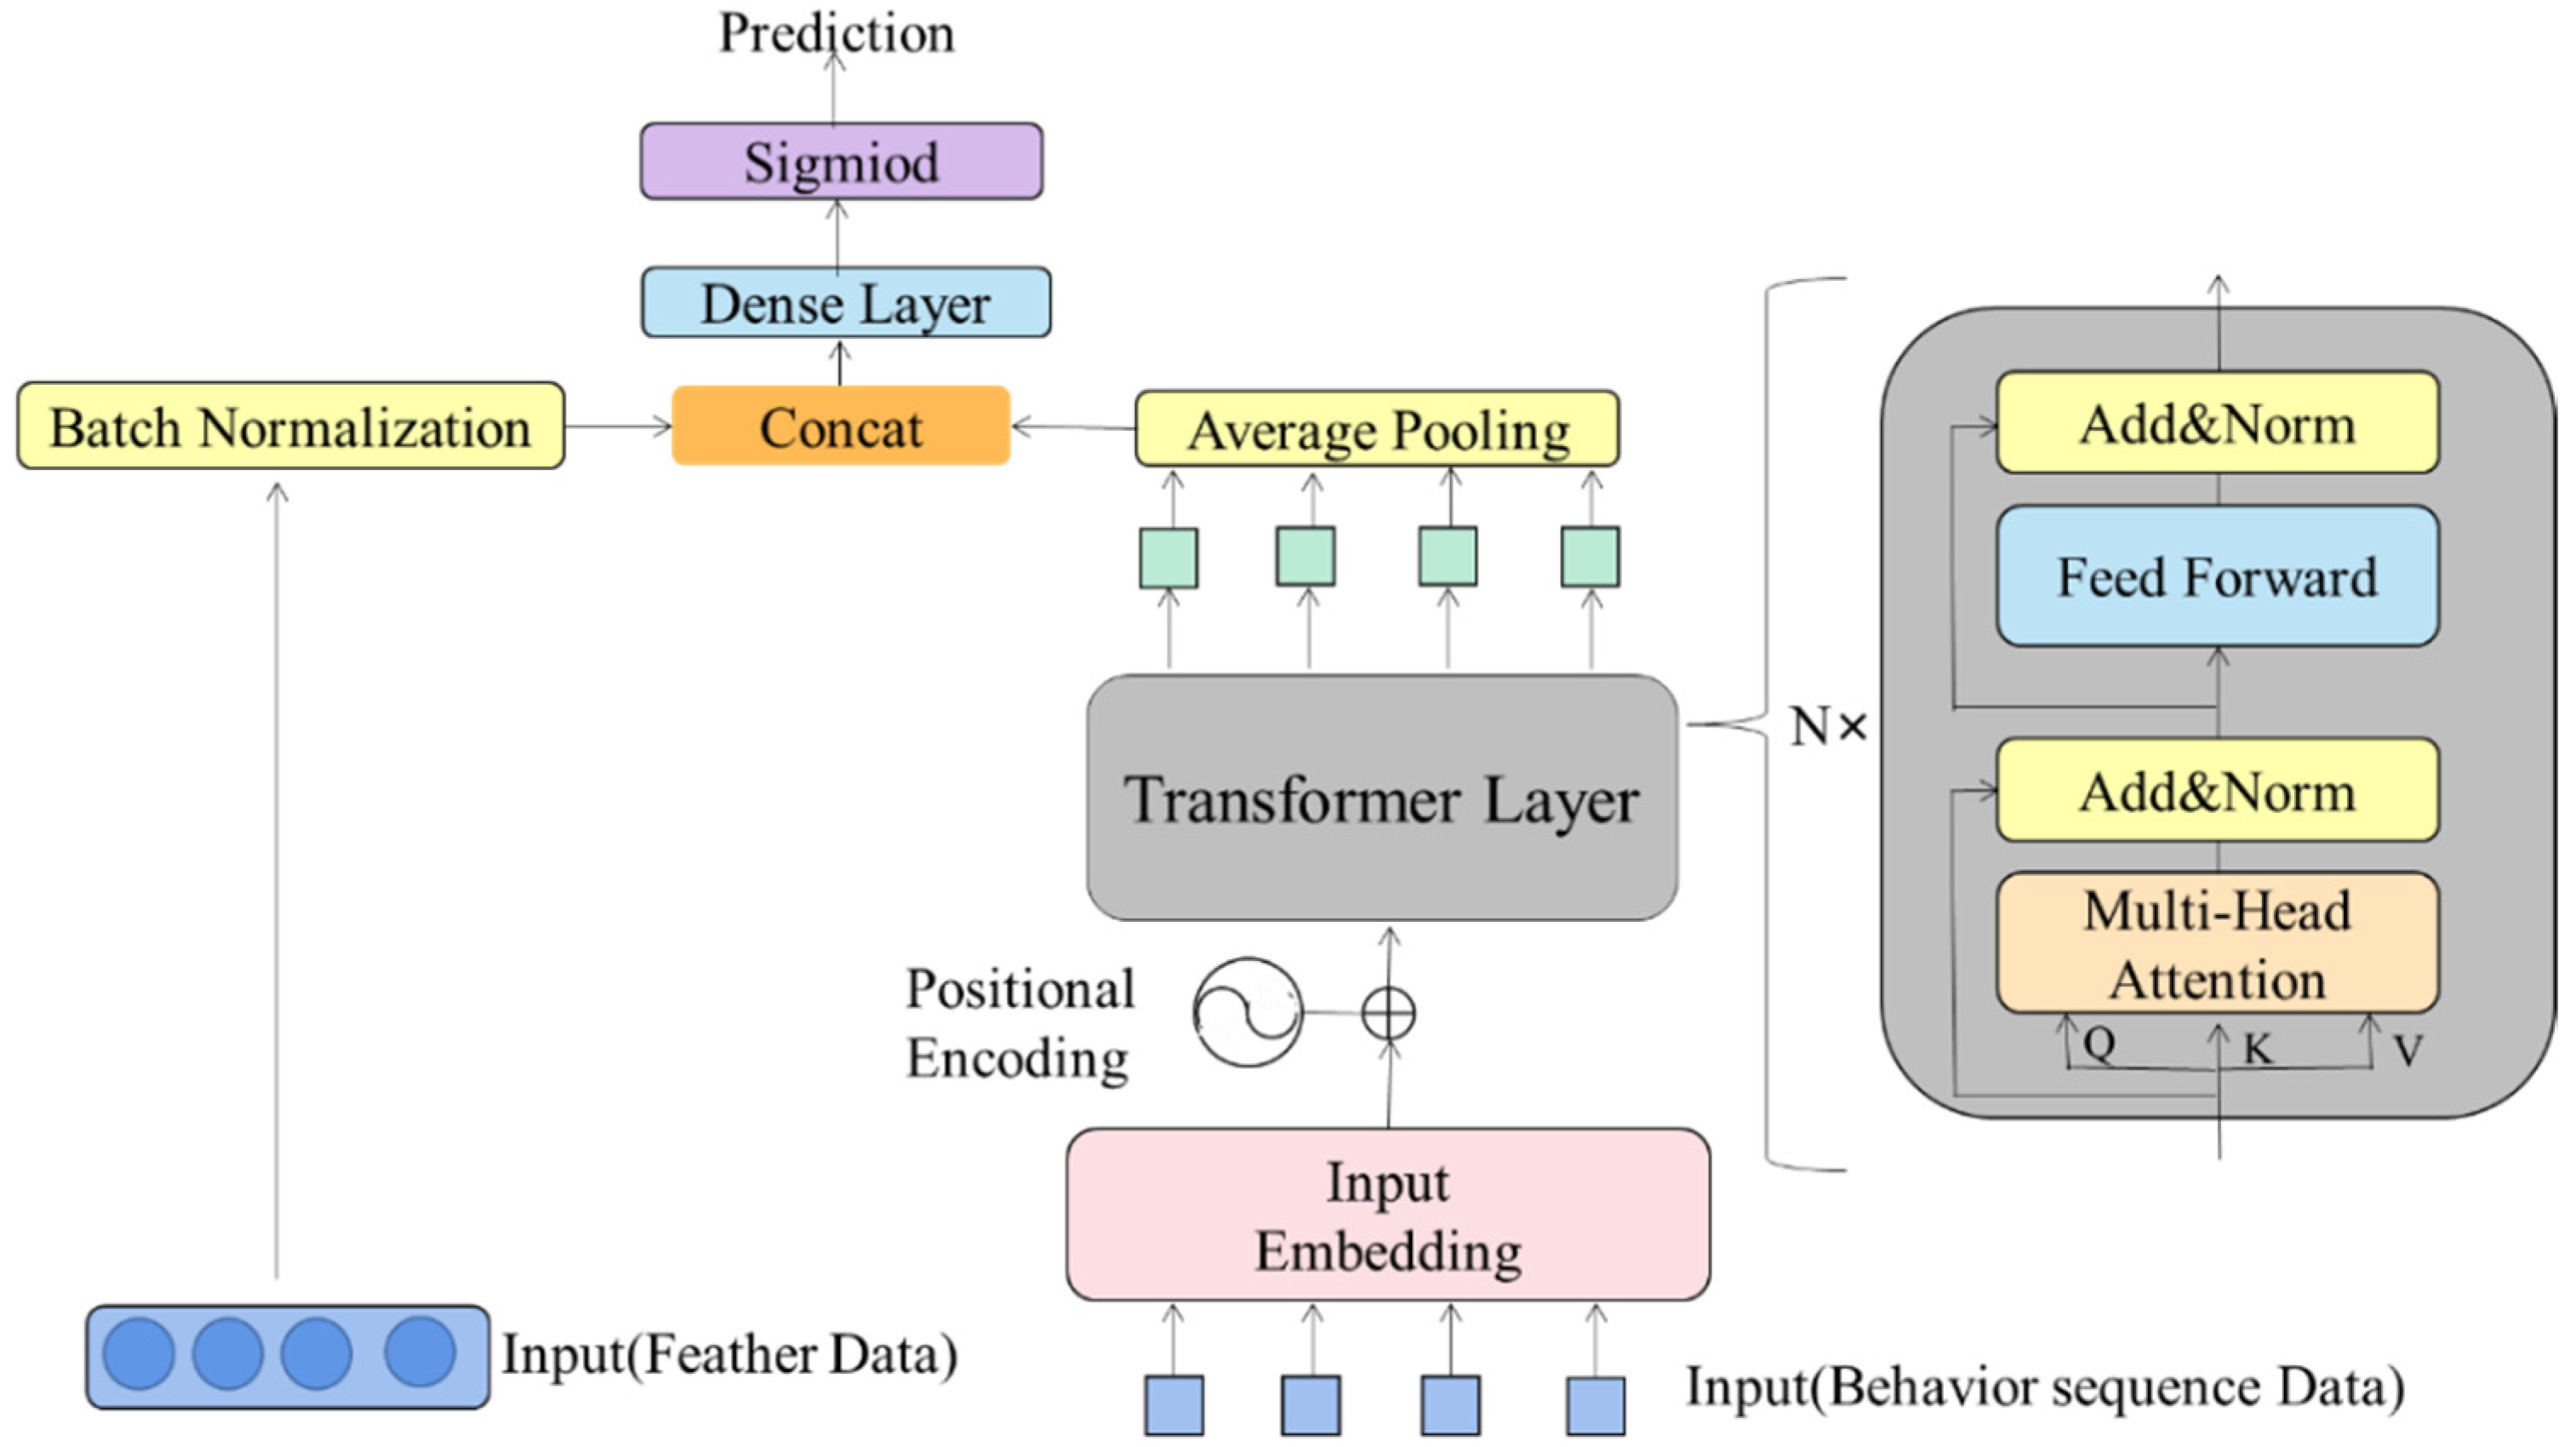
A Deep Learning Approach for Credit Scoring Using Feature Embedded ...

Hierarchical Vector Quantized Transformer for Multi-class Unsupervised ...

[論文レビュー] Lightweight Embedded FPGA Deployment of Learned Image ...

TCU-Net: Transformer Embedded in Convolutional U-Shaped Network for ...