
Figure 2 From Introducing Depth Into Transformer Based 3d Object

Figure 2 from Introducing Depth into Transformer-based 3D Object ...

Figure 1 from Introducing Depth into Transformer-based 3D Object ...

Figure 3 from Introducing Depth into Transformer-based 3D Object ...

Figure 4 from Introducing Depth into Transformer-based 3D Object ...

Figure 5 from Introducing Depth into Transformer-based 3D Object ...

Table 2 from Introducing Depth into Transformer-based 3D Object ...
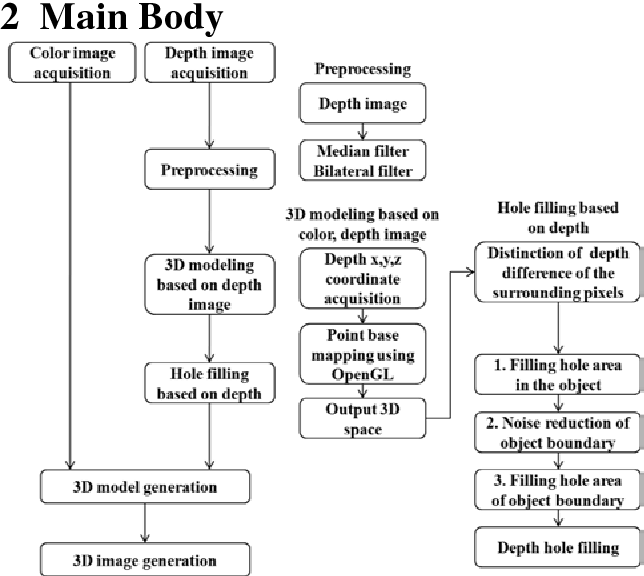
Figure 1 from Depth Image Based 3D Object Model Generation | Semantic ...

Table 3 from Introducing Depth into Transformer-based 3D Object ...

Table 1 from Introducing Depth into Transformer-based 3D Object ...

Table 4 from Introducing Depth into Transformer-based 3D Object ...
Advertisement Space (300x250)
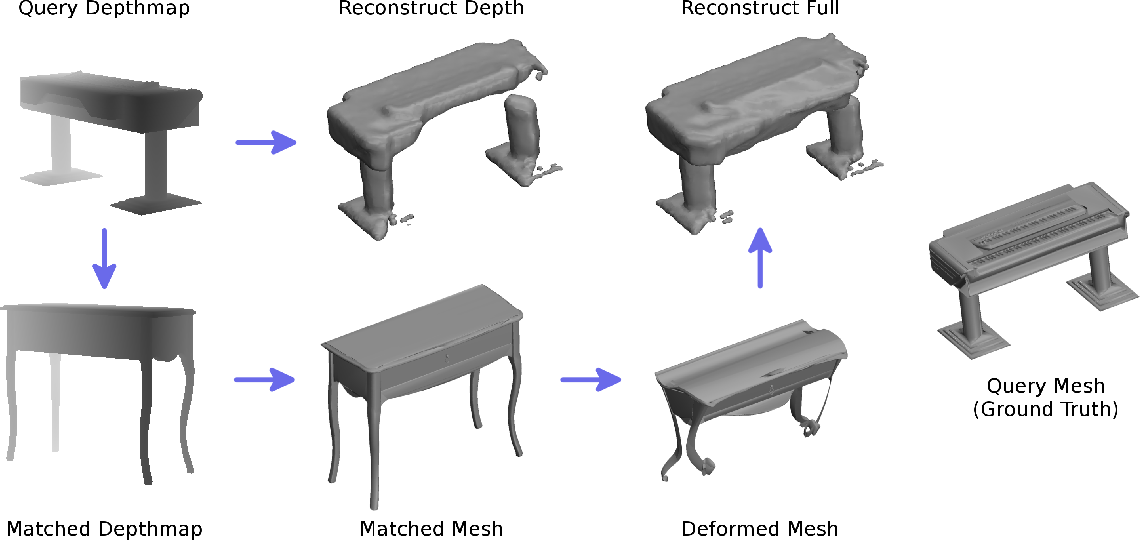
Figure 2 from Completing 3D object shape from one depth image ...

Figure 2 from SGFormer: Spherical Geometry Transformer for 360 Depth ...

Figure 2 from Depth Super-Resolution by Texture-Depth Transformer ...

Figure 2 from Recurrent Transformer for 3D Human Pose Estimation ...

Figure 2 from Depth Estimation with Simplified Transformer | Semantic ...

Figure 1 from Voxel Transformer with Shifted Windows for 3D Object ...

Figure 2 from Unsupervised Full Transformer for Pose, Depth and Optical ...

Figure 2 from Applying auxiliary supervised depth-assisted transformer ...

[BEV] DA-BEV : Depth Aware BEV Transformer for 3D Object Detection - 知乎

DA-BEV: Depth Aware BEV Transformer for 3D Object Detection
Advertisement Space (336x280)
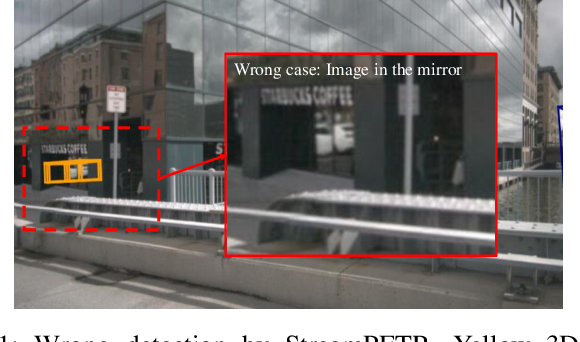
Figure 1 from DQ3D: Depth-guided Query for Transformer-Based 3D Object ...

[BEV] DA-BEV : Depth Aware BEV Transformer for 3D Object Detection - 知乎

Figure 2 from Transformer-based Global 3D Hand Pose Estimation in Two ...

Figure 2 from TranSal: Depth-guided Transformer for RGB-D Salient ...

Figure 2 from Depth Estimation From Surface-Ground Correspondence for ...

Figure 2 from Improving Deep Transformer with Depth-Scaled ...

Figure 1 from Fully Cross-Attention Transformer for Guided Depth Super ...

Figure 1 from Depth Estimation Algorithm Based on Transformer-Encoder ...

Figure 2 from Transformer-Based Self-Supervised Monocular Depth and ...

Figure 2 from Depth-Adaptive Transformer | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from ViTA: Video Transformer Adaptor for Robust Video Depth ...
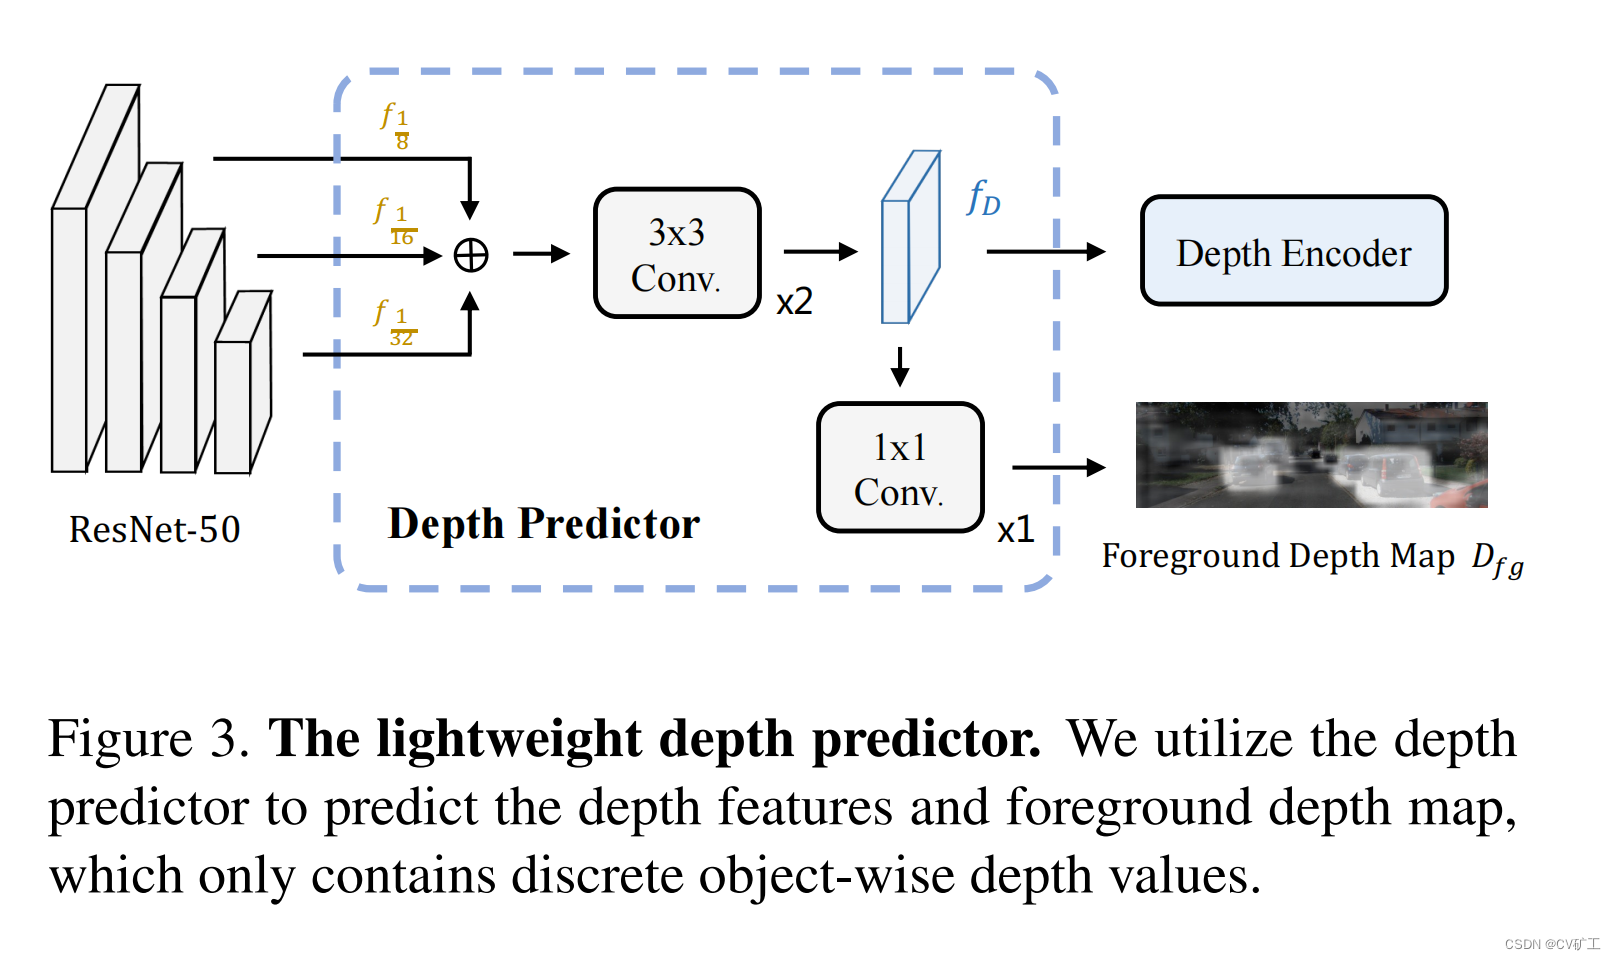
MonoDETR: Depth-guided Transformer for Monocular 3D Object Detection 论文解读

MonoDETR: Depth-guided Transformer for Monocular 3D Object Detection论文 ...
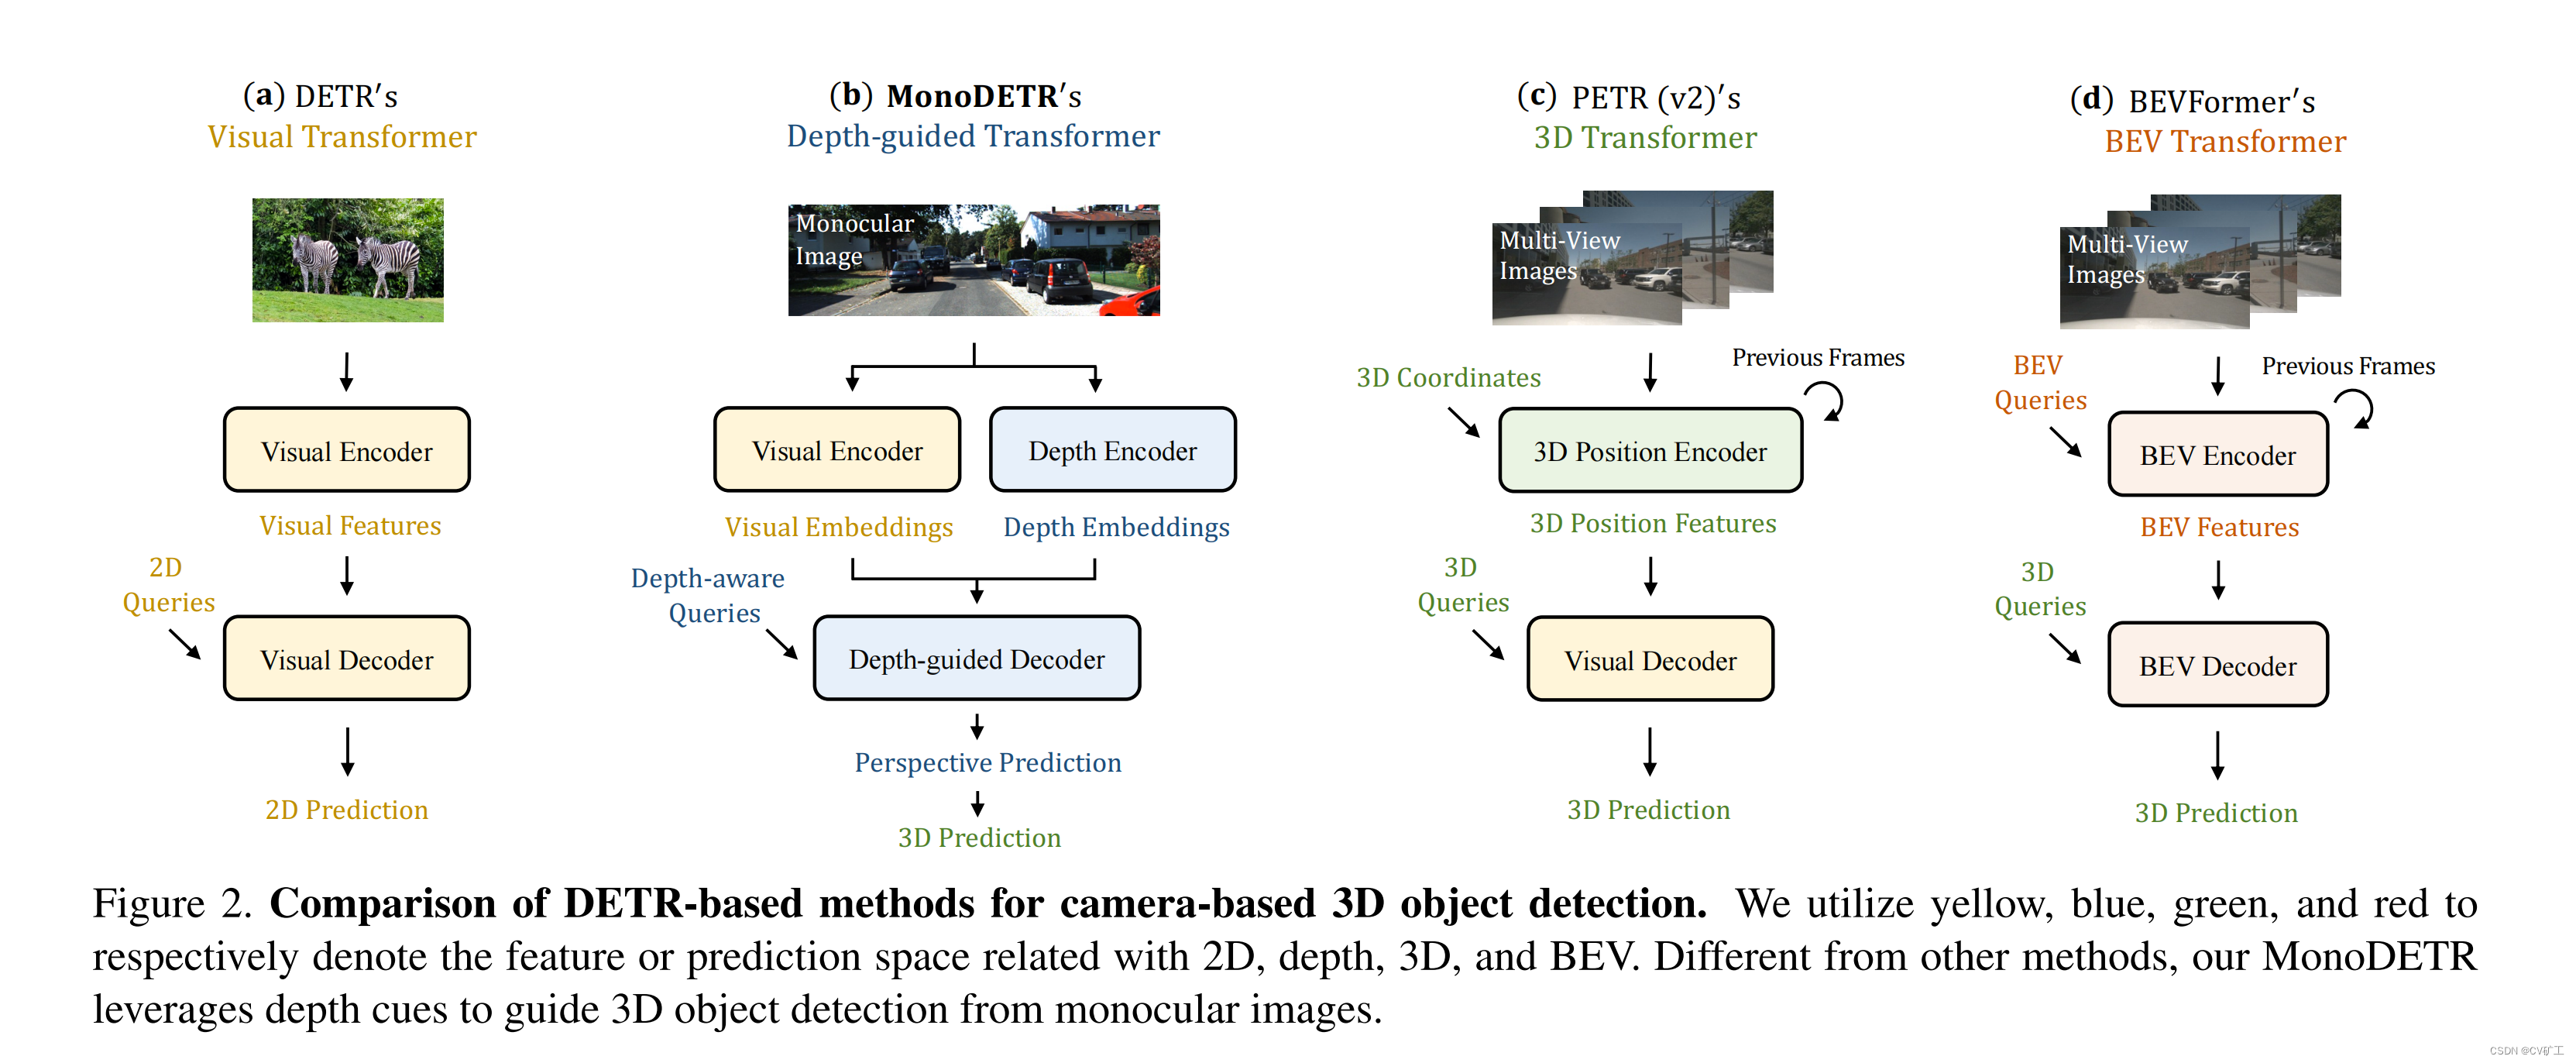
MonoDETR: Depth-guided Transformer for Monocular 3D Object Detection 论文解读

[2203.13310] MonoDETR: Depth-guided Transformer for Monocular 3D Object ...
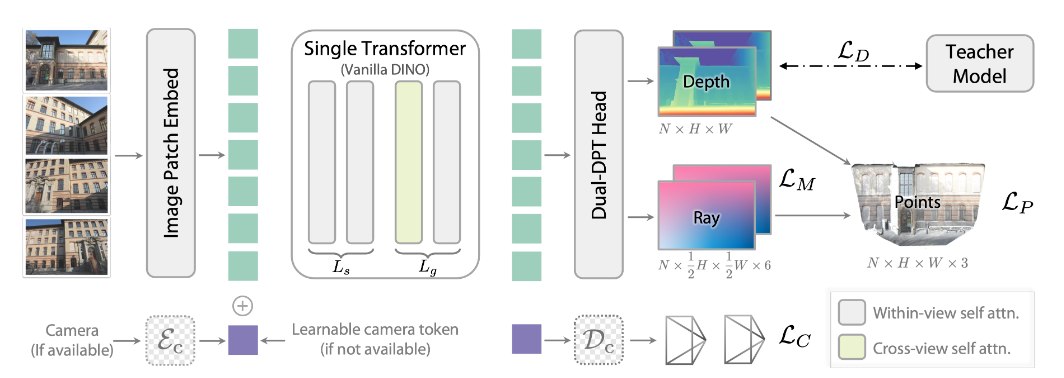
Depth Anything 3:单一 Transformer 击败 VGGT,全景视角的 3D 几何新范式_depthanything3 ...