
Figure 2 From Rethinking Masked Representation Learning For 3d Point
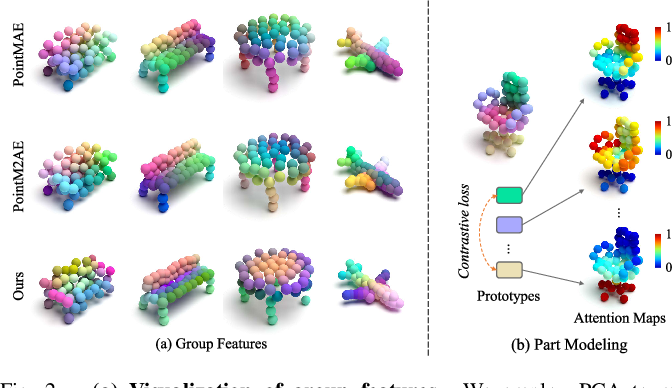
Figure 2 from Rethinking Masked Representation Learning for 3D Point ...
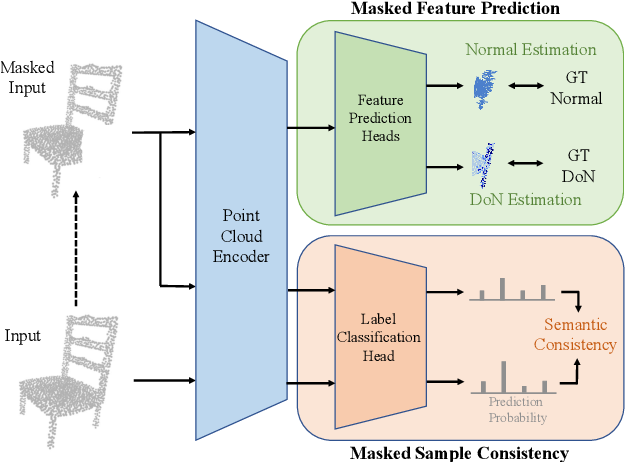
Figure 1 from Masked Local-Global Representation Learning for 3D Point ...

Figure 1 from Masked Local-Global Representation Learning for 3D Point ...

Figure 1 from Masked Local-Global Representation Learning for 3D Point ...

Figure 2 from Masked Autoencoders in 3D Point Cloud Representation ...

Rethinking Masked Representation Learning for 3D Point Cloud Understanding

Figure 2 from Masked Representation Learning for Domain Generalized ...

Rethinking Masked Representation Learning for 3D Point Cloud Understanding

Rethinking Masked Representation Learning for 3D Point Cloud Understanding
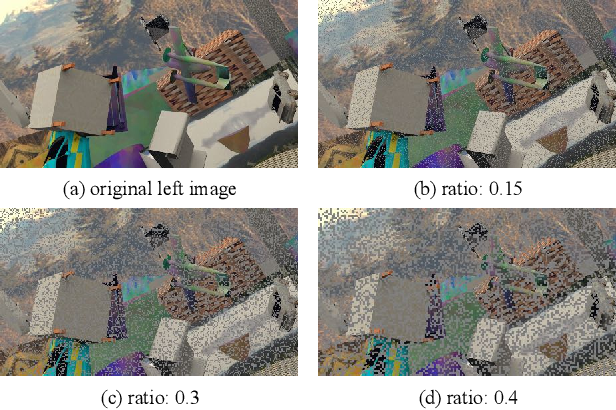
Figure 2 from Masked Representation Learning for Domain Generalized ...
Advertisement Space (300x250)

Figure 1 from Joint Representation Learning for Text and 3D Point Cloud ...

Rethinking Masked Representation Learning for 3D Point Cloud Understanding

Figure 2 from Point Cloud Self-supervised Learning via 3D to Multi-view ...

Figure 3 from Masked Autoencoders in 3D Point Cloud Representation ...

Figure 1 from Masked Autoencoders in 3D Point Cloud Representation ...

Figure 5 from Masked Autoencoders in 3D Point Cloud Representation ...

Figure 2 from Masked Contrastive Representation Learning | Semantic Scholar

Figure 2 from Masked Modeling for Self-supervised Representation ...

Figure 2 from Learning 3D Representations from 2D Pre-Trained Models ...

Figure 2 from Masked Motion Predictors are Strong 3D Action ...
Advertisement Space (336x280)

Figure 2 from Towards Compact 3D Representations via Point Feature ...

Figure 2 from Masked Video Distillation: Rethinking Masked Feature ...
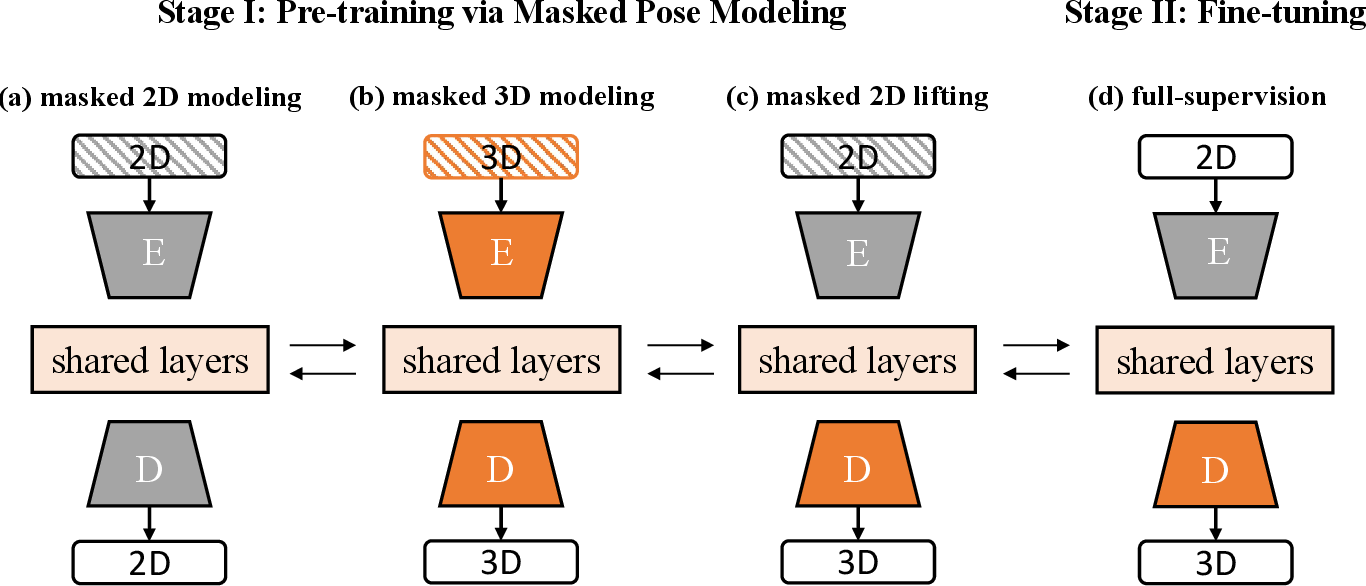
Figure 2 from MPM: A Unified 2D-3D Human Pose Representation via Masked ...

(PDF) Masked Autoencoders in 3D Point Cloud Representation Learning

Figure 1 from Rethinking Masked-Autoencoder-Based 3D Point Cloud ...

Figure 2 from Mask3D for 3D Semantic Instance Segmentation | Semantic ...

Figure 1 from Self-Supervised 3D Action Representation Learning with ...

Figure 1 from Representation Learning for Visual Object Tracking by ...

Figure 2 from M3Video: Masked Motion Modeling for Self-Supervised Video ...

Figure 2 from Self-supervised Video Representation Learning with Motion ...
Advertisement Space (336x280)

(PDF) Learning geometry-image representation for 3D point cloud generation

Self-supervised Adversarial Masking for 3D Point Cloud Representation ...

Masked Autoencoder for Pre-Training on 3D Point Cloud Object Detection

Figure 1 from Towards Compact 3D Representations via Point Feature ...

MASH: Masked Anchored SpHerical Distances for 3D Shape Representation ...

Figure 1 from MPM: A Unified 2D-3D Human Pose Representation via Masked ...