
Figure 2 From Transformer Based Knowledge Distillation For Efficient
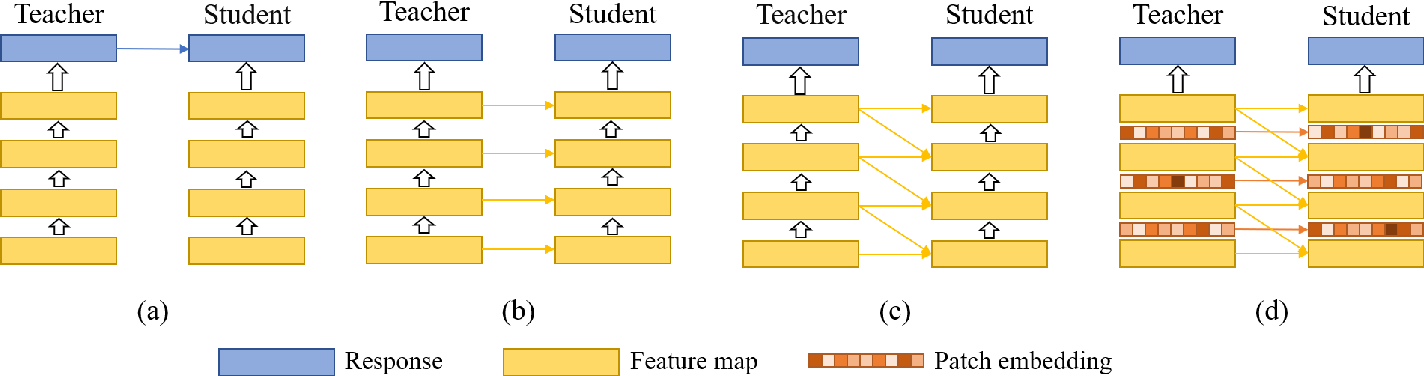
Figure 2 from TransKD: Transformer Knowledge Distillation for Efficient ...
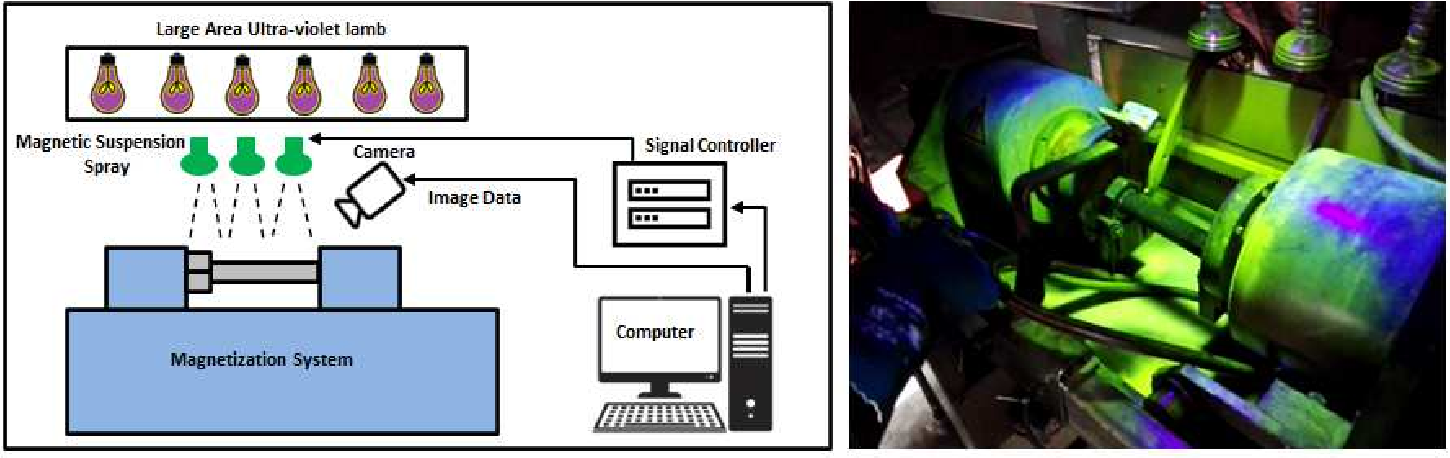
Figure 2 from Vision Transformer based knowledge distillation for ...

Figure 2 from Transformer-based Knowledge Distillation for Efficient ...
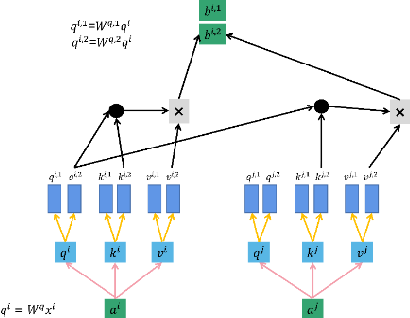
Figure 2 from Vision Transformer Based on Knowledge Distillation in TCM ...
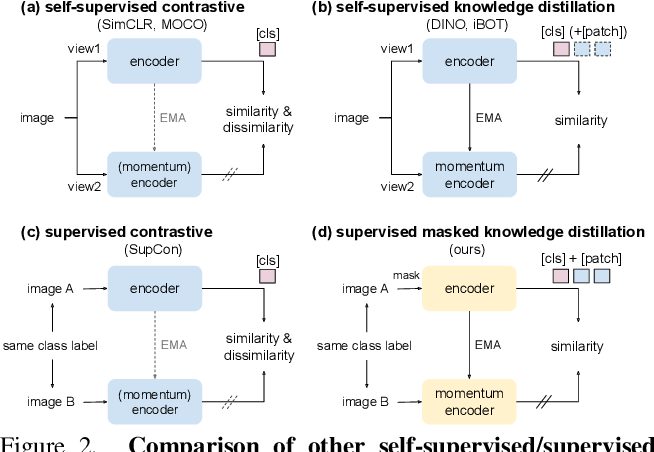
Figure 2 from Supervised Masked Knowledge Distillation for Few-Shot ...

Figure 2 from Knowledge Distillation via the Target-aware Transformer ...

Figure 2 from A Distributed Knowledge Distillation Framework for ...
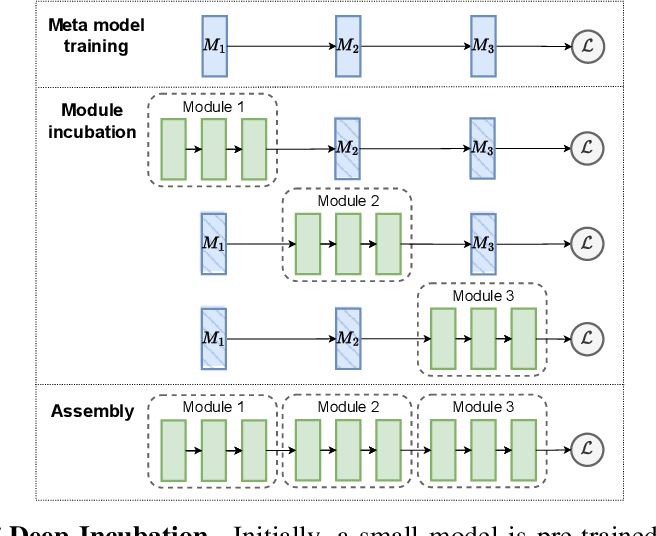
Figure 2 from m2mKD: Module-to-Module Knowledge Distillation for ...
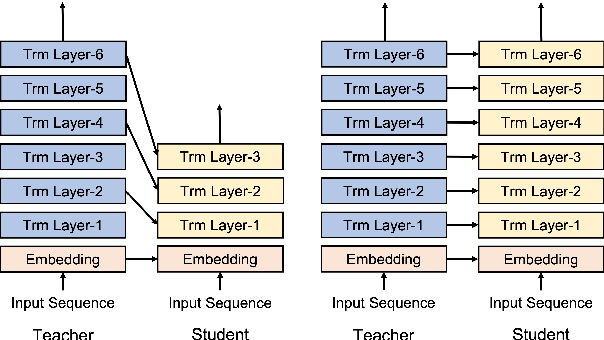
Figure 2 from Understanding and Improving Knowledge Distillation for ...
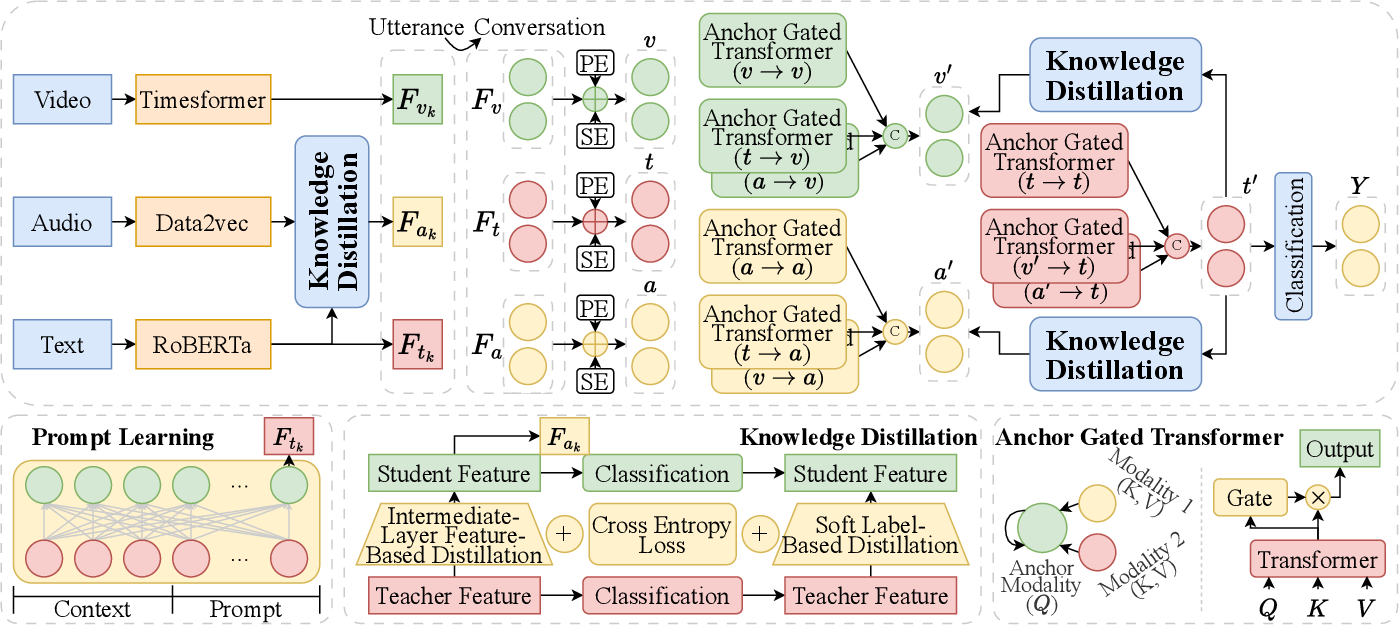
Figure 2 from Multi-modal Anchor Gated Transformer with Knowledge ...
Advertisement Space (300x250)
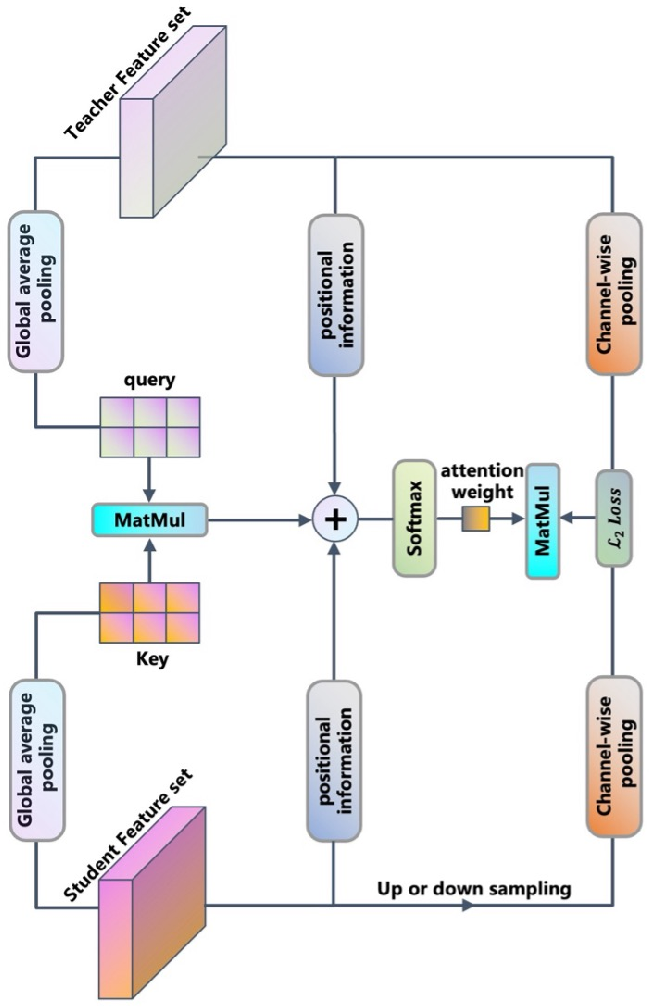
Figure 2 from TAKD: A Temporal Attention-Based Knowledge Distillation ...
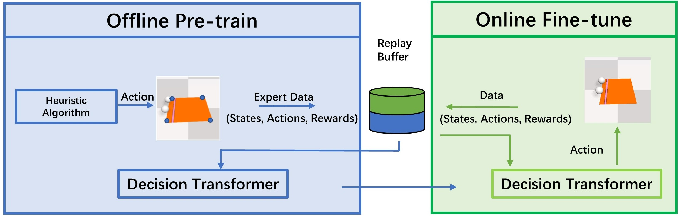
Figure 2 from TraKDis: A Transformer-Based Knowledge Distillation ...

Paper page - TransKD: Transformer Knowledge Distillation for Efficient ...
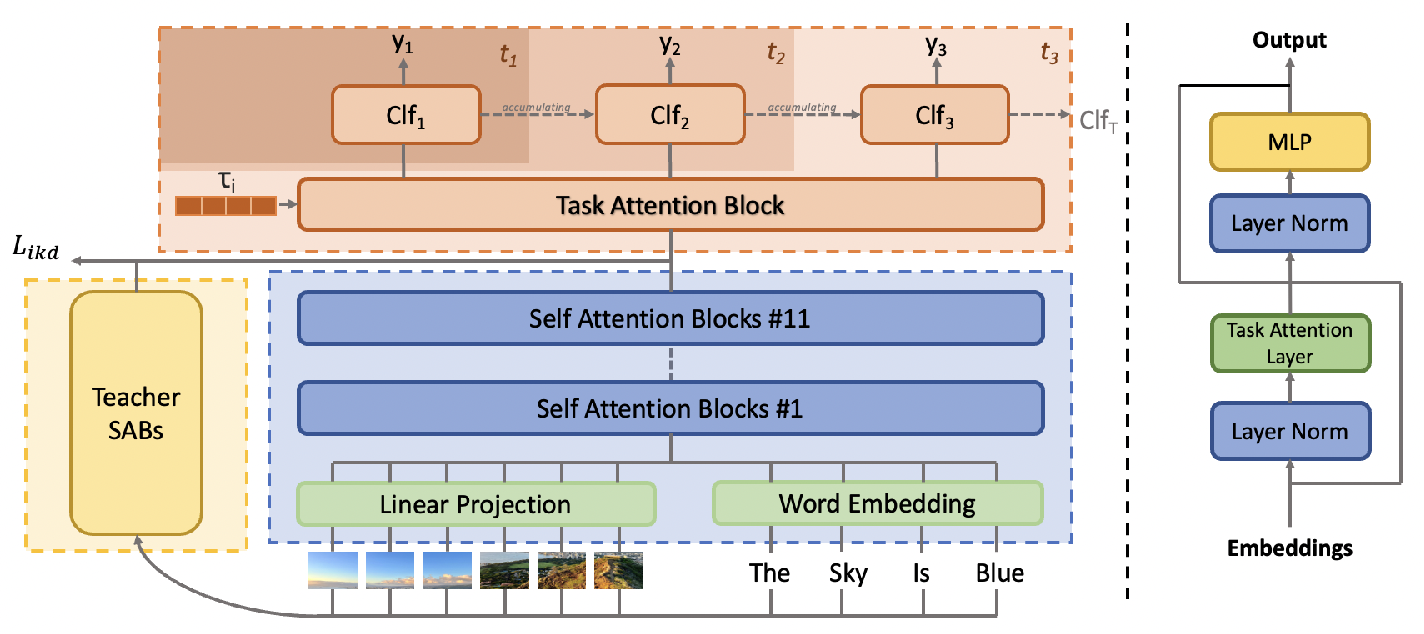
Figure 2 from Task-Attentive Transformer Architecture for Continual ...

Figure 2 from MVKD-Trans: A Multi-View Knowledge Distillation Vision ...
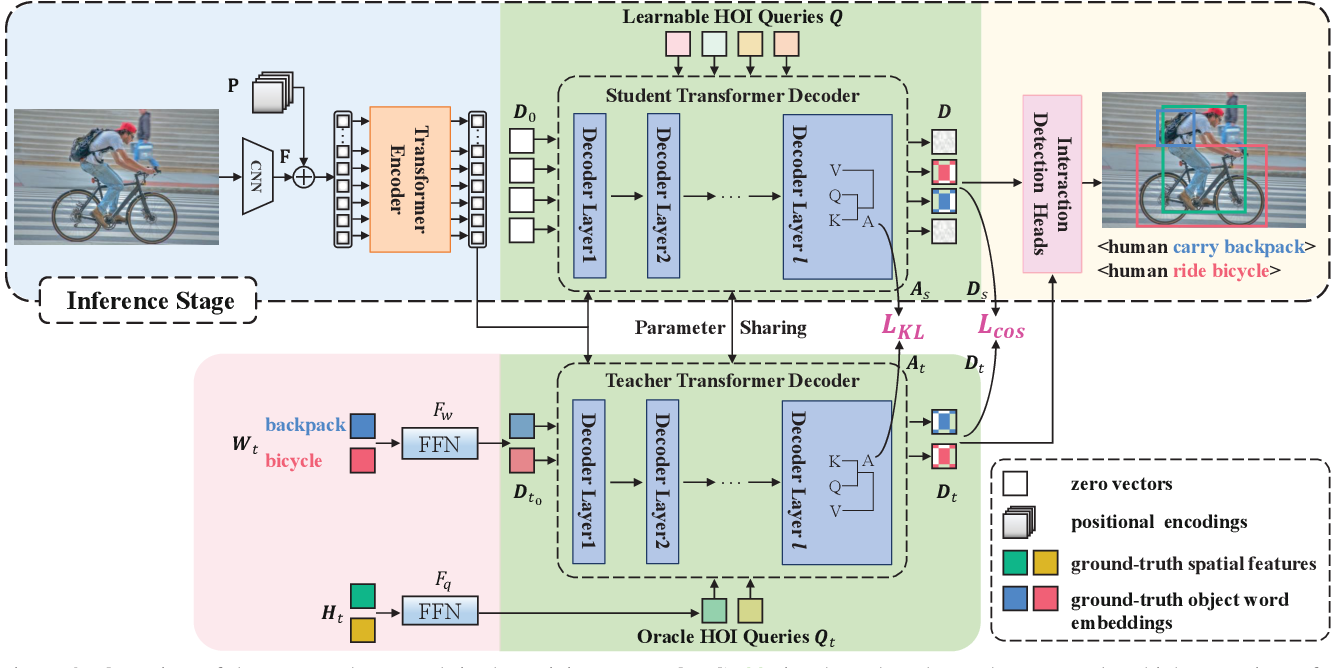
Figure 2 from Distillation Using Oracle Queries for Transformer-based ...
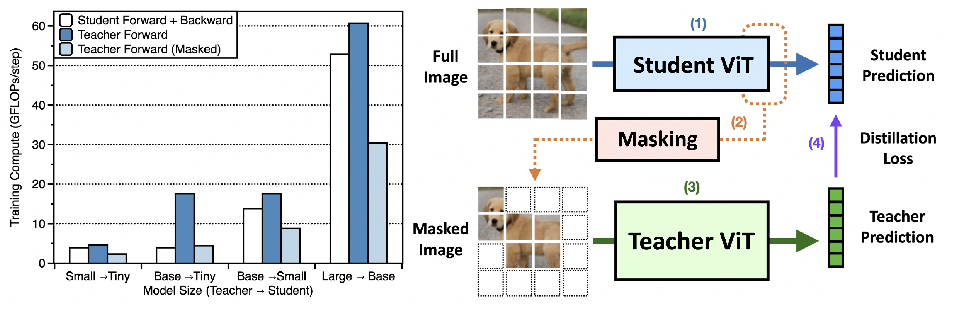
Figure 1 from The Role of Masking for Efficient Supervised Knowledge ...
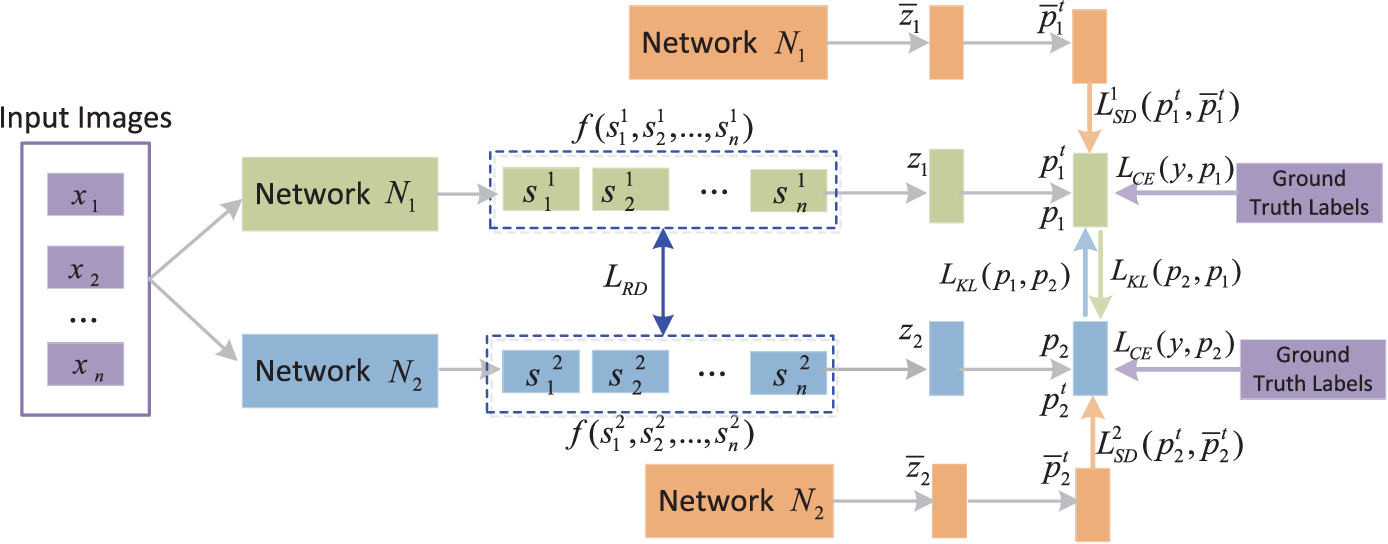
Figure 2 from Collaborative Knowledge Distillation via Multiknowledge ...
TransKD: Transformer Knowledge Distillation for Efficient Semantic ...
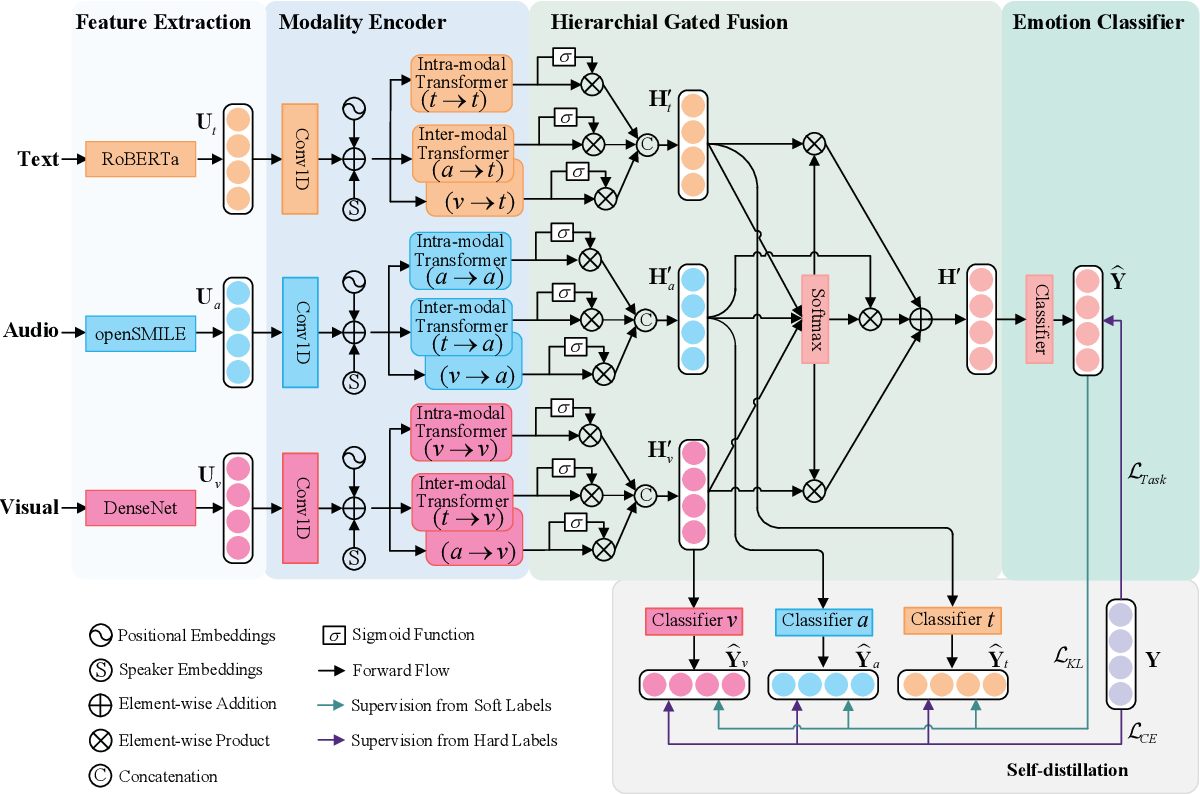
Figure 2 from A Transformer-Based Model With Self-Distillation for ...
Advertisement Space (336x280)

Knowledge Distillation for Efficient Transformer-Based Reinforcement ...

Figure 2 from Curriculum-Based Knowledge Distillation: From Ranking to ...
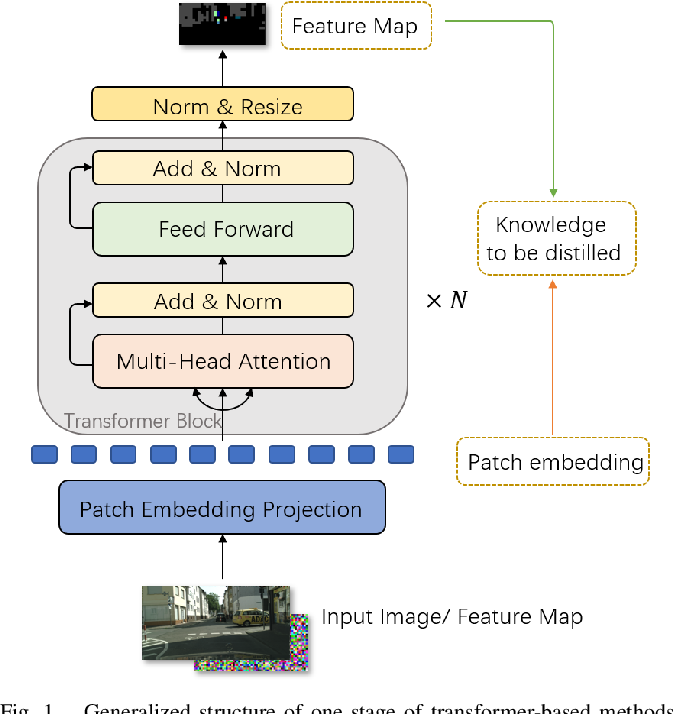
Transformer-based Knowledge Distillation for Efficient Semantic ...
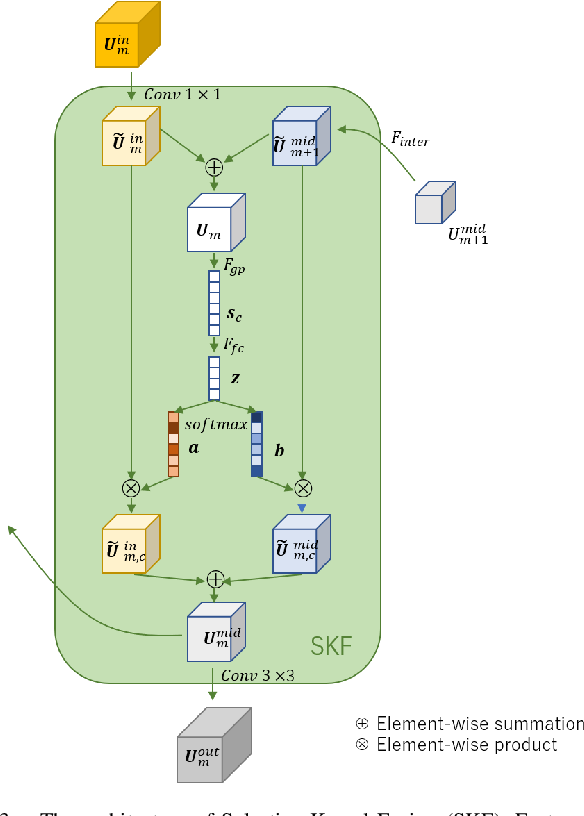
Transformer-based Knowledge Distillation for Efficient Semantic ...

(PDF) Transformer-based Knowledge Distillation for Efficient Semantic ...
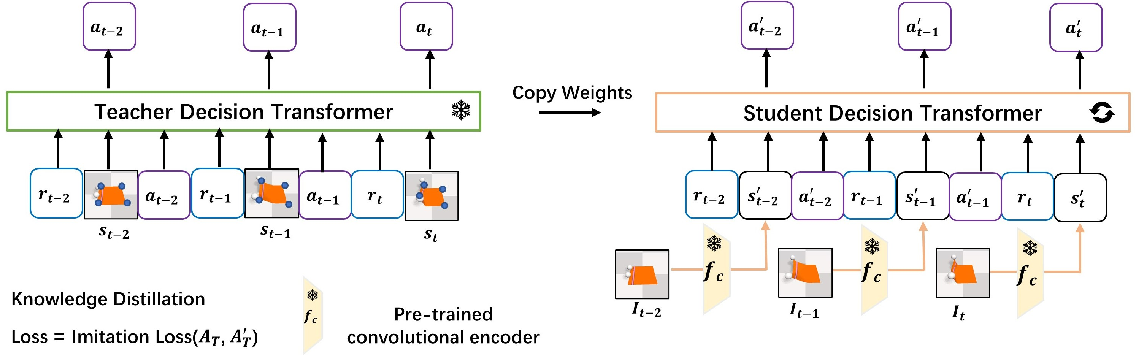
Figure 4 from TraKDis: A Transformer-Based Knowledge Distillation ...
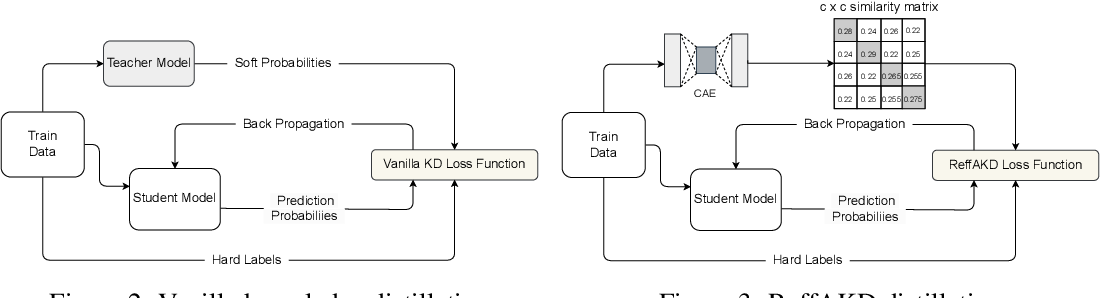
Figure 2 from ReffAKD: Resource-efficient Autoencoder-based Knowledge ...
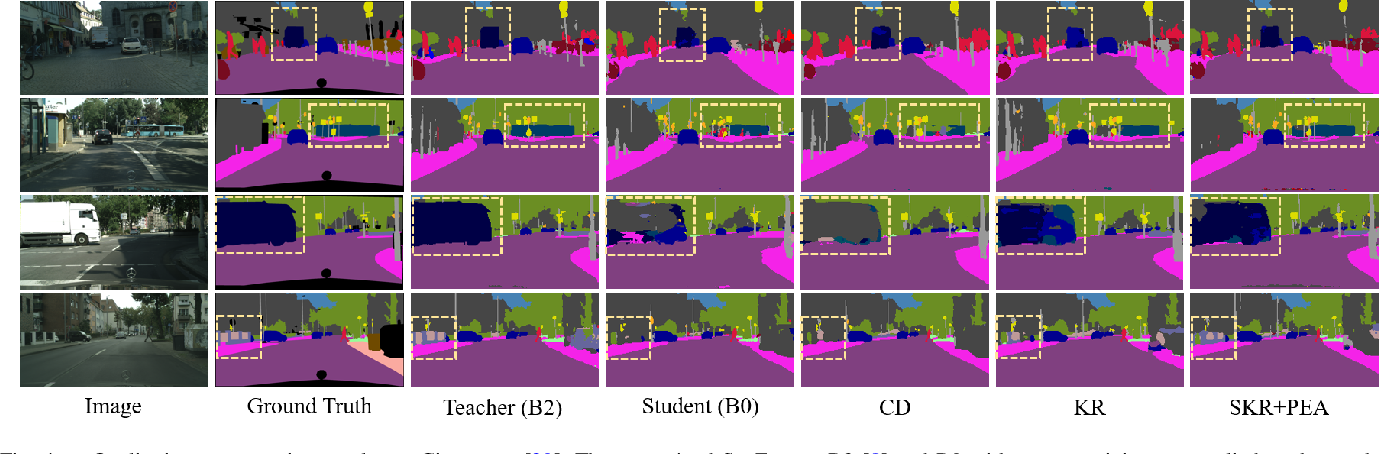
Transformer-based Knowledge Distillation for Efficient Semantic ...

(PDF) Pruning‐guided feature distillation for an efficient transformer ...
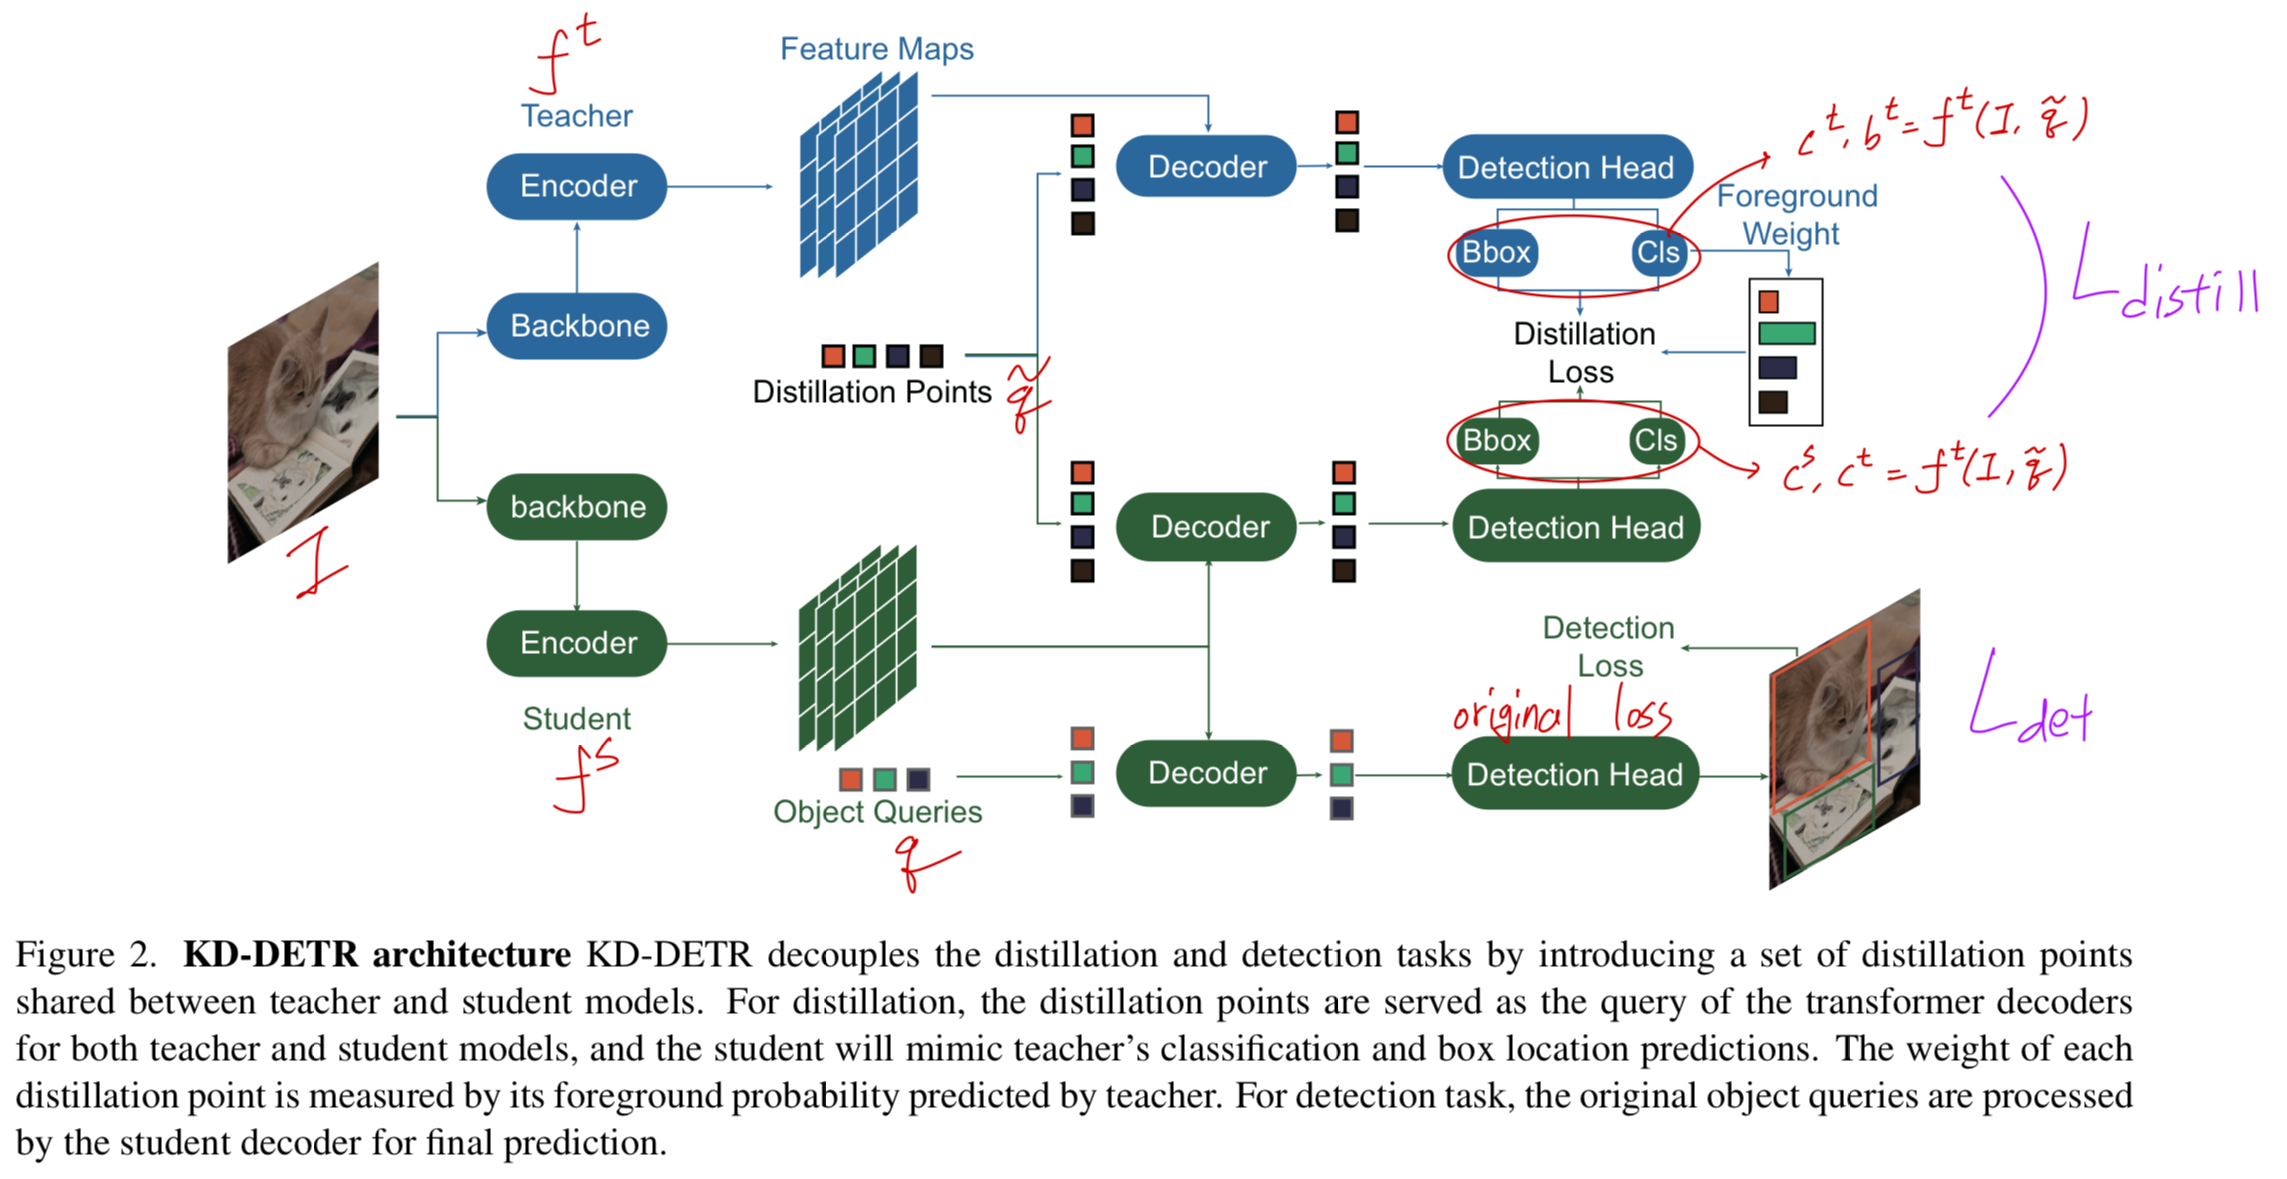
KD-DETR: Knowledge Distillation for Detection Transformer with ...
Advertisement Space (336x280)
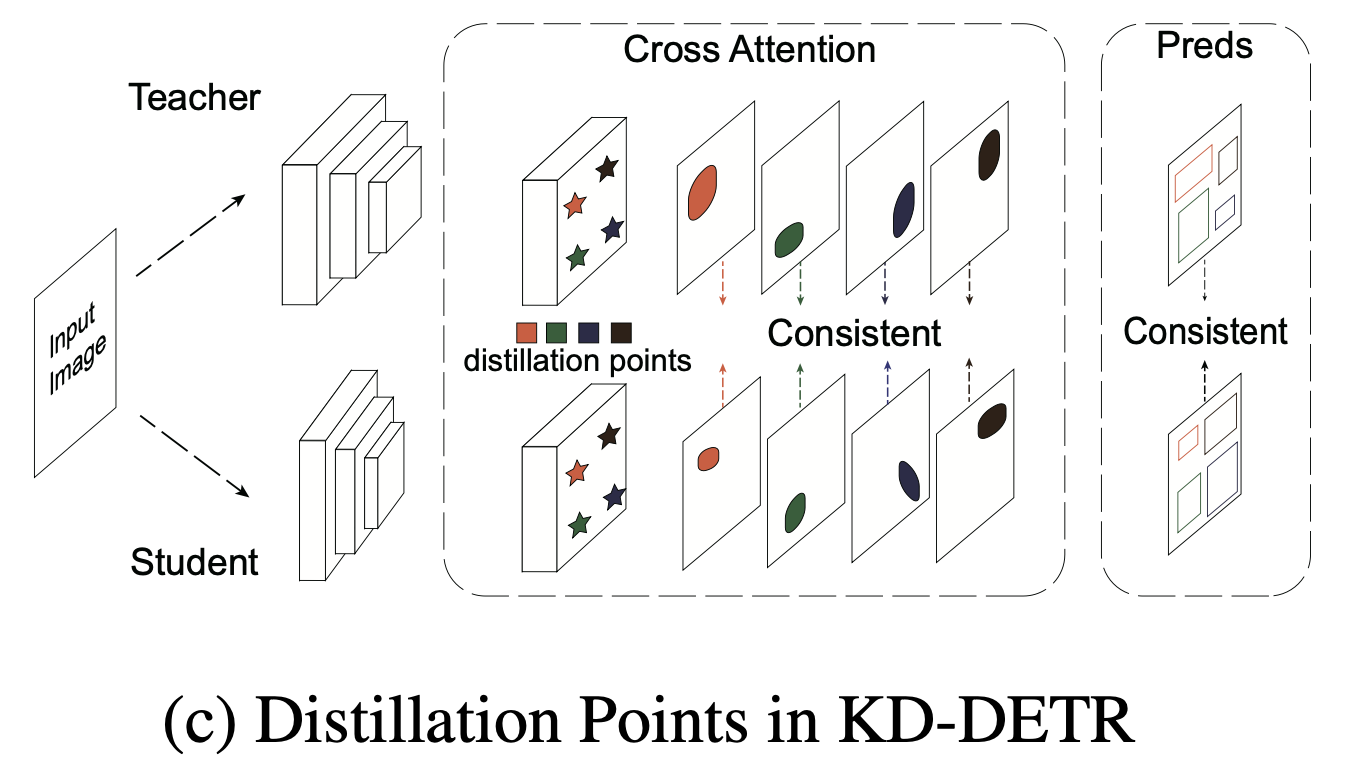
KD-DETR: Knowledge Distillation for Detection Transformer with ...

Knowledge Distillation for Efficient Transformer-Based Reinforcement ...

Table 1 from Supervised Masked Knowledge Distillation for Few-Shot ...
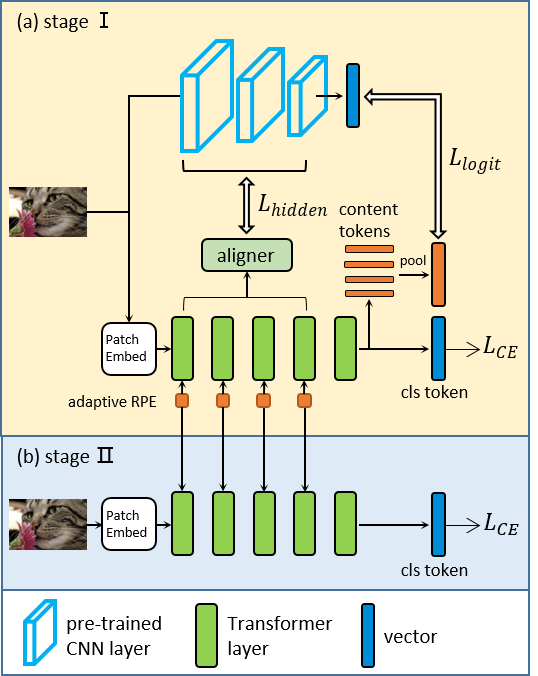
[2204.12997] DearKD: Data-Efficient Early Knowledge Distillation for ...

Pruning‐guided feature distillation for an efficient transformer‐based ...

Pruning‐guided feature distillation for an efficient transformer‐based ...