
Figure 3 From Lip Feature Fusion In Speech Synthesis System Driven By

Figure 3 from Lip feature fusion in speech synthesis system driven by ...

Figure 1 from Lip feature fusion in speech synthesis system driven by ...

Figure 1 from Using viseme based acoustic models for speech driven lip ...
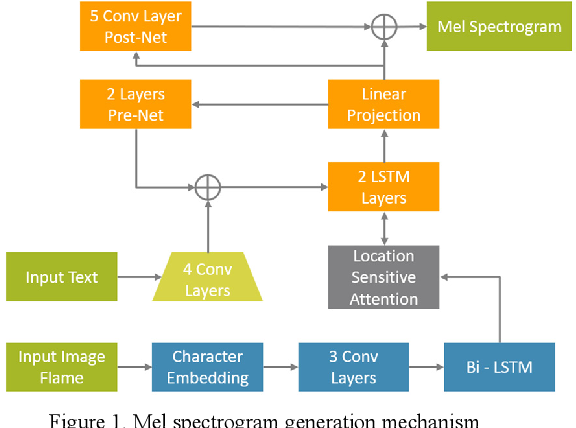
Figure 1 from Synthesis of Speech Reflecting Features from Lip Images ...

Figure 1 from Lip-to-Speech Synthesis in the Wild with Multi-Task ...
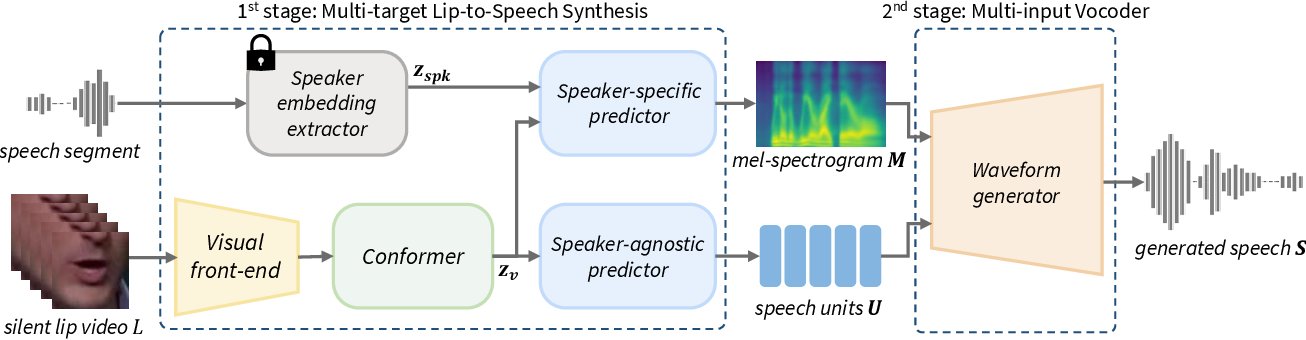
Figure 1 from Intelligible Lip-to-Speech Synthesis with Speech Units ...

Figure 2 from Data-Driven Speech Animation Synthesis Focusing on ...

Figure 1 from Data-Driven Speech Animation Synthesis Focusing on ...

(PDF) Using viseme based acoustic models for speech driven lip synthesis
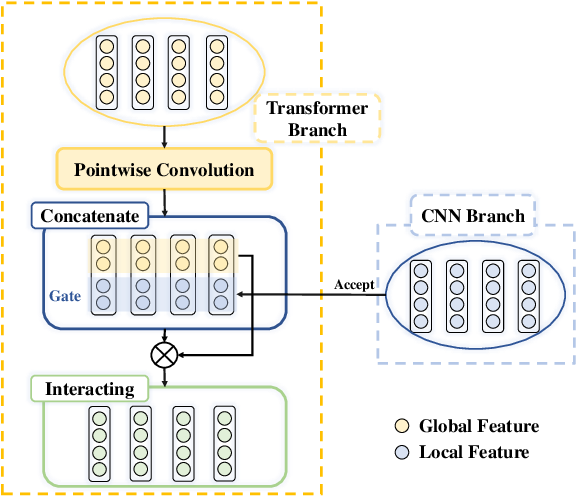
Figure 3 from InterFormer: Interactive Local and Global Features Fusion ...
Advertisement Space (300x250)

Figure 1 from MFFCN: Multi-layer Feature Fusion Convolution Network for ...

The recognition results of feature and decision fusion in our system ...

Figure 3 from Evaluation of a computer aided 3D lip sync instructional ...
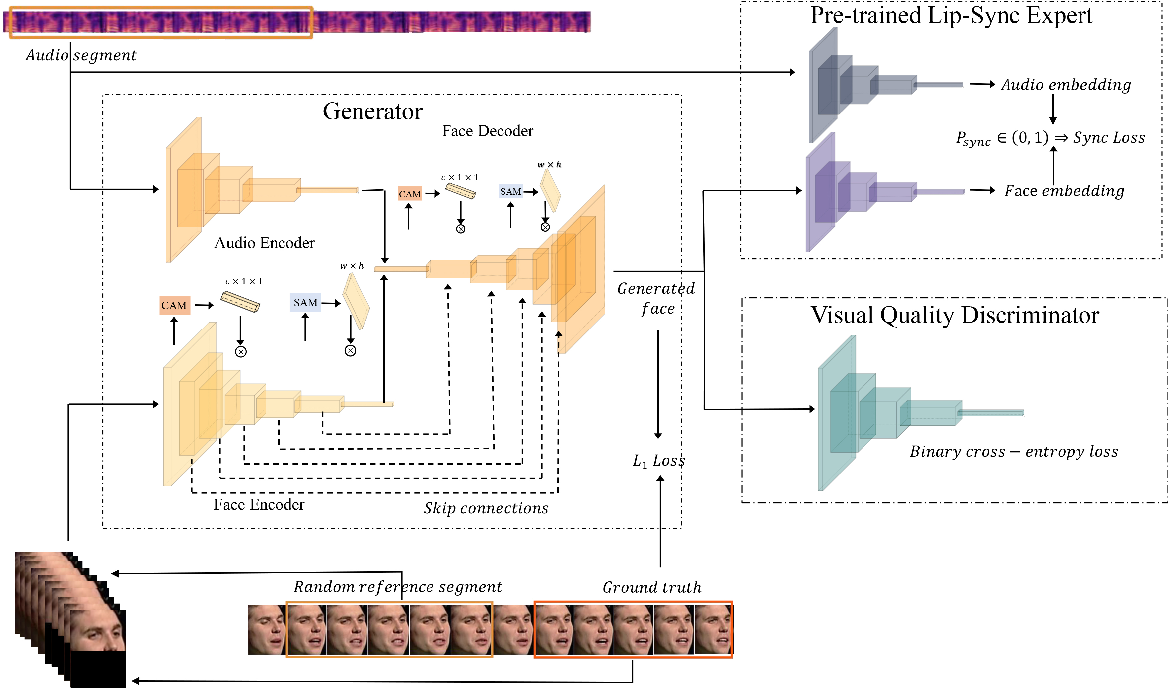
Figure 1 from Attention-Based Lip Audio-Visual Synthesis for Talking ...

Figure 1 from Static and dynamic lip feature analysis for speaker ...
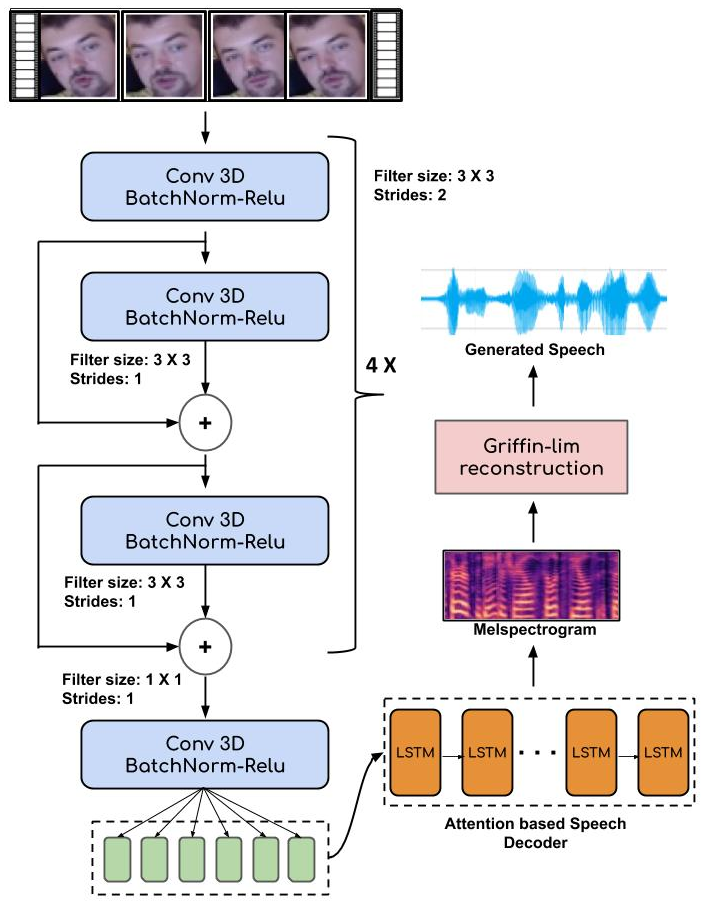
Learning Individual Speaking Styles for Accurate Lip to Speech Synthesis

A Facial Feature and Lip Movement Enhanced Audio-Visual Speech ...

Lip synchronization schema in our agent’s speech synthesis. | Download ...
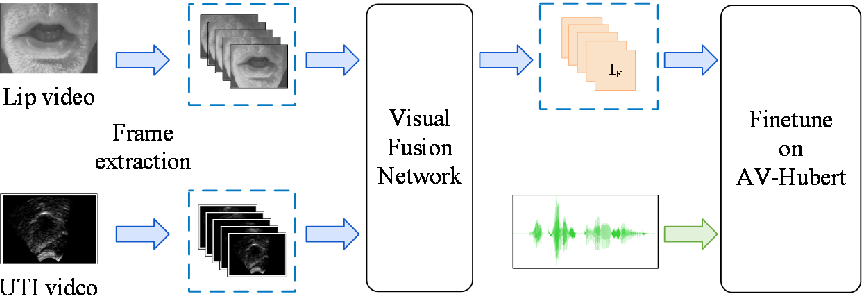
Figure 1 from Multi-stage Multi-modalities Fusion of Lip, Tongue and ...

The feature fusion for a multimodal speech recognition application ...
Advertisement Space (336x280)
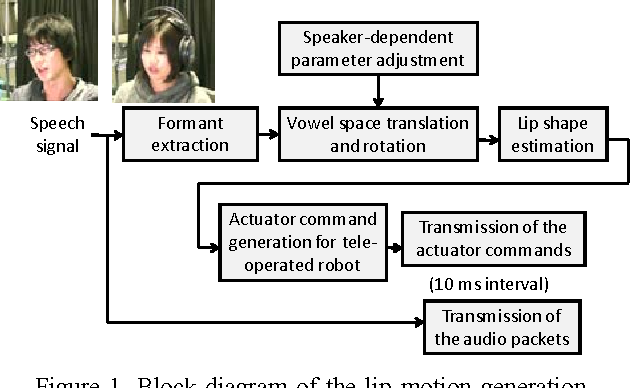
Figure 1 from Speech-driven lip motion generation for tele-operated ...

The feature fusion for a multimodal speech recognition application ...
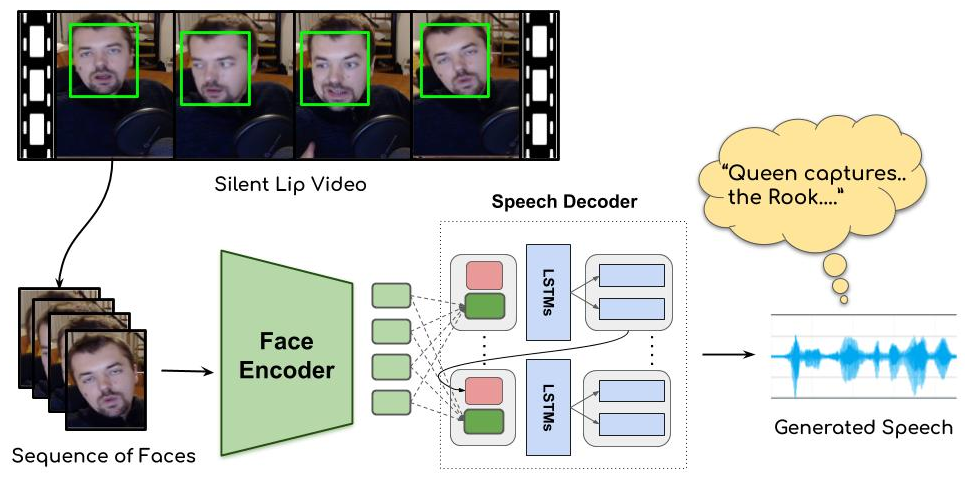
Learning Individual Speaking Styles for Accurate Lip to Speech Synthesis

Speech driven face animation system framework | Download Scientific Diagram
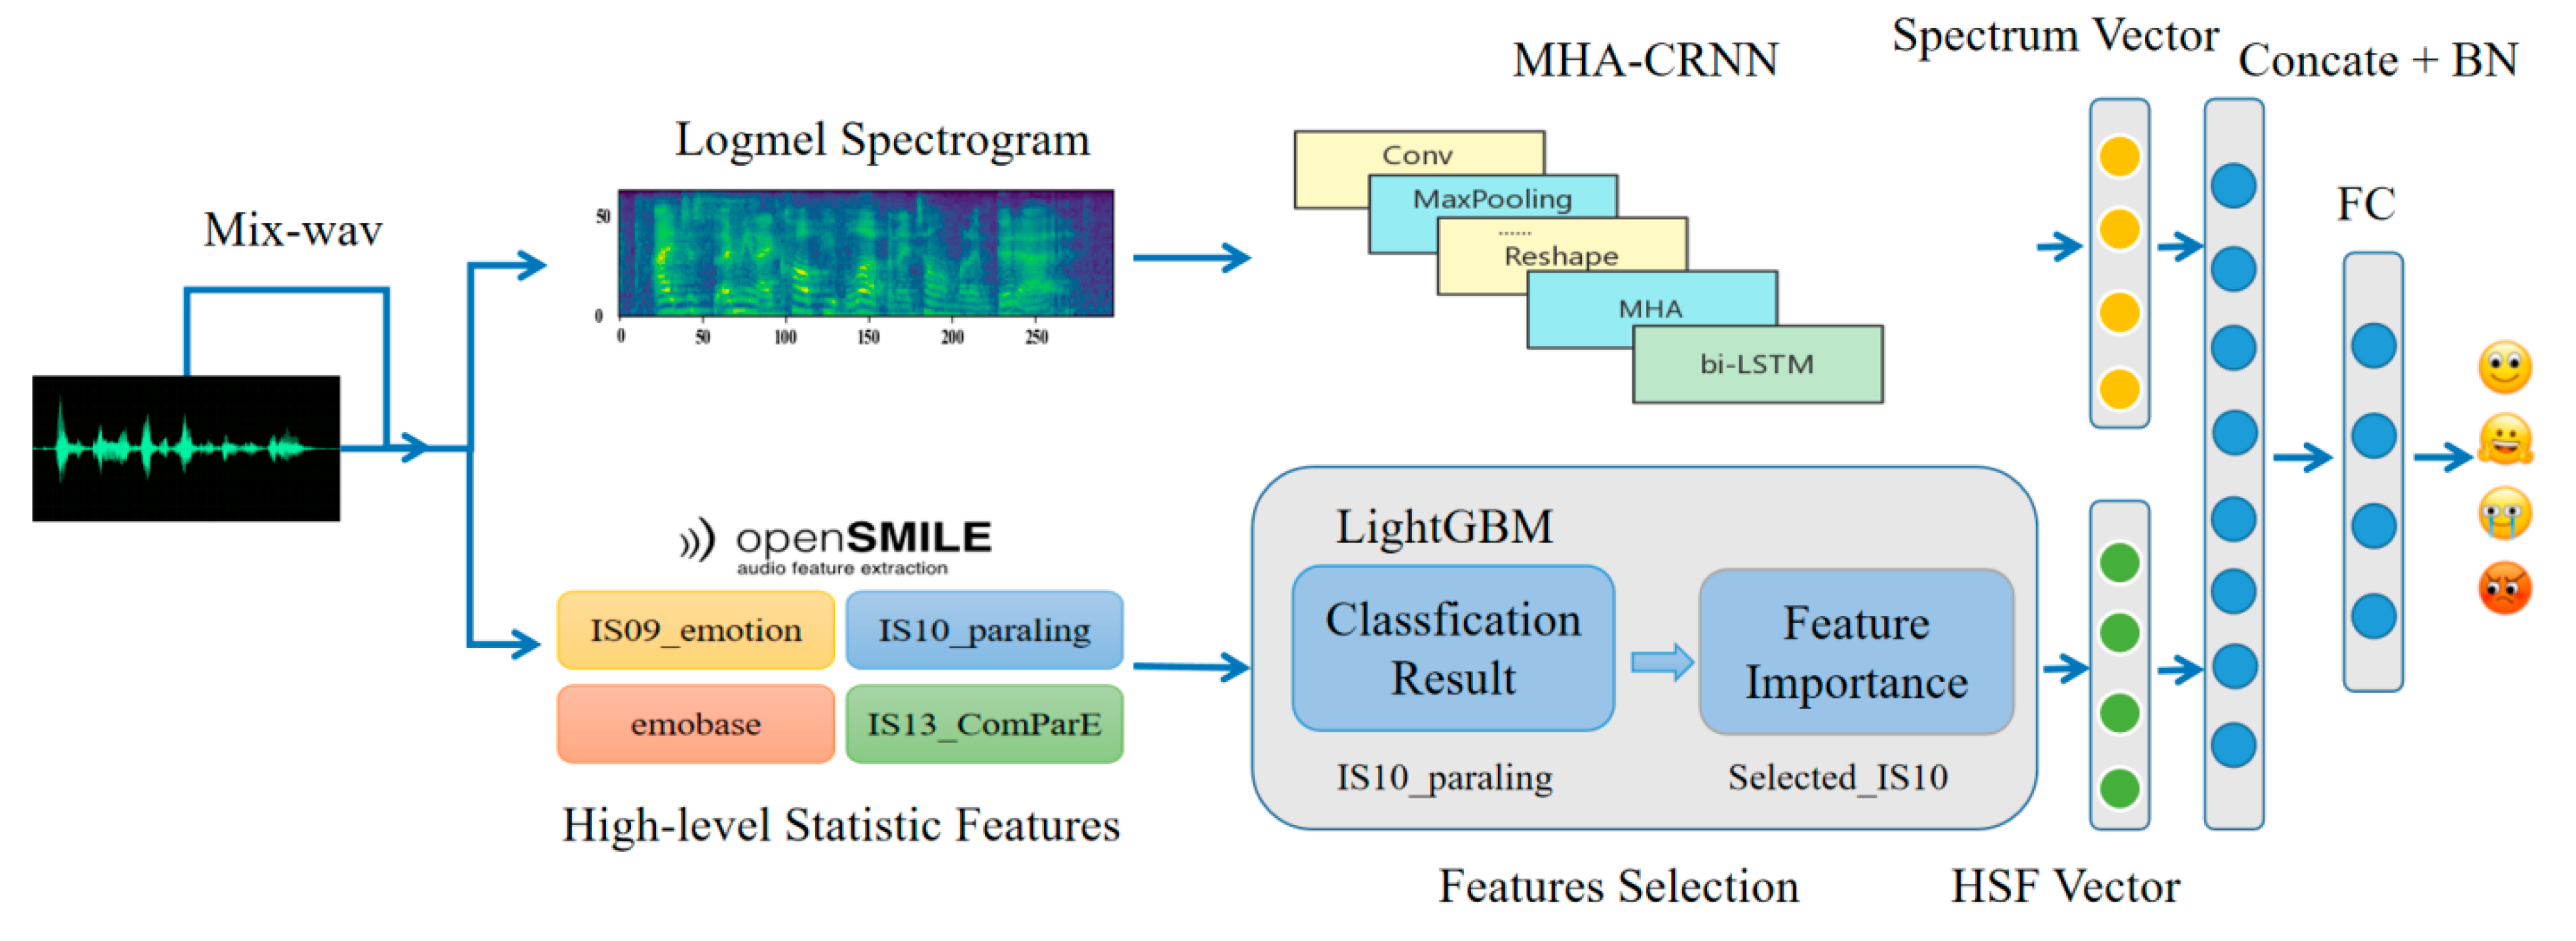
A Feature Fusion Model with Data Augmentation for Speech Emotion ...

Feature Fusion in Medical AI for Enhanced Diagnosis and Decision-Making ...

(PDF) Optimizing feature fusion for improved zero-shot adaptation in ...

Figure 1 from Lip features automatic extraction | Semantic Scholar

Figure 2 from FaceDiffuser: Speech-Driven 3D Facial Animation Synthesis ...

Development and Evaluation of Speech Synthesis System Based on Deep ...
Advertisement Space (336x280)

Improving Speech Recognition Performance in Noisy Environments by ...
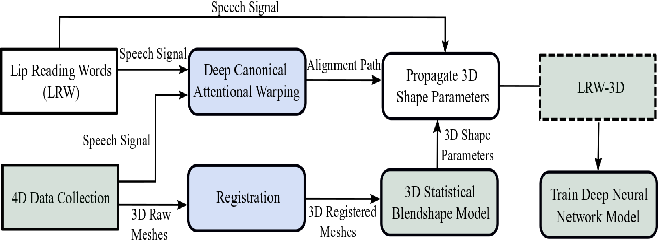
Figure 2 from Synthesising 3D Facial Motion from “In-the-Wild” Speech ...

A Facial Feature and Lip Movement Enhanced Audio-Visual Speech ...

Automatic Lip Reading System Based on a Fusion Lightweight Neural ...

Figure 1 from Efficient Speech Signal Accent Recognition Algorithm ...

Block diagram of the feature fusion for AVSR. The algorithm generates ...