
Figure 3 From Task Alignment Interaction And Cross Scale Guided
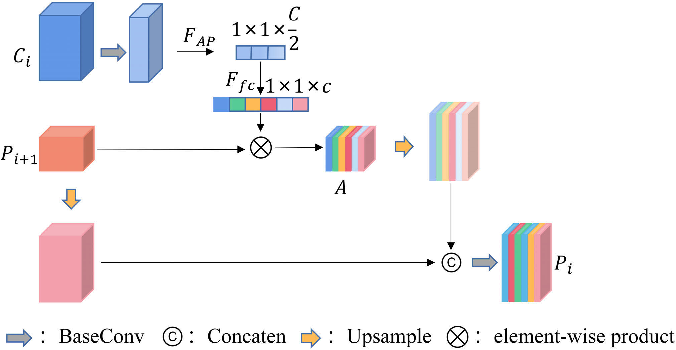
Figure 3 from Task Alignment Interaction and Cross-Scale Guided ...

Figure 1 from Task Alignment Interaction and Cross-Scale Guided ...
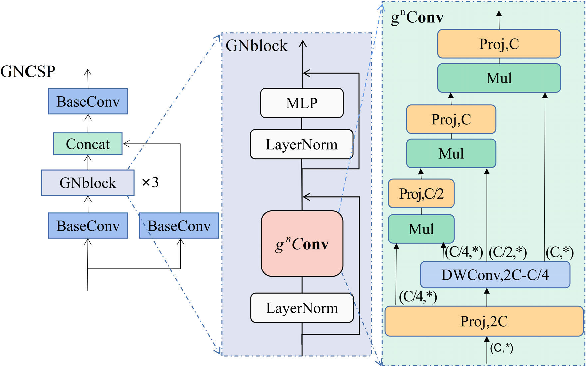
Figure 4 from Task Alignment Interaction and Cross-Scale Guided ...

Figure 1 from Task Alignment Interaction and Cross-Scale Guided ...

Figure 3 from Prototype-guided Cross-modal Completion and Alignment for ...
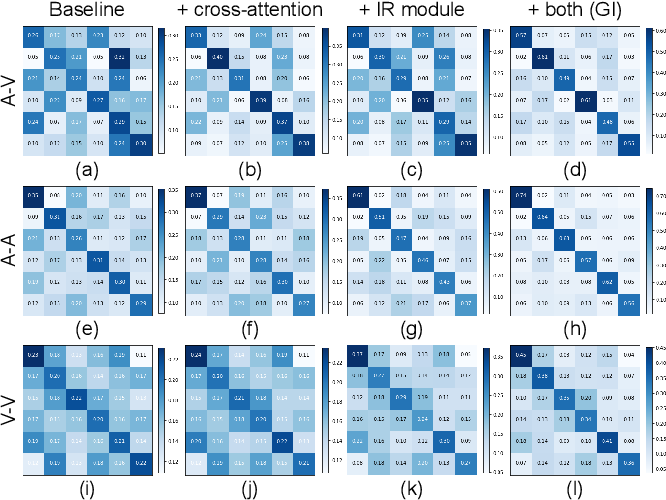
Figure 1 from Cross-Modal Global Interaction and Local Alignment for ...
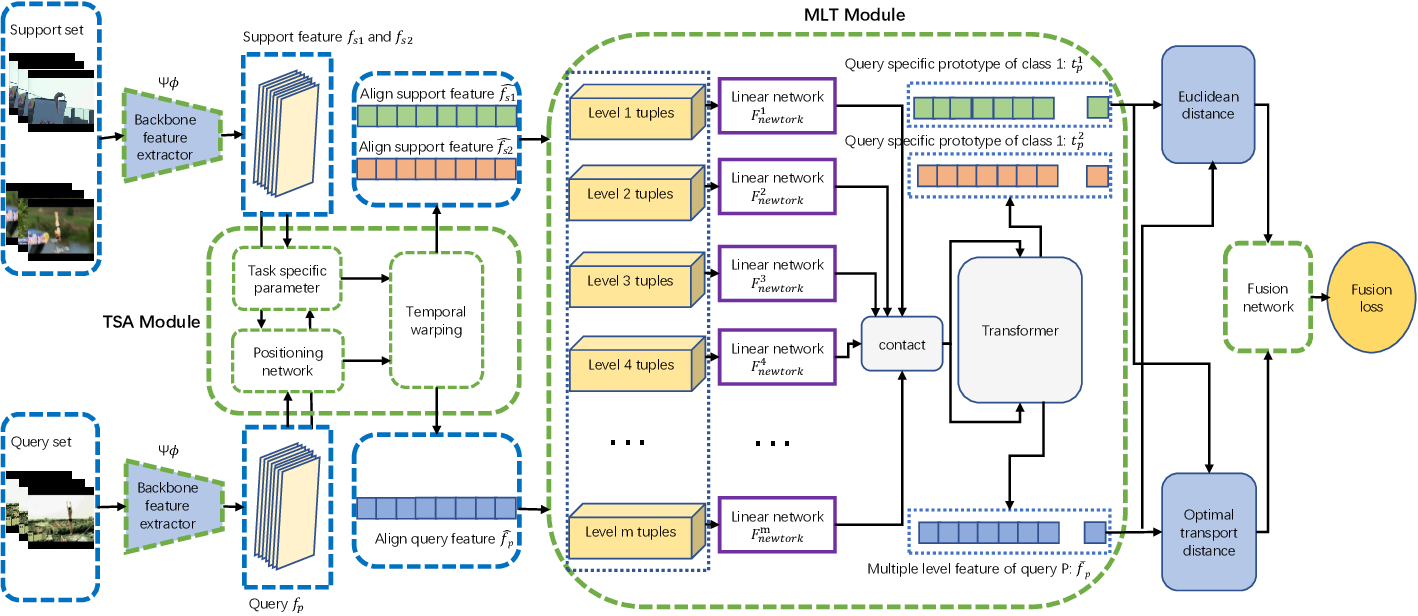
Figure 3 from Task-Specific Alignment and Multiple Level Transformer ...
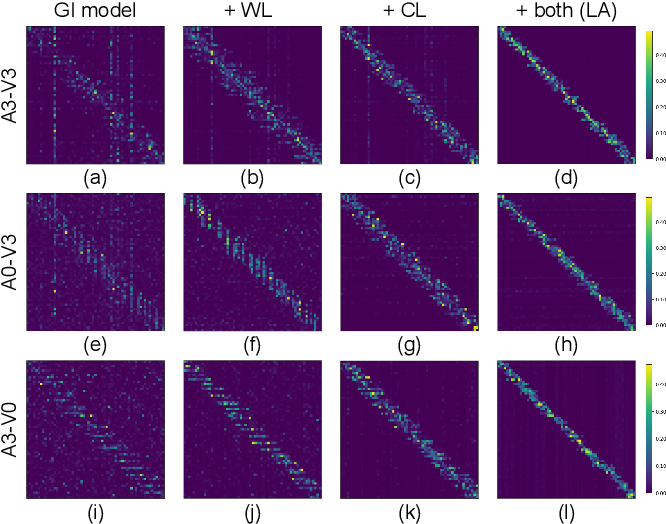
Figure 1 from Cross-Modal Global Interaction and Local Alignment for ...

Figure 1 from Cross-Modal Global Interaction and Local Alignment for ...

Figure 1 from CrossInteraction: Multi-Modal Interaction and Alignment ...
Advertisement Space (300x250)

Figure 1 from Multilevel Semantic Interaction Alignment for Video–Text ...
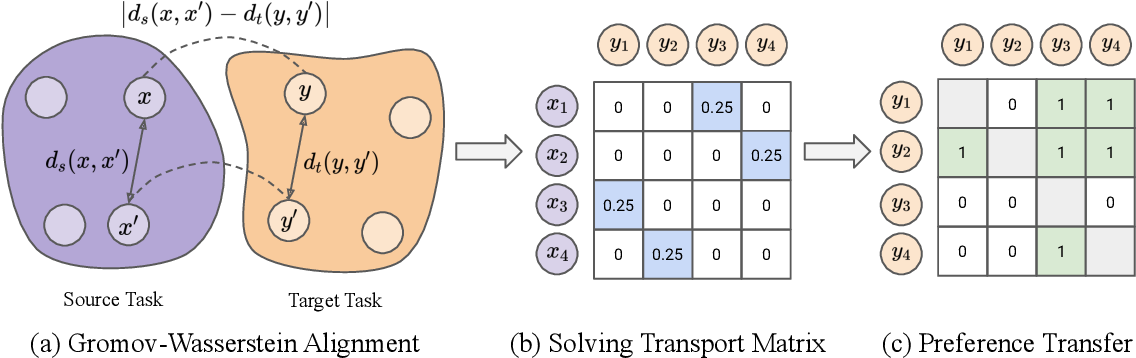
Figure 2 from PEARL: Zero-shot Cross-task Preference Alignment and ...
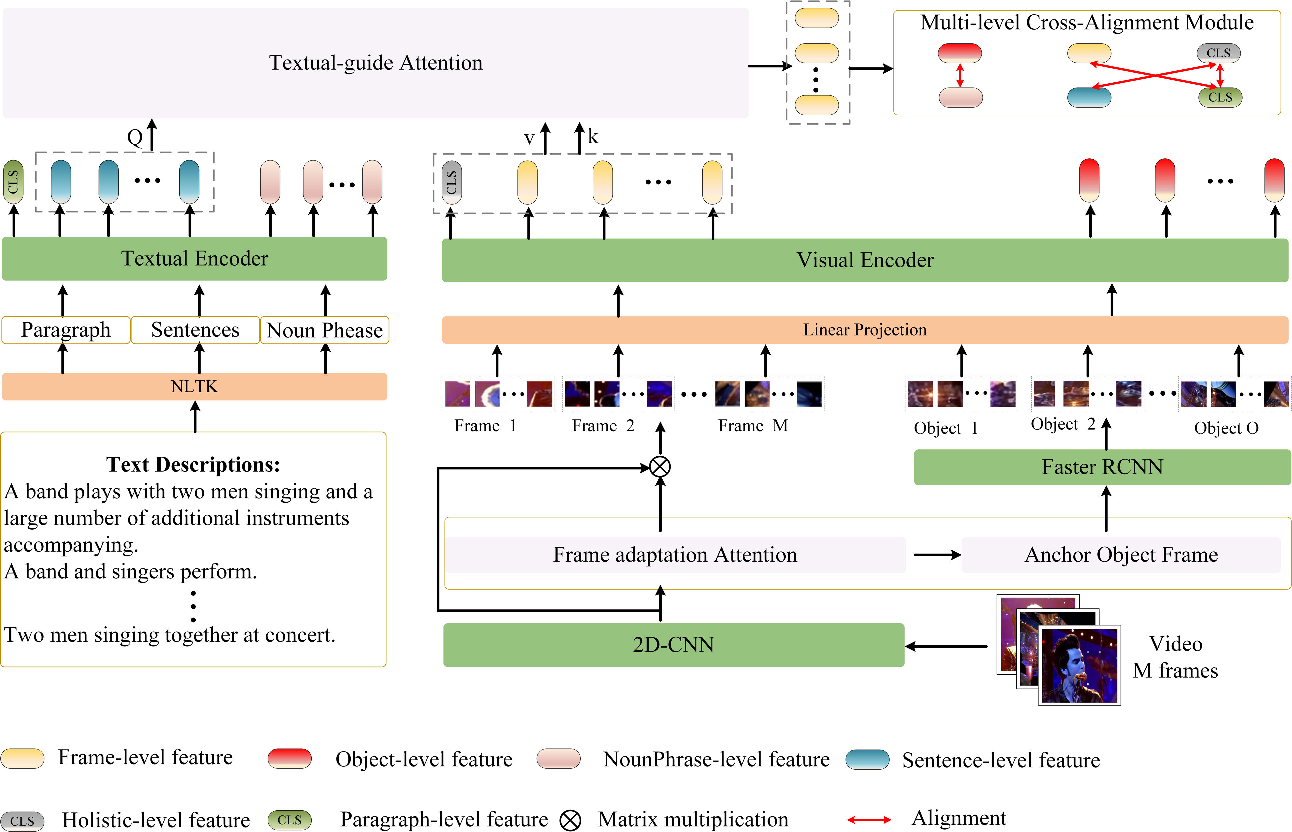
Figure 4 from Multilevel Semantic Interaction Alignment for Video–Text ...

Figure 1 from Prototype-guided Cross-modal Completion and Alignment for ...

Figure 3 from Multi-Task Paired Masking With Alignment Modeling for ...
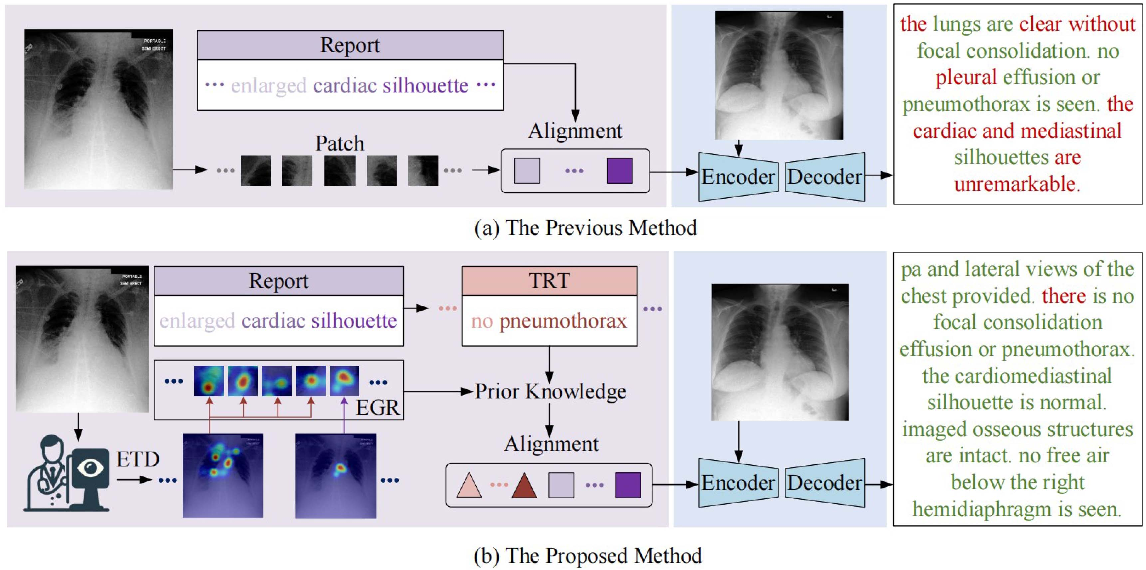
Figure 1 from Eye Gaze Guided Cross-Modal Alignment Network for ...

Figure 2 from VideoLights: Feature Refinement and Cross-Task Alignment ...

Figure 2 from Eye Gaze Guided Cross-Modal Alignment Network for ...

Figure 1 from PEARL: Zero-shot Cross-task Preference Alignment and ...

Figure 3 from From Passive Alignment to Active Participation: Robots ...
Advertisement Space (336x280)
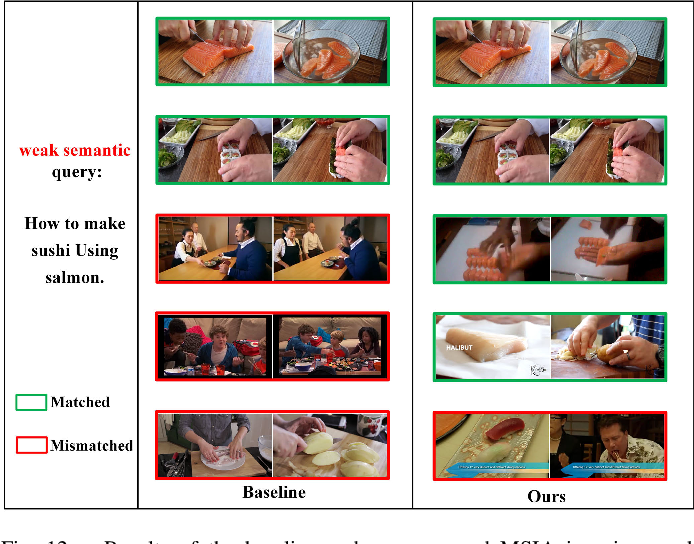
Figure 12 from Multilevel Semantic Interaction Alignment for Video–Text ...

Figure 1 from Cross-Modal Translation and Alignment for Survival ...

Figure 2 from VideoLights: Feature Refinement and Cross-Task Alignment ...
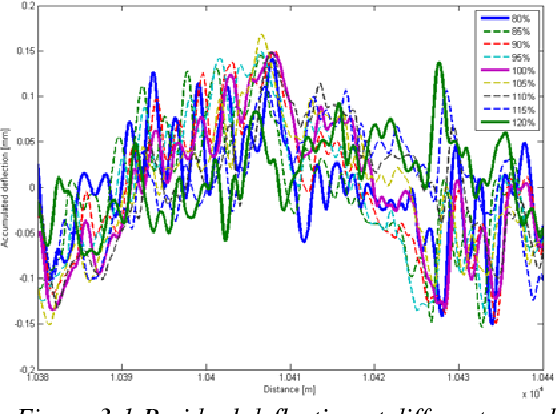
Figure 3-1 from THE INTERACTION BETWEEN RAILWAY VEHICLE DYNAMICS AND ...

Task by fixation cross length interaction for secondary ANOVA ...
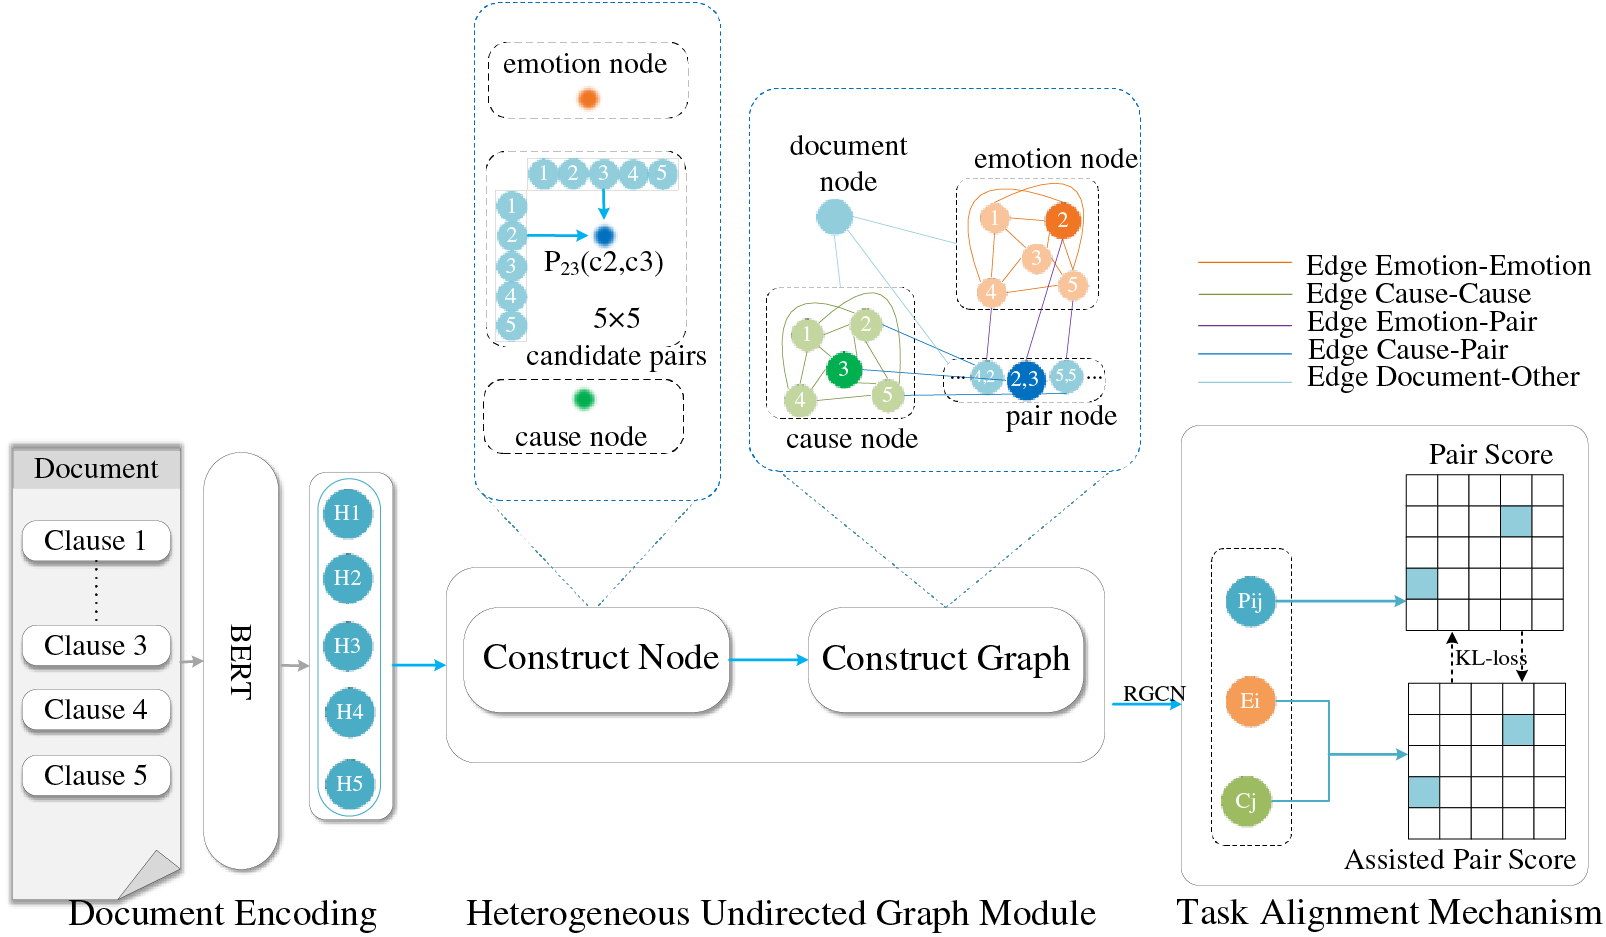
CMC | Free Full-Text | Joint Feature Encoding and Task Alignment ...

Figure 1 from Improving Cross-modal Alignment for Text-Guided Image ...
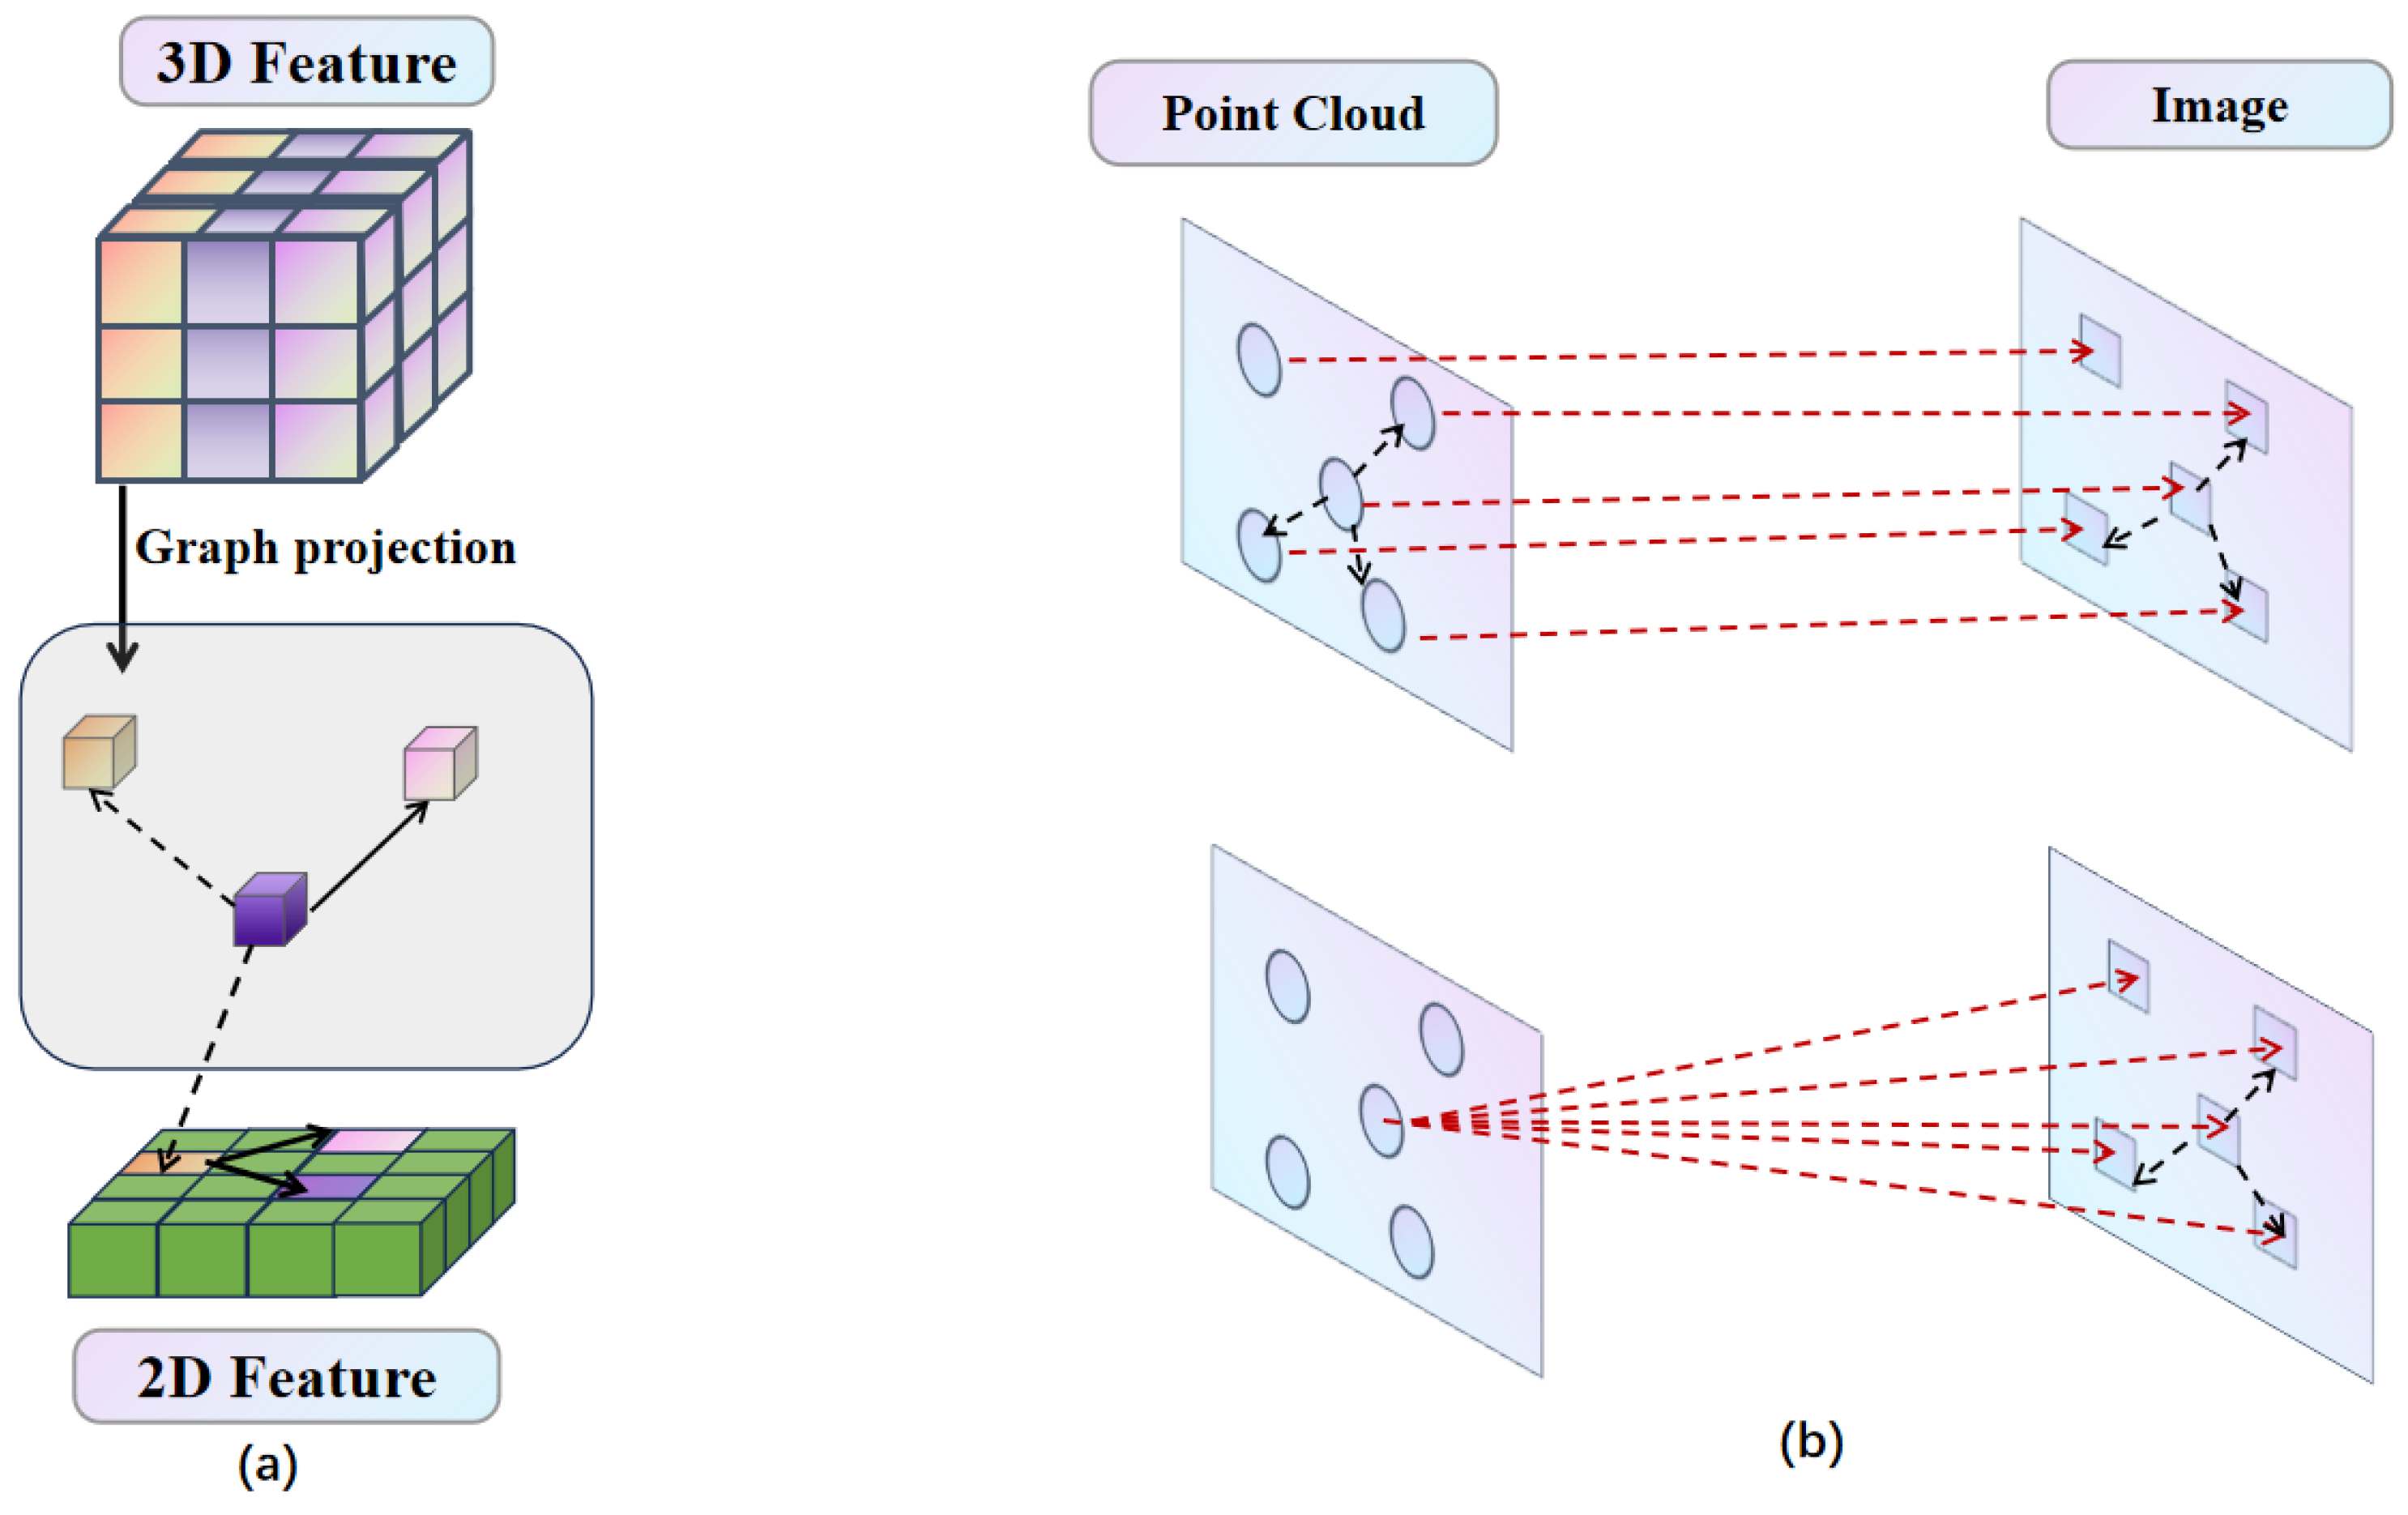
CrossInteraction: Multi-Modal Interaction and Alignment Strategy for 3D ...
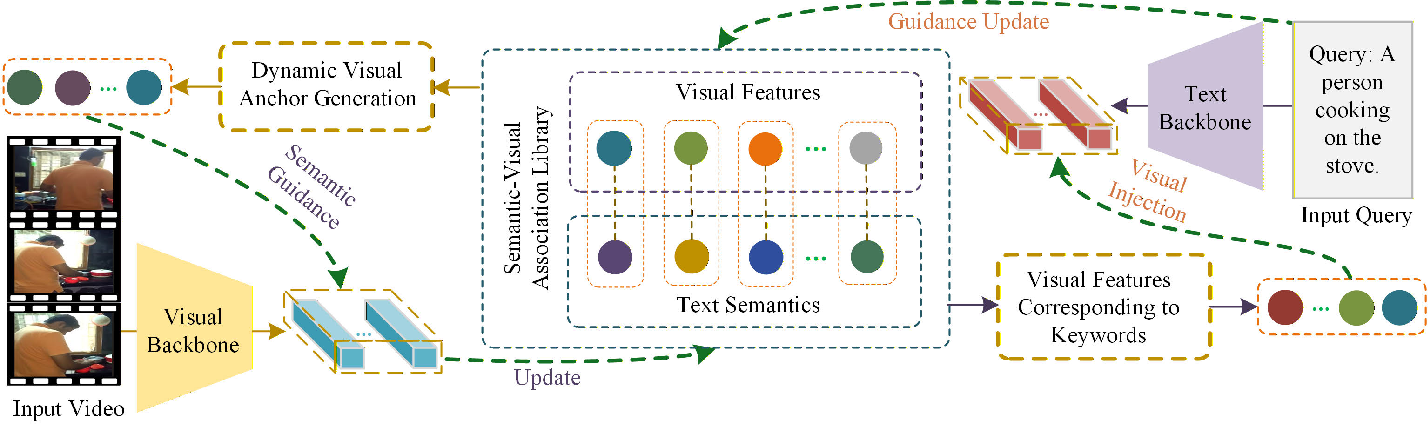
Figure 1 from Bidirectional Cross-Modal Collaborative Alignment via ...
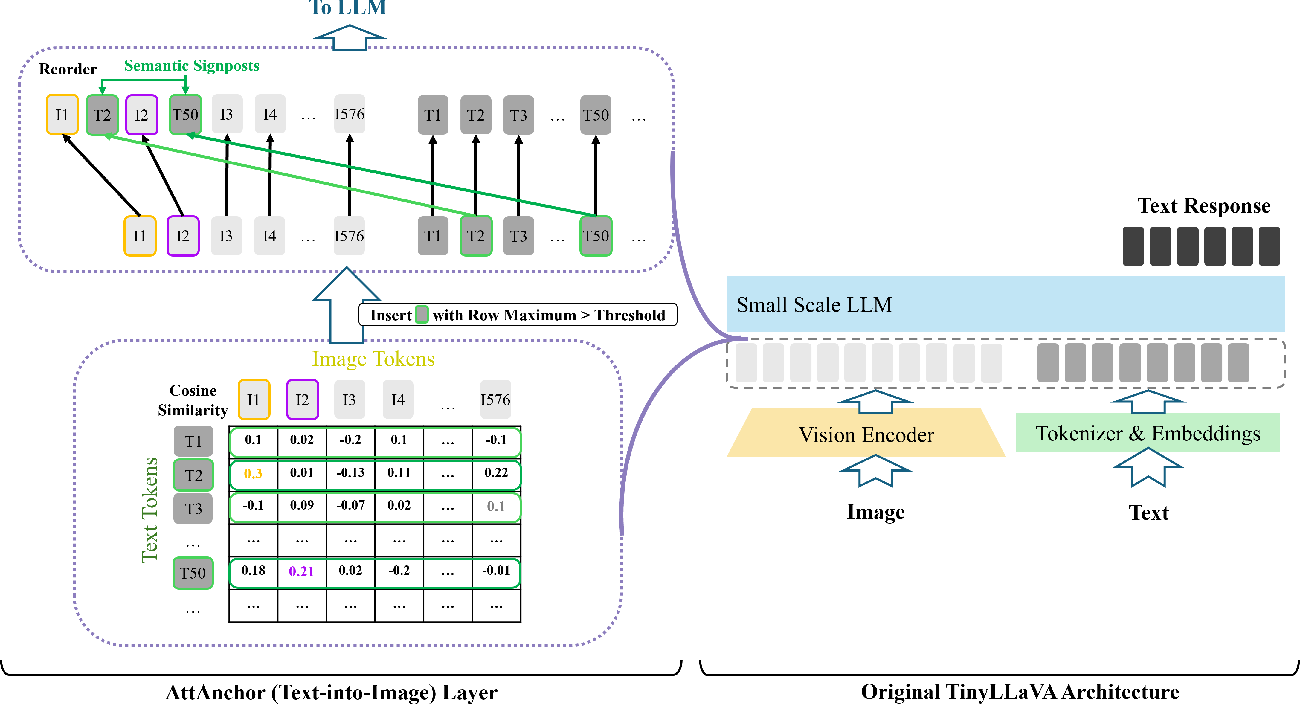
Figure 1 from AttAnchor: Guiding Cross-Modal Token Alignment in VLMs ...
Advertisement Space (336x280)

Table 2 from Cross-modal Generation and Alignment via Attribute-guided ...
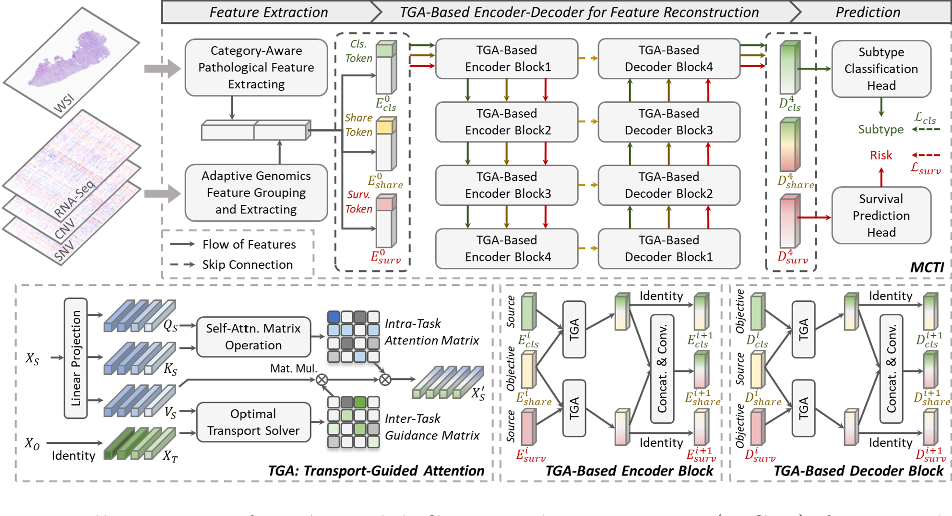
Figure 1 from Multimodal Cross-Task Interaction for Survival Analysis ...

Figure 1 from Pose-Guided Modality-Invariant Feature Alignment for ...

(PDF) Cross Task Modality Alignment Network for Sketch Face Recognition
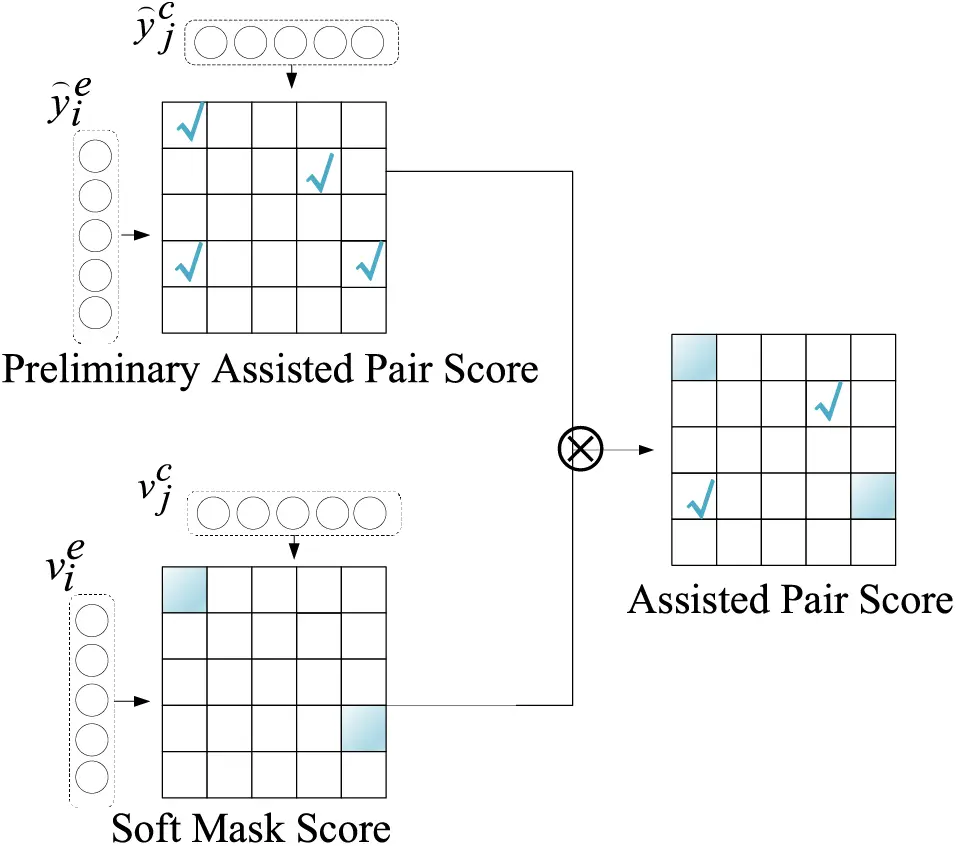
CMC | Free Full-Text | Joint Feature Encoding and Task Alignment ...

Figure 2 from Pose-Guided Modality-Invariant Feature Alignment for ...