
Figure 3 From Vision Transformer With Deformable Attention Semantic
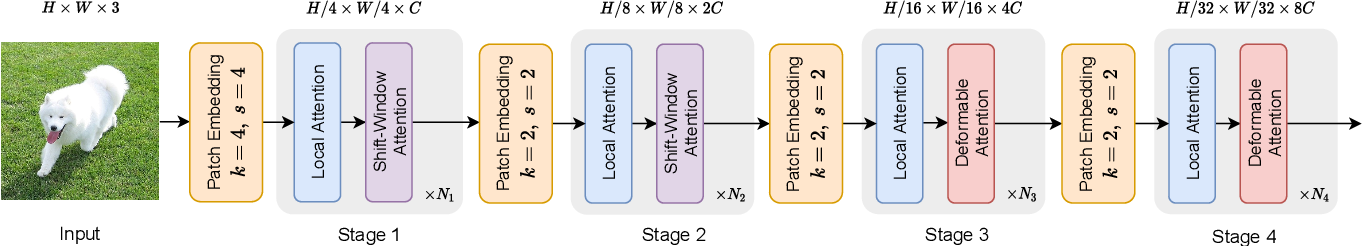
Figure 3 from Vision Transformer with Deformable Attention | Semantic ...

Figure 3 from DeBiFormer: Vision Transformer with Deformable Agent Bi ...

[PDF] Vision Transformer with Deformable Attention | Semantic Scholar

[PDF] Vision Transformer with Deformable Attention | Semantic Scholar

[PDF] Vision Transformer with Deformable Attention | Semantic Scholar

[PDF] Vision Transformer with Deformable Attention | Semantic Scholar

Figure 2 from DeBiFormer: Vision Transformer with Deformable Agent Bi ...

Figure 3 from A Convolutional Vision Transformer for Semantic ...

Figure 3 from Reference-based Image Super-Resolution with Deformable ...
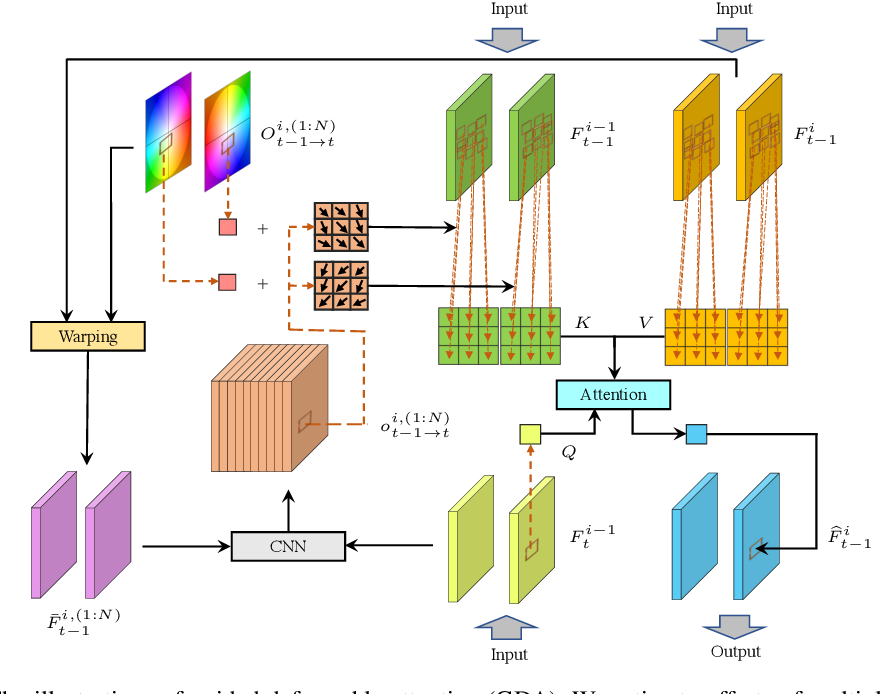
Figure 3 from Recurrent Video Restoration Transformer with Guided ...
Advertisement Space (300x250)
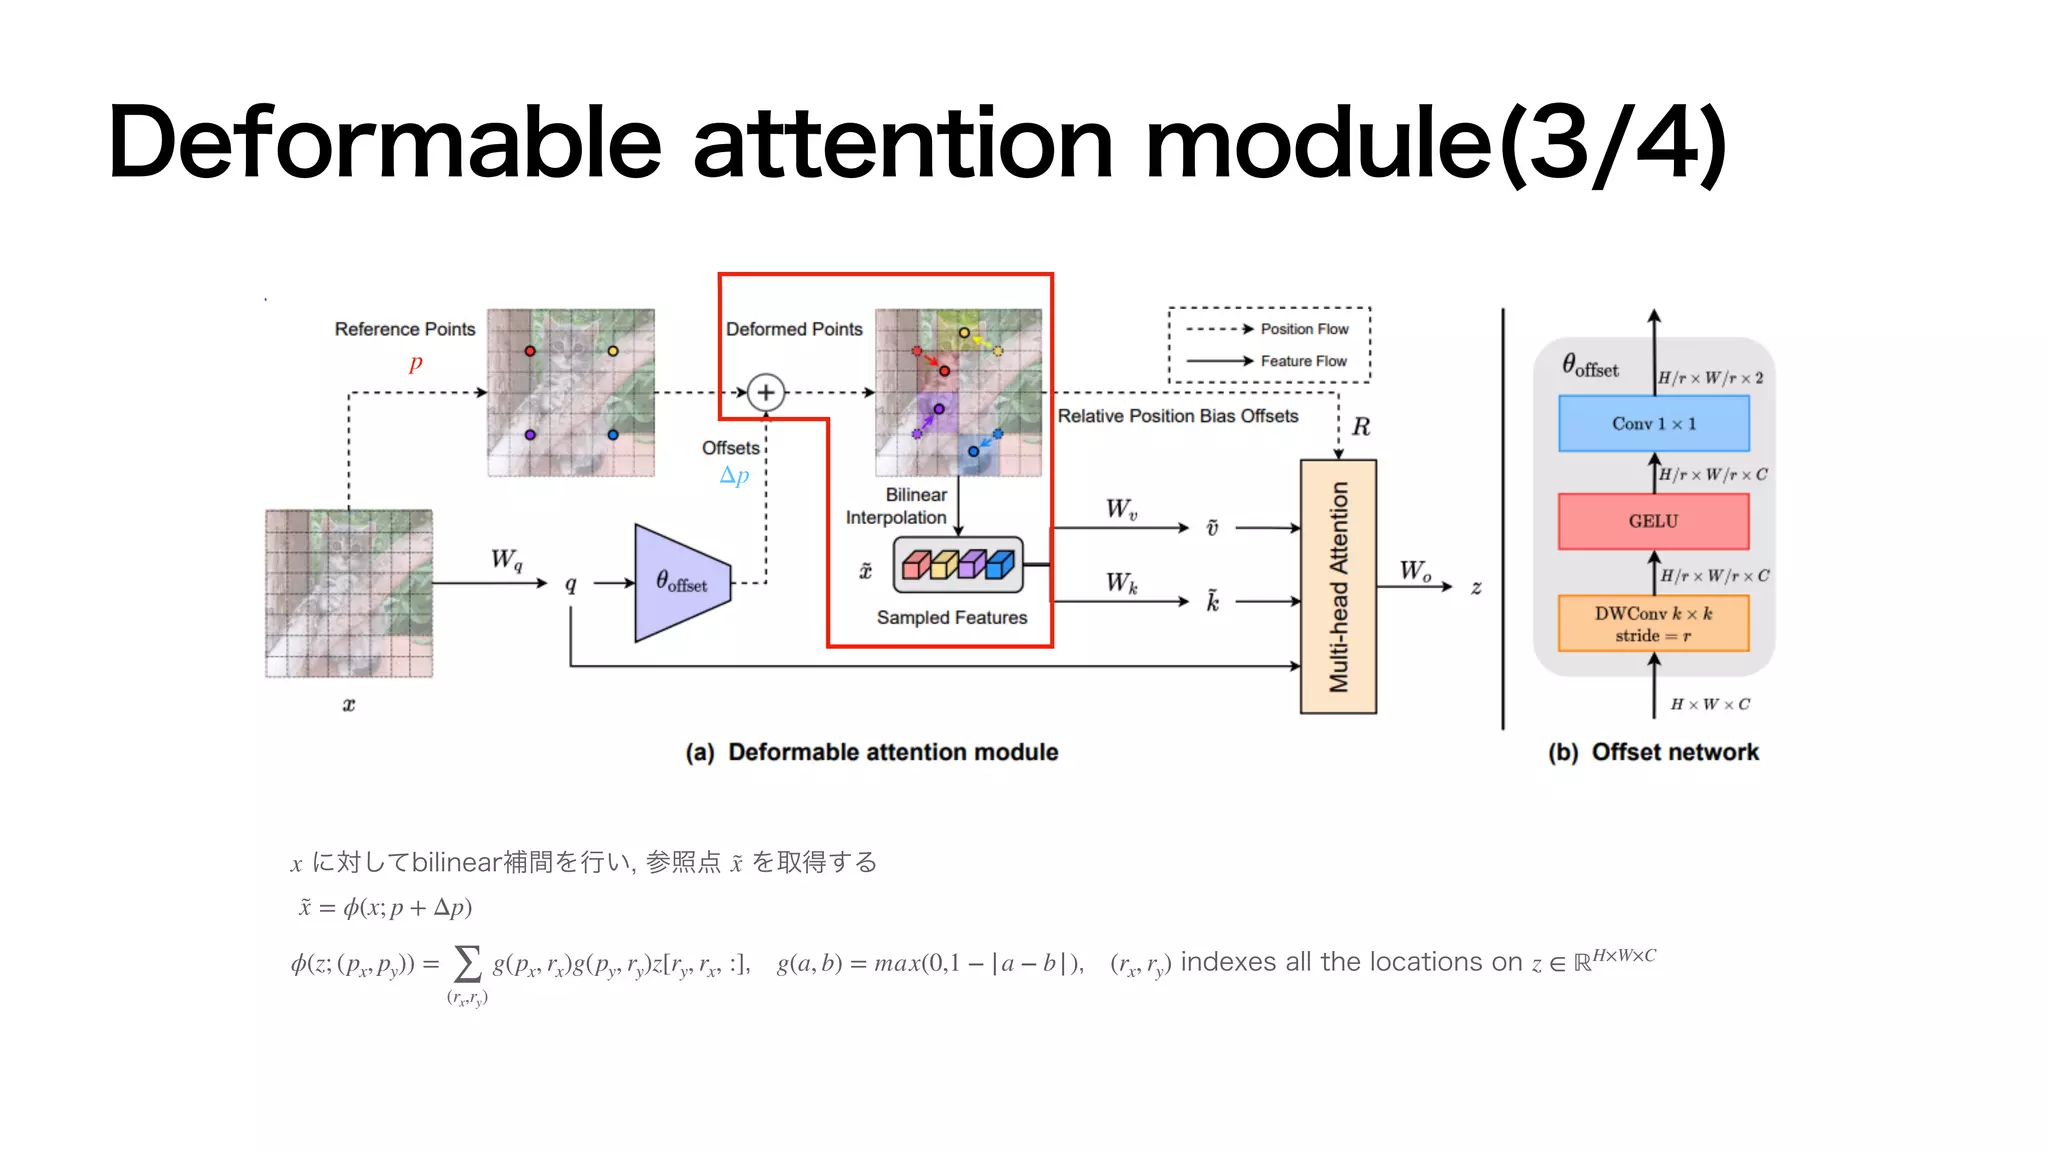
論文紹介 : Vision Transformer with Deformable Attention | PDF

Figure 3 from A Lightweight Convolution and Vision Transformer ...
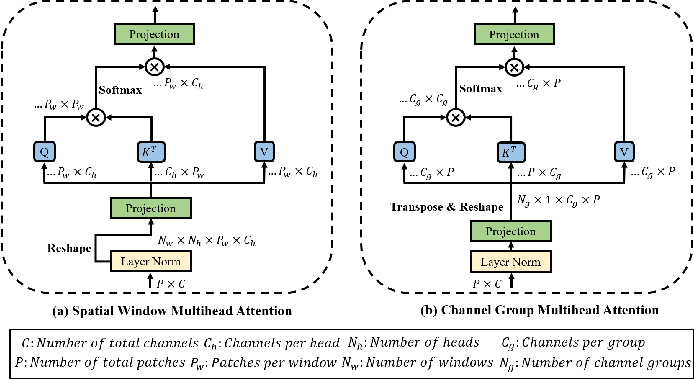
Figure 3 from Triple Attention Vision Transformers for Remote Sensing ...
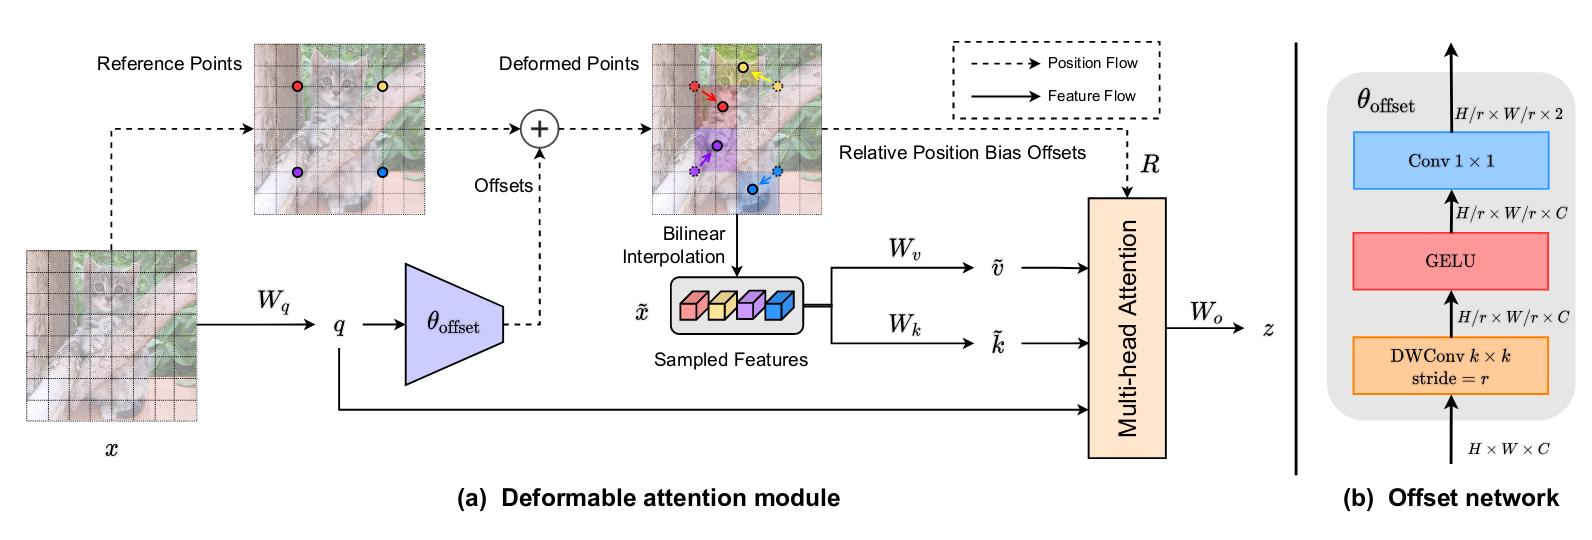
Vision Transformer with Deformable Attention | MYRIAD

Vision Transformer with Deformable Attention | Dayeon Yu

Vision Transformer with Deformable Attention | Dayeon Yu

(PDF) Vision Transformer with Deformable Attention

Vision Transformer with Deformable Attention | MYRIAD
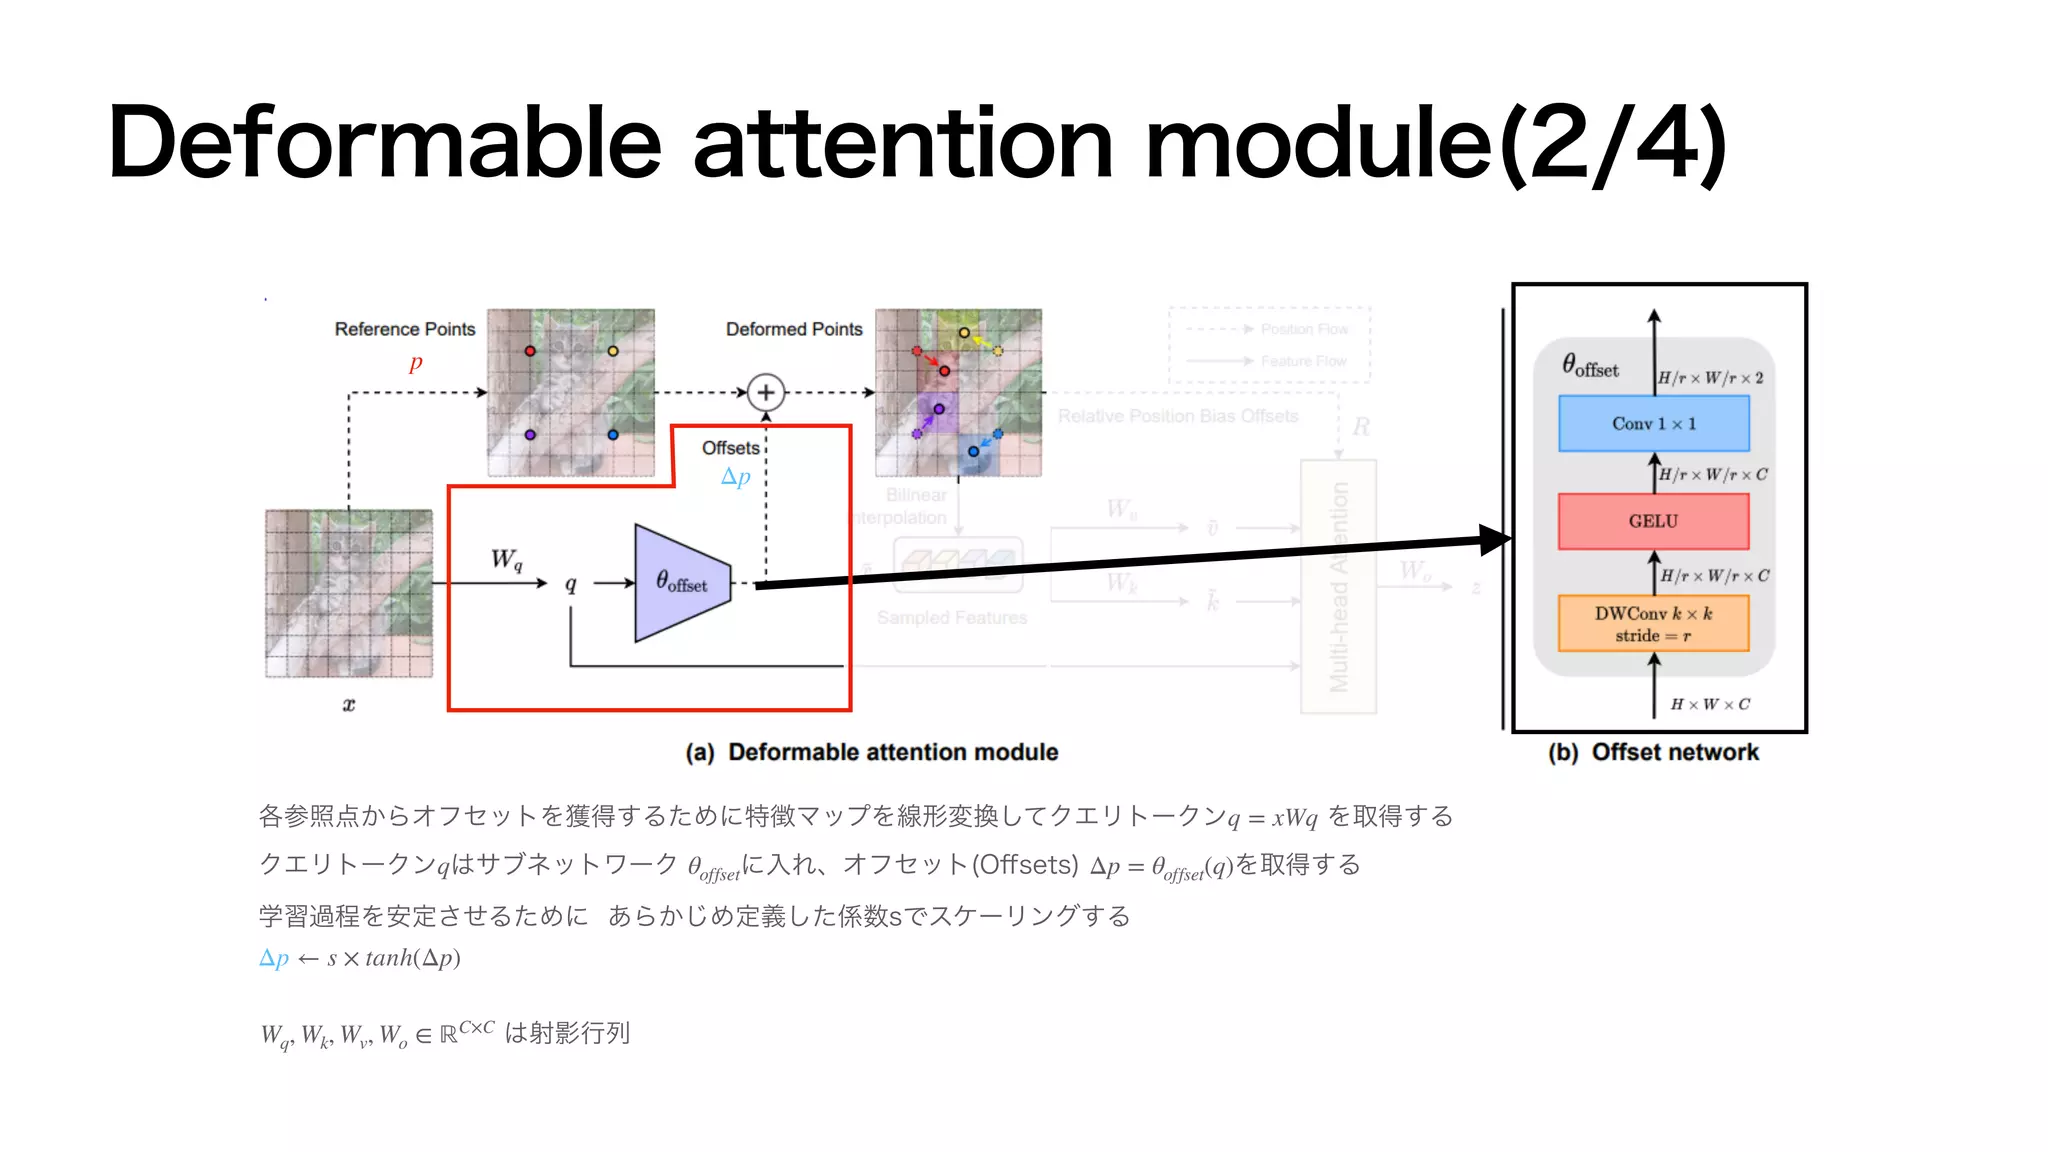
論文紹介 : Vision Transformer with Deformable Attention | PDF
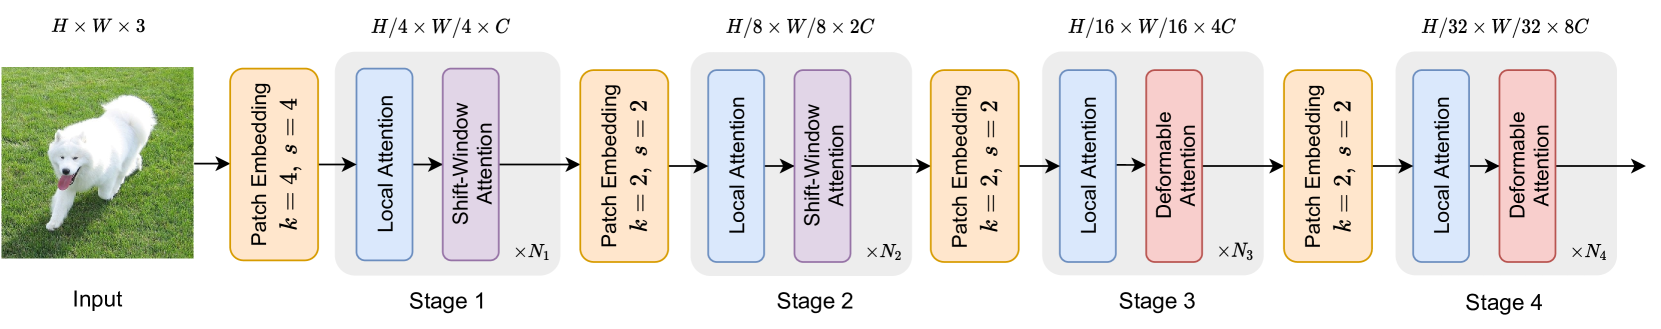
Vision Transformer with Deformable Attention — Vision Transformer의 모든 것
Advertisement Space (336x280)

Figure 1 from DAT++: Spatially Dynamic Vision Transformer with ...

Figure 3 from Deformable Mesh Transformer for 3D Human Mesh Recovery ...
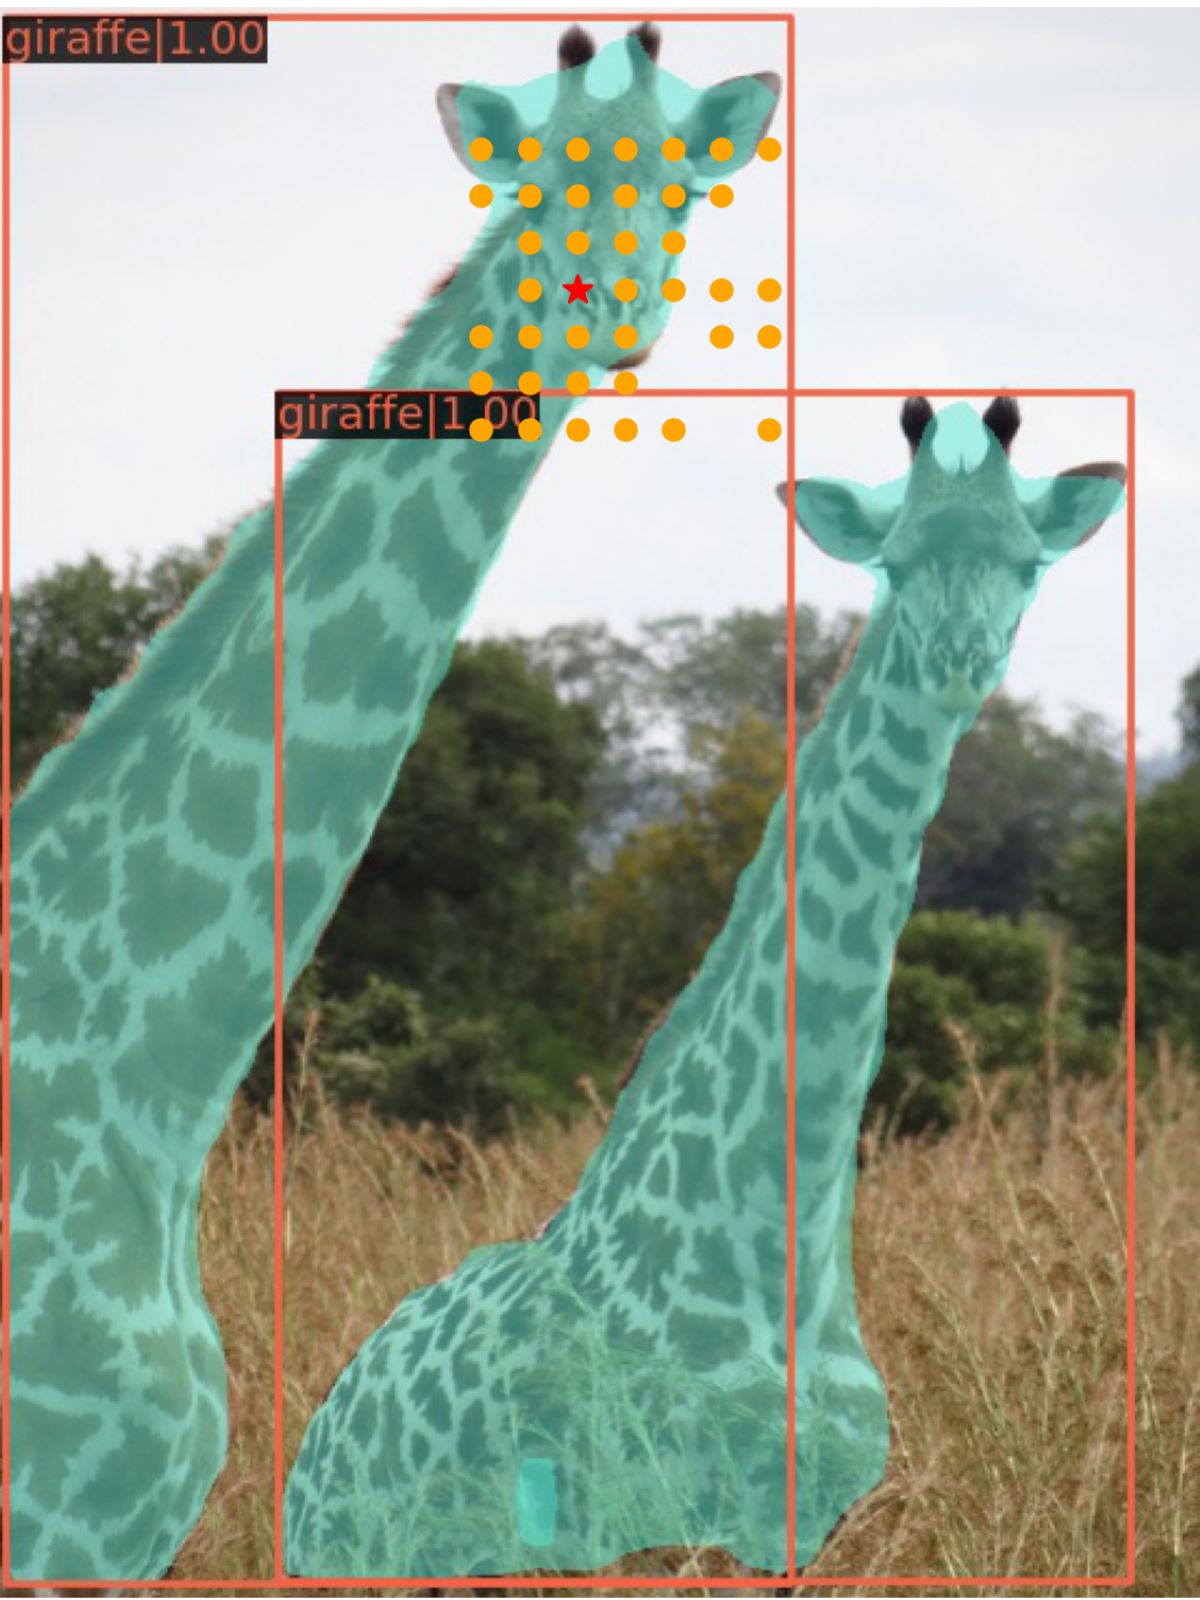
[2201.00520] Vision Transformer with Deformable Attention
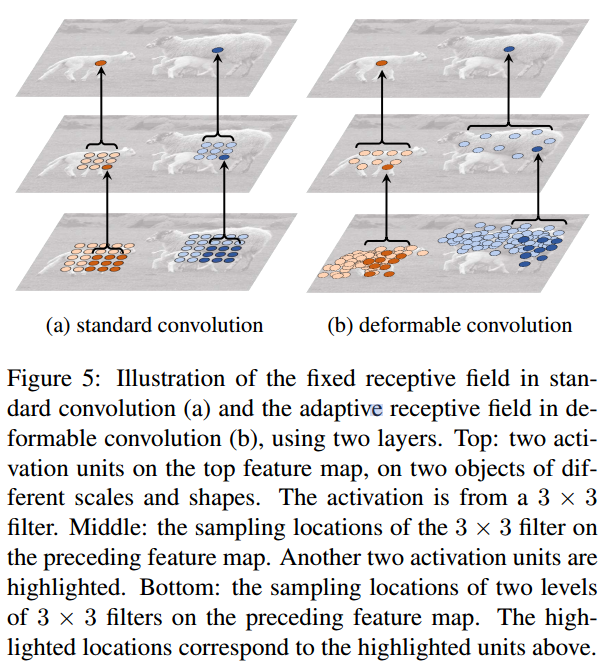
Vision Transformer with Deformable Attention — Vision Transformer의 모든 것
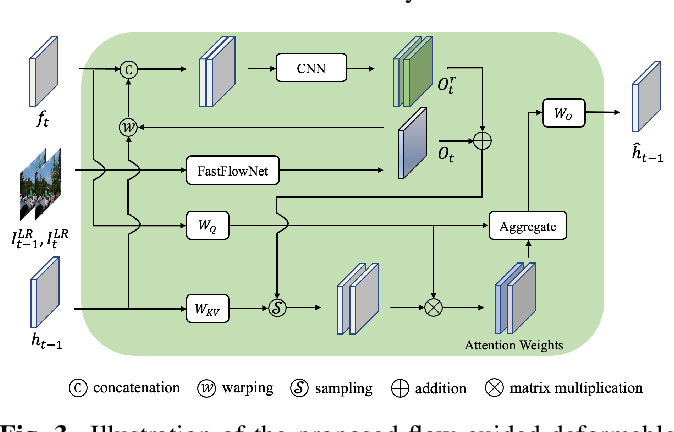
Figure 3 from Flow-Guided Deformable Attention Network for Fast Online ...
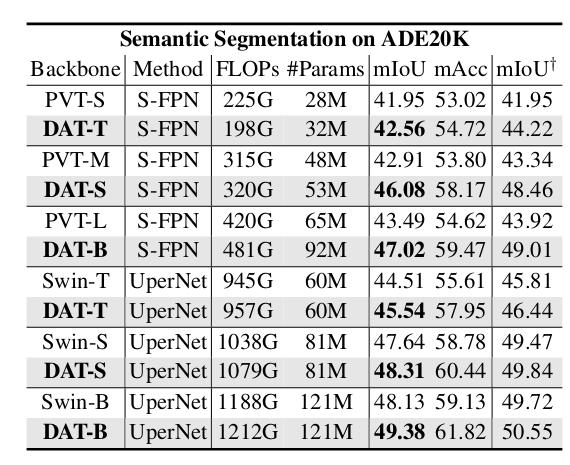
Vision Transformer with Deformable Attention | MYRIAD
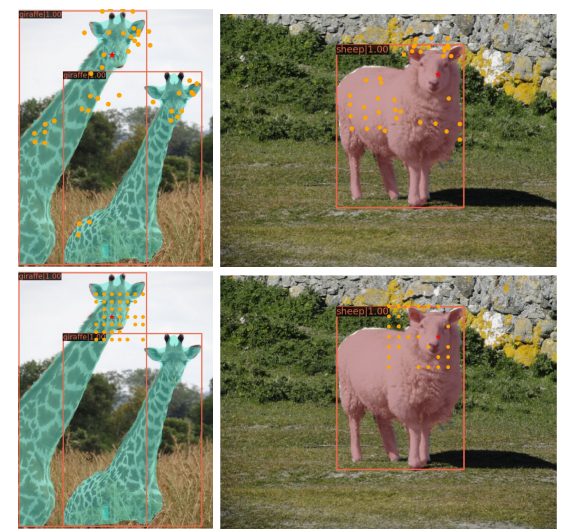
Vision Transformer with Deformable Attention — Vision Transformer의 모든 것

Figure 3 from DFA3D: 3D Deformable Attention For 2D-to-3D Feature ...

論文紹介 : Vision Transformer with Deformable Attention | PDF

Figure 3 from Diffusion-based RGB-D Semantic Segmentation with ...
Advertisement Space (336x280)

DeforHMR: Vision Transformer with Deformable Cross-Attention for 3D ...
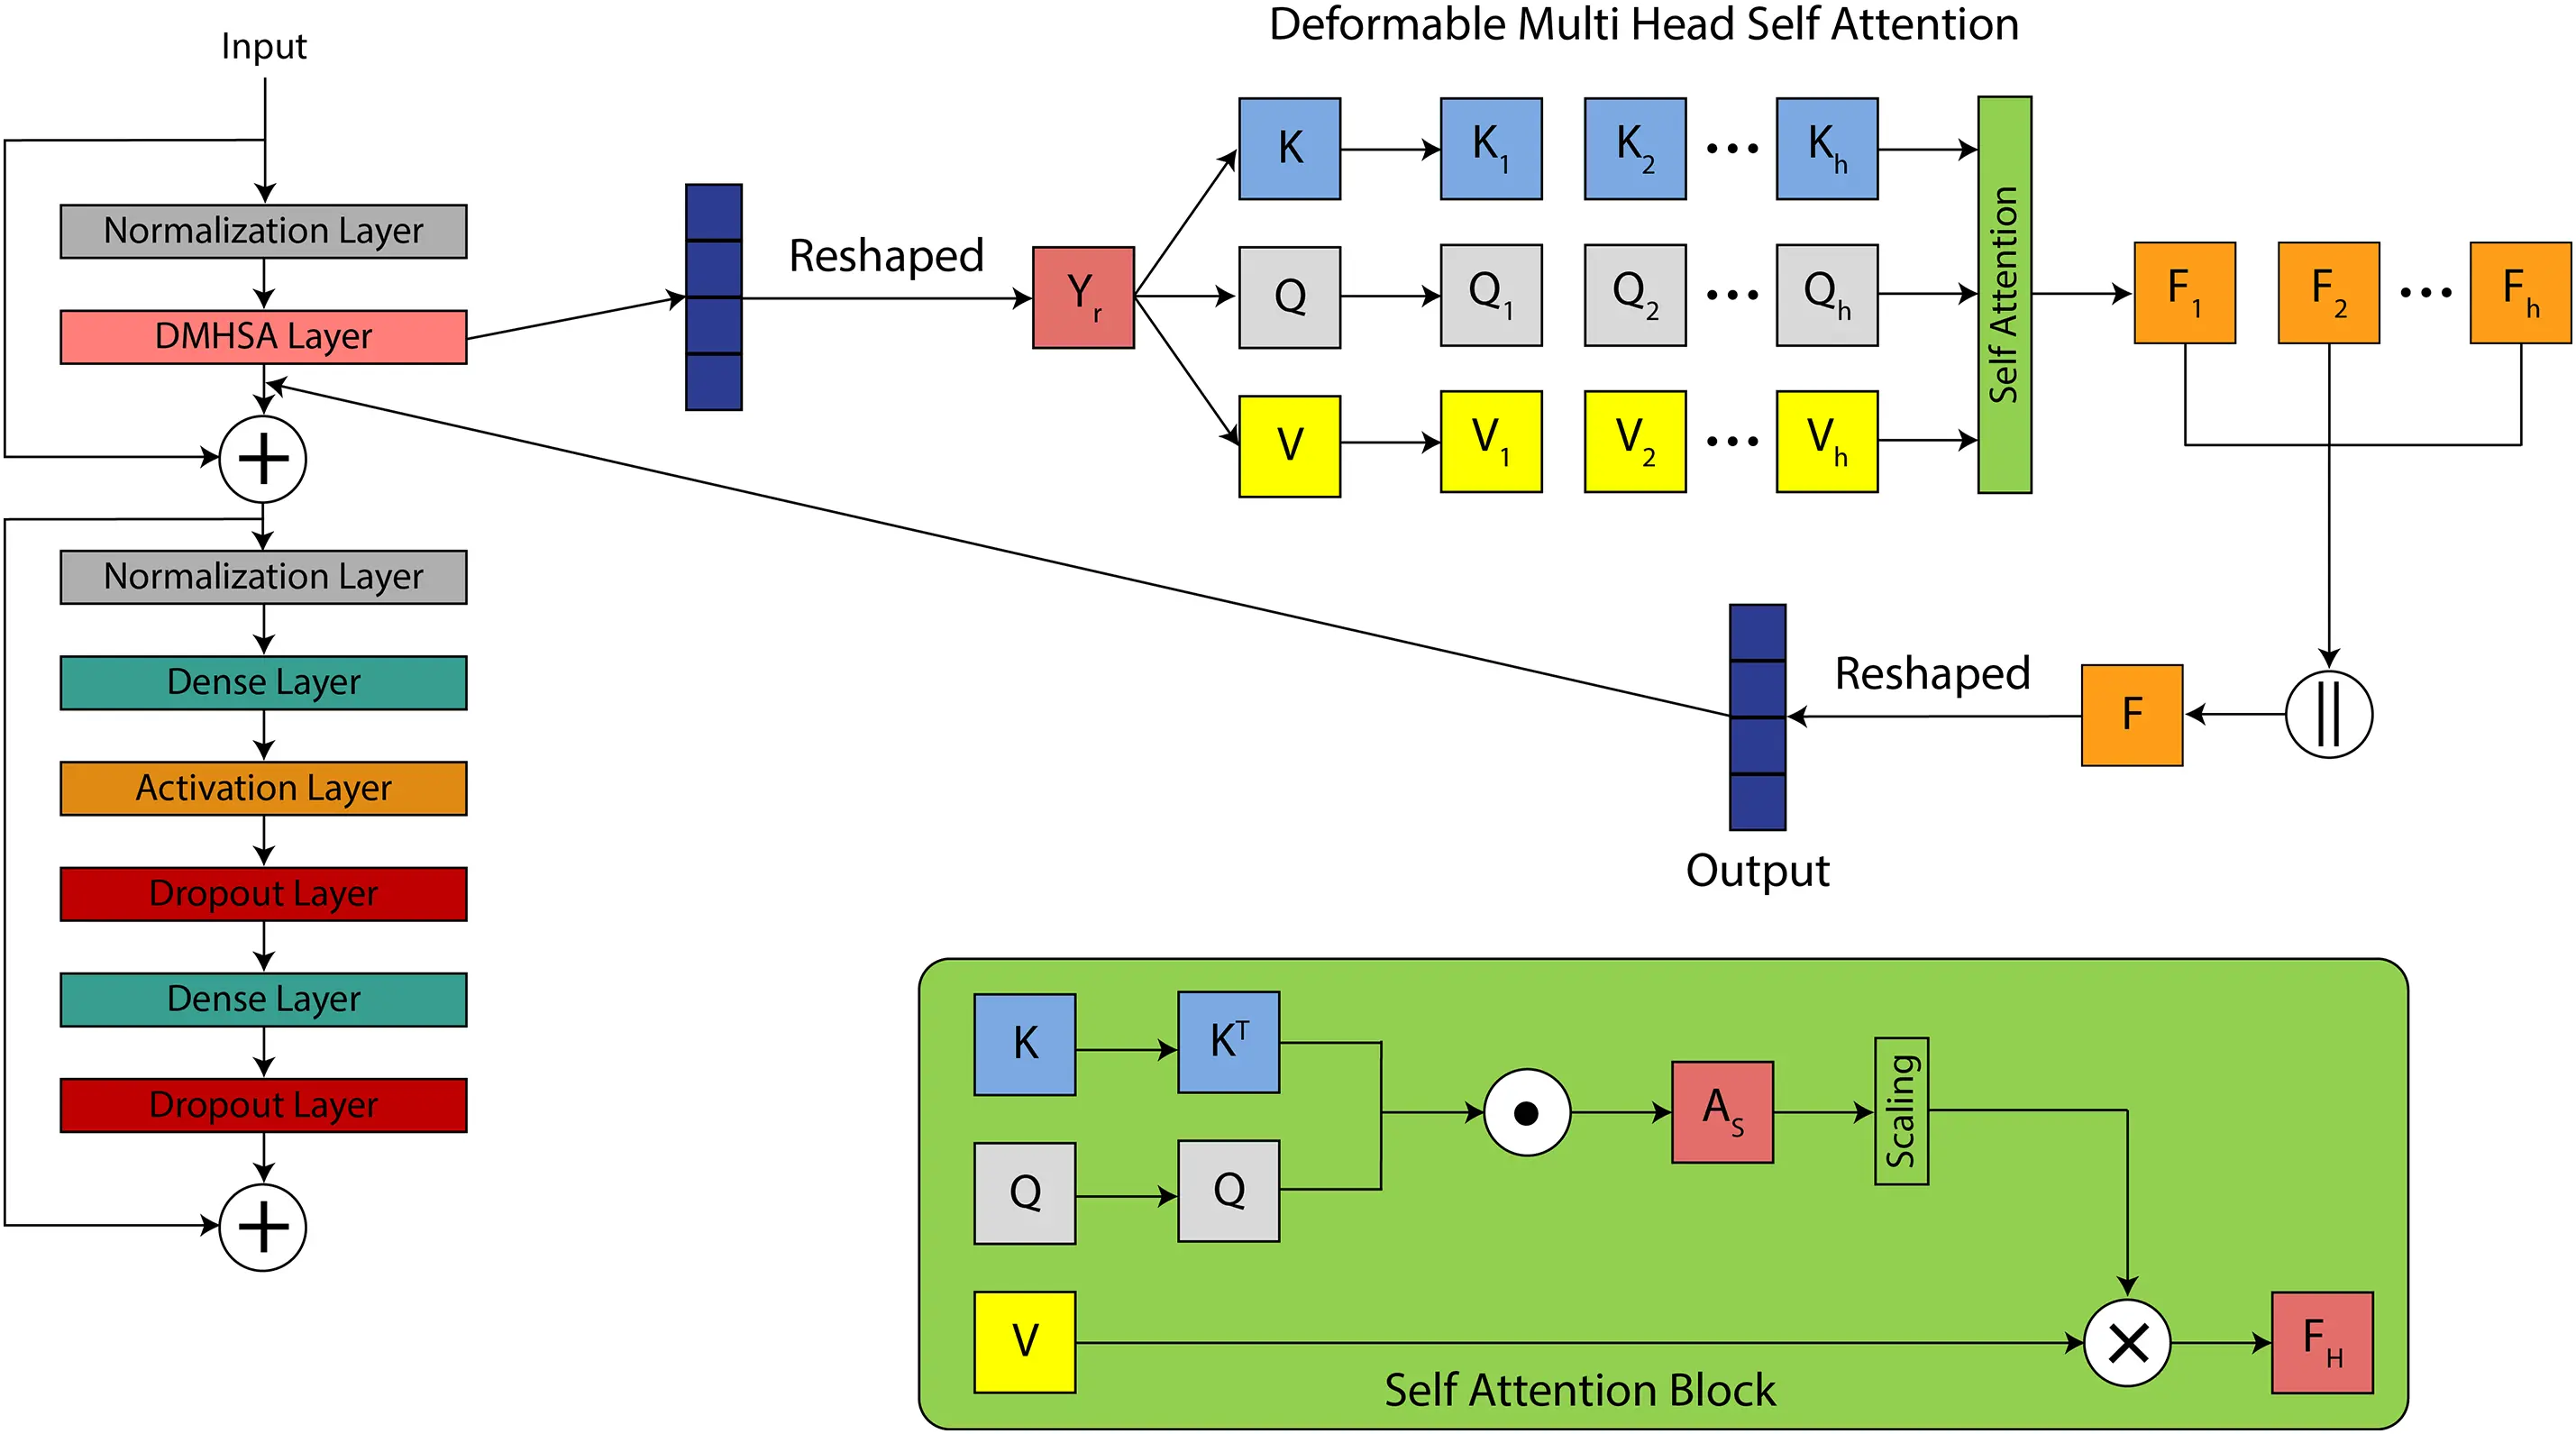
CMES | Free Full-Text | DA-ViT: Deformable Attention Vision Transformer ...

DeforHMR: Vision Transformer with Deformable Cross-Attention for 3D ...

Voxel Transformer with Density-Aware Deformable Attention for 3D Object ...
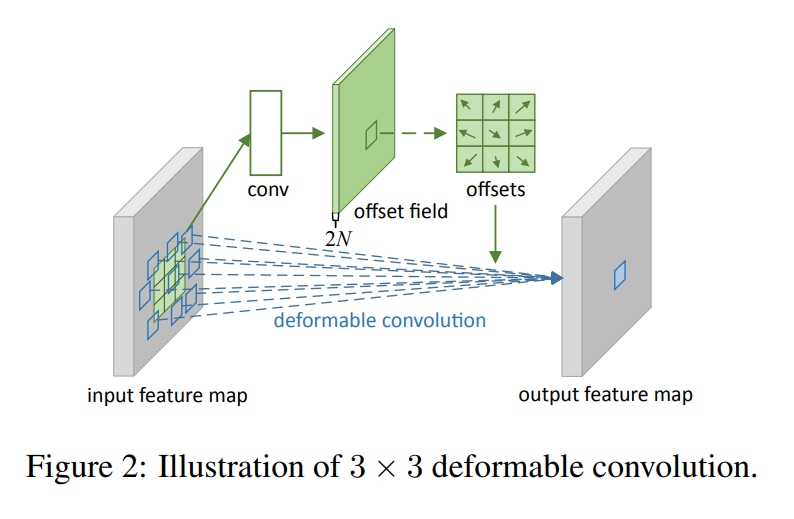
论文解读:Vision Transformer with Deformable Attention - 知乎
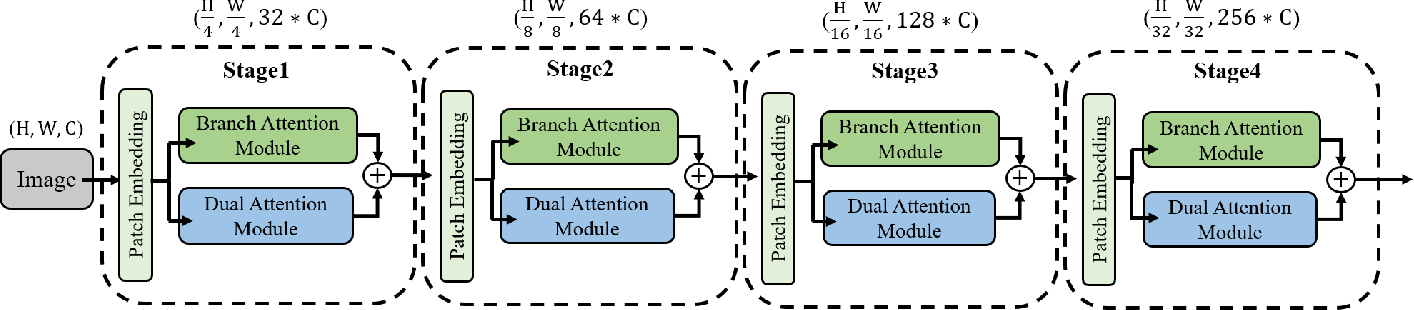
Figure 1 from Triple Attention Vision Transformers for Remote Sensing ...