
Figure 4 From Mpmoe Memory Efficient Moe For Pre Trained Models With

Figure 4 from MPMoE: Memory Efficient MoE for Pre-Trained Models With ...

MPipeMoE: Memory Efficient MoE for Pre-trained Models with Adaptive ...

Long runs. Soft MoE and ViT models trained for 4 million steps with ...

Long runs. Soft MoE and ViT models trained for 4 million steps with ...
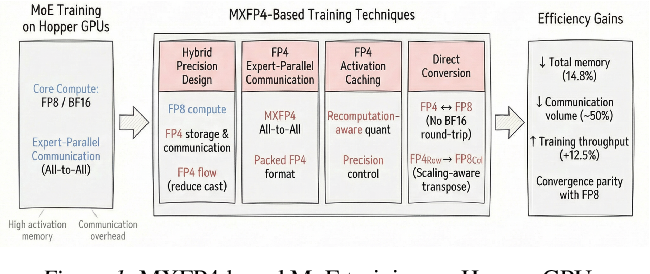
Figure 1 from Practical FP4 Training for Large-Scale MoE Models on ...

Figure 1 from A Scheduling Framework for Efficient MoE Inference on ...

AquilaMoE: Efficient Training for MoE Models with Scale-Up and Scale ...

[논문 리뷰] AquilaMoE: Efficient Training for MoE Models with Scale-Up and ...

Paper page - AquilaMoE: Efficient Training for MoE Models with Scale-Up ...
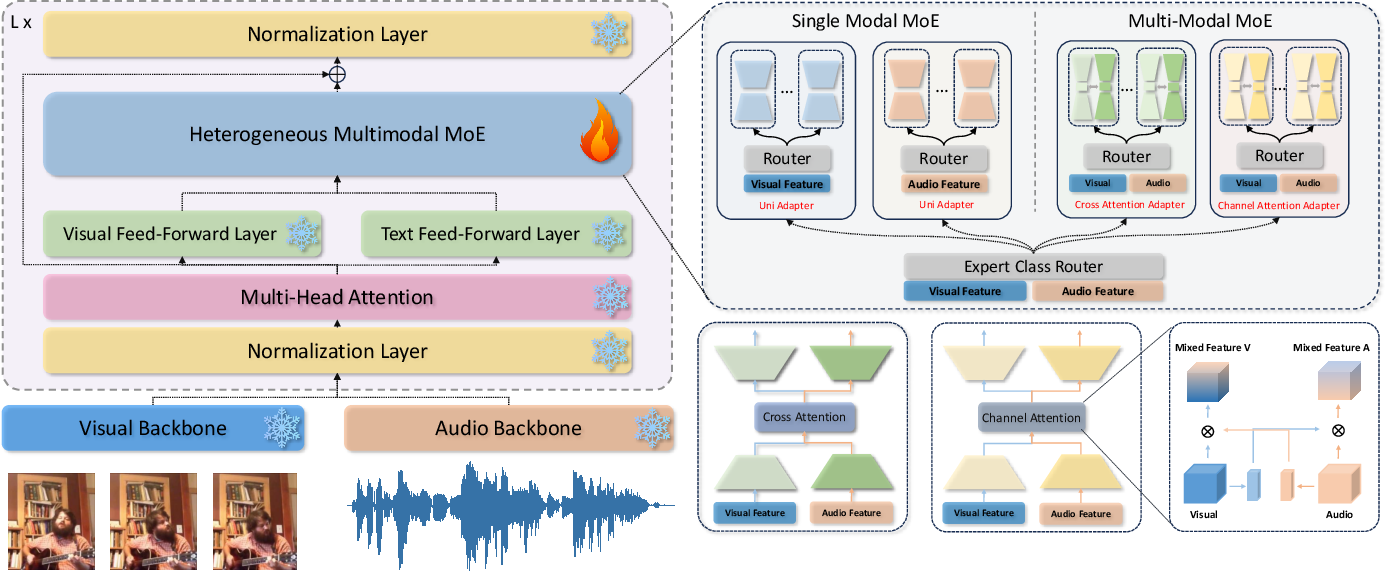
Figure 1 from Enhancing Multi-modal Models with Heterogeneous MoE ...
Advertisement Space (300x250)
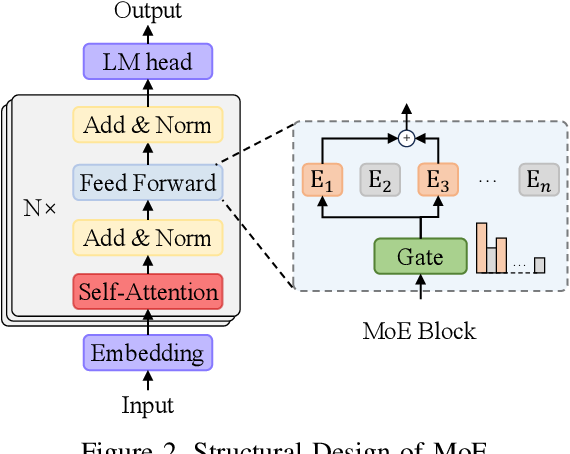
Figure 2 from DS-MoE: Dynamic Expert Scheduling for Efficient MoE-based ...
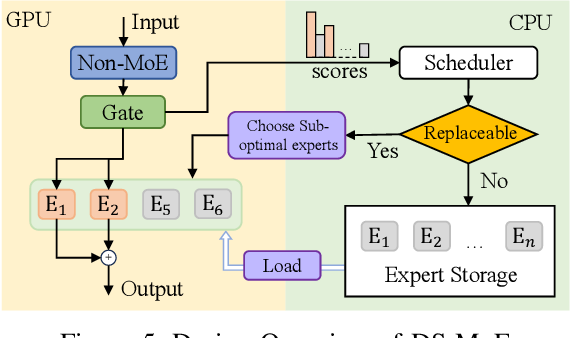
Figure 5 from DS-MoE: Dynamic Expert Scheduling for Efficient MoE-based ...

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...
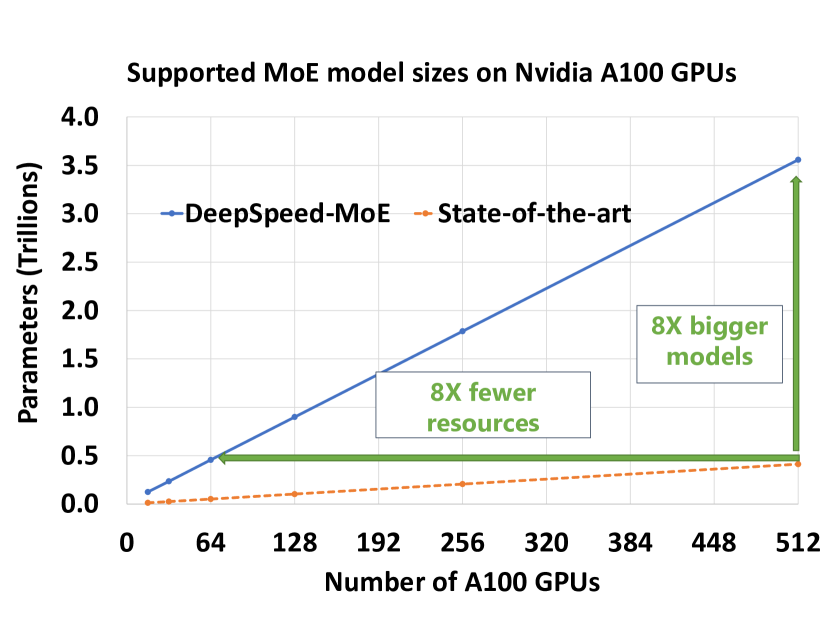
[2109.10465] Scalable and Efficient MoE Training for Multitask ...

New Unified Framework for MoE Models | Juan Sebastian Quiroga posted on ...

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive
Advertisement Space (336x280)

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Figure 1 from ExpertFlow: Adaptive Expert Scheduling and Memory ...

MoE-APEX: An Efficient MoE Inference System with Adaptive Precision ...

DS-MoE: Making MoE Models More Efficient and Less Memory-Intensive

MiLo: Efficient Quantized MoE Inference with Mixture of Low-Rank ...
MoE models over a distributed setup with Expert Parallelism. | Download ...

MoE-Mamba: Efficient Selective State Space Models with Mixture of ...
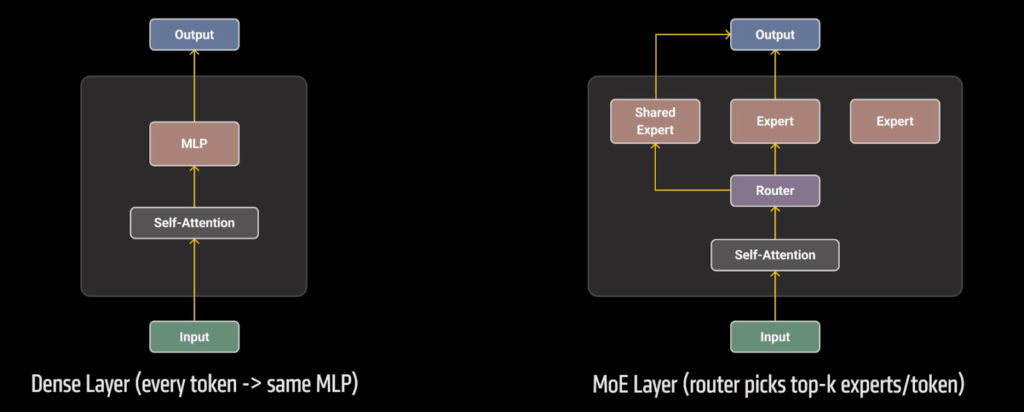
Efficient MoE Pre-training at Scale on 1K AMD GPUs with TorchTitan ...

MoE-APEX: An Efficient MoE Inference System with Adaptive Precision ...

MoE-Mamba: Efficient Selective State Space Models with Mixture of ...
Advertisement Space (336x280)

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

[2401.04081] MoE-Mamba: Efficient Selective State Space Models with ...
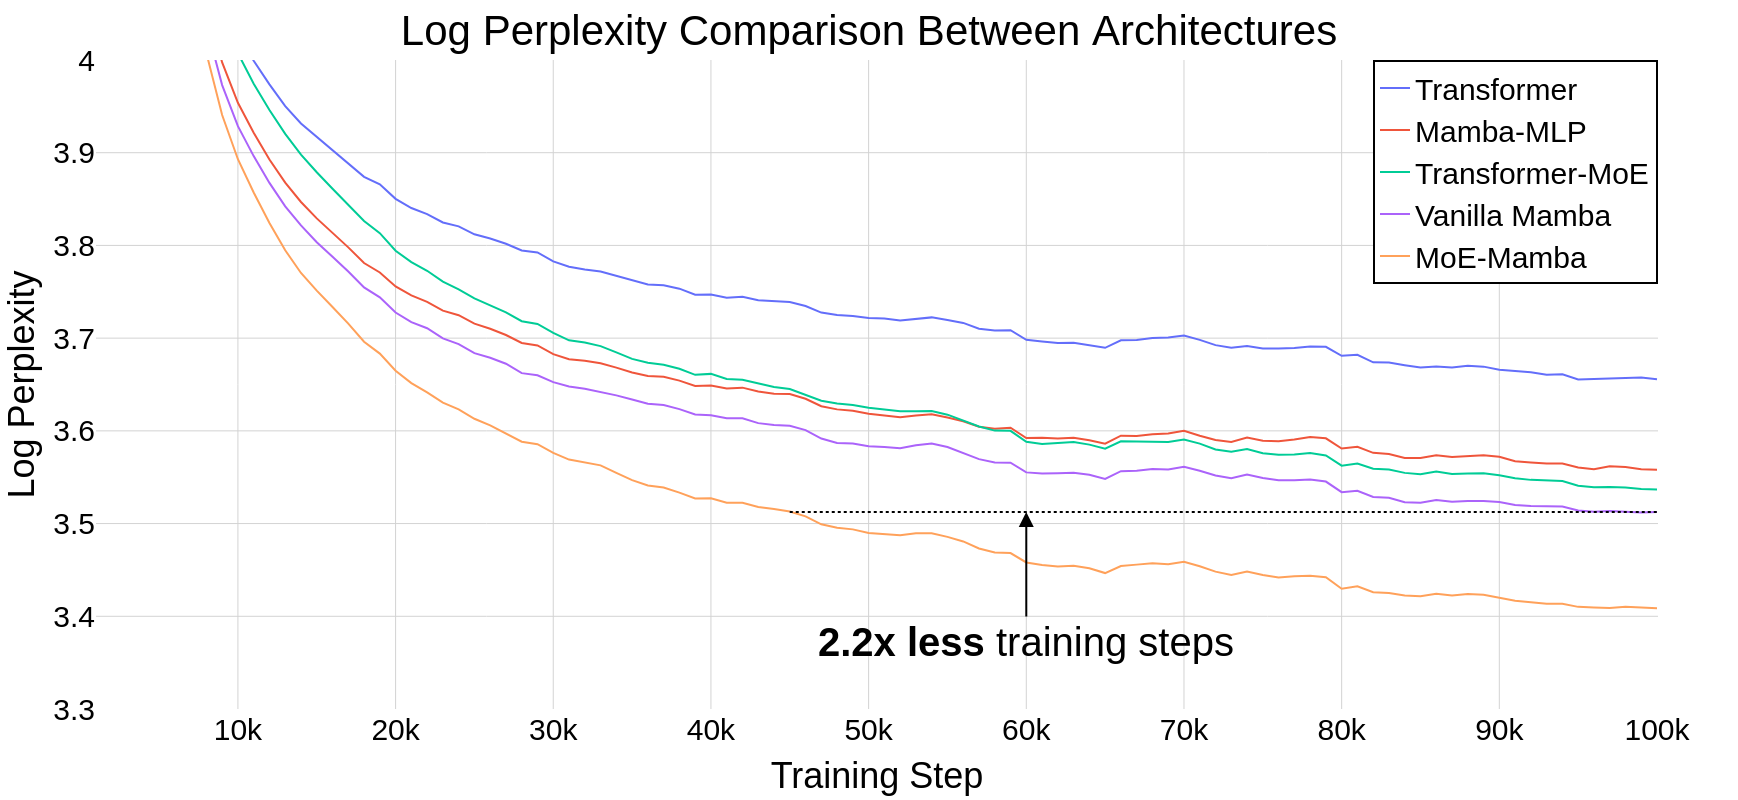
llm-random - MoE-Mamba: Efficient Selective State Space Models with ...

[논문 리뷰] MiLo: Efficient Quantized MoE Inference with Mixture of Low ...

MoE-APEX: An Efficient MoE Inference System with Adaptive Precision ...
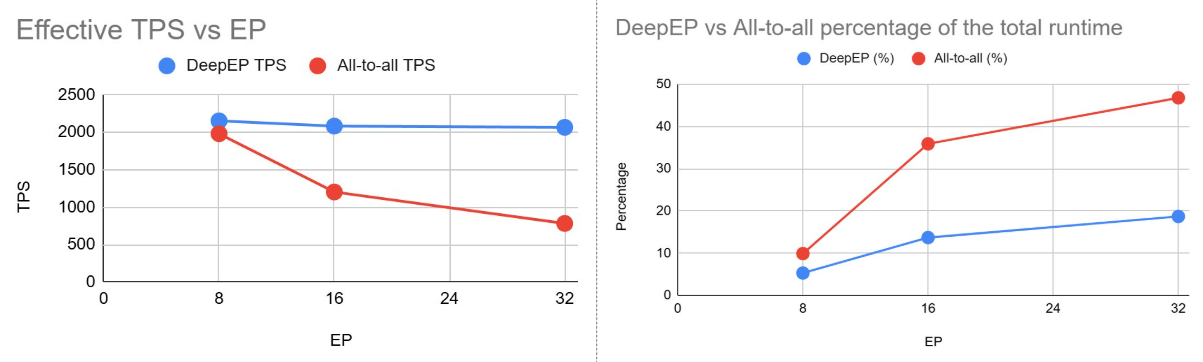
Efficient MoE Pre-training at Scale on 1K AMD GPUs with TorchTitan ...