
Figure 5 From Learning Semantic Alignment Using Global Features And

Figure 5 from Learning Semantic Alignment Using Global Features and ...

Figure 1 from Learning Semantic Alignment Using Global Features and ...

Figure 6 from Learning Semantic Alignment Using Global Features and ...
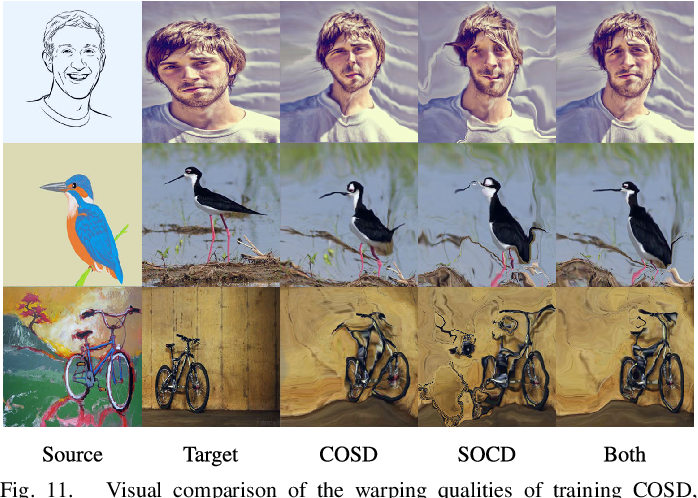
Figure 11 from Learning Semantic Alignment Using Global Features and ...
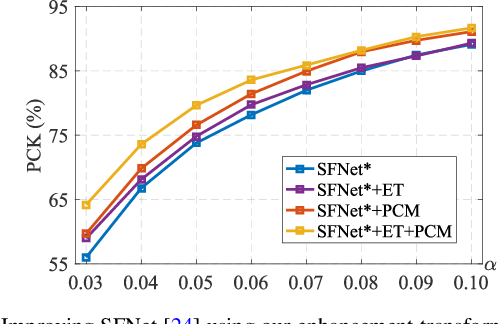
Figure 12 from Learning Semantic Alignment Using Global Features and ...
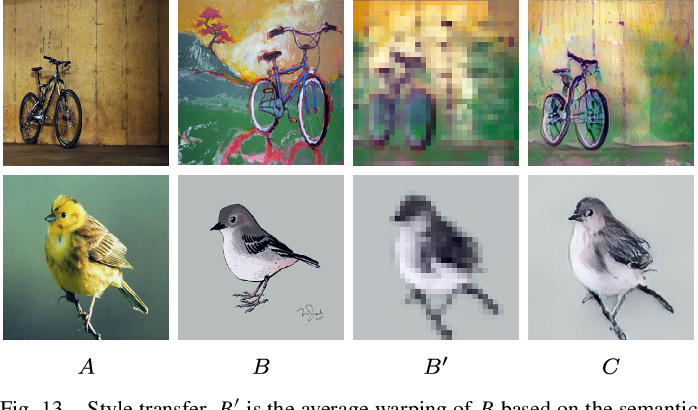
Figure 13 from Learning Semantic Alignment Using Global Features and ...

Table IV from Learning Semantic Alignment Using Global Features and ...

Learning Semantic Alignment Using Global Features and Multi Scale ...
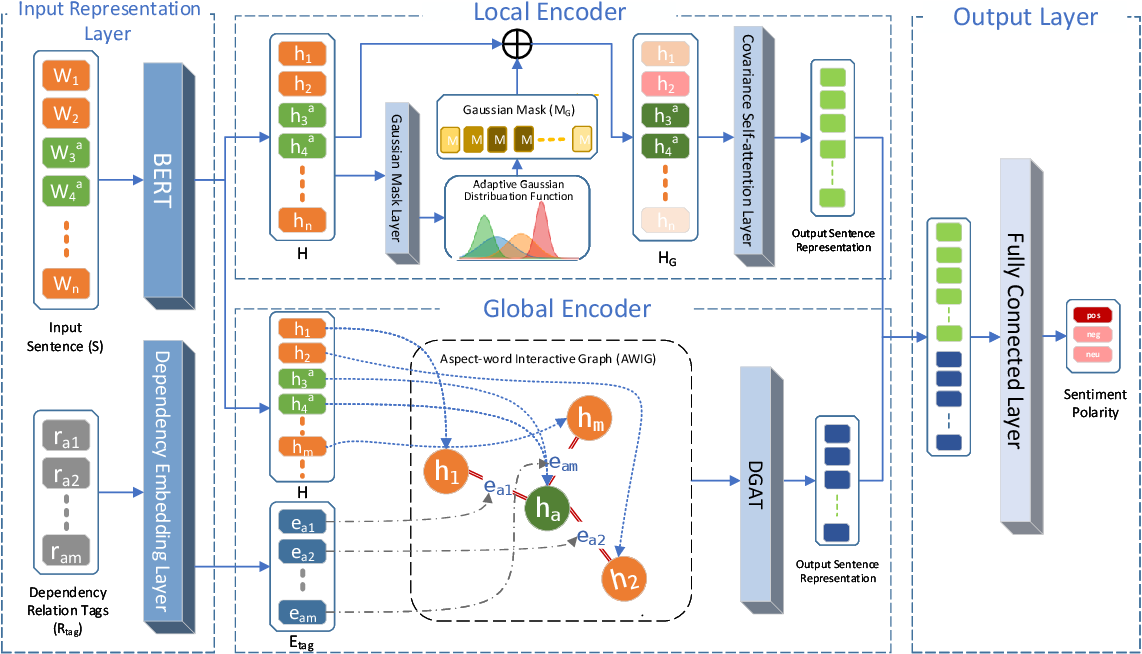
Figure 1 from Joint Learning of Local and Global Features for Aspect ...

(PDF) Video alignment using unsupervised learning of local and global ...
Advertisement Space (300x250)
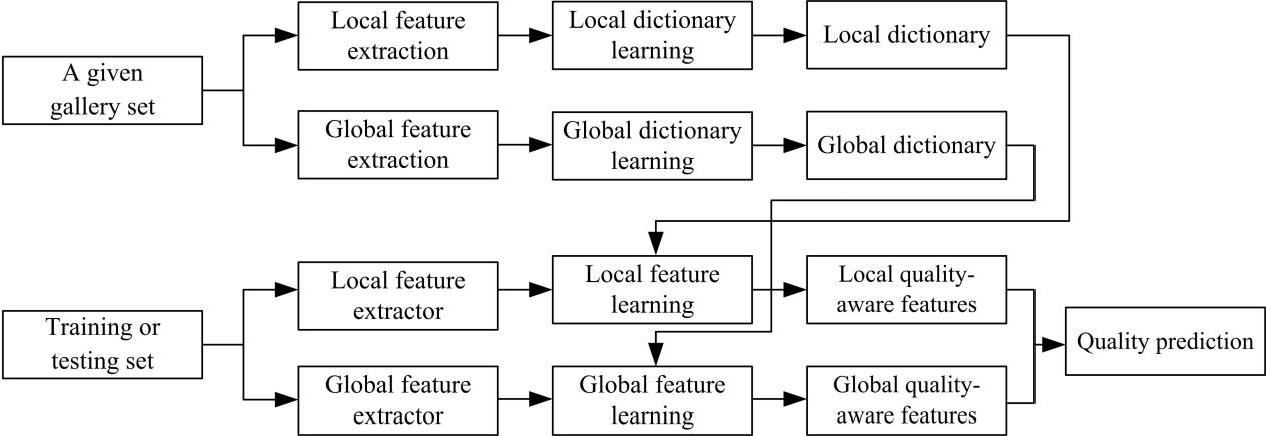
Figure 1 from Local and Global Feature Learning for Blind Quality ...

(PDF) Cross-lingual semantic alignment and transfer learning using ...

Figure 1 from Learning Implicit Feature Alignment Function for Semantic ...

Figure 1 from Semantic Pre-Alignment and Ranking Learning With Unified ...

Figure 1 from Joint Semantic and Spatial Feature Learning for Audio ...

Figure 1 from Learning Pixel-wise Alignment for Unsupervised Image ...

Figure 2 from Multi-Level Representation Learning with Semantic ...
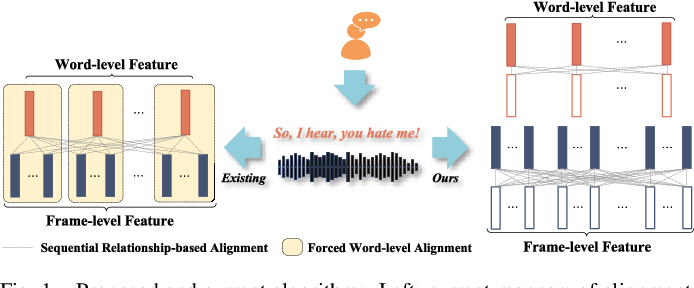
Figure 1 from Semantic Alignment Network for Multi-Modal Emotion ...

Figure 1 from Multilevel Semantic Interaction Alignment for Video–Text ...

Figure 1 from Discrete Joint Semantic Alignment Hashing for Cross-Modal ...
Advertisement Space (336x280)

Figure 2 from A Deep Learning-based Global and Segmentation-based ...

Figure 1 from Aligner: Efficient Alignment by Learning to Correct ...
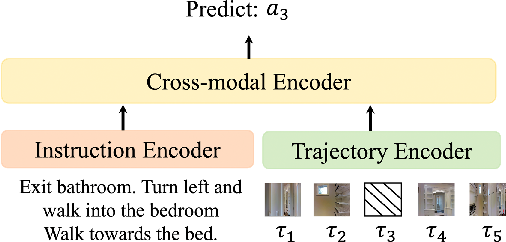
Figure 5 from Vision-and-Language Navigation via Latent Semantic ...

Figure 1 from Learning to Align Multi-Camera Domains using Part-Aware ...
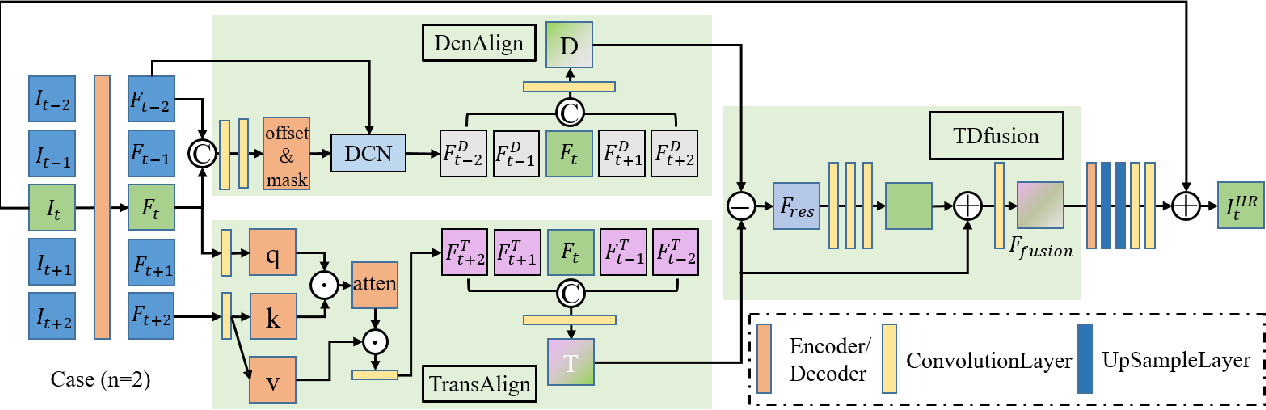
Figure 1 from Learning a Local-Global Alignment Network for Satellite ...

[2306.07096] Global and Local Semantic Completion Learning for Vision ...

Figure 1 from Semantic Manifold Alignment in Visual Feature Space for ...

Figure 1 from Multilevel Semantic Interaction Alignment for Video–Text ...
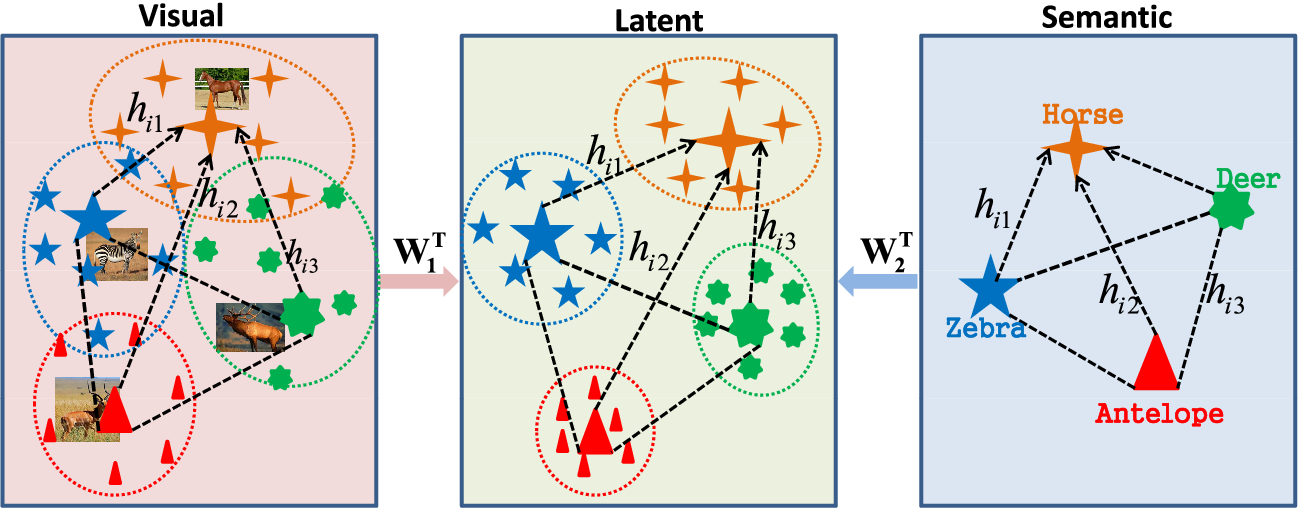
Figure 2 from Learning Discriminative Projection With Visual Semantic ...

Figure 1 from Cascade Semantic Prompt Alignment Network for Image ...
Advertisement Space (336x280)

Figure 5 from Contrastive Learning-Based Multi-Modal Entity Alignment ...
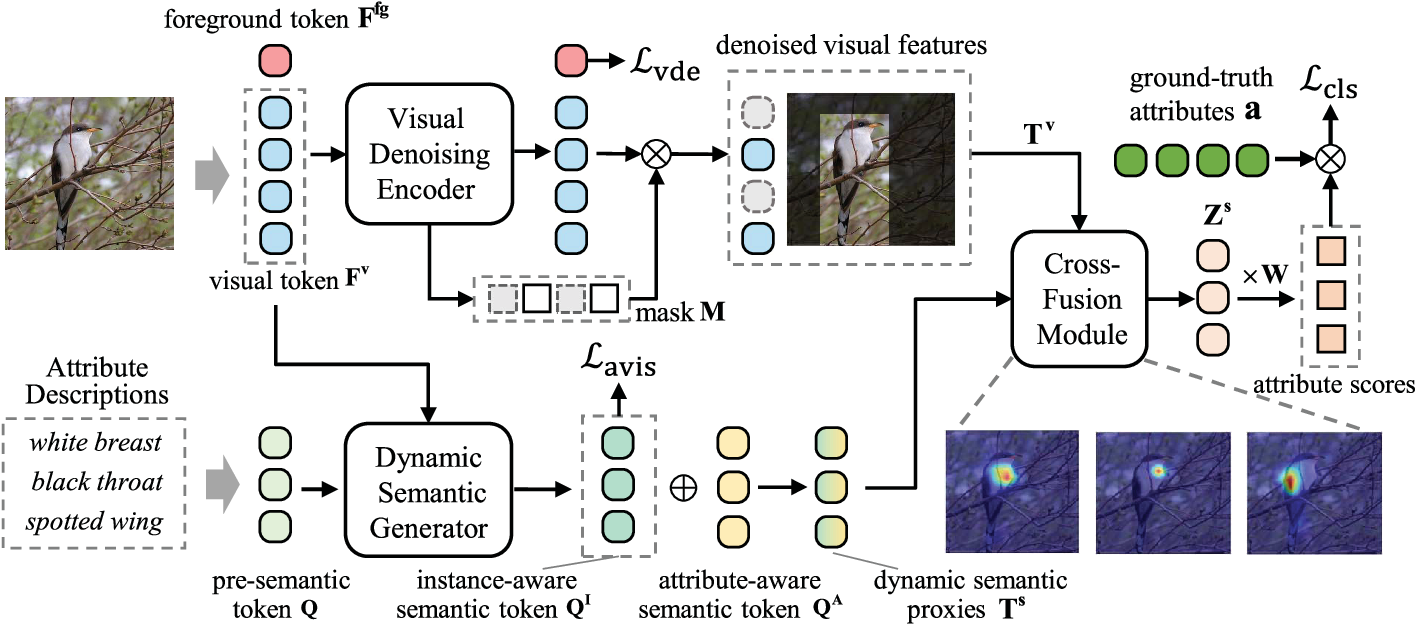
Figure 3 from Denoised and Dynamic Alignment Enhancement for Zero-Shot ...
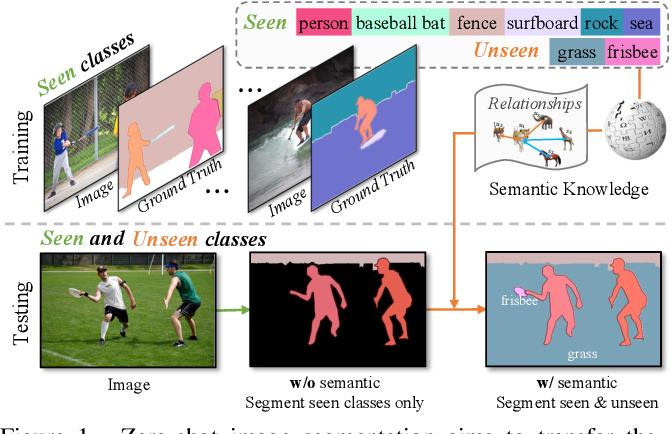
Figure 1 from Primitive Generation and Semantic-Related Alignment for ...

Figure 5 from Intent-aware Multi-source Contrastive Alignment for Tag ...

Figure 1 from CA_DeepSC: Cross-Modal Alignment for Multi-Modal Semantic ...

Learning semantic alignment from image for text-guided image inpainting ...